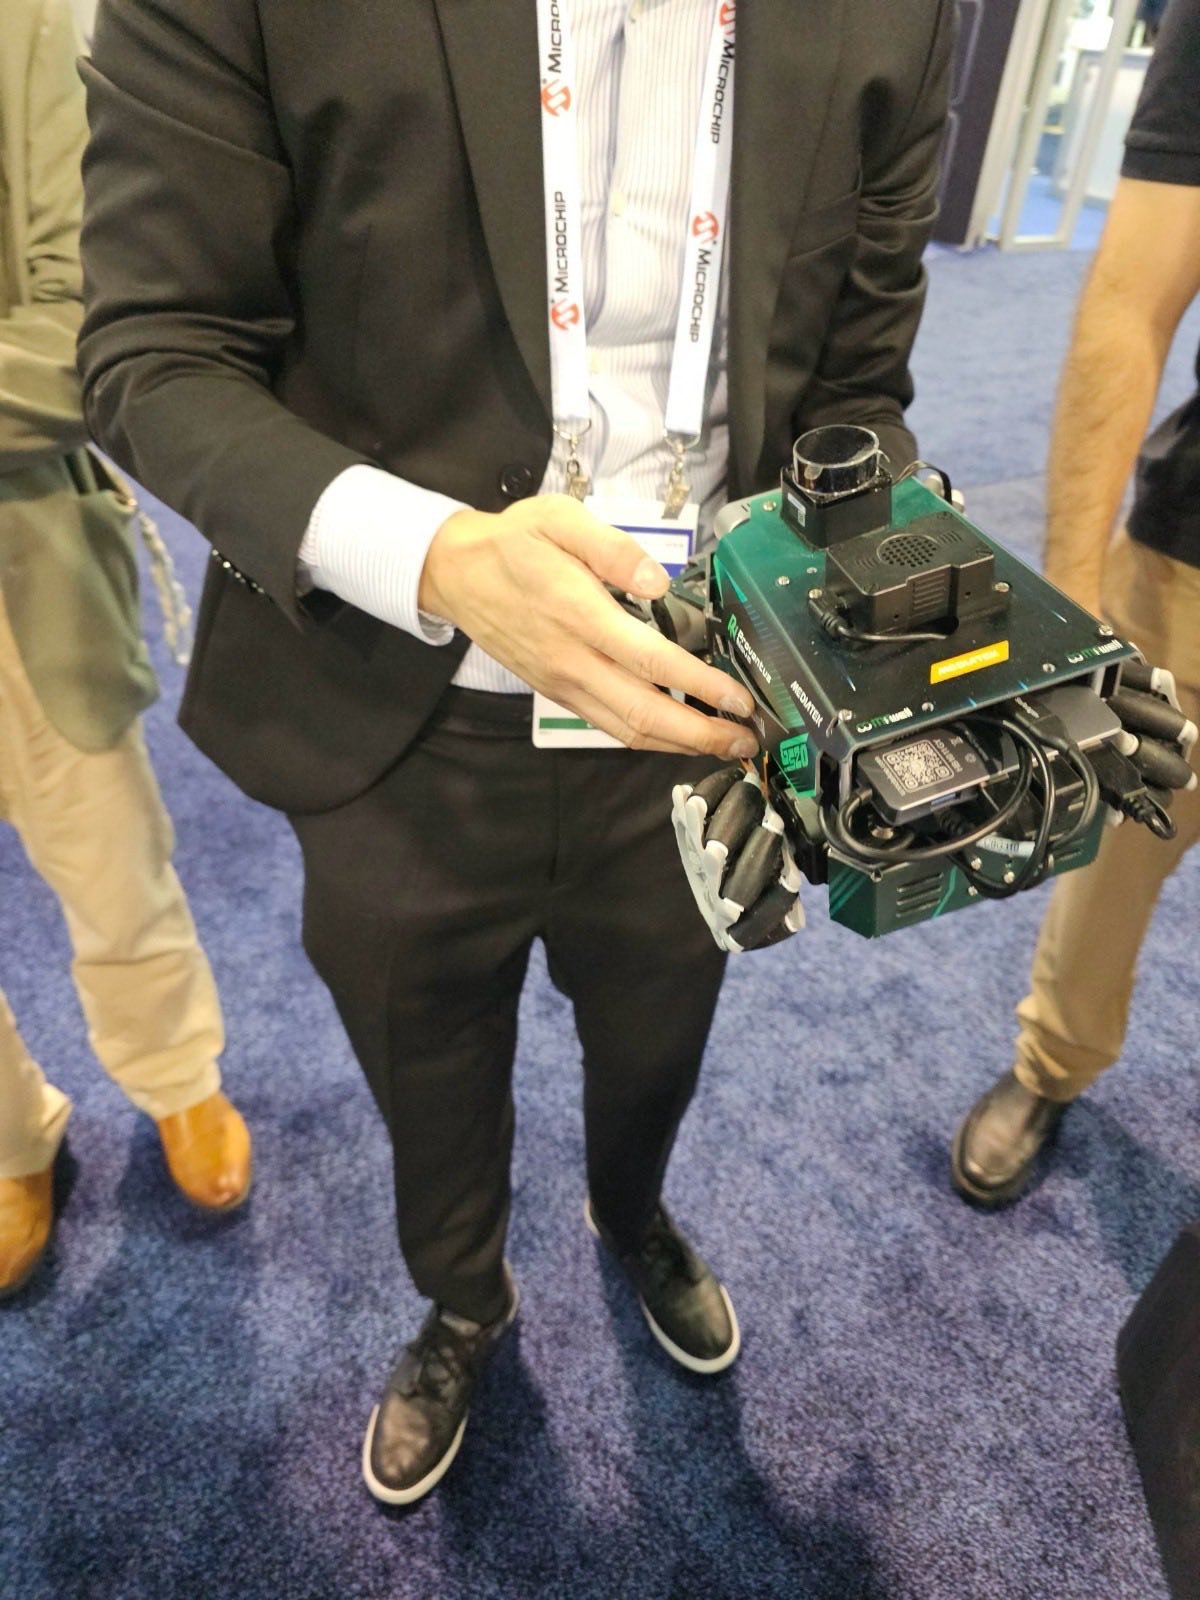
Whisper Speech-to-Text on the MediaTek Genio NPU
We wanted our robot to take spoken commands with no phone, no server, and no internet. That means speech-to-text has to run on the robot. Here is what it took to put Whisper on the MediaTek Genio’s neural accelerator, and an honest account of the latency, because that part is more interesting than the headline.
Key Insights
- Whisper runs on the MediaTek Genio 520 NPU using only the on-device runtime that ships in the image, with no extra runtime libraries on the target
- Speech-to-text happens fully offline, which is the point for a robot, a kiosk, or any product that cannot depend on a network
- With a Whisper-medium model, the encoder runs in about 1.5 seconds and a short command is 6 to 9 seconds to transcribe
- End to end, from speaking to the robot moving, is about 8 to 13 seconds, and lowering that is a tuning problem, not a hardware one
- The accelerator gets you on-device speech at all; the latency you actually ship is decided by model choice and how the model is served
Why on-device speech, and why the NPU
Cloud speech recognition is easy and it is the wrong choice for a lot of edge products. A robot at a trade show, a device in a vehicle, a product that handles anything sensitive: all of them need to keep working when the network does not, and some of them cannot send audio off the device at all. That pushes speech-to-text onto the device.
Whisper is a strong model for this, and it is heavy. Running it on the Genio’s CPU is possible but competes with everything else the robot is doing. The neural accelerator is the right home for it, the same way it is for vision.
What we did, and what it took
We run a Whisper model on the Genio NPU and it drives the robot’s voice control directly: you speak, the robot transcribes on-device, an on-device step maps the words to an action, and the wheels respond. No cloud is involved at any point.
The part worth calling out is that this runs on the stock on-device runtime already present in the Genio image. You do not need to install a separate accelerator runtime on the target to execute the model. That keeps the deployment clean: the device ships with what it needs to run inference.
Getting a model into the form the accelerator loads is the engineering work, and it is the part we keep for a conversation. The reason is the same as with vision: the interesting question for your product is not the toolchain, it is whether your speech model hits a latency your users will tolerate on the board you have. That we can tell you.
The latency reality
Here is the honest picture, because it is the useful part. With a Whisper-medium model:
- The encoder runs in about 1.5 seconds per utterance.
- A short spoken command transcribes in about 6 to 9 seconds.
- Add a second or two for the on-device step that turns the text into an action, and you are at roughly 8 to 13 seconds from speaking to motion.
That is real, and for a walk-up demo it is on the edge of acceptable. The levers that bring it down are model size and how the model is loaded and served between calls. A smaller Whisper model is dramatically faster and gives up some accuracy; a better serving strategy removes overhead that has nothing to do with the model at all. Which of those is right depends on the product, and choosing well is most of the latency you actually ship.
We are running a direct CPU-versus-NPU speech benchmark on this exact board, and the result is more nuanced than the vision case. When it is done we will publish the numbers, because “put it on the NPU” is not automatically the fastest answer for speech, and the honest version of that story is worth more than a slogan.
Where this fits
If your product needs voice or audio understanding on-device, on the MediaTek Genio or on NVIDIA Jetson, the pattern is the same: the accelerator makes on-device speech possible, and the latency you ship is an engineering choice you want to get right early rather than discover late. That is the work we do on a fixed timeline. Tell us what you are building and we will tell you the fastest path to a working result. For the robot this came from, see the ROSOrin build overview, and for the vision side, YOLOv8 on the Genio NPU.
Relevant Services
MediaTek Genio Expert Support
Building on MediaTek Genio?
BSP bring-up, GStreamer pipelines, NeuroPilot integration, we've shipped it. Get unblocked fast. One call to scope it, fixed bid to deliver it.
Frequently Asked Questions
Can you run Whisper on the MediaTek Genio NPU?
Yes. On our ROSOrin robot we run a Whisper speech-to-text model on the MediaTek Genio 520 neural accelerator to turn spoken commands into robot actions, fully offline. It runs using only the on-device runtime that ships in the Genio image, so no special runtime libraries need to be copied onto the board.
How fast is Whisper on the Genio NPU?
With a Whisper-medium model the encoder runs in about 1.5 seconds and a short spoken command transcribes in roughly 6 to 9 seconds, with another second or two for the on-device step that maps the text to an action, so about 8 to 13 seconds from speech to motion. Smaller Whisper models are the path to lower latency, at some cost in accuracy.
Do you need the cloud for on-device speech recognition?
No. The whole point of running Whisper on the NPU is that speech-to-text happens on the device with no network. For a robot, a kiosk, or any product that has to work without connectivity or keep audio private, on-device speech is the difference between a feature that always works and one that depends on a signal.
Is a bigger Whisper model always better on an edge NPU?
No. Model size trades accuracy against latency and memory, and on an edge accelerator the loading and setup cost per call can dominate. Choosing the right model size, and structuring how it is loaded and served, matters as much as the raw accelerator speed. That tuning is where the real-world latency is won or lost.
Written by
Andrés CamposCo-Founder & CTO · ProventusNova
8 years deep in embedded systems, from underwater ROVs to edge AI. Andrés leads every technical delivery personally.
Connect on LinkedInRelated Articles
NPU vs CPU on the MediaTek Genio: the Thermal Reality
On a fanless MediaTek Genio, running a vision model on the CPU pushed our robot to 84 C and throttled. On the NPU it held 58 C. Why edge AI is a heat problem.
ONNX Runtime on the MediaTek Genio NPU (520 and 720)
Run ONNX Runtime on the Genio NPU. Only the Genio 520 and 720 support the NeuronExecutionProvider out of the box, plus the mandatory FP16 flag and benchmarks.
Getting started with Ubuntu on MediaTek Genio
Run Ubuntu on MediaTek Genio: supported boards, first boot, the genio-public BSP PPA, hardware video and NPU packages, and how it differs from Yocto.
Voice-to-Wheels: Turning Speech into ROS 2 Motion
Routing every spoken command through an LLM made our robot slow and wrong. A rule layer in front of the model fixed both. How we structured voice control.