# ProventusNova, Full Site Content for LLM Indexing
Source: https://proventusnova.com
Generated: 2026-09-28
---
# Company Overview
ProventusNova is an embedded software development firm that works exclusively with hardware startups building computer vision and EdgeAI products. We specialize in NVIDIA Jetson (Orin, AGX, NX) and MediaTek Genio platforms.
Our core model is fixed-bid, milestone-driven delivery. We do not bill hourly. Every engagement starts with a Proof Sprint™, a short, bounded scope that delivers working results in days so founders can validate before committing to a larger engagement.
**Core capabilities:**
- Custom carrier board bring-up (U-Boot, kernel, device tree), typical timeline: 7 days
- GMSL2 camera driver development and multi-camera synchronization, typical timeline: 1 month
- CSI camera integration and ISP tuning on Jetson and Genio
- GStreamer pipeline development for real-time multi-camera vision systems
- AI model deployment and optimization (TensorRT, INT8 quantization, DLA mapping), typical timeline: 14 days
- Hardware sourcing, ODM selection, and carrier board specification guidance
**Who we work with:**
Hardware startup founders and CTOs building products on NVIDIA Jetson or MediaTek Genio who are blocked on embedded software and need working results fast, not a long hiring process or an hourly contractor.
**Pricing model:**
Fixed-bid engagements. Typical Proof Sprint™ scope: $15,000–$25,000. Full-project engagements: $150,000+ over 6 months.
---
# Services
## GMSL Camera Driver Development
URL: https://proventusnova.com/services/gmsl/
Get GMSL cameras capturing reliably in 1 month. We develop SerDes initialization, virtual channel configuration, and multi-camera synchronization for GMSL2 camera systems on NVIDIA Jetson. Fixed bid. Named outcome: reliable simultaneous capture from all cameras.
## CSI Camera Integration
URL: https://proventusnova.com/services/csi/
Unblock camera capture for CSI-based vision systems. Device tree configuration, V4L2 driver bring-up, ISP pipeline setup on Jetson and Genio.
## Custom Board Bring-Up
URL: https://proventusnova.com/services/custom-board-bringup/
Board bring-up in 7 days. We take your custom carrier board from no boot to a working Linux environment, U-Boot configuration, kernel build, device tree authoring, first-boot validation. Fixed bid.
## EdgeAI Deployment
URL: https://proventusnova.com/services/edgeai-deployment/
Deploy optimized AI models to NVIDIA Jetson in 14 days. TensorRT engine conversion, INT8/FP16 quantization, DLA mapping, throughput benchmarking. Fixed bid. Guaranteed delivery timeline.
## GStreamer Pipeline Development
URL: https://proventusnova.com/services/gstreamer/
Build reliable GStreamer pipelines for multi-camera, real-time vision products. Source plugin selection, pipeline architecture, buffer management, latency optimization.
## Hardware Sourcing
URL: https://proventusnova.com/services/hardware-sourcing/
Guided ODM relationship management, hardware sourcing, and carrier board specification. We manage the process from component selection to delivery.
---
# Blog Posts
## Camera Lifecycle in Docker: SIGINT vs SIGTERM
URL: https://proventusnova.com/blog/docker-camera-lifecycle-sigint-ros2/
Published: 2026-09-28
Author: Andres Campos
Tags: ros2, docker, mediatek genio, camera, embedded linux
Our ROS 2 camera container would not restart cleanly, and the camera got stuck. The cause was the stop signal. Why SIGTERM broke it and SIGINT fixed it.
A camera that will not restart cleanly is a small bug with a large blast radius, because everything downstream depends on it. Ours got stuck in a way that looked like flaky hardware and was actually a stop signal. This is one of those fixes that is one line and saves a day, so it is worth knowing before you meet it.
## Key Insights
- Our ROS 2 camera container took ten seconds to stop and left the camera in a bad state
- The launcher ran as PID 1 and ignored SIGTERM, so every stop rode out Docker's grace period and ended in a hard kill
- The hard kill left the camera mid-operation, it self-reset, and the next open collided with that reset and never recovered
- Switching the container's stop signal to SIGINT let the process close the camera cleanly in about a second, and restarts became reliable
- A frame watchdog was added as a backstop to recover from any remaining stuck state
## The symptom
Stopping and restarting the camera container was unreliable. A stop took a full ten seconds, and afterward the camera would often fail to open, throwing the same error over and over and never recovering until a deeper reset. It alternated between working and failing in a way that felt like a bad cable or a marginal device, which is the kind of symptom that sends teams down the hardware path for days.
## The cause: PID 1 and the stop signal
Inside the container, the ROS 2 launcher ran as process ID 1. When Docker stops a container it sends the SIGTERM signal and waits a grace period before hard-killing with SIGKILL. The launcher, as PID 1, did not act on SIGTERM, so every stop waited out the entire grace period and then died by force. That is why the stop took ten seconds, and it is why the camera was left in a bad state: a forced kill does not give the process a chance to close the device cleanly.
Then the two halves collided. The camera, abandoned mid-operation, would reset itself a couple of seconds later. Meanwhile the next start of the container was already trying to open the camera, and that open landed right on top of the device's self-reset. The result was a camera that never came back until something reset it harder.
## The fix
The camera closed cleanly when the process received SIGINT, the interrupt signal, rather than SIGTERM. Telling the container to use SIGINT as its stop signal changed the shutdown from a ten-second forced kill into a clean close in about a second, with no device reset and reliable restarts. We also added a frame watchdog as a backstop: if the camera goes quiet unexpectedly, it recovers the device rather than sitting stuck.
That is the whole fix, and it is the kind of thing that is obvious once seen and invisible until then. The general lesson is broader than cameras: any container that owns a hardware device needs its shutdown to actually reach the process, so the device gets released cleanly. When PID 1 ignores the signal Docker sends, you get hard kills and stuck devices, and the cure is to send a signal the process respects.
We keep the specific launch and compose details for the projects we do, because they vary with your stack. The reusable insight, the one worth publishing, is to check the stop signal the moment a device-owning container restarts badly.
If your containerized robotics or vision stack has services that will not cycle cleanly, on the MediaTek Genio or on NVIDIA Jetson, [tell us what you are building](/contact) and we will make the lifecycle reliable. For the whole robot, see [the ROSOrin build overview](/blog/voice-controlled-robot-mediatek-genio).
---
## NPU vs CPU on the MediaTek Genio: the Thermal Reality
URL: https://proventusnova.com/blog/genio-npu-vs-cpu-thermal-edge-ai/
Published: 2026-09-28
Author: Andres Campos
Tags: mediatek genio, npu, edge ai, thermal, computer vision
On a fanless MediaTek Genio, running a vision model on the CPU pushed our robot to 84 C and throttled. On the NPU it held 58 C. Why edge AI is a heat problem.
Here is a lesson that surprises product teams: on a small fanless edge board, running AI is a heat problem before it is a speed problem. We learned it the direct way, by watching our robot's MediaTek Genio climb past its throttle temperature within a minute of turning the camera on. This is what that looks like and how to think about it.
## Key Insights
- Running our vision model on the MediaTek Genio 520 CPU drove the chip to 78 to 84 C and past its passive throttle point in about a minute
- The same model on the NPU held 58 to 60 C on the same board, cool enough to run fanless
- Capping CPU usage does not solve it: if inference is already too slow, throttling only makes it slower
- Some embedded kernels do not expose a working CPU quota control at all, so that lever may not even exist
- On a fanless edge device, plan the thermal budget of your AI workload before integration, not after
## What overheating looks like
We ran our object detector on the Genio's CPU cores first, because that is the path of least resistance. Within about sixty seconds of real camera frames, the board was at 78 to 84 C. The passive design wants to throttle well below that, so the chip started slowing itself down to protect itself. Every core was pinned at maximum clock the whole time, drawing six to nearly eight cores' worth of load for a detector running at roughly two frames a second.
A throttling chip is the worst of both worlds. You are already too slow, and now the hardware makes you slower to keep from cooking. On a robot with no fan, in a warm room, this is not a demo you can leave running, let alone a product you can ship.
## Why you cannot throttle your way out
The instinct is to cap the CPU so it runs cooler. It does not work here, for two reasons. First, the model is already slower than the frame rate we want, so limiting cores just trades heat for even lower frame rate, and you still may not get under the thermal limit. Second, and this is the embedded twist, the kernel on this board did not expose a working CPU quota control at all, so the usual container-level cap was simply unavailable. The lever you reach for may not be there.
The workload is on the wrong processor. That is the actual problem, and cooling tricks only paper over it.
## The real answer
Moving the detection onto the Genio's neural accelerator dropped the board to 58 to 60 C doing the same job, cool enough to run without a fan while the camera and the rest of the stack ran alongside it. That is the headline: the NPU is not only faster, it is what makes on-device vision thermally possible on a passive board. We cover the speed side in [YOLOv8 on the Genio NPU](/blog/yolov8-mediatek-genio-npu).
If for some reason a workload has to stay on the CPU, then the honest options are a smaller, cheaper model and real cooling, a heatsink or a fan sized to the sustained load. Both are legitimate, and both are decisions you want to make early.
## The order of operations that saves months
The expensive mistake is discovering your thermal problem at integration time. The order that avoids it is: choose the board for its accelerator, confirm your model runs on that accelerator within your frame-rate and temperature budget, then design the enclosure and cooling around the load you measured. Teams that skip the measurement and assume the CPU will cope tend to find out in the enclosure, which is the most expensive place to find out.
Sizing an AI workload to a fanless board, on the MediaTek Genio or on NVIDIA Jetson, is exactly the kind of thing we characterize quickly because we have done it before. [Tell us what you are building](/contact) and we will tell you whether your model fits your board before you commit to the enclosure. For the robot this came from, see [the ROSOrin build overview](/blog/voice-controlled-robot-mediatek-genio).
---
## Getting an LD06 Lidar onto the MediaTek Genio
URL: https://proventusnova.com/blog/ld06-lidar-mediatek-genio-kernel-module/
Published: 2026-09-28
Author: Andres Campos
Tags: mediatek genio, lidar, embedded linux, yocto, robotics
The LD06 lidar got no device node on our MediaTek Genio: the vendor kernel had no driver for its USB-serial chip. Building the module, and the UART fallback.
A lidar that shows up on the USB bus but never becomes a serial port is a classic embedded dead end. Our LD06 lidar did exactly that on the MediaTek Genio's vendor kernel, and getting it working meant either adding a driver to a kernel we could not easily rebuild, or bypassing USB entirely. Here is the situation and both routes out.
## Key Insights
- The LD06 uses a CH340-class USB-serial chip that needs the ch341 driver, which the vendor kernel did not include
- Without the driver the lidar enumerated on USB but never got a serial device node, so the software found nothing to open
- The fix was to build the driver as an out-of-tree kernel module against the vendor kernel, which has a real gotcha around build options
- The alternative is to wire the lidar to a hardware UART on the carrier and skip USB, at the cost of a possible level shifter and sourcing 5 volts
- On a new board, assume some peripheral you need will be missing its driver, and plan time for it
## The dead end
The LD06 is a cheap, popular 360-degree lidar, and like a lot of inexpensive serial peripherals it talks over USB through a CH340-class serial chip. On a normal Linux system the ch341 driver claims that chip and hands you a serial port. The MediaTek Genio's vendor kernel, trimmed for the platform, did not include that driver. So the lidar enumerated on the USB bus, the kernel saw a device, and no serial port ever appeared. Software that tried to open the lidar's port found nothing there.
This is one of the most common surprises on a new embedded board. The hardware is fine, the sensor is fine, and a missing driver makes the whole thing invisible to your application.
## Route one: build the driver
The direct fix is to build the missing driver as an out-of-tree kernel module against the exact kernel on the board, then install it so it loads automatically. That sounds routine and has two real snags. First, you need the vendor's kernel headers and configuration to build a module that will actually load, and vendors do not always hand those over without a reason, so asking with a concrete need helps. Second, the module has to match the kernel's build options, and there is a specific trap around how the kernel handles module type information that will stop an otherwise-correct module from loading if you miss it. Once those line up, the driver loads at boot and the lidar becomes a normal serial port.
We keep the specifics of that build, the exact configuration and the trap, for the work we do, because it is precisely the kind of thing that turns a lost week into an afternoon when someone has hit it before.
## Route two: skip USB entirely
The other route is to not use the USB-serial chip at all and wire the lidar directly to a hardware UART on the carrier board. That removes the driver problem completely, because a hardware UART is a first-class serial port with no chip in between. The cost is on the electrical side. The board's UART may run at a different logic voltage than the sensor expects, in which case you need a level shifter so you do not feed the wrong voltage into a pin, and you have to find a 5-volt source on the carrier to power the sensor, since not every header provides one. It is more wiring and a meter check, and it sidesteps the kernel entirely.
Which route is right depends on whether you would rather own a kernel module or a bit of wiring, and on what your carrier board exposes.
## The takeaway
The real lesson is the one at the top: on a new board, budget for the fact that some peripheral you need will arrive with no working driver, and the failure will look like dead hardware rather than a missing piece of software. Recognizing that pattern fast is most of the fix.
Bringing up sensors and peripherals on a fresh board, MediaTek Genio or NVIDIA Jetson, is a large part of what we do, and it is where the schedule risk on a new platform lives. [Tell us what you are building](/contact) and we will get your sensors talking. For the whole robot, see [the ROSOrin build overview](/blog/voice-controlled-robot-mediatek-genio).
---
## Driving a Mecanum Robot from ROS 2
URL: https://proventusnova.com/blog/mecanum-robot-ros2-wheel-wiring/
Published: 2026-09-28
Author: Andres Campos
Tags: ros2, robotics, mecanum, mediatek genio, motor control
Our mecanum robot strafed sideways when told to go forward. The cause was a diagonal wheel pair wired backwards. How mecanum drive works and how to catch it.
We told our robot to drive forward and it slid sideways instead. Nothing was broken, in the sense that every motor turned and the code was correct. The wheels were simply not the wheels the software thought they were. Mecanum drives make this failure easy to hit, so here is how the motion works and how to catch the wiring when it goes wrong.
## Key Insights
- Mecanum wheels use angled rollers so the robot can drive forward, strafe sideways, or spin in place
- The drive code turns a desired forward, sideways, and rotational velocity into four individual wheel speeds, and that math depends on each wheel being in a known position
- If a diagonal wheel pair is wired backwards, a forward command resolves into a sideways one, which is exactly what we saw
- Diagnose by commanding one wheel at a time and mapping which physical wheel actually moves, then compare to what the code assumes
- The symptom tells you the fault: forward becoming a strafe points to a diagonal pair inverted
## How mecanum drive works
A mecanum wheel is a normal wheel with rollers set at an angle around its rim, so instead of pushing straight ahead it pushes at 45 degrees to its axle. Put four of them at the corners of a robot, each oriented correctly, and you can produce net motion in any direction by mixing their speeds. Spin them all forward and the robot goes forward. Spin one diagonal pair one way and the other pair the other way, and the robot strafes sideways without turning. Spin the left and right sides opposite each other and it rotates in place.
The drive code does the inverse of this. It takes the motion you want, a forward velocity, a sideways velocity, and a rotation, and solves for how fast and which direction each of the four wheels must turn. That solution is only correct if each wheel is where the code thinks it is and turns the direction the code expects.
## Why "forward" became "sideways"
Our robot had every motor working and still strafed on a forward command. That is the fingerprint of a specific fault: a diagonal pair of wheels wired backwards relative to what the code assumes. The forward and sideways cases in the mecanum math differ by exactly which diagonal is doing what, so swapping a diagonal pair rotates your commands ninety degrees. Forward comes out as a strafe. It looks like a deep control bug and it is a connector in the wrong place.
In our case the cause was mundane: the robot had been reassembled after painting, and the motor connectors came back one position off. Every wheel worked, none was where the driver expected.
## How to catch it
The diagnosis is simple once you suspect wiring. Command one wheel at a time and watch which physical wheel moves and in which direction. Build the real map of connector to wheel to spin direction, then compare it to the mapping the drive code assumes. The corrections are either at the connectors or in the configuration, whichever you would rather own.
A useful shortcut is the symptom rule. Forward turning into a strafe means a diagonal pair is inverted. A robot that spins when told to go straight means one side is reversed. The way the motion is wrong tells you where to look before you touch anything.
We keep the exact drive configuration and the wheel-mapping conventions for the projects we do, because those are specific to your chassis and motor controller. The reusable part, the one worth publishing, is that mecanum motion failures usually live in the wiring, not the math, and the symptom points straight at the fault.
If you are integrating a drive base with ROS 2, mecanum or otherwise, on the MediaTek Genio or on NVIDIA Jetson, [tell us what you are building](/contact) and we will get it moving in the right direction. For the whole robot, see [the ROSOrin build overview](/blog/voice-controlled-robot-mediatek-genio).
---
## MediaTek Genio vs Jetson for a ROS 2 Robot
URL: https://proventusnova.com/blog/mediatek-genio-vs-jetson-ros-robot/
Published: 2026-09-28
Author: Andres Campos
Tags: mediatek genio, nvidia jetson, ros2, robotics, edge ai
We built a ROS 2 robot on the MediaTek Genio. Here is how the Genio and NVIDIA Jetson actually compare for robotics, from first-hand experience on both.
We build robots on both the MediaTek Genio and NVIDIA Jetson, and our Embedded World robot ran on the Genio. So when a founder asks which one to choose for a ROS 2 robot, the answer comes from having shipped on both, not from a spec sheet. Here is the honest comparison, aimed specifically at robotics. For the broader edge-AI platform view, see our [MediaTek Genio versus NVIDIA Jetson Orin comparison](/blog/mediatek-genio-vs-nvidia-jetson).
## Key Insights
- Both platforms run ROS 2 well and both have a neural accelerator, so neither is disqualified for robotics
- Jetson brings the more mature robotics and AI ecosystem, with more examples, drivers, and community knowledge to lean on
- The Genio can win on power, thermals, cost, and supply, which matter a great deal for a battery-powered or price-sensitive product
- The two accelerators take different routes to inference, so a model that runs on one does not automatically run on the other
- The decision should be validated with your real vision and speech models, not made on datasheets alone
## Both are real robotics platforms
Start with the thing that is not in dispute: ROS 2 runs well on both, and both carry a dedicated AI accelerator so your vision and speech can run on-device rather than on the CPU. We run a complete ROS 2 Humble robot on the Genio, with camera, lidar, navigation, voice, and a mecanum drive, all at once. So this is not a case of one platform being for robots and the other not. It is a case of trade-offs.
## Where Jetson leads
Jetson's advantage is maturity. It has been the default for edge robotics and vision for years, and that shows up as a larger body of examples, more ready driver support for common sensors, and a deeper community you can search when you hit a wall. For a team that wants to move fast on well-trodden ground, that ecosystem is worth real money, because the time you do not spend solving already-solved problems is time you spend on your product.
## Where the Genio is compelling
The Genio's case is on the platform factors that a datasheet comparison of raw performance tends to undersell. Power efficiency and thermals matter enormously on a robot, where every watt is battery life and every degree is a fan you would rather not add. Cost matters when you are building more than a handful of units. And supply, the plain question of whether you can buy the part in the volume and timeframe you need, has decided more product platforms in the last few years than benchmarks have. On those axes the Genio can be the better answer, which is exactly why we built our demo robot on it.
## The accelerator is the real question
The place teams get surprised is the AI accelerator. The Genio and Jetson reach on-device inference by different routes, which means a model tuned for one does not simply drop onto the other. For a robot, the practical question is not which accelerator is faster in the abstract, it is whether your specific detector and your specific speech model convert cleanly and hit your frame rate and your thermal budget on the accelerator you choose. We have written about what that took on the Genio in [YOLOv8 on the Genio NPU](/blog/yolov8-mediatek-genio-npu). The lesson that transfers is to answer that question with your real models early, because it is the one most likely to move your decision.
## How to actually decide
Weigh ecosystem maturity, where Jetson leads, against power, thermals, cost, and supply, where the Genio often does, and then validate the choice by running your real workload on the real accelerator before you commit. That last step is the one teams skip and regret. We do it for clients on both platforms, so the platform decision is made on measured fact rather than a hopeful reading of a datasheet.
If you are choosing a compute platform for a robotics or vision product and want that decision grounded in your actual models, [tell us what you are building](/contact) and we will help you choose with evidence. For the robot behind this, see [the ROSOrin build overview](/blog/voice-controlled-robot-mediatek-genio).
---
## The WiFi Bug That Almost Killed Our Booth Demo
URL: https://proventusnova.com/blog/mt76-wifi-txpower-reporting-bug/
Published: 2026-09-28
Author: Andres Campos
Tags: mediatek genio, wifi, mt76, embedded linux, debugging
Our robot's WiFi hotspot looked capped at 3 dBm. It was a cosmetic mt76 driver reporting bug: the radio runs at full power. How to verify before you panic.
Two days before a trade show, our robot's built-in WiFi hotspot looked broken. The tools reported it was transmitting at 3 dBm, a level so low that a tablet a few feet away should barely see it. We nearly bought hardware to work around it. It turned out the radio was fine and the number was a lie. Here is the story, because you will hit this exact one.
## Key Insights
- The tools reported the robot's WiFi transmitting at 3 dBm, which looks like a crippling power cap
- It was a cosmetic reporting bug in the mt76 driver family, not a real limit; the radio transmitted at normal power the whole time
- We confirmed the real transmit power through the driver's own debug interface: roughly 13 to 16 dBm while the tool said 3
- The lesson is to verify actual transmit power at the driver level before you conclude you have a hardware or firmware cap
- Believing the wrong number nearly cost us money and time on a fix for a problem that did not exist
## The scare
The robot runs its own WiFi hotspot so a tablet can drive it and show its camera at a booth. During setup, every tool agreed the access point was transmitting at 3 dBm. That is roughly two milliwatts, and at a busy exhibition with hundreds of competing radios, it would mean the tablet loses the robot the moment you step back. Worse, trying to raise the power with the usual command did nothing: the setting refused to stick on readback, which is exactly what a firmware-locked regulatory cap looks like.
So the working theory became "this radio is region-locked to almost no power, we need a separate WiFi dongle or a travel router." That is a real cost and a real point of failure to carry to a show. Before committing to it, we checked whether the number was even true.
## The number was lying
The MediaTek WiFi driver family, mt76, has a known quirk: it does not always update the transmit-power value that the standard tools read back. So the tool reports whatever stale or default number it has, often a bogus low one, while the radio is actually transmitting at the correct regulatory power. The "won't stick" behaviour when you try to set it is the same bug, not a lock.
We did not take that on faith either. The driver exposes the real per-rate transmit-power table through its own debug interface, and that is the number that reflects what the hardware is actually doing. It showed the radio transmitting at roughly 13 to 16 dBm across the relevant rates, while the standard tool insisted on 3. The radio was at normal power the entire time. The hotspot worked at booth range once we stopped chasing a cap that was not there.
## The lesson
When a radio reports a suspiciously low or oddly unchangeable transmit power, do not believe it and do not buy hardware to fix it until you have checked the real value at the driver level. The reported number and the transmitted number are not always the same thing, and on this driver family they routinely are not. Verifying the truth takes minutes; acting on the lie costs days and sometimes a hardware order.
This is a small story with a large moral for anyone shipping on embedded WiFi: your telemetry can be wrong, and a wrong number that happens to match a scary explanation is the most dangerous kind. The habit that saves you is confirming the physical reality before you design around the readout.
If you are bringing up WiFi, or any radio, on a MediaTek Genio or another embedded platform and you want someone who has already met the driver's quirks, that is the kind of thing we sort out quickly. [Tell us what you are building](/contact). For the robot this came from, see [the ROSOrin build overview](/blog/voice-controlled-robot-mediatek-genio).
---
## Building a Tablet Cockpit for a Robot
URL: https://proventusnova.com/blog/robot-tablet-dashboard-pwa/
Published: 2026-09-28
Author: Andres Campos
Tags: robotics, mediatek genio, dashboard, pwa, debugging
Our robot's tablet dashboard froze on one device: camera live, everything else dead. A single unsupported browser call had halted the page. The field-UI lesson.
The dashboard that drives our robot has to run on whatever tablet is on hand, which is a harder requirement than it sounds. Two days before a show, it froze on the demo tablet in the most confusing way possible: the live camera worked and nothing else did. The cause is a great lesson in building interfaces for devices you do not control.
## Key Insights
- The robot serves its own installable web dashboard: a first-person camera view, a joystick, a live lidar radar, and voice, with no cloud
- On one tablet the page froze with the camera live but every button and readout dead
- The cause was a single unsupported browser call early in startup that threw and halted everything scheduled after it
- Parts set up before the failing call kept working, which is why the symptom looked so strange
- A field-ready UI guards modern browser features, wraps its draw loops, and limits live connections so one failure cannot take the page down
## What the cockpit is
We built the robot's operator interface as a web app the robot serves itself. Any tablet or phone on the robot's network loads it, and it can be installed to the home screen so it feels like a native app. It shows a first-person camera view with a joystick for driving, a live radar scope drawn from the lidar so the operator can see obstacles around the robot, and voice controls. Serving it from the device means it needs no app store and no internet, only the robot.
## The freeze
At setup, the dashboard came up on the demo tablet with a working camera feed and nothing else. The drive joystick did nothing, the telemetry never updated, the command buttons were dead. It was not the network, because a laptop on the same connection showed everything working. It was not the camera streams competing for bandwidth, because the heaviest thing on the page, the video, was the part that worked.
The way we found it was to log what the tablet actually requested. It asked for the page and the camera feed, and it never asked for telemetry and never sent a single button press. That pointed straight at the cause: the page's startup script had thrown an error partway through, so everything it tried to set up after that point simply never happened.
## The cause
The lidar radar drew its sweep using a modern browser drawing call that the tablet's older browser did not support. The first time the page tried to draw the radar, that call threw. Because it threw during the page's initialization, everything scheduled after it, the telemetry stream, the live status, the buttons, the joystick, never got wired up. Everything before it, the camera feeds and a health check, had already been set up and kept working. That is why the symptom was so lopsided: a live camera on top of a completely dead control panel.
## The lesson: build for devices you do not control
The fix was to stop assuming the browser. Guard the modern drawing call before using it so an unsupported feature is skipped rather than fatal, wrap the drawing loop so a failure inside it cannot halt the rest of the page, and be economical with live connections, because a thin wireless link and an older browser both have hard limits on how many simultaneous streams they will hold. With those in place the dashboard degrades gracefully instead of dying, and it works on whatever tablet is at the booth.
The general principle is the one in the heading. A dashboard that only runs on your development machine is not done. A field UI has to survive an unknown, possibly old browser on an unknown network, and that means defensive initialization so that no single unsupported feature can take the whole interface down.
We keep the implementation details for the projects we do, because they depend on your stack. The reusable insight is to treat the operator's device as hostile terrain and build the UI to tolerate it.
If you are building operator interfaces for robots or edge devices that have to run anywhere, [tell us what you are building](/contact). For the robot this drives, see [the ROSOrin build overview](/blog/voice-controlled-robot-mediatek-genio).
---
## ROS 2 Across Containers: the Fast DDS Gotchas
URL: https://proventusnova.com/blog/ros2-fast-dds-containers-genio/
Published: 2026-09-28
Author: Andres Campos
Tags: ros2, fast dds, docker, mediatek genio, robotics
Our containerized ROS 2 robot froze in ways that made no sense. The cause was DDS transport across container boundaries. The two settings that fixed it.
The most confusing bugs in a containerized ROS 2 system are the ones where everything looks connected and nothing works. Our robot had two of them, and both came down to how Fast DDS moves messages across container boundaries. Here is what happened and the two settings that fixed it, so you can recognize the shape before it costs you a day.
## Key Insights
- ROS 2's Fast DDS prefers shared memory between nodes, and separate containers do not share that memory namespace by default
- The fix is a shared IPC namespace for the containers that need to talk, which restores the fast shared-memory transport
- DDS also binds to network interfaces by default, and on one board that is a liability, because a changing address staled our locators and wedged all topic traffic
- Restricting discovery and transport to loopback fixed it, because every node was on the same board anyway
- Commands appearing to arrive while nothing moves is a classic sign that one transport is broken while another still works
## Gotcha one: shared memory needs a shared namespace
Running each ROS 2 node in its own container is the right call for a product. It also quietly breaks an assumption Fast DDS makes. For speed, DDS tries to pass messages between local nodes through shared memory rather than the network stack. Two nodes in the same container share that memory naturally. Two nodes in separate containers do not, unless you arrange for them to share the relevant namespace.
Miss it, and you get a maddening state: the nodes discover each other, the topics show up, and yet data does not move the way it should. The fix is to give the containers that need the fast path a shared IPC namespace so the shared-memory transport works across the boundary. Knowing this exists is most of the battle; it is invisible once set and baffling until you know to look.
## Gotcha two: DDS binds to interfaces that move
The second one bit us at the worst time. Our robot brings up its own WiFi access point for a booth tablet, which changes the address on its wireless interface. Fast DDS, by default, binds to the network interfaces it finds. When the access point came up and the interface address changed, the DDS locators went stale, and all topic traffic between the containers wedged.
The tell was that the robot's command buttons still seemed to work, because a separate direct loopback path delivered them, while the camera and telemetry, which ride the DDS topics, froze solid. Commands arriving while nothing happens is the signature of one transport alive and another dead.
The fix, since every node runs on the same board, was to restrict ROS 2 discovery and transport to loopback. Once DDS stopped caring about the wireless interface entirely, the changing address could not stale anything, and the traffic flowed even while the access point was up.
## The general lesson
Both gotchas share a root: the DDS defaults are tuned for nodes spread across a network, and a single-board robot with containerized nodes is a different world. On one board, you want the fast local path between containers and you want DDS to ignore the network interfaces whose addresses can shift under it. Set those two things and a whole category of intermittent, transport-level failures disappears.
We have kept the exact configuration out of this post, because the valuable part for your team is knowing these two failure modes exist and what causes them, not a snippet that changes with your topology. Getting the transport right for your specific system, one board or many, is the work we do.
If your ROS 2 system stalls in ways that do not make sense, on the MediaTek Genio or on NVIDIA Jetson, that is exactly the kind of thing we untangle quickly. [Tell us what you are building](/contact). For the wider stack this came from, see [running ROS 2 on the MediaTek Genio](/blog/ros2-mediatek-genio) and [the ROSOrin build overview](/blog/voice-controlled-robot-mediatek-genio).
---
## Running ROS 2 on the MediaTek Genio
URL: https://proventusnova.com/blog/ros2-mediatek-genio/
Published: 2026-09-28
Author: Andres Campos
Tags: mediatek genio, ros2, robotics, yocto, docker, edge ai
ROS 2 runs well on the MediaTek Genio, and containers on a custom Yocto image make it reproducible. What the stack looks like and the gotchas to expect.
People are often surprised that ROS 2 runs cleanly on a MediaTek Genio. It does. Our ROSOrin robot runs a full ROS 2 Humble stack on a Genio 520: speech, vision, lidar, navigation, and a mecanum drive, all at once. This post is the honest lay of the land, what the stack looks like and where the friction actually is, so you can plan around it.
## Key Insights
- ROS 2 Humble runs well on the MediaTek Genio 520, driving a complete robot with vision, lidar, and motion together
- We run each ROS 2 node as a Docker container on a custom Yocto image, which is what makes the build reproducible across boards and reflashes
- ROS 2 itself is rarely the hard part; the friction is peripherals, device access into containers, and cross-container communication
- Getting ROS 2 nodes in separate containers to talk efficiently needs deliberate configuration, and skipping it produces confusing failures
- The Genio is a credible robotics compute platform, and the AI accelerator is a real reason to consider it over a CPU-only board
## Yes, and here is the shape of it
ROS 2 Humble on the Genio behaves like ROS 2 anywhere: the nodes, topics, and tooling are the same. What differs on an embedded target is how you package and ship it. We run each part of the robot, the camera driver, the object detector, the speech pipeline, the brain that decides what to do, the motor server, and the dashboard, as its own container.
Those containers are baked into a **custom Yocto image**. That choice is what turns a demo into something you can reproduce. A Yocto image rebuilds identically, boots the same way every time, and can be flashed onto the next board without a day of manual setup. For a product, that reproducibility is not a nicety, it is the whole game.
## Where the friction actually is
The surprising thing about bringing ROS 2 up on a new board is how little of the trouble is ROS 2. In our build the time went to three things, and they will be the same three on your board.
**Peripherals and their drivers.** Cameras, lidar, microphones, and motor controllers each have to enumerate reliably and survive reboots. On a new board that is where the days go, and the failures are rarely where you first look. We have separate write-ups on the ones that cost us the most, because they are the parts nobody documents.
**Getting devices into containers.** Running nodes in containers is the right call, and it means every physical device has to be presented into the right container correctly and stay stable across restarts. This is a solvable, well-understood problem, and it is easy to get subtly wrong in a way that only shows up under load.
**Cross-container communication.** This is the one that bites hardest. ROS 2 nodes in separate containers on the same board have to be able to talk to each other efficiently, and the defaults are not always what you want when everything is local. Set it up correctly and it is invisible; set it up naively and you get intermittent, baffling stalls where messages seem to arrive but nothing happens. It has a clean answer, and it is worth knowing before you hit it rather than after.
## What we are not putting in this post
You will notice this is not a step-by-step. That is deliberate. The commands to stand up ROS 2 on a Genio are not the valuable part, and they change with every image and SDK version. The valuable part is knowing which choices matter, where the schedule risk is, and how to avoid spending a month learning the same three lessons. That is the work we do, and it is the part worth a conversation.
## If you are choosing a robotics platform
The Genio is a serious option for a robotics or vision product, and the reason to reach for it over a CPU-only board is the neural accelerator, which is where the AI has to run to be fast and cool enough to ship. We cover that in [YOLOv8 object detection on the Genio NPU](/blog/yolov8-mediatek-genio-npu) and [Whisper speech-to-text on the Genio NPU](/blog/whisper-mediatek-genio-npu).
If you are standing up ROS 2 on a MediaTek Genio or on NVIDIA Jetson and want to skip the month of integration lessons, that is exactly what we do on a fixed timeline. [Tell us what you are building](/contact) and we will tell you the fastest path to a working result. For the robot this all came from, see [the ROSOrin build overview](/blog/voice-controlled-robot-mediatek-genio).
---
## When a USB Camera Browns Out Your Edge Board
URL: https://proventusnova.com/blog/usb-camera-brownout-edge-board/
Published: 2026-09-28
Author: Andres Campos
Tags: mediatek genio, usb, embedded linux, debugging, camera
A depth camera kept crashing our MediaTek Genio robot. It was not the camera or the USB hub, it was current. How we found it, and the rule that saved the build.
One of the most expensive kinds of bug in embedded work looks like a flaky cable and is actually physics. On our MediaTek Genio robot, a depth camera would enumerate, stream for a moment, and then take the whole board down. It looked random. It was not. It was current, and the path to proving that is worth telling because you will meet this bug on your own build.
## Key Insights
- A USB camera that works on one port and dies on another is almost always a current problem, not a data or driver problem
- USB power descriptors routinely lie; the kernel budgets on those numbers, so a peaky device gets no headroom and browns out
- The signature was a chain reaction: the camera's illuminator turned on, a neighbouring device dropped, then the camera itself disconnected
- No over-current message ever appeared, which is exactly why teams chase the wrong layer for days
- The fix is a power layout that supplies the peak current cleanly, and the right layout is specific to the board
## The symptom
The camera behaved differently on the two USB ports of the board, and neither was reliable in the obvious way. On one port it streamed. On the other it delivered a single frame, reset a few seconds later, then failed to open ever again with the same error repeating forever. Move it, and the pattern moved with it. Add a hub, and new variations appeared. It had every appearance of a bad cable or a driver bug, and it was neither.
## The tell
The breakthrough was watching the order of events, not the error messages. The sequence was always the same. The camera's driver opened the device, which turned on its infrared projector. About a second later, the other high-speed device sharing that rail dropped off the bus. About a second after that, the camera itself disconnected and re-enumerated. Then nothing.
That is not a data fault, that is a power sag. The projector's inrush pulled the rail down far enough to knock out its neighbour first, then itself. And there was never an over-current message, because nothing on the board thought it was over-current: the devices had declared tiny power needs in their descriptors, one even claiming to be self-powered while drawing from the bus, so the kernel had budgeted almost nothing and had no reason to complain.
That last part is the trap. The system tells you everything is fine right up until the board reboots.
## The lesson, and the rule
The fix in principle is simple: supply the peak current through a path that can actually deliver it, and keep the hungry, peaky device away from shared power with anything sensitive. In our case that meant a specific layout using an externally powered hub feeding its own 5 volts, with the camera on the strong rail and the other peripherals arranged so nothing shared a rail with the projector's inrush. Once the power path could source the peak, the whole class of failures disappeared, and the board ran for reboots on end with everything attached.
The exact layout that works is specific to your board's ports, rails, and controllers, and finding it is a matter of characterizing where the current can actually flow. We keep that part, the specific working layout and how we arrive at it, for the projects we do, because it is the engineering, not the anecdote.
## Why this costs teams weeks
This bug is expensive because every instinct points the wrong way. The error text implicates the camera or its driver. The intermittency implicates a cable. The absence of an over-current warning implicates anything but power. Teams rewrite drivers and swap hardware for days before they think to watch the timing and suspect the rail.
If you are integrating cameras, illuminators, lidar, or any peaky USB peripheral onto an edge board, on the MediaTek Genio or on NVIDIA Jetson, the power layout is worth getting right before it costs you a sprint. That characterization is exactly the kind of thing we do quickly because we have seen it before. [Tell us what you are building](/contact) and we will save you the week. For the robot this came from, see [the ROSOrin build overview](/blog/voice-controlled-robot-mediatek-genio).
---
## Voice-to-Wheels: Turning Speech into ROS 2 Motion
URL: https://proventusnova.com/blog/voice-control-ros2-robot/
Published: 2026-09-28
Author: Andres Campos
Tags: ros2, voice control, robotics, mediatek genio, edge ai
Routing every spoken command through an LLM made our robot slow and wrong. A rule layer in front of the model fixed both. How we structured voice control.
A robot you control by voice lives and dies on two numbers: how long from speaking to moving, and how often it does the wrong thing. Our first version was slow and occasionally wrong, and the fix was not a better model, it was a better structure. Here is how we ended up building voice-to-wheels.
## Key Insights
- The voice chain is speech-to-text, then intent, then a ROS 2 motion command, and on our robot all of it runs on-device
- Routing every command through a language model was both slower and occasionally wrong, for example mapping "move forward" to a sideways strafe
- A deterministic rule layer for the known command vocabulary runs instantly and reliably, with the model kept only as a fallback for open phrasing
- Safety commands like stop need their own fast path that bypasses transcription entirely
- The right structure matters more than the model choice for a responsive, trustworthy voice interface
## The naive version, and why it disappoints
The obvious design is a pipeline: transcribe the speech, hand the text to a small on-device language model to figure out what the person meant, and send the resulting action to the robot. It works, and it disappoints in two specific ways.
It is slow, because the language step adds one to three seconds on top of transcription for even a trivial command. And it is occasionally wrong in ways that feel dumb to a user: our model would take "move forward" and produce a sideways strafe, or take "come here" and produce nothing. When a person says a plain command and the robot does something odd, the whole thing feels broken, no matter how clever the model is elsewhere.
## The fix: a rule layer in front of the model
The insight is that the commands that matter most for a demo or a product are a small, known vocabulary: stop, forward, back, turn, follow, play. Those do not need a language model at all. We put a deterministic rule layer in front of the model that resolves the known vocabulary directly, in effectively zero time, and only hands the sentence to the language model when nothing in the rules matches.
That single change fixed both problems. The core commands became instant and correct, because they no longer depended on a model guessing at them, and the language model was reserved for the open-ended phrasing it is actually good at. The user-facing result is a robot that responds to plain commands immediately and predictably, which is the whole point.
## Stop is special
There is one more structural rule worth stating on its own: a safety command cannot wait in line. On our robot a spoken "stop" that went through the full transcription pipeline took several seconds, which is far too long when the robot is moving toward a table edge. So stop got its own path that bypasses transcription entirely and publishes the halt directly, alongside a dedicated stop control on the dashboard. The direct path responds in well under a tenth of a second versus seconds for the spoken route. When it matters, you use the fast path.
The general principle: the more important and time-critical a command is, the fewer stages it should have to pass through.
## What we keep for a conversation
This post is the shape of the design, not the implementation. The reason is that the interesting decisions for your product, where the rule layer ends and the model begins, how the intent maps to your specific actions, how you keep it responsive on your hardware, are judgement calls we make with you, not a snippet to paste. Structuring a voice interface that is fast and trustworthy on-device is the work we do.
If you are building voice or command interfaces on an edge robot or device, on the MediaTek Genio or on NVIDIA Jetson, [tell us what you are building](/contact) and we will help you get the structure right. For the speech model behind this, see [Whisper on the Genio NPU](/blog/whisper-mediatek-genio-npu), and for the whole robot, [the ROSOrin build overview](/blog/voice-controlled-robot-mediatek-genio).
---
## Voice-Controlled Robot on the MediaTek Genio: the ROSOrin Build
URL: https://proventusnova.com/blog/voice-controlled-robot-mediatek-genio/
Published: 2026-09-28
Author: Andres Campos
Tags: mediatek genio, robotics, ros2, edge ai, npu, embedded world
We built a voice-controlled, self-driving robot on the MediaTek Genio and demoed it at Embedded World NA. The stack, the on-NPU AI, and what it took.
At Embedded World North America this year we walked the floor with a robot small enough to hold in one hand. You could tell it to follow you, drive it from a tablet, or set a ball down and watch it play. Everything it did ran on a single MediaTek Genio 520, offline, with no cloud behind it.
We call it ROSOrin. This post is the overview of what it is and what it took to build. The deep dives on each part link out from here.
Watch the demo from the show floor:
## Key Insights
- ROSOrin runs voice control, person and ball detection, navigation, and driving on one MediaTek Genio 520, fully offline
- The two AI workloads that matter, speech-to-text and object detection, both run on the Genio NPU, not the CPU
- Moving object detection from the CPU to the NPU took it from unusable to real-time, and dropped the board temperature enough to run fanless
- The software is ROS 2 in a container stack on a custom Yocto image, which is what makes the whole thing reproducible instead of a one-off demo
- The hard parts were rarely the parts you would expect, and that is the theme of every deep dive below
## What the robot does
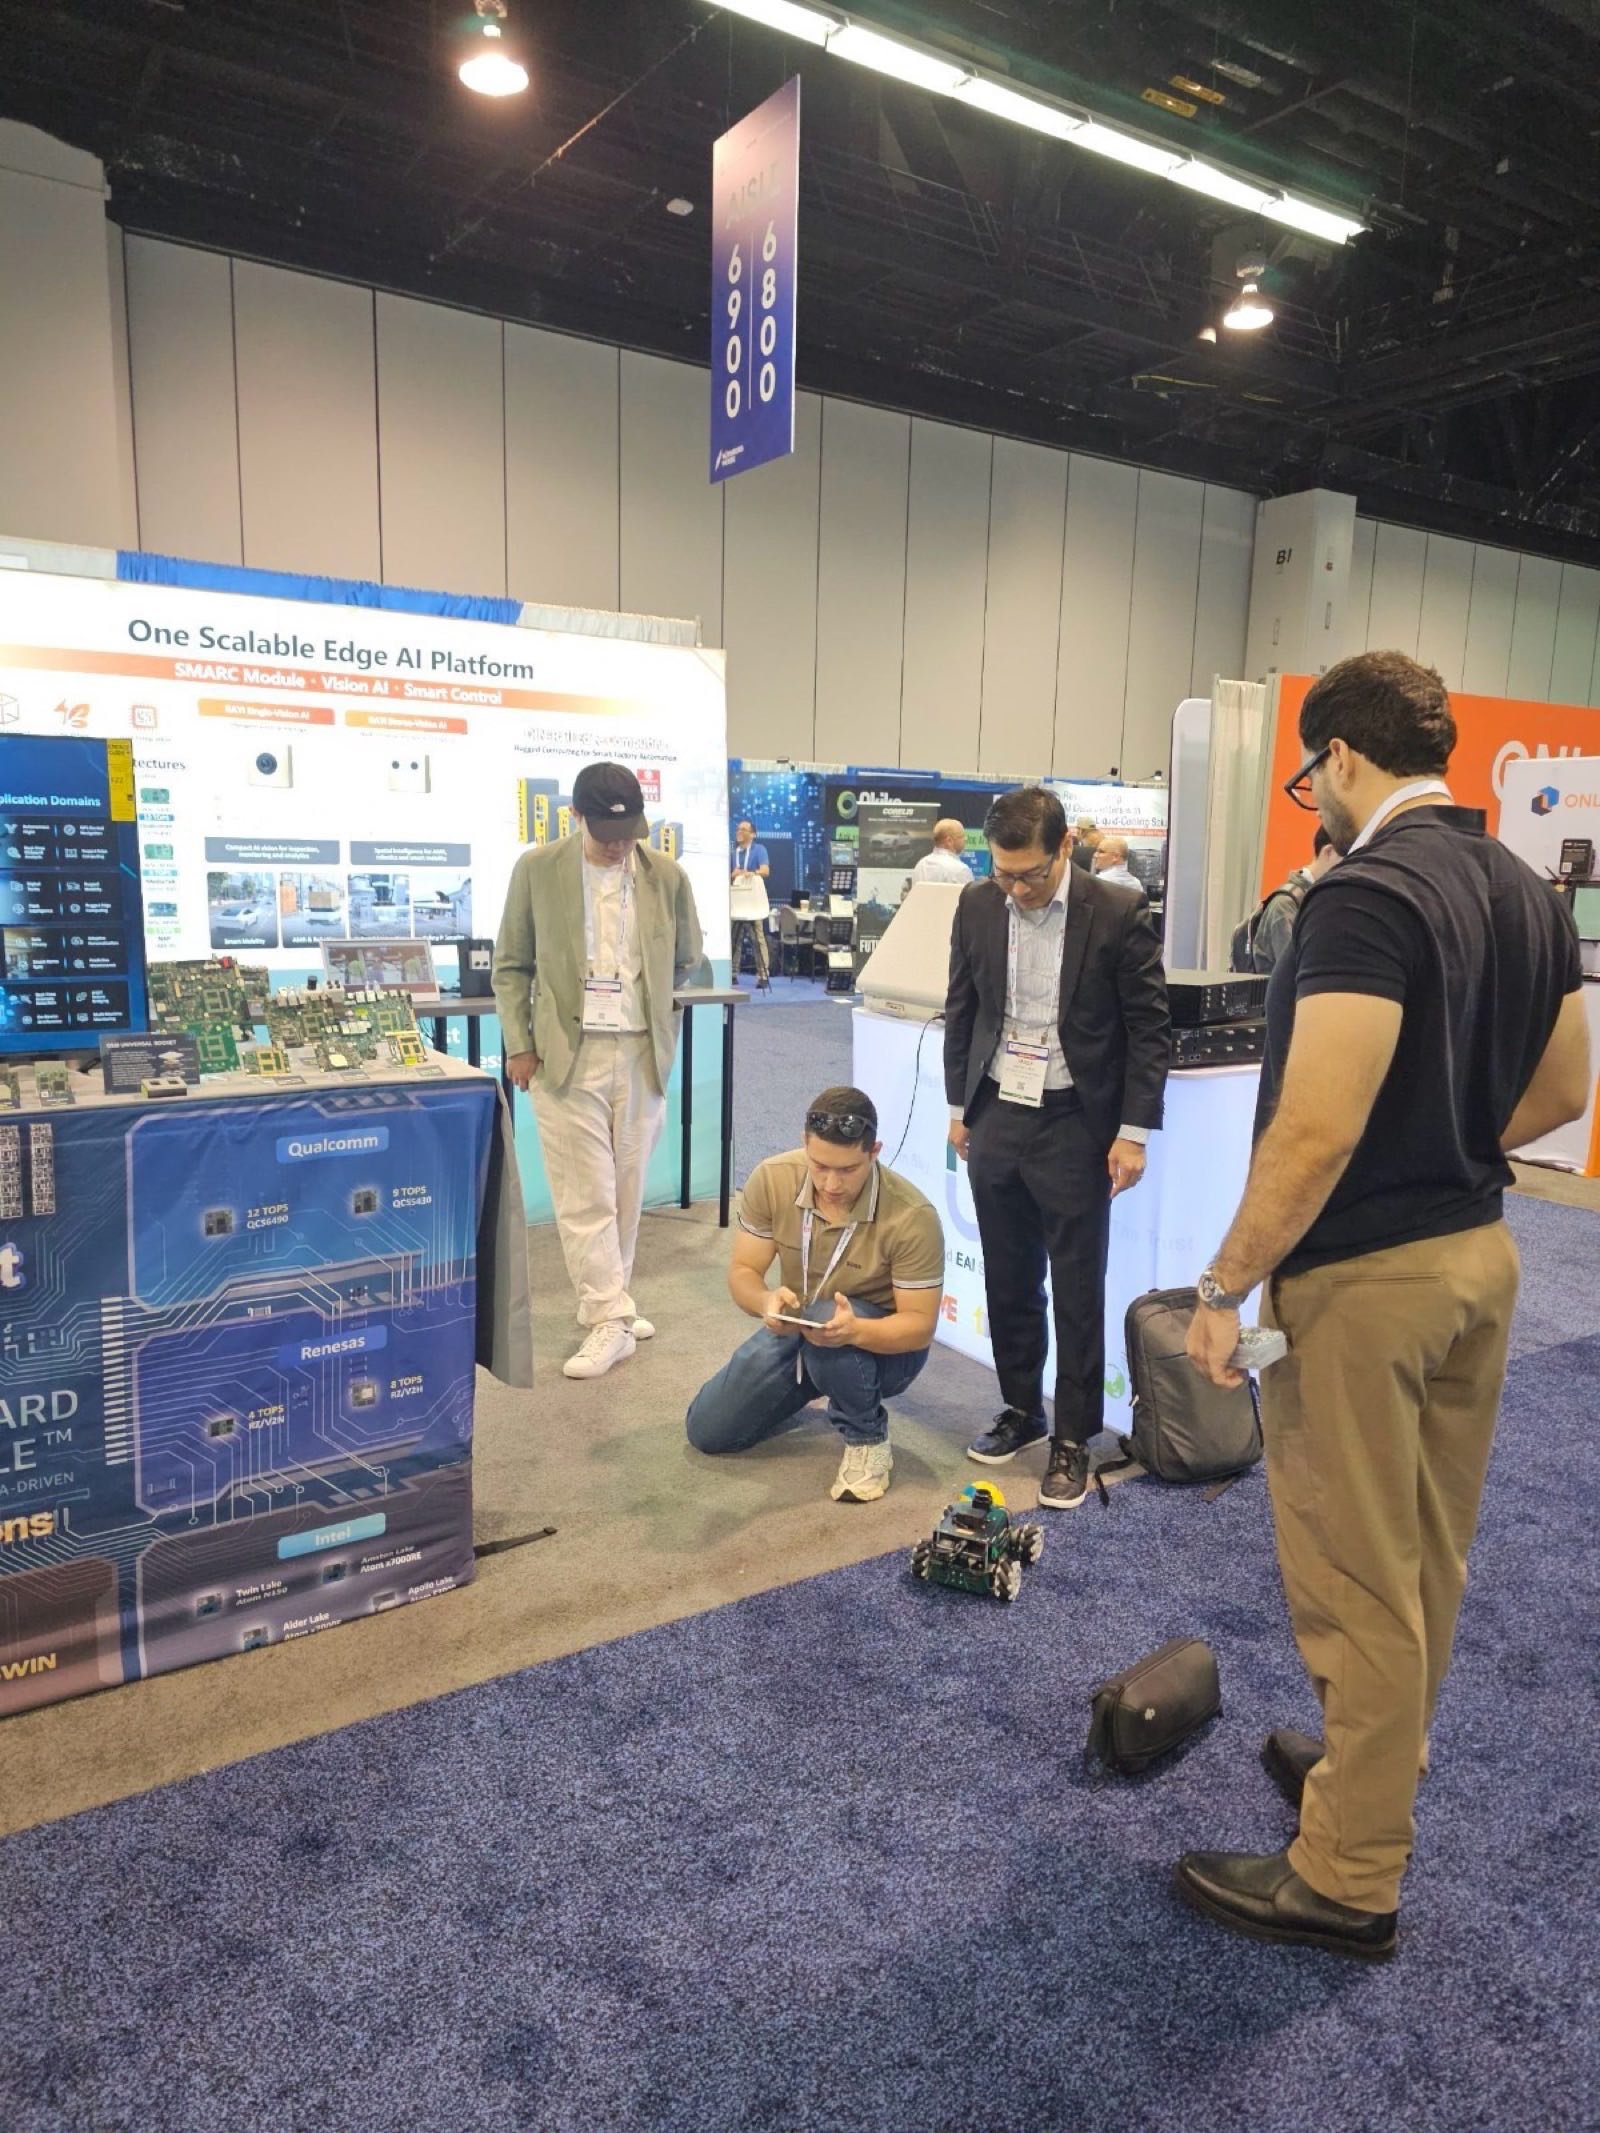
You speak to it. "Follow me", "move forward", "turn left", "stop", "let's play". A microphone on the robot turns your voice into text, a small on-device language step turns that text into an action, and the wheels respond. No phone app, no server, no internet.
It sees. A depth camera feeds an object detector that finds people and a ball. In floor mode it can follow a person or chase the ball. In table mode it stays put and just turns to keep you in frame, so it can sit on a stand at a booth and never drive off the edge.
You can also drive it yourself. A tablet loads an installable dashboard, a first-person camera view with a joystick, plus a live radar scope from the lidar so you can see what the robot sees around it.
And it holds still until told otherwise. A trade-show robot that wanders on its own is a liability, so the default is passive: it does nothing until a voice command or the dashboard engages it.
## The stack, in one picture
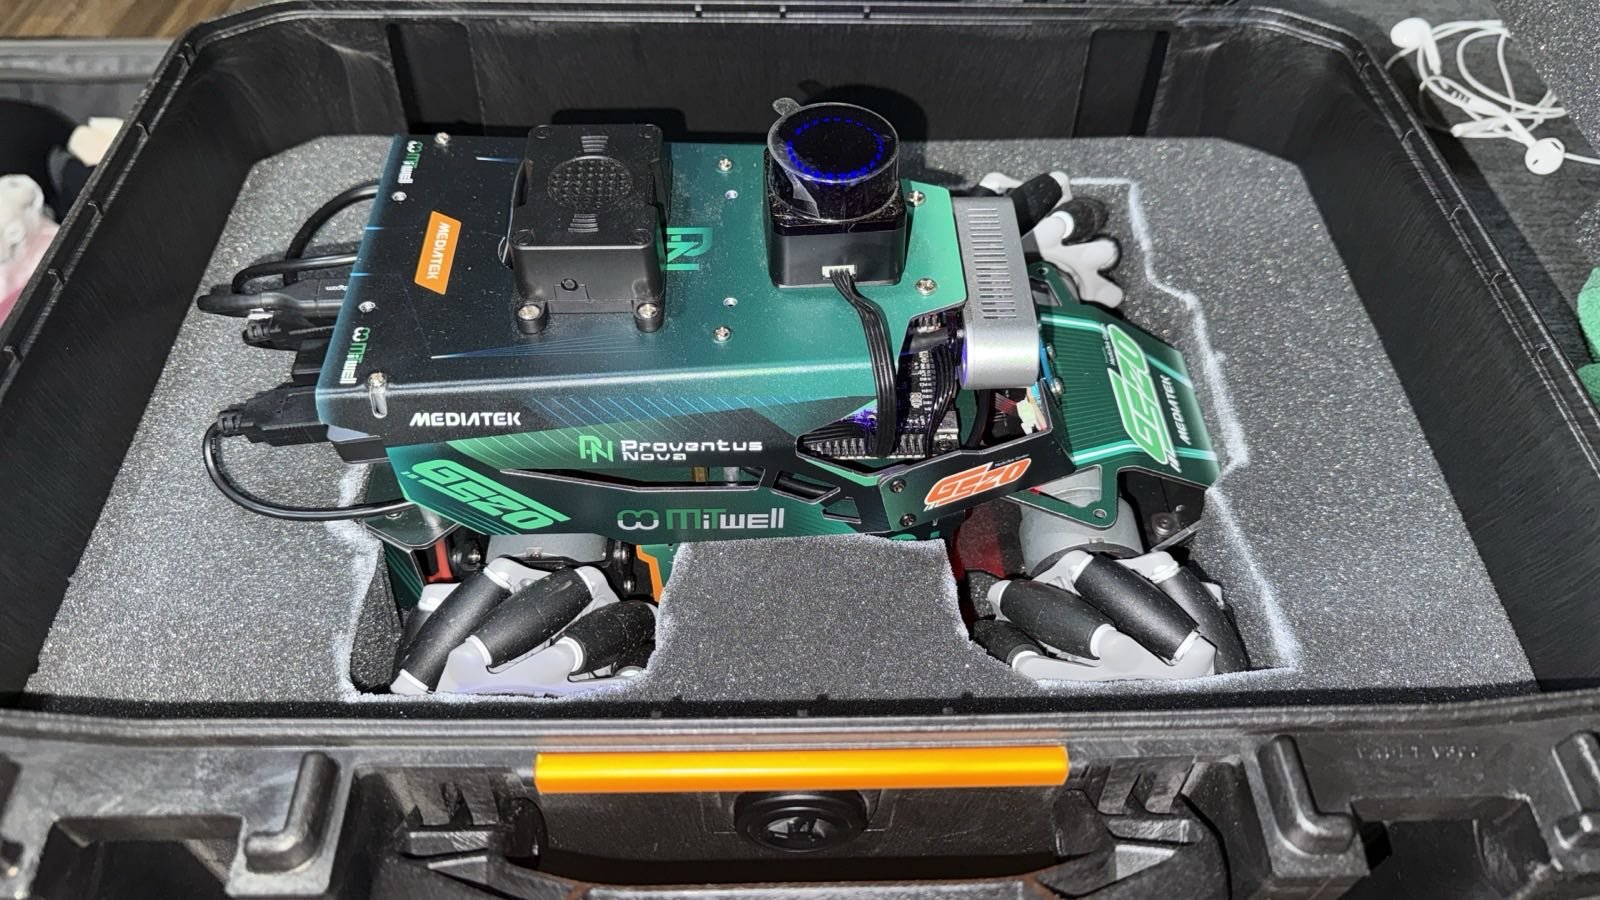
- **Compute:** a MediaTek Genio 520 on a MiTwell PicoITX board, our partner hardware for this build.
- **AI on the NPU:** speech-to-text and object detection both run on the Genio's neural accelerator. This is the difference between a demo that works and one that overheats. See [running YOLOv8 object detection on the Genio NPU](/blog/yolov8-mediatek-genio-npu) and [Whisper speech-to-text on the Genio NPU](/blog/whisper-mediatek-genio-npu).
- **Software:** ROS 2 Humble, running as a set of Docker containers on a custom Yocto image. See [running ROS 2 on the MediaTek Genio](/blog/ros2-mediatek-genio).
- **Sensing and motion:** an LD06 lidar for 360-degree awareness, a depth camera for vision, and a mecanum drive that can move in any direction.
## What it actually took
The interesting part of a build like this is never the block diagram. It is the week you lose to a camera that browns out the whole board, the driver bug that makes your booth WiFi look dead when it is fine, and the AI model that runs at three frames per second until you move it onto the right silicon.
We wrote those stories up, because they are the parts nobody publishes and the parts that actually decide whether an edge AI product ships. Each one names the problem and the point in the build where it bites. The exact fix is the work we do for clients, so we keep that part for a conversation.
## Embedded World North America
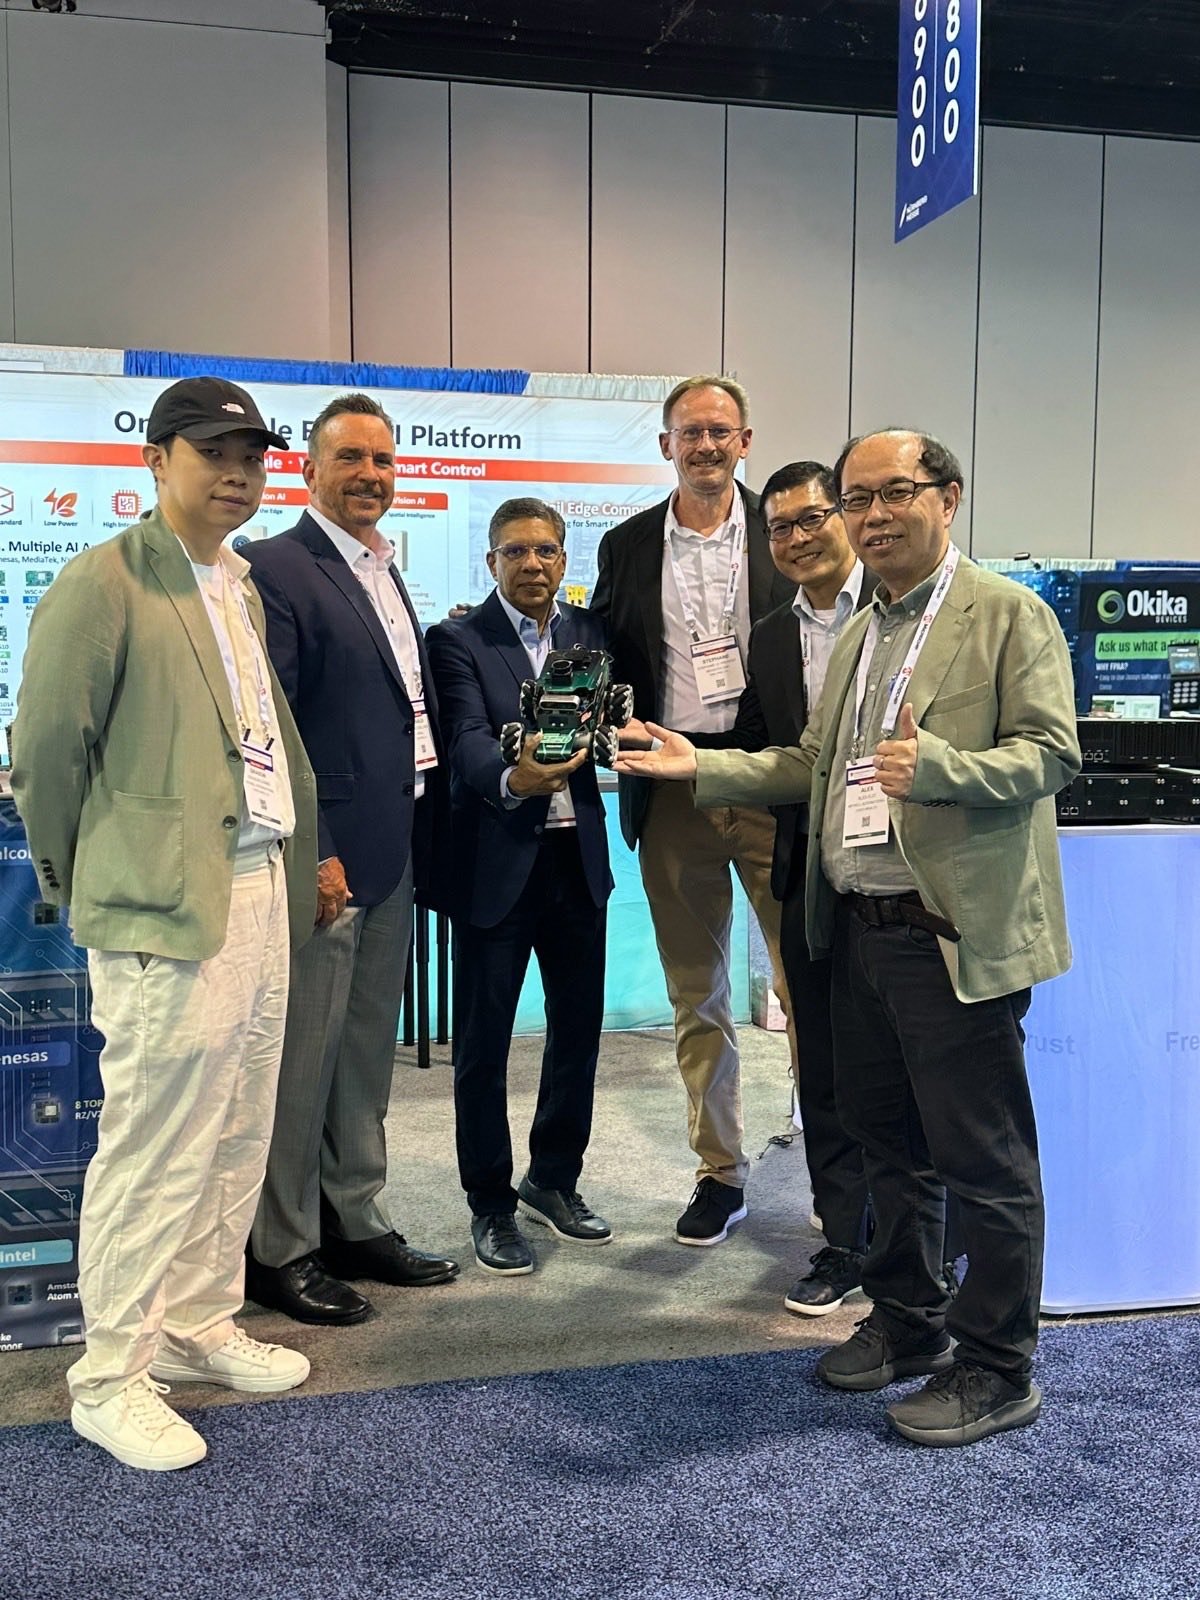
We showed ROSOrin at the MiTwell booth alongside MediaTek, the two partners behind the platform. It drew a crowd, which was the point: a hand-sized robot doing real on-device speech and vision is a good way to make "edge AI on the Genio" concrete for a founder who is deciding what to build their product on.
If you are building a computer-vision or robotics product on the MediaTek Genio or on NVIDIA Jetson and you want it to run real AI on-device, that is exactly the work we do. [Tell us what you are building](/contact) and we will tell you the fastest path to a working result.
---
## Whisper Speech-to-Text on the MediaTek Genio NPU
URL: https://proventusnova.com/blog/whisper-mediatek-genio-npu/
Published: 2026-09-28
Author: Andres Campos
Tags: mediatek genio, npu, whisper, speech to text, edge ai, voice control
We ran Whisper on the MediaTek Genio NPU for offline robot voice control, using only the stock on-device runtime. What it takes, and the latency reality.
We wanted our robot to take spoken commands with no phone, no server, and no internet. That means speech-to-text has to run on the robot. Here is what it took to put Whisper on the MediaTek Genio's neural accelerator, and an honest account of the latency, because that part is more interesting than the headline.
## Key Insights
- Whisper runs on the MediaTek Genio 520 NPU using only the on-device runtime that ships in the image, with no extra runtime libraries on the target
- Speech-to-text happens fully offline, which is the point for a robot, a kiosk, or any product that cannot depend on a network
- With a Whisper-medium model, the encoder runs in about 1.5 seconds and a short command is 6 to 9 seconds to transcribe
- End to end, from speaking to the robot moving, is about 8 to 13 seconds, and lowering that is a tuning problem, not a hardware one
- The accelerator gets you on-device speech at all; the latency you actually ship is decided by model choice and how the model is served
## Why on-device speech, and why the NPU
Cloud speech recognition is easy and it is the wrong choice for a lot of edge products. A robot at a trade show, a device in a vehicle, a product that handles anything sensitive: all of them need to keep working when the network does not, and some of them cannot send audio off the device at all. That pushes speech-to-text onto the device.
Whisper is a strong model for this, and it is heavy. Running it on the Genio's CPU is possible but competes with everything else the robot is doing. The neural accelerator is the right home for it, the same way it is for vision.
## What we did, and what it took
We run a Whisper model on the Genio NPU and it drives the robot's voice control directly: you speak, the robot transcribes on-device, an on-device step maps the words to an action, and the wheels respond. No cloud is involved at any point.
The part worth calling out is that this runs on the **stock on-device runtime** already present in the Genio image. You do not need to install a separate accelerator runtime on the target to execute the model. That keeps the deployment clean: the device ships with what it needs to run inference.
Getting a model into the form the accelerator loads is the engineering work, and it is the part we keep for a conversation. The reason is the same as with vision: the interesting question for your product is not the toolchain, it is whether your speech model hits a latency your users will tolerate on the board you have. That we can tell you.
## The latency reality
Here is the honest picture, because it is the useful part. With a Whisper-medium model:
- The encoder runs in about **1.5 seconds** per utterance.
- A short spoken command transcribes in about **6 to 9 seconds**.
- Add a second or two for the on-device step that turns the text into an action, and you are at roughly **8 to 13 seconds** from speaking to motion.
That is real, and for a walk-up demo it is on the edge of acceptable. The levers that bring it down are model size and how the model is loaded and served between calls. A smaller Whisper model is dramatically faster and gives up some accuracy; a better serving strategy removes overhead that has nothing to do with the model at all. Which of those is right depends on the product, and choosing well is most of the latency you actually ship.
We are running a direct CPU-versus-NPU speech benchmark on this exact board, and the result is more nuanced than the vision case. When it is done we will publish the numbers, because "put it on the NPU" is not automatically the fastest answer for speech, and the honest version of that story is worth more than a slogan.
## Where this fits
If your product needs voice or audio understanding on-device, on the MediaTek Genio or on NVIDIA Jetson, the pattern is the same: the accelerator makes on-device speech possible, and the latency you ship is an engineering choice you want to get right early rather than discover late. That is the work we do on a fixed timeline. [Tell us what you are building](/contact) and we will tell you the fastest path to a working result. For the robot this came from, see [the ROSOrin build overview](/blog/voice-controlled-robot-mediatek-genio), and for the vision side, [YOLOv8 on the Genio NPU](/blog/yolov8-mediatek-genio-npu).
---
## Building a Yocto Image for a MediaTek Genio Robot
URL: https://proventusnova.com/blog/yocto-image-mediatek-genio-robot/
Published: 2026-09-28
Author: Andres Campos
Tags: yocto, mediatek genio, ros2, embedded linux, bsp
A demo becomes a product when it boots identically every time. How we baked our robot's ROS 2 stack into a Yocto image, and the trap that ruins a reflash.
There is a moment in every hardware project where a working demo has to become something you can build twice. For an embedded product on the MediaTek Genio, that moment is a Yocto image. Here is how we packaged our robot into one, and the single discipline that decides whether your image is trustworthy.
## Key Insights
- A demo lives on one hand-tuned board; a product lives in a Yocto image that rebuilds and reflashes identically
- We package the robot's ROS 2 container stack, its recipes, and a boot service into a custom layer so the whole system lands the same way every build
- The boot service starts the stack in order and brings up only the nodes whose hardware is actually present
- The most dangerous mistake is a fix made live on the board that never made it into the recipe, because a reflash silently loses it
- Treat the recipe as the source of truth, and verify that a fresh flash reproduces the working board
## Why Yocto, and not a setup script
You can bring a board up by hand. You should not ship that way. A board configured by hand is a board only one person can reproduce, and only until they forget a step. A Yocto image is the opposite: it is a build that produces the same root filesystem every time, boots the same way, and can be written onto the next unit with no bespoke setup. The first time you need a second board, or need to reflash the one you have, the image is what saves you from redoing bring-up from memory.
For our robot the image carries the whole software system: the ROS 2 nodes as containers, the recipes that place them and their supporting files, and the orchestration that starts everything at boot.
## Baking in a container stack
Running each ROS 2 node as a container is the right structure, and Yocto is how you make that structure durable. A custom layer packages the container images and the recipes that install them, so that a freshly flashed board comes up with the exact stack you tested. On top of that sits a boot service that starts the stack in a defined order and is smart about hardware: it brings up the camera and its consumers only when the camera is present, the lidar-dependent nodes only when the lidar is there, and so on. That way one image behaves sensibly whether a given peripheral is plugged in or not, which matters on a robot that gets reconfigured on the bench.
## The trap that bites reflashes
Here is the discipline that separates a real image from a fragile one. During bring-up you will fix things live on the board, because that is faster than a rebuild. Every one of those fixes has to be folded back into the layer, or your image is quietly wrong. We hit exactly this: several pieces of the boot orchestration existed only on the board and not in the recipe, which meant a fresh flash would have come up missing part of the startup. The board worked; the image that was supposed to reproduce it did not.
The rule is simple to state and easy to violate: the recipe is the source of truth, not the board. The check that enforces it is to flash a clean image and confirm the result matches your working unit, before you rely on the image for anything. If a reflash loses a fix, you have found the gap while it is cheap.
We keep the specifics of our layer and recipes for the projects we do, because they are particular to the platform and the product. The reusable lesson is the one above: a Yocto image is only as trustworthy as your discipline about keeping the board and the recipe in sync.
If you are turning a working prototype into a reproducible, flashable image on the MediaTek Genio or on NVIDIA Jetson, that BSP and image work is a core part of what we do. [Tell us what you are building](/contact). For the robot this image runs, see [the ROSOrin build overview](/blog/voice-controlled-robot-mediatek-genio) and [running ROS 2 on the MediaTek Genio](/blog/ros2-mediatek-genio).
---
## YOLOv8 Object Detection on the MediaTek Genio NPU
URL: https://proventusnova.com/blog/yolov8-mediatek-genio-npu/
Published: 2026-09-28
Author: Andres Campos
Tags: mediatek genio, npu, yolo, object detection, edge ai, computer vision
Moving YOLOv8 to the MediaTek Genio NPU took our robot's detection from 426 ms to 32 ms per frame and let it run fanless. What it takes, and when it pays off.
Our robot needed to find people and a ball from a live camera, on the robot itself, with no fan and no cloud. We started where most teams start, running YOLOv8 on the CPU. It technically worked and it was unusable. Here is what the numbers looked like, and what it took to fix them.
## Key Insights
- YOLOv8s on the MediaTek Genio 520 CPU ran at 426 ms per frame and drove the chip to 84 C, throttling under its own load
- The same model on the Genio NPU ran at 32 ms per frame at 58 to 60 C, about 13 times faster and cool enough to run fanless
- The NPU output matched the CPU output on the same frames, so this was a speed and thermal win, not a change in accuracy
- The real work is converting the model to the accelerator's format correctly, especially the detection head, not the runtime
- On a fanless edge board, on-device vision is a thermal problem before it is a speed problem, and the NPU solves both at once
## The problem: the CPU cannot do this
YOLOv8s at a normal input size on the Genio's CPU cores runs at about 426 milliseconds per frame. That is roughly two frames per second, and to get even that the board pins every core at maximum clock. The chip climbs past 80 C and sits at 84 C, above the point where it wants to throttle. On a robot with no fan, in a warm exhibition hall, that is not a demo you can leave running.
You cannot cap the CPU usage your way out of it either. The inference is simply slower than the frame rate you want, so limiting cores just makes it slower. The workload is on the wrong processor.
## The fix, in shape: move it to the NPU
The MediaTek Genio has a dedicated neural accelerator. Moving YOLOv8 onto it took the same model to **32 milliseconds per frame** at **58 to 60 C**, with the camera and the rest of the stack running at the same time. That is about 13 times faster, and roughly 25 degrees cooler, on the same board doing the same job.
Crucially, the detections did not change. We ran the accelerator output against the CPU output on identical frames and got the same results, down to a person detected at 0.86 confidence on a reference image. This is the outcome you want: the NPU is not a lossy shortcut, it is the correct place to run the model.
| YOLOv8s on the Genio 520 | Per frame | SoC temperature | Practical result |
|---|---|---|---|
| CPU | 426 ms | 84 C (throttling) | ~2 fps, cannot run fanless |
| NPU | 32 ms | 58-60 C | ~8-9 fps, runs fanless |
## What it takes, and where it gets hard
At a high level the path is what you would expect. The model has to be converted from its trained form into the format the accelerator loads. Then it runs through the on-device runtime that already ships on the Genio image, so you do not need any special runtime libraries on the target to execute it.
The difficulty is in the conversion, and specifically in the parts of a detection network that do not map cleanly onto the accelerator. A YOLO model is not just a stack of convolutions; the detection head does work that needs care to land on the NPU without losing correctness or speed. Getting that conversion right, for your exact model and your exact board, is the engineering, and it is the difference between the 426 ms result and the 32 ms one.
That conversion work is what we do. We have kept the step-by-step out of this post on purpose, because the interesting question for a product team is not the command line, it is whether your model can hit your frame rate and thermal budget on the silicon you have chosen. That is a question we can answer quickly.
## When this matters for your product
If you are putting a camera and a vision model on a fanless or battery-powered edge device, assume from the start that the CPU is not where inference belongs. The order of operations that saves teams months is: pick the board for its accelerator, confirm your model converts and hits your numbers on it, then build the product around that. Discovering at integration time that your detector cooks the board is an expensive way to learn the same thing.
We do this on the MediaTek Genio and on NVIDIA Jetson: get a real model running on the real accelerator, at the frame rate and temperature your product needs, on a fixed timeline. If that is your problem, [tell us what you are building](/contact) and we will tell you the fastest way to a working result. For the wider picture of the robot this came from, see [the ROSOrin build overview](/blog/voice-controlled-robot-mediatek-genio).
---
## GStreamer alternatives on NVIDIA Jetson: what really replaces it
URL: https://proventusnova.com/blog/gstreamer-alternatives-nvidia-jetson/
Published: 2026-09-18
Author: Andres Campos
Tags: jetson, gstreamer, ffmpeg, deepstream, multimedia api, pipeline optimization
GStreamer alternative on NVIDIA Jetson? FFmpeg, the Multimedia API, DeepStream, OpenCV and libcamera compared by job, plus when switching is the wrong fix.
Most Jetson teams searching for a GStreamer alternative do not have a GStreamer problem. They have a pipeline that was never profiled. We know because the pipelines that reach us with "we need to get off GStreamer" in the first email usually leave with the same framework, a different element graph, and the latency they wanted.
That is not an argument for staying. There are real cases where GStreamer is the wrong tool on Jetson, and there are four alternatives worth knowing in detail. This guide covers what each one is, which job each wins, and a ten-minute test that tells you whether switching would change anything before you rewrite a working pipeline.
## Key Insights
- There is no drop-in replacement for GStreamer on Jetson. Every accelerated path ends at NVENC, NVDEC, the VIC and the Argus ISP, and the alternatives are different wrappers around the same blocks
- DeepStream is not an alternative. It is GStreamer plus NVIDIA's inference, tracking and on-screen-display plugins, and it inherits every GStreamer behavior you are trying to escape
- FFmpeg on Jetson decodes in hardware with NVIDIA's patch and encodes in hardware only through the unsupported community jetson-ffmpeg project, which makes it a transcode tool, not a live multi-camera pipeline tool
- The Jetson Multimedia API is the layer GStreamer's nv plugins wrap. It buys direct control of NvBufSurface buffers at the price of roughly ten times the code and all the buffer management
- The problems that drive most switch attempts are diagnosable in minutes: a software videoconvert in the path, buffers leaving NVMM memory, a missing queue, sync=true on a live sink, or Python in the frame loop
## Why teams go looking for a GStreamer alternative on Jetson
The complaints are consistent. Caps negotiation fails with an error that names none of the elements involved. A pipeline that ran at 30 fps on a desktop runs at 9 fps on an Orin NX. CPU sits at 100% on one core while the GPU idles. Adding a second camera halves the frame rate of the first one. The debug output is a wall of `GST_DEBUG` lines that explain everything except the problem.
None of those are GStreamer being slow. Each one maps to a specific misuse of Jetson's memory and hardware model, and each has a known fix. We documented the four patterns that kill throughput in the [GStreamer pipeline performance guide](/blog/gstreamer-pipeline-performance-jetson), and the short version is that Jetson pipelines fail when buffers leave NVMM memory, when a CPU element sits where a hardware element belongs, or when several processes fight over the single VIC block.
The reason this matters for the alternatives question is simple. Every alternative on this list runs on the same hardware blocks with the same memory rules. If your pipeline copies frames through system RAM in GStreamer, the same design copies them through system RAM in FFmpeg or in raw Multimedia API code. Switching frameworks does not remove the constraint. It removes the tooling that makes the constraint visible.
## What actually replaces GStreamer on Jetson
Short answer: nothing replaces it outright, but four options cover real jobs better than GStreamer does, and one option that looks like an alternative is not one.
| Option | What it is | When it beats GStreamer |
|---|---|---|
| **FFmpeg** | General media toolkit. Hardware decode on Jetson via NVIDIA's patch; hardware encode only via community `jetson-ffmpeg` (nvmpi) | File transcode jobs, batch processing, simple single-stream capture to disk. Weak for live multi-camera pipelines |
| **Jetson Multimedia API** | The C++ layer (V4L2 codecs, Argus, NvBufSurface, EGL) that GStreamer's `nv` plugins wrap | Maximum control and minimum latency when you will write and maintain roughly 10x the code |
| **DeepStream** | NVIDIA's AI video framework, built on top of GStreamer, not beside it | Never as an escape from GStreamer. It is the right choice for multi-stream inference, and it is still GStreamer |
| **OpenCV VideoCapture** | Convenience capture API. On Jetson, the accelerated path runs through OpenCV's GStreamer backend | Quick prototypes where pipeline control does not matter |
| **libcamera / raw V4L2** | Mainline Linux camera stack, or direct V4L2 capture | Sensors that bypass the ISP on purpose, such as RAW capture for your own debayer on the GPU. Not a production path for tuned CSI cameras |
### FFmpeg on Jetson: decode yes, encode maybe
NVIDIA ships a patch for FFmpeg that adds a V4L2-based hardware decoder for H.264, H.265 and the other NVDEC formats. Decode-only workflows, such as pulling frames from an RTSP source to feed a model, work well with it. Encode is the gap. NVIDIA does not provide FFmpeg hardware encode on Jetson. The community `jetson-ffmpeg` project fills it with the nvmpi encoder and decoder, and it works, but it trails JetPack releases, breaks on major L4T changes, and has no vendor behind it when it does.
That makes FFmpeg the right tool for transcode jobs, archival, and batch work, and the wrong tool for a live camera pipeline that needs supported hardware encode on every JetPack you will ship on.
### The Jetson Multimedia API: the layer under the nv plugins
When you use `nvv4l2decoder`, `nvvidconv` or `nvarguscamerasrc`, you are calling the Multimedia API through a plugin. Calling it directly gives you the NvBufSurface buffer as a first-class object, explicit control of every DMA transfer, and no negotiation layer between you and the hardware.
The gain is real but bounded. Once a GStreamer pipeline keeps every buffer in NVMM memory, the hardware is doing the same work either way. What you remove is GStreamer's scheduling overhead and its opinions about buffering, which matters when you are chasing the last few milliseconds on a single deterministic pipeline. What you take on is everything GStreamer was doing for you: threading, queueing, format conversion, error recovery, and the RTSP or WebRTC server you probably also need.
Our own experience with this trade is documented in the [Python to C++ latency post](/blog/python-to-cpp-embedded-ai-device-time-to-market). The 4x latency reduction in that engagement came from moving the frame loop out of Python and into C++ with zero-copy NvBufSurface access. The GStreamer pipeline stayed. The interpreter left.
### DeepStream is GStreamer with NVIDIA's AI plugins
This one deserves a direct statement because "DeepStream vs GStreamer" is a common search and a category error. DeepStream is a set of GStreamer plugins: `nvstreammux` batches streams, `nvinfer` runs TensorRT, `nvtracker` tracks objects, `nvdsosd` draws the overlay. The sample apps are GStreamer applications. If your team is fighting caps negotiation today, DeepStream adds elements to negotiate with.
Choose DeepStream when the job is multi-stream inference on Jetson, because the batching and zero-copy inference path is excellent. Do not choose it to leave GStreamer.
### OpenCV VideoCapture on Jetson goes through GStreamer anyway
`cv2.VideoCapture(pipeline_string, cv2.CAP_GSTREAMER)` is the standard way to get accelerated frames into OpenCV on Jetson, and the name gives it away. The V4L2 backend avoids GStreamer, and it also avoids the ISP, the hardware color conversion and NVMM memory. You get raw CPU frames, which is acceptable for a prototype and a guaranteed bottleneck in production.
### libcamera and raw V4L2: capture without the ISP
libcamera is the modern Linux camera stack and it is not NVIDIA's. Jetson's ISP is reached through libargus, which is what `nvarguscamerasrc` wraps. Capturing through raw V4L2 with `v4l2src` or libcamera works for sensors where you want the RAW Bayer frames untouched, for instance to run your own debayer on the GPU. For a tuned production CSI camera, Argus is the path that delivers usable images.
## Which option wins by job
| Job | Best fit on Jetson | Why |
|---|---|---|
| Live CSI or GMSL2 camera capture | GStreamer (`nvarguscamerasrc`) | Only supported route through the Argus ISP |
| Hardware encode for streaming | GStreamer (`nvv4l2h264enc` / `nvv4l2h265enc`) | Supported NVENC path on every JetPack |
| RTSP or WebRTC server | GStreamer (`gst-rtsp-server`, `webrtcbin`) | Nothing else on the list includes a server |
| Multi-stream inference | DeepStream (still GStreamer) | `nvstreammux` batching and zero-copy `nvinfer` |
| File transcode, archival, batch | FFmpeg | Simpler tooling, hardware decode is supported |
| Single deterministic pipeline, latency budget in single-digit ms | Jetson Multimedia API | Direct NvBufSurface control, no scheduler in the way |
| RAW sensor capture for custom GPU processing | Raw V4L2 | Bypasses the ISP by design |
| Prototype in a notebook | OpenCV with the GStreamer backend | Fast to write, and honest about what it is |
Read the table as a map of jobs, not a ranking. Most Jetson products need three or four rows at once, and the framework that covers the most rows without a rewrite is the one that already wraps every block.
## The ten-minute test before you switch
Before any rewrite, measure where the frames spend their time. We released [gst-profile](/resources/gst-profile) for exactly this. It is a stdlib-only Python tool, MIT licensed, verified on a real Orin NX, and it ranks per-element time and flags the three faults that account for most "GStreamer is slow" reports: a zero-copy break where buffers leave GPU memory and come back, a software element doing work a hardware block should do, and a missing queue that pins the whole pipeline to one thread.
While it runs, check the five things we find most often:
1. **A `videoconvert` anywhere in the path.** On Jetson it copies every frame through system RAM. `nvvidconv` does the same job on the VIC and stays in NVMM.
2. **Buffers leaving NVMM memory.** Look for `video/x-raw` caps without `(memory:NVMM)` between two `nv` elements. Each break costs two DMA copies per frame.
3. **`sync=true` on a live sink.** The default presentation clock adds tens to hundreds of milliseconds. Setting `sync=false` on the output sink is the single largest latency fix on a live camera pipeline, as measured in our [end-to-end latency guide](/blog/reduce-gstreamer-pipeline-latency-jetson).
4. **Several GStreamer processes sharing the VIC.** `nvvidconv` instances in separate processes serialize on one hardware block, and throughput can fall five to ten times. The fix is [one process for all pipelines](/blog/nvvidconv-performance-multiple-gstreamer-processes), not a new framework.
5. **Python in the frame loop.** On Jetson CV pipelines, interpreter overhead is typically 30 to 45 percent of end-to-end latency. Moving the loop to C++ fixes that inside GStreamer.
If the profile comes back clean and the pipeline is still outside its budget, you have a real reason to consider the Multimedia API. If it comes back with any of the five, you have a pipeline fix, and it is usually a one-session fix.
## When switching is the right call
**Stay on GStreamer when** the product needs live camera capture through the ISP, supported hardware encode, a streaming server, or multi-camera composition. That describes most Jetson vision products, and the [working pipeline examples](/blog/gstreamer-pipeline-examples-jetson) cover the standard topologies.
**Move to the Jetson Multimedia API when** you have one fixed pipeline, a latency budget that GStreamer's scheduler measurably breaks after profiling, and an engineer who will own buffer management for the life of the product. Budget the rewrite honestly: the [live streaming pipeline](/blog/gstreamer-live-streaming-jetson-orin) is a few dozen characters in GStreamer and a few thousand lines in the Multimedia API.
**Use FFmpeg when** the job is offline: transcoding recordings, extracting frames for a dataset, or decoding a file to feed a model once. Keep it away from live encode unless you accept an unsupported codec path.
**Use DeepStream when** the job is inference across many streams. Go in knowing it is GStreamer, and bring the same NVMM discipline.
**Use raw V4L2 when** you want the sensor's RAW output on purpose. The rest of the stack, including the [nvcompositor versus parallel pipelines](/blog/jetson-nvcompositor-vs-parallel-gstreamer) question, stays in GStreamer.
## What we see on client projects
The pattern repeats often enough to state plainly. A team arrives certain that GStreamer is the bottleneck. The profile shows a `videoconvert` that nobody remembers adding, three processes queued on the VIC, or a `queue` with the default 200-frame buffer on a live feed. The fix lands in a working session, the frame rate comes back, and the framework question disappears. The rare exception is a single-pipeline product with a hard real-time budget, where the Multimedia API rewrite is justified and we scope it as its own milestone.
The expensive outcome is the middle path: a partial migration to FFmpeg or hand-written V4L2 code that removes the parts of GStreamer that were working, keeps the memory copies that were not, and adds a codebase with no upstream. If you are considering that path, profile first.
## When to call a specialist
Pipeline fixes are bounded work. If profiling points at a design problem, an unusual sensor combination, or a latency budget that needs the Multimedia API, the [GStreamer development service](/services/gstreamer) page describes how we scope that as a fixed-bid milestone with a working result at the end of it, rather than an open-ended rewrite.
---
## AGPL to Permissive License Migration on Jetson TensorRT
URL: https://proventusnova.com/blog/agpl-permissive-license-migration-jetson-tensorrt/
Published: 2026-08-03
Author: Andres Campos
Tags: jetson, tensorrt, agpl license, computer vision, open source license
How we migrated a Jetson TensorRT stack off AGPL YOLO-World and FastSAM to Apache-2.0 models, and the checkpoint trap that almost broke it.
When a Jetson-based perception stack ships to a paying customer, the license graph underneath the model weights matters as much as the inference architecture on top of it. We recently ran an AGPL to permissive license migration on a client's TensorRT pipeline: an open-vocabulary detector, an instance segmenter, and a depth model, prototyped fast on licenses that would not have cleared for a commercial deliverable as-is. The fix was not a rewrite. It was a capability map, a checkpoint audit, and one gotcha that would have re-tainted the whole deliverable if we had missed it: a model whose code is Apache-2.0 but whose default checkpoint is not.
## Key Insights
- AGPL-3.0's network-use clause reaches any service that talks to a user over a socket. A single AGPL import in a Jetson inference pipeline can put the commercial license of the entire deliverable at risk, not just that one component.
- Treat the migration as a capability swap, not a package swap. A monolithic AGPL-3.0 vision library (in this case bundling YOLO-World for open-vocabulary detection and FastSAM for instance segmentation) hides several distinct capabilities behind one import; decompose first, then replace each one.
- Code license and weights license are not the same thing. Depth-Anything-V2's code is Apache-2.0, but only the Small checkpoint carries that license. The Base and Large checkpoints are CC-BY-NC and will re-taint a commercial product if a config file ever points at them.
- Freeze the public interface of every model wrapper before touching the implementation. When `Detector.detect()` and `Segmenter.segment()` keep the same signature, the orchestrator, the ROS 2 node, the tracker, and the overlay code never have to change.
- A permissive fallback path is worth more than raw throughput. When our optimized TensorRT segmentation path broke at export time, we dropped to plain PyTorch for that one model and still shipped roughly 4x faster end to end than the original AGPL baseline, because the detector stayed TensorRT-native.
## What Is AGPL to Permissive License Migration and Why Does It Matter on Jetson?
AGPL-3.0 differs from plain GPL in one clause that catches most engineering teams off guard: Section 13, the network-use clause. Regular GPL triggers on distributing a binary. AGPL triggers on letting a user interact with the software over a network, whether or not you ever hand them a copy of it. A Jetson device that runs inference and answers a request, whether that request comes from a companion app, a REST call from a fleet manager, or another service on the same LAN, counts as that kind of interaction. Ship a modified AGPL-3.0 model in that path and you can trigger an obligation to offer the corresponding source, including your own glue code around the model.
For a client who owns a proprietary, closed-source product, that is not a negotiable licensing cost. It is disqualifying. The stack we inherited used a single AGPL-3.0 vision library for two jobs at once: an open-vocabulary detector (YOLO-World) and an instance segmenter (FastSAM). Both are capable models. Neither is licensable into a client-owned commercial deliverable without a paid Ultralytics Enterprise license.
The mistake teams make here is treating the fix as "find a permissive alternative to library X." That framing sends people looking for a single drop-in replacement that does not exist. The library was never one thing; it bundled two capabilities behind one import, plus a third that had not been added yet (monocular depth). Once we reframed the task as a capability inventory, the migration stopped being a research problem and became a mechanical one.
## The AGPL to Permissive License Migration Capability Map
Once you decompose the AGPL package into distinct capabilities, each one gets its own permissive replacement, and some capabilities may already be clean. Here is the map we built for this stack:
| Capability | AGPL-3.0 incumbent | Permissive replacement | License |
|---|---|---|---|
| Open-vocabulary detection | YOLO-World | NanoOWL / OWL-ViT | Apache-2.0 |
| Instance segmentation | FastSAM | NanoSAM, or upstream MobileSAM | Apache-2.0 |
| Monocular depth | (new capability) | Depth-Anything-V2-Small | Apache-2.0* |
| Multi-object tracking | (already separate) | `supervision` / ByteTrack | MIT |
| PyTorch to TensorRT conversion | (already separate) | `torch2trt` | MIT |
| Weights and text/image encoders | (already separate) | HuggingFace `transformers` | Apache-2.0 |
*See the checkpoint trap below; the Apache-2.0 grant does not cover every checkpoint in this repo.
Tracking was already MIT before we touched anything. We verified it and left it alone. Half the value of building this table is knowing which capabilities do not need to move, so you do not spend engineering time re-validating a component that was never the problem.
## The Checkpoint License Trap: Apache-2.0 Code, Non-Commercial Weights
This is the part almost nobody checks, and it is the reason this migration is worth writing up. A repository's code license is not automatically the license of the model weights it publishes. Depth-Anything-V2 ships its code under Apache-2.0. Its Small checkpoint is Apache-2.0 too. Its Base and Large checkpoints, the ones with the best accuracy and the ones a benchmark table will point you toward, are released under CC-BY-NC, a non-commercial license. Load the Base checkpoint into an otherwise clean Apache-2.0 codebase and you have re-introduced the exact problem you spent the migration solving, just one layer down, in the weights instead of the code.
We pin the exact checkpoint name in config, not just the model family:
```yaml
models:
depth:
enabled: false
name: depth-anything-v2-small # SMALL only, Base/Large are CC-BY-NC
backend: tensorrt
```
A comment in a YAML file will not survive config edits by someone who was not in the room for this decision, so we enforce it in code:
```python
_APACHE_OK = {"depth-anything-v2-small"} # Base/Large are CC-BY-NC
def __init__(self, cfg):
if cfg.name not in _APACHE_OK:
raise ValueError(
f"{cfg.name!r} is not an Apache-2.0 checkpoint; "
f"only {sorted(_APACHE_OK)} may ship commercially"
)
```
The wrapper raises before the model even loads if someone points the config at a non-commercial checkpoint. That single check is cheap insurance against a future fine-tune or a well-meaning teammate chasing an accuracy number, silently reintroducing a license problem that a code review would probably not catch, because the diff looks like a one-line config change.
## Freezing Wrapper Interfaces to Contain the Blast Radius
The reason this kind of migration is cheap instead of a rewrite is that every model lives behind a thin wrapper class, and we freeze the public interface of that wrapper before changing anything inside it.
| Wrapper | Frozen public surface | What changes inside |
|---|---|---|
| `Detector` | `set_classes(prompts)`, `detect(frame) -> list[Detection]`, `.active_classes` | Constructor and implementation now wrap `OwlPredictor` instead of the AGPL detector |
| `Segmenter` | `segment(frame, boxes) -> list[mask]` | Constructor and implementation now wrap MobileSAM instead of FastSAM |
Because those method signatures and the `Detection` dataclass never move, the orchestrator, the ROS 2 node, the overlay renderer, and the tracker do not need to change at all. The entire change set collapses to five things: the two wrapper implementations, their tests, the config schema (new fields for engine paths, checkpoint names, thresholds), the Dockerfile, and asset provisioning for the new engines. The one caller-side change we could not avoid was the constructor call site, since the new wrappers take a config object instead of unpacked positional arguments; we isolated that to a single line in the node.
We also make the license reasoning visible right where dependencies enter the container image, so a future audit does not have to reconstruct the decision from memory:
```dockerfile
# ultralytics removed, AGPL-3.0. supervision (ByteTrack) is MIT, transformers is Apache-2.0.
RUN python3 -m pip install --no-cache-dir --no-deps \
supervision==0.24.0 defusedxml==0.7.1 \
&& python3 -m pip install --no-cache-dir transformers
# NanoOWL (Apache-2.0), detection.
RUN git clone --depth 1 https://github.com/NVIDIA-AI-IOT/nanoowl /opt/nanoowl \
&& cd /opt/nanoowl && python3 setup.py develop
# Upstream MobileSAM (Apache-2.0). --no-deps preserves the platform CUDA torch.
RUN python3 -m pip install --no-cache-dir --no-deps \
git+https://github.com/ChaoningZhang/MobileSAM.git timm
```
`--no-deps` matters for two reasons on an accelerator platform. It stops pip from silently pulling a transitive AGPL dependency back in, and it stops pip from overwriting the vendor-built CUDA-enabled `torch` with a stock PyPI wheel that does not know your GPU exists. Audit the transitive closure, not just the direct import; the AGPL package is only gone once nothing underneath it is AGPL either.
## When the Optimized TensorRT Path Breaks, Keep the Permissive Fallback
The cleanest replacement on paper does not always survive the target toolchain, and that is where the license decision has to hold independently of the performance plan. Our first choice for the segmentation swap was to run MobileSAM through TensorRT for the mask decoder. It did not survive contact with the hardware: the vendor-published ONNX assets for that decoder were dead links, and the version we exported locally contained a shape-computation op that the target TensorRT release rejected outright.
Because we had picked an Apache-2.0 replacement rather than the cheapest replacement, the fallback was simple: run that same MobileSAM segmenter in plain PyTorch instead of TensorRT. The license held. Only the performance plan changed. End-to-end throughput still landed at roughly 4x the original AGPL PyTorch baseline, because the detector stayed TensorRT-native and dominated the wall-clock budget; the segmenter running unoptimized cost us some headroom, not the deliverable.
The lesson generalizes past this one project: pick a replacement whose permissive license still holds in its slowest, least-optimized execution mode. A toolchain block should cost you throughput. It should never cost you the license.
If you are running this same class of migration, the checklist we use every time is short:
1. Identify every AGPL import and the discrete capabilities each one provides.
2. Map each capability to an Apache-2.0 or MIT replacement, and confirm which capabilities were already clean so you do not touch them.
3. Audit both the code license and the per-checkpoint or per-weights license for every replacement; pin the exact commercial-safe variant by name.
4. Freeze wrapper public interfaces; contain the change to wrapper internals, tests, config schema, the Dockerfile, and asset provisioning.
5. Encode the license reasoning at the dependency boundary and install with `--no-deps` where relevant; verify the transitive closure is AGPL-free.
6. Enforce the checkpoint or weights license in code so a future config edit cannot silently regress it.
7. Confirm the replacement's license still holds in any degraded or fallback execution path before you commit to that replacement.
We ran this same detection, segmentation, and depth stack on the [real-time perception demo we built on Jetson](/blog/real-time-edge-perception-demo). If you are deciding where to spend optimization budget once the licensing is settled, our [TensorRT vs DLA comparison on Jetson Orin](/blog/tensorrt-vs-dla-jetson-orin) covers GPU-versus-DLA placement for whichever of these models you end up optimizing.
## Frequently Asked Questions
### Is YOLO-World free to use in a commercial product?
Not without a separate commercial license. YOLO-World ships as part of the Ultralytics package under AGPL-3.0, which means any product that lets a user interact with it over a network, including an on-device API on a customer-owned appliance, can trigger source-disclosure obligations. Ultralytics sells an Enterprise license specifically to cover this case.
### Does AGPL apply to a Jetson device that never touches the public internet?
Yes, in most practical cases. The AGPL network-use clause is not limited to the public internet; it covers any network interaction where a user sends the modified program a request and receives a response, including a LAN-only API or a companion app talking to the device locally. Shipping the device itself to a customer is also a form of conveyance under GPL-family licenses, independent of the network clause.
### Is Depth-Anything-V2 free for commercial use?
Only the Small checkpoint. The code repository is Apache-2.0 across the board, but the Base and Large checkpoints are released under CC-BY-NC, a non-commercial license, separate from the code license. Pin the checkpoint name explicitly in config and enforce it in code, since a benchmark table will usually point you toward Base or Large for accuracy, not Small.
### What license are NanoOWL and NanoSAM released under?
Both are Apache-2.0, published by NVIDIA-AI-IOT as Jetson-optimized ports of open-vocabulary detection (NanoOWL, built on OWL-ViT) and segmentation (NanoSAM). They are common permissive replacements for YOLO-World and FastSAM in exactly this kind of migration.
### Do I need a lawyer to do an AGPL to permissive license migration?
Get legal sign-off before you ship, but the bulk of the work is engineering: building the capability map, auditing per-checkpoint licenses, and freezing wrapper interfaces. Doing that work first turns an open-ended legal review into a short table your counsel can confirm in an afternoon instead of an audit that stalls the release.
---
*ProventusNova helps hardware startups solve embedded systems problems fast. If your Jetson perception stack needs an AGPL to permissive license audit before it can ship to a customer, see our [edge AI deployment services](https://proventusnova.com/services/edgeai-deployment).*
---
## CTI Carrier Board Yocto Layer: Two-Tier Wrapper Pattern
URL: https://proventusnova.com/blog/cti-carrier-board-yocto-layer-pattern/
Published: 2026-08-03
Author: Aaron Angulo
Tags: jetson, yocto, bsp, carrier board, device tree
How to wrap Connect Tech's meta-cti Yocto layer with your own distro layer to add camera overlay DTBs without forking the vendor's BSP.
A CTI carrier board Yocto layer only holds up long-term if you never edit the vendor's files directly. Connect Tech Inc. ships `meta-cti` as a complete BSP layer for their Boson-family carrier boards running Jetson Orin NX modules, and the moment someone copies one of CTI's machine configs into a project layer and starts editing it, that project has forked a vendor BSP it doesn't control. We ran into this on an Orin NX bring-up where the ask sounded simple: add a camera overlay device tree for a sensor CTI doesn't ship by default. The fix was a two-tier layer split that lets `meta-cti` keep updating on its own schedule while the camera work sits cleanly on top of it.
## Key Insights
- **`require`, not fork.** Your wrapper machine config pulls in CTI's base machine file with `require conf/machine/cti-orin-nx-boson-.conf` and overrides only what changes, mainly `KERNEL_DEVICETREE`.
- **Ownership splits cleanly by directory, not by file edits.** CTI owns the base machine, the base carrier DTS, and default kernel/bootloader providers. Your distro layer owns the camera overlay DTS, the image recipe, and package selection.
- **The Makefile entry triggers the DTB build, not the DTS file alone.** Dropping a new `.dts`/`.dtsi` pair into CTI's kernel-hardware tree does nothing until a bbappend adds a corresponding line to `nvidia-kernel-oot`'s Makefile.
- **Pull only the files you need from the vendor tarball.** CTI distributes a full `cti-l4t-src` tarball; extract the specific DTS/DTSI paths for your variant with `tar -xOf`, don't unpack and copy the whole tree into your layer.
- **A vendor BSP update becomes a version bump, not a merge, once the split is in place.** Everything CTI owns can move without touching a single file your team maintains.
## Fixing a CTI carrier board Yocto layer that's been forked
The failure mode we see most often on Connect Tech carrier boards starts the same way: an engineer needs a camera variant CTI doesn't ship, copies `cti-orin-nx-boson-.conf` into the project's own layer, renames it, and starts editing device tree entries directly. It works. The board boots, the camera comes up, the milestone closes. Then CTI ships a BSP update for the next JetPack release, and now someone has to diff the old vendor machine config against the new one, line by line, and manually re-apply every custom edit into the new file. On the second update, that diff gets harder because the custom edits and the vendor's own changes have started overlapping in the same regions of the file.
The two-tier pattern avoids this by never letting your changes and the vendor's changes live in the same file. Your distro layer, call it `meta-yourdistro`, has its own machine config that requires CTI's machine config rather than copying it:
```bitbake
# conf/machine/yourdistro-orin-nx-boson-.conf
require conf/machine/cti-orin-nx-boson-.conf
MACHINEOVERRIDES =. "yourdistro:"
# Point the kernel device tree at your camera overlay instead of CTI's default
KERNEL_DEVICETREE:append = " \
tegra234-orin-nx-cti---cam.dtb \
"
# Anything else your product needs on top of the base carrier
MACHINE_FEATURES += "wifi bluetooth"
```
This is the entire wrapper. When CTI ships a new BSP release, you bump the reference to their updated machine file (or it updates automatically if you're tracking their layer as a submodule), rebuild, and your `KERNEL_DEVICETREE:append` and `MACHINE_FEATURES` additions carry forward untouched. There's no file to diff, because there was never a copy to diverge from.
The [Connect Tech BSP track record we've covered when comparing third-party Jetson carrier board vendors](/blog/jetson-carrier-board-manufacturers-compared) is one of the better ones in the market, largely because CTI keeps their machine configs and kernel Makefiles in a predictable, requireable shape release over release. That predictability is exactly what the two-tier pattern depends on. If a vendor restructures their layer wholesale on every release, `require` still protects you (the build fails loudly instead of silently drifting), but the rework on your side goes up regardless of layering discipline.
## Splitting ownership between meta-cti and your distro layer
The two-tier split isn't just the machine config. Every piece of the BSP has a clear owner, and the rule is simple: if CTI ships it and validates it against their hardware, they own the file; if it's specific to your camera, your image, or your product, it lives in your layer.
| Owned by `meta-cti` (vendor) | Owned by your distro layer (you) |
| --- | --- |
| `conf/machine/cti-orin-nx-boson-.conf` (base board machine) | `conf/machine/yourdistro-orin-nx-boson-.conf` (wrapper machine) |
| Base carrier DTS (`tegra234-orin-nx-cti-.dts`) | Camera overlay DTS (`tegra234-orin-nx-cti---cam.dts`) |
| Default kernel and bootloader providers | Image recipe, package selection, distro features |
| Carrier-specific binary blobs and firmware | `nvidia-kernel-oot` bbappend that adds your DTBs to the OOT Makefile |
| `meta-cti`'s own CI config | Your CI job, one per machine |
Read that table as a checklist during code review. Any pull request that touches a file in the left column is a sign someone reached into vendor territory instead of overriding it from the right column, most commonly a new sensor node hand-edited directly into CTI's base carrier DTS instead of added as a new overlay DTSI in the project layer. Catching that in review before it merges is what keeps the base DTS identical to what CTI ships, which is the entire point of the pattern.
## Wiring the camera overlay DTB into CTI's kernel build
Adding a device tree file to the right directory is necessary but not sufficient. CTI's `nvidia-kernel-oot` recipe builds DTBs from a Makefile under a fixed path in their kernel-hardware tree:
```
recipes-kernel/nvidia-kernel-oot/files/hardware-/nvidia/t23x/cti-public/orin-nx-nano/
├── cti_camera/
│ ├── tegra234-orin-nx-cti--cam-base.dtsi # base camera overlay
│ └── tegra234-orin-nx-cti---cam.dtsi
└── orin-nx/
├── Makefile # add new entries here via bbappend
└── tegra234-orin-nx-cti---cam.dts
```
Five steps get a new camera variant from source to a bootable DTB:
1. **Write the wrapper machine config first.** It's the file that ties everything else together, and getting `require` and `KERNEL_DEVICETREE:append` right early avoids chasing a "DTB not found" error later that's really a machine-config typo.
2. **Add the DTS/DTSI pair under the vendor's existing hardware directory.** Match the naming convention CTI already uses (`tegra234-orin-nx-cti---cam.dts`), placed in your bbappend's `FILESEXTRAPATHS`, not directly inside `meta-cti`.
3. **bbappend `nvidia-kernel-oot` to add a line to the Makefile.** This is the step people skip and then can't figure out why their DTB never shows up in the deploy directory. The `.dts` file compiling on its own means nothing to BitBake until the Makefile references it.
4. **Extract only the source files you need from CTI's L4T tarball**, rather than unpacking the whole archive into your layer:
```bash
tar -xOf .tar \
sources/kernel/hardware/nvidia/t23x/cti-public/orin-nx-nano/cti_camera/tegra234-orin-nx-cti--cam-base.dtsi \
> /tmp/-base.dtsi
```
Keep the tarball itself out of source control and note its archived location in your bring-up notes so the next engineer knows where it came from.
5. **Build and confirm the DTB lands in the deploy output** (`tmp/deploy/images//`) before flashing. A missing DTB at this stage almost always traces back to step 3, a Makefile entry that didn't get added, rather than a device tree syntax error.
## Keeping deploy and CI ready for the next camera variant
The layering discipline only pays off if the surrounding tooling doesn't quietly assume there's one machine. Two habits keep that true.
Keep `deploy.sh` generic across variants. A `select`-menu script that composes the flash artifact name from image and machine choices doesn't need to know anything about camera specifics, because the artifact name is deterministic: `-.rootfs.tegraflash.tar.zst`. Add a new camera variant, and the deploy script already knows how to flash it, no changes needed.
Keep CI per-machine rather than one matrix job covering every board. A `build:` job parameterized by `MACHINE` gives a clean failure surface when a single variant breaks, and lets you skip machines selectively when a `meta-cti` update only touches one board in the fleet. A single matrix job that builds every variant in one pipeline stage makes it harder to tell at a glance which board broke, and it forces a full rebuild even when only one machine needs it.
The same require-and-override discipline applies outside Jetson too. On [MediaTek Genio, wrapping meta-mediatek-bsp and meta-rity with a product-specific meta-layer](/blog/mediatek-genio-custom-yocto-meta-layer) follows the identical logic: bbappend the vendor's recipes, scope patches to your machine name, and never edit the upstream layer's files directly. The vendor and the SoC change. The rule that keeps a BSP maintainable across upgrades doesn't.
## Frequently Asked Questions
### What is the meta-cti Yocto layer?
`meta-cti` is Connect Tech Inc.'s Yocto BSP layer for their Jetson carrier boards, including the Boson-family carriers paired with Orin NX modules. It ships the base machine configuration, the base carrier device tree, and the default kernel and bootloader providers for each board CTI supports.
### Should I fork meta-cti or wrap it with my own layer?
Wrap it. Create a distro layer whose machine config uses `require` to pull in CTI's machine file, then override only what changes, typically `KERNEL_DEVICETREE` for a camera overlay. Forking means manually re-applying every custom change on top of every vendor BSP update, and that gets more expensive with each release.
### How do I add a custom camera overlay DTB to a Jetson Orin NX carrier board in Yocto?
Write the DTS/DTSI overlay under the same hardware directory tree the vendor's `nvidia-kernel-oot` recipe already scans, then bbappend that recipe to add your new file to the OOT kernel's Makefile. The Makefile entry is what triggers the DTB build. Point `KERNEL_DEVICETREE` at the resulting `.dtb` from your wrapper machine config.
### What is the difference between require and include in a Yocto machine configuration?
Both pull in another file's contents at parse time. `require` fails the build immediately if the file is missing or moved. `include` fails silently and the parse continues without it. For a vendor-wrapping machine config, `require` is the right choice: if a CTI BSP update renames or restructures their machine file, the build tells you at the next run instead of shipping a config that silently stopped pulling in vendor settings.
### How do CTI BSP updates affect a custom distro layer built on meta-cti?
If your distro layer only requires the CTI machine config and overrides variables instead of copying files, a vendor BSP update is a version bump and a rebuild, not a merge. Your camera overlay DTB, kernel bbappend, and image recipe stay in your layer untouched. The only real risk is CTI restructuring a path your bbappend depends on, which is exactly why a loud `require` failure is a feature and not just an inconvenience.
---
*ProventusNova helps hardware startups solve embedded systems problems fast. [See our Custom Board Bring-up service](https://proventusnova.com/services/custom-board-bringup).*
---
## GMSL2 Multi-Camera Sync Past 4 Cameras: Fanout Topology
URL: https://proventusnova.com/blog/gmsl2-multi-camera-sync-past-4-cameras/
Published: 2026-08-03
Author: Andres Campos
Tags: gmsl2, multi-camera sync, frame sync, deserializer topology, jetson
Why GMSL2 multi-camera sync breaks past 4 cameras, how daisy-chaining deserializers wrecks frame alignment, and the fanout topology that scales correctly.
Every GMSL2 deserializer on the market caps out at four camera inputs per chip, so any system that needs five, six, or eight synchronized cameras has to bridge multiple deserializer chips together. GMSL2 multi-camera sync past 4 cameras is not a bigger-chip problem, because no bigger chip exists. It is a topology decision, and the wrong one turns an "8-camera synchronized array" into two perfectly-synced but mutually unsynced islands of four. This post covers why daisy-chaining deserializers destroys frame alignment as you scale up, and the fanout topology that keeps an array of any size on one shared timing reference.
## Key Insights
- GMSL2 deserializers have a hard per-chip camera-input ceiling, commonly four, so scaling past that always means adding chips, not reconfiguring one
- Daisy-chaining deserializers, where one chip generates the sync pulse and relays it to the next over a GPIO link, routes the reference through a full extra hop of relay propagation delay before it reaches the second chip's cameras
- That extra hop is not a rounding error: it moves the delay budget from a tight, single-chip skew figure to something orders of magnitude larger, and it lands on every camera downstream of it
- The fix is parallel-subordinate fanout: one shared hardware-timer reference, split on length-matched traces, feeding every deserializer at the same time, with none of them relaying for another
- A software GPIO toggle cannot serve as that shared reference no matter how the chips are wired; only a hardware timer or PWM source has jitter tight enough to matter at this scale
## Why GMSL2 multi-camera sync breaks down past 4 cameras
A GMSL2 deserializer is built to be the sync hub for its own links. It owns the timing reference, whether that reference originates internally or from an external GPIO, and it distributes that reference to every camera wired to it. Inside a single chip, this is a solved problem: the deserializer's own datasheet specifies a tight skew budget across its links, and as long as you enable the delay-compensated mode for that reverse-channel signal, every camera on that chip sees the same edge within that chip's own tight tolerance of every other camera on it.
The ceiling is the chip itself. Deserializers in this class support four camera inputs each. A system that needs five, six, or eight cameras needs two or more of these chips, full stop, there is no larger single-chip part that changes this math. Once frames span more than one deserializer, frame-start alignment stops being a per-chip configuration question and becomes a system-architecture question: every chip in the array now has to be driven from a common reference, or the array is not one synchronized system, it is several small synchronized systems that happen to share a housing and a power supply.
If you have not configured FSYNC on a single deserializer yet, our [GMSL2 multi-camera sync FSYNC setup guide](/blog/gmsl2-multi-camera-sync-jetson) covers the delay-compensated mode and DTS wiring for arrays of up to four cameras. This post picks up where that one leaves off, once a fifth camera forces a second chip into the design.
That failure mode is common enough that it has a name we use internally: islands of four. Boards marketed as "8-camera synchronized" often turn out, on inspection, to be two four-port deserializers that are each internally perfect and never shared a timing source with each other. Each half looks fine in isolation. Across the two halves, there is no relationship at all between frame starts, because nobody wired a shared reference between the chips in the first place. For an application where the whole point is that every camera captures the same instant, an unsynchronized pair of perfectly-synchronized quads is a very expensive way to fail the actual requirement.
This is exactly the kind of thing to catch before hardware is committed. When you are [choosing a GMSL2 carrier board for Jetson Orin](/blog/gmsl2-carrier-board-jetson-orin), port count and deserializer chipset are not the only questions that matter, whether the board's own layout ties multiple deserializers to one shared reference matters just as much, and it is rarely called out in a vendor's marketing copy.
## The daisy-chain trap
The instinctive way to connect two deserializer chips is to make the first one the source and let it drive the second, the same way you'd chain two switches on a network. For GMSL2 sync, this is the wrong instinct, and it is worth being explicit about why.
In a daisy chain, deserializer 1 is configured as the sync generator and deserializer 2 is configured to receive its reference from deserializer 1 over a GPIO link between the two chips. That link is not a passive wire. The reference has to pass through deserializer 1's own relay logic (the same reverse-channel GPIO path it uses to forward sync to its own cameras) before it ever reaches deserializer 2. That relay adds a full hop of propagation delay, well outside the tight tolerance a chip's own internal skew budget is built around. That gap is not something you tune around. It shows up as every camera behind deserializer 2 capturing measurably later than every camera behind deserializer 1, consistently, on every frame.
| Topology | What the reference passes through | Effect on cross-chip alignment |
|---|---|---|
| Single deserializer (up to 4 cameras) | Nothing, the chip drives its own links directly | Tight, chip-specified skew across those cameras only |
| Daisy-chain (chip 1 MAIN drives chip 2 as a downstream source) | One full hop of chip 1's own relay/propagation path | A fixed, much larger delay added to every camera behind chip 2 |
| Parallel-subordinate fanout (recommended) | Nothing extra, every chip receives the same external reference directly | Cross-chip alignment reduces to trace and cable length matching, not chip-to-chip relay delay |
The daisy chain is also fragile in a way that is easy to miss during bring-up. If deserializer 1 ever glitches, resets, or briefly loses lock, every chip behind it loses sync at the same time, because they were never independent from deserializer 1's health. A topology should not have a single point of failure sitting in the middle of the timing path.
## The correct topology: parallel-subordinate fanout
The fix is to stop treating any deserializer as the source for another deserializer. Instead, pick one shared reference, generated once on the host side by a hardware timer or PWM peripheral, and fan it out on length-matched PCB traces (or equal-length cable runs, if the fanout point is off-board) to the sync input of every deserializer in the array, in parallel.
```
Host hardware-timer / PWM GPIO
| (one source, length-matched fanout)
+----+----+ ... +
v v v
Deser 1 Deser 2 Deser k <- each configured independently
(subordinate) (subordinate) (subordinate) as a delay-compensated subordinate
| | |
<=4 cams <=4 cams <=4 cams (each chip still handles its own cameras)
```
Every deserializer in this diagram is configured the same way: it receives an external reference and distributes it to its own cameras. None of them generates the pulse, and none of them relays it to a sibling chip. Because every chip sits directly on the shared source rather than behind another chip, cross-chip skew should collapse to two things you control directly on the PCB and in the harness: how well you matched the trace lengths in the fanout, and how well you matched the cable lengths running out to each deserializer. Neither of those is a chip-to-chip propagation delay, and neither compounds as you add more chips. That's the design rationale for why this topology is sound, and it's worth being direct that it's rationale: the achievable cross-chip skew with real trace and cable mismatch on a specific board is a hardware validation question, not something to assume from the architecture alone. Measure it on your own layout before you commit to it in a spec.
This is also why parallel-subordinate fanout scales cleanly and daisy-chaining does not. Going from an 8-camera array (two chips) to a 12 or 16-camera array (three or four chips) means adding another branch to the fanout, not another link in a chain. The reference source does not care how many chips are listening, as long as it can drive the electrical load, which at higher chip counts may mean a buffer or repeater stage on the fanout network rather than a longer chain of relays. The alignment story stays the same for every chip you add: distance from the same source, not distance from the previous chip.
One requirement applies regardless of how you wire the chips: the shared reference itself has to come from a hardware timer or PWM output, not a GPIO toggled from a software loop. A software-driven GPIO carries scheduling jitter that lands in the microsecond-to-millisecond range depending on system load, which is the same order of magnitude as the daisy-chain penalty you were trying to avoid in the first place. Fixing the topology and then feeding it from an unstable source solves nothing.
## Verifying the array is synchronized
Do not trust the wiring diagram. Verify the array after every board revision, cable change, or chip swap, using both of these checks:
1. **Read back the chip's own alignment measurement.** Most deserializers in this class expose a runtime register that reports the measured difference between the earliest and latest sync arrival across their own links. Treat that readback as ground truth immediately after enabling sync on new hardware, before you assume the topology diagram matches what got built.
2. **Compare host-side timestamps across chips, not just within one chip.** Capture frames from at least one camera behind each deserializer at the same time and compare arrival timestamps the way you would for a single-chip array. A small, fixed offset that holds steady across a long capture points to trace or cable length mismatch, which is fixable in hardware. An offset that grows over time, or jumps unpredictably between chips, points to a topology problem, most often a daisy-chain link that got wired in somewhere without anyone deciding it should be there.
3. **Confirm the source, not just the fanout.** Before debugging anything downstream, check that the shared reference is coming from a hardware timer or PWM peripheral and not a software GPIO toggle. This single check rules out the most common root cause we see on arrays that fail sync past four cameras.
4. **Re-run all of the above after any physical change.** Trace and cable length matching is a property of that specific harness, not a permanent property of the schematic. A cable swap during a later production run can reintroduce a mismatch that the original design review never had to account for.
Skipping this verification step is how "islands of four" ship. The two halves of the array each pass every test you run on them individually, because each half really is internally synchronized. The only way to catch the missing cross-chip relationship is to test across chips deliberately, not just within each one.
## Frequently Asked Questions
### Can a single GMSL2 deserializer synchronize more than 4 cameras?
No. GMSL2 deserializers in common use cap out at four camera inputs per chip. Once a system needs five or more synchronized cameras, you need multiple deserializer chips, and frame alignment becomes a topology decision between those chips rather than a single-chip configuration setting.
### Why does daisy-chaining GMSL2 deserializers break frame sync?
Daisy-chaining has one deserializer generate the sync pulse and relay it to the next deserializer over a GPIO link, instead of both chips receiving the reference directly from a shared source. That relay adds a full extra hop of propagation delay before the signal reaches the second chip's cameras, a delay that is orders of magnitude larger than the tight single-chip skew budget. Cameras behind the second chip end up capturing measurably later than cameras on the first chip, on every frame.
### What is the correct way to synchronize multiple GMSL2 deserializer chips?
Use a parallel-subordinate fanout. Generate one shared reference on the host with a hardware timer or PWM peripheral, then distribute it on length-matched traces or equal cable runs directly to every deserializer's sync input at the same time. Configure each chip independently as a subordinate; none of them should generate the pulse or relay it to another chip.
### Can a software GPIO toggle work as the shared sync reference for multiple deserializers?
No. A GPIO toggled from a software loop carries scheduling jitter in the microsecond-to-millisecond range, which is large enough to defeat the entire purpose of hardware sync. The shared reference needs deterministic, low-jitter timing from a hardware timer or PWM source. Fixing the topology does not help if the source feeding it is unstable.
### How do I verify that a multi-deserializer camera array is synchronized?
Read back each deserializer's own measured sync-alignment value after any wiring change, then separately capture and compare host-side frame timestamps from a camera behind each chip. A small, steady offset points to a cable or trace length mismatch. A growing or unpredictable offset between chips usually means a daisy-chain link exists somewhere in the topology that should have been a parallel fanout instead.
---
*ProventusNova helps hardware startups solve embedded systems problems fast. [Talk to us about GMSL2 multi-camera bring-up](/services/gmsl).*
---
## Jetson Nano vs Orin Nano: Same Name, Different Chip
URL: https://proventusnova.com/blog/jetson-nano-vs-orin-nano/
Published: 2026-08-03
Author: Andres Campos
Tags: jetson nano, jetson orin nano, jetson comparison, migration, edge ai
Jetson Nano and Orin Nano share a name, not an architecture. Compare the Maxwell-to-Ampere jump, the JetPack stack change, and why it's a re-port.
"Jetson Nano vs Orin Nano" shows up in search a lot lately, mostly from people who assume this is a simple hardware refresh, order an Orin Nano devkit, and then discover their old Jetson Nano image doesn't boot, their carrier board doesn't fit the module, and their camera driver doesn't load. It isn't a refresh. Jetson Nano and Orin Nano share a product name and a rough price point, and almost nothing else.
## Key Insights
- Jetson Nano (Tegra X1, Maxwell GPU, 2019) and Orin Nano (Orin SoC, Ampere GPU, 2023) are two full GPU generations apart, not a version bump
- Jetson Nano is end-of-life with a last shipment date of January 2027; Orin Nano is active through January 2032
- The two modules use the same 260-pin SO-DIMM connector standard but different pinouts, they are not interchangeable on the same carrier board
- Software is not forward compatible: Jetson Nano tops out at JetPack 4.6.x (CUDA 10.2, Ubuntu 18.04); Orin Nano runs JetPack 6.x (CUDA 12.6, Ubuntu 22.04)
- NVIDIA rates Nano at 472 GFLOPS (FP16) and Orin Nano at up to 40 TOPS (quantized inference), different units measuring different things, but every directly comparable axis, CUDA core count, memory bandwidth, real-world inference speed, moved by a full order of magnitude or more
## What's different between Jetson Nano and Orin Nano?
Jetson Nano runs NVIDIA's Tegra X1 SoC, the same chip family used in the original Nintendo Switch, with a Maxwell-generation GPU: 128 CUDA cores, no Tensor Cores, no DLA, quad-core ARM Cortex-A57 CPU, and 4GB of LPDDR4 at 25.6 GB/s. It launched in 2019 as a low-cost entry point into Jetson development and was never meant to be a production AI inference platform, more a way to get students and hobbyists writing CUDA code on cheap hardware.
Orin Nano runs the Orin SoC, an Ampere-generation GPU with either 512 or 1024 CUDA cores depending on the 4GB or 8GB variant, an 8-core (4GB) or 6-core (8GB) ARM Cortex-A78AE CPU, and up to 68.3 GB/s of memory bandwidth. It's a genuinely current platform, sharing its architecture with the same Orin family used in AGX Orin and Orin NX production designs. See [Jetson Orin AGX vs Orin NX vs Orin Nano](/blog/jetson-orin-agx-vs-orin-nx-vs-orin-nano) if you're also deciding between Orin variants.
| | Jetson Nano | Orin Nano 8GB |
|---|---|---|
| **SoC** | Tegra X1 | Orin (T234) |
| **GPU architecture** | Maxwell | Ampere |
| **CUDA cores** | 128 | 1024 |
| **CPU** | Quad-core Cortex-A57 | 6-core Cortex-A78AE |
| **Memory** | 4GB LPDDR4 | 8GB LPDDR5 |
| **Memory bandwidth** | 25.6 GB/s | 68.3 GB/s |
| **AI performance** | 472 GFLOPS (FP16) | 40 TOPS |
| **DLA** | None | None |
| **CUDA version** | 10.2 | 12.6 |
| **JetPack / L4T** | 4.6.x / R32.7.x | 6.2.2 / R36.5.0 |
| **Ubuntu base** | 18.04 | 22.04 |
| **Connector** | 260-pin SO-DIMM (Nano/TX1/TX2 NX family) | 260-pin SO-DIMM (Orin NX/Nano/Xavier NX family) |
| **Lifecycle status** | End of life, last shipment Jan 2027 | Active through Jan 2032 |
Neither module has a DLA (Deep Learning Accelerator), the fixed-function inference block present on AGX Orin and Orin NX. If your workload leans on DLA offload, Orin NX is the module to look at, not Orin Nano.
## Same connector, different pinout: the carrier board trap
This is the mistake we see most often. Jetson Nano and Orin Nano both use a 260-pin SO-DIMM style module connector, so a board with the right physical socket looks compatible at a glance. It isn't.
Jetson Nano's pinout is shared with Jetson TX1 and TX2 NX, an older pin mapping tied to the Tegra X1/X2 I/O layout. Orin Nano's pinout is shared with Orin NX and Xavier NX, a separate, newer mapping. Plugging an Orin Nano module into a Jetson Nano carrier board will not work, and depending on which pins carry power versus signal on each side, it's the kind of mistake that can damage a board rather than just fail to boot.
If you're planning a hardware refresh around this migration, treat it as a new carrier board design targeting the Orin NX/Nano pinout, not a drop-in module swap. We cover the Yocto side of standing up a fresh Orin Nano carrier board in [flashing a custom Yocto image to Jetson Orin Nano Super](/blog/yocto-custom-image-flash-jetson-orin-nano-super).
## The software stack doesn't carry over either
Jetson Nano is stuck on JetPack 4.6.x, L4T R32.7.x, a kernel 4.9-based BSP running Ubuntu 18.04 with CUDA 10.2. NVIDIA has marked this branch legacy, it receives no new features, only security patches on a best-effort basis. Orin Nano runs JetPack 6.2.2, L4T R36.5.0, kernel 5.15, Ubuntu 22.04, CUDA 12.6, the actively developed current stable branch. See our [JetPack versions and L4T compatibility table](/blog/jetpack-versions-l4t-compatibility-table) for the full version matrix across every Jetson generation.
The practical effect: there's no upgrade path, no OTA, no in-place migration. You're standing up a new BSP from scratch on Orin Nano. Anything built against JetPack 4.6's toolchain (CUDA 10.2, TensorRT for Maxwell's compute capability 5.3) needs to be rebuilt, not just recompiled, against JetPack 6's stack targeting Ampere's compute capability 8.7. TensorRT engine files in particular are architecture-specific and won't load across this jump; you rebuild the engine on the target hardware.
Camera drivers hit the same wall. Jetson Nano's camera path runs through the older Tegra X1 VI/CSI hardware and an earlier Argus daemon implementation. Orin Nano uses `tegra-camera-platform`, a different driver architecture with its own device tree bindings. A custom V4L2 sensor driver written for Jetson Nano is a real re-port on Orin Nano, not a recompile, expect to touch device tree overlays, VI channel mapping, and Argus configuration.
## What actually carries over
It's not all bad news. The parts of Jetson development that live above the BSP layer transfer better than the hardware does.
GStreamer pipeline concepts carry over. Element names change (Jetson Nano's `nvvidconv` and `nvv4l2decoder` behave differently under Orin's memory subsystem, and buffer NVMM handling shifts) but the pipeline model, the reasons you'd reach for hardware-accelerated decode versus CPU decode, and general debugging approach (checking `gst-inspect-1.0`, tracing with `GST_DEBUG`) are the same skills. Same story for ROS2: a robotics stack built around ROS2 nodes doesn't care which Jetson SoC it's running on, as long as the underlying sensor drivers and TensorRT models are re-ported first.
NVIDIA SDK Manager still drives the flashing and package install process, the workflow of selecting a target, downloading a BSP, and flashing over USB or via SD card is conceptually the same, even though you're picking a different target board and a different JetPack version. Documentation and community support is also stronger on the Orin side. Jetson Nano's forum activity has been declining for years as NVIDIA shifted developer attention to Orin; Orin Nano has an active developer community, current NVIDIA forum support, and code examples still being written against its stack today.
None of this changes the hardware answer. You still need a new carrier board and a re-ported BSP. But the engineering skills and workflow habits your team built on Jetson Nano aren't wasted, they transfer to figuring out the Orin re-port faster than starting from zero would.
## Should you migrate from Jetson Nano to Orin Nano now?
If you're building on Jetson Nano today, the honest answer is: yes, start planning the move. January 2027 sounds far off, but a production hardware design, BSP re-port, and camera/driver validation cycle easily takes 6 to 12 months on its own, and that's before you've qualified a new carrier board.
Module pricing isn't the reason to hesitate. Orin Nano 8GB runs about $149, Orin Nano 4GB about $99, both close to what Jetson Nano cost at retail. The real cost of this migration is engineering time: the carrier board redesign, the BSP bring-up, and the camera driver re-port, not the module itself.
Orin Nano is the right target if your workload fits in its lane: no DLA requirement, up to 4 MIPI CSI cameras, and a design that doesn't need more than 68 GB/s of memory bandwidth. If you're running sustained multi-camera inference or need DLA offload for a TensorRT-heavy pipeline, look at Orin NX instead, same pinout family as Orin Nano, meaning your new carrier board design can support both on one board across cost tiers. The [Orin AGX vs NX vs Nano comparison](/blog/jetson-orin-agx-vs-orin-nx-vs-orin-nano) breaks down that decision in more detail.
Either way, this is a from-scratch bring-up: new carrier board, new BSP, re-ported camera drivers, rebuilt inference engines. Budget for it like one.
---
*Migrating off Jetson Nano before the January 2027 cutoff? Our [Jetson expert support service](/get-expert-nvidia-jetson-support) handles the carrier board redesign, BSP bring-up, and camera driver re-port as one fixed-bid engagement.*
---
## MQTT and Protobuf IPC for Edge AI Appliances
URL: https://proventusnova.com/blog/mqtt-protobuf-ipc-edge-ai-appliances/
Published: 2026-08-03
Author: Aaron Angulo
Tags: mqtt, protobuf, edge ai, docker, embedded linux
How we structure MQTT and protobuf IPC between containerized services on edge AI appliances, plus logging, restart policy, and watchdog recovery.
Most edge AI appliances end up running five or six independent programs on one board: a capture service reading the camera or sensor array, an inference service running the model, a connectivity service managing BLE or WiFi, a fusion service combining sensor readings, and an OTA or provisioning service handling updates. The question that decides whether that fleet stays maintainable is how those programs talk to each other. On appliances we've built, the answer is MQTT and protobuf IPC: a local broker carrying protobuf-encoded messages as the only communication path between services, with no direct sockets and no shared code. This post covers why that pattern holds up in the field, along with the container structure, logging strategy, and recovery layers that turn it from a demo into something you can leave running unattended for months.
## Key Insights
- **The MQTT broker is the only IPC surface**: services never import each other's code or open direct sockets to one another; if a message doesn't cross the broker, it isn't an interface between services
- **Protobuf keeps the wire format compact and schema'd**: services agree on message shape through a `.proto` contract instead of hand-rolled JSON parsing that drifts out of sync over time
- **Per-service privileged containers trade isolation for hardware reach**: acceptable on a single-tenant appliance where the container fleet is the entire system, not a pattern to carry over to shared infrastructure
- **Logging is split by severity, not by service**: verbose and debug logs live in a RAM-backed tmpfs and disappear on reboot; only error-and-above logs get written to flash, capped and rotated
- **Recovery is layered, not left to Docker's restart policy**: an external process supervisor owns restart decisions for the whole fleet, and a hardware watchdog wired through an I2C GPIO expander is the last resort when userspace itself has wedged
## MQTT and protobuf IPC as the only bus between services
The obvious alternative to a broker is direct connections: give the inference service a socket to the capture service, give the fusion service a socket to both, and so on. That works until the fourth or fifth service joins the fleet, at which point you're maintaining N-squared point-to-point wiring, and adding a new service means touching every existing one that needs to talk to it. A local MQTT broker collapses that to one connection per service, always to the broker, regardless of fleet size. Adding a downloader or provisioning service later means subscribing it to the topics it cares about; nothing else changes.
We run `eclipse-mosquitto` as its own container, bound to `127.0.0.1:1883`, with no cloud dependency for local traffic. The broker address is injected as an environment variable, `MQTT_BROKER_ADDRESS`, so the exact same service image runs against a remote broker on a developer's laptop and the loopback broker on the device, unchanged. That single decision removes an entire class of "works on my machine, breaks on the board" bugs, because the IPC path is identical in both environments.
Protobuf as the payload format matters more than it looks. JSON would work fine if every service were written in the same language, but a fleet of services written in different languages needs a contract that isn't tied to any one of their native serialization formats. A `.proto` schema compiles to typed bindings in each language, so a field rename or a new enum value is caught at build time in every service that consumes it, instead of surfacing as a silent `KeyError` on a device in the field six months later.
The other piece worth calling out is retained topics. Configuration and runtime state get published once with the MQTT retain flag set, and any service that subscribes afterward, whether it started a second later or after a container restart, immediately receives the last published value without waiting for the next update. That makes the broker the single source of truth for runtime config and removes the need for a separate config-distribution path (a shared file, a database, a sidecar). A service that restarts mid-flight doesn't need special-case bootstrap logic; it just subscribes and gets caught up.
## Structuring the container fleet
Each service gets its own container, one responsibility per container, sharing a common baseline set through a YAML anchor rather than duplicating settings across five service definitions:
| Setting | Value | Why |
|---|---|---|
| `restart` | `"no"` | Docker doesn't own recovery; an external supervisor does |
| `network_mode` | `host` | every container reaches the loopback broker with no bridge/NAT hop |
| `logging.driver` | `json-file` | standard driver, but capped (see logging section) |
| `logging.options.max-size` | `1m` | hard ceiling on flash writes per log file |
| `logging.options.mode` | `non-blocking` | log I/O never stalls the application |
| `privileged` | `true` (device-touching services only) | direct access to host devices and buses |
The broker itself is the one service that stays unprivileged; it only needs the shared log mount, since it isn't reaching into hardware.
If you've only ever run one container on a Genio or Jetson board (see our post on [Docker with GPU acceleration on MediaTek Genio](/blog/mediatek-genio-docker-gpu-containers)), the jump to a fleet mostly means deciding, per service, how far to open the door:
1. **Memory caps on heavy services.** A capture service holding frame buffers gets a `deploy.resources.limits.memory` ceiling in the low hundreds of MB, so a leak in one service can't OOM the whole board.
2. **Device passthrough scoped to what each service touches.** An audio or voice service gets `devices: [/dev/snd]` plus read-only ALSA config mounts; it doesn't get the whole `/dev` tree.
3. **`pid: host` only where a service must see host processes.** A host-side Bluetooth manager typically needs this; a pure compute service doesn't.
4. **Selective binary bind-mounts instead of a wholesale rootfs mount, where feasible.** If a service only shells out to a handful of specific host binaries, mount those paths rather than the whole filesystem.
The two settings that make the rest of this possible, `network_mode: host` and a full `/:/host_root` bind-mount on `privileged: true` containers, are a deliberate trade. They give up per-container network isolation and most of the filesystem sandboxing Docker normally provides, in exchange for services being able to reach real host devices, firmware blobs, and tool binaries without baking a copy of each into every image. On a single-tenant appliance where the container fleet is the entire software stack, that's a reasonable trade. On shared or multi-tenant infrastructure, it would not be.
## Flash-wear-aware logging
Embedded flash (eMMC or SD) has a finite number of write cycles, and a chatty service fleet logging at debug level around the clock will wear through it faster than most teams expect, especially on a device that runs for years without a storage replacement. The fix is splitting log destinations by severity:
| Log class | Destination | Survives reboot | Notes |
|---|---|---|---|
| Verbose / debug / info | `/tmp` (tmpfs, RAM-backed) | No | every container mounts the same RAM disk, so all services log to one place |
| Error and above | Docker `json-file` on flash | Yes | capped by `max-size` and `max-file`, non-blocking so log writes never stall the app |
This changes how debugging happens day to day, for the better. Live tailing during development or a field debug session reads the RAM logs directly:
```sh
tail -F /tmp/.log
tail -F /tmp/.log | grep -i
```
Post-mortem after a reboot or a crash only has the persisted error stream to work with:
```sh
docker logs
```
The verbose logs are gone after a power cycle, on purpose. Keeping only error-and-above on flash is the entire point: you get full visibility while a device is up and reachable, and you get just enough on-flash history to diagnose why it went down, without writing gigabytes of debug chatter to storage that has to survive the product's whole field life.
## Recovery in layers: supervisor, then hardware watchdog
Every service container is configured with `restart: "no"`. That's deliberate: Docker's built-in restart policies are per-container and don't know about dependency order, backoff, or what "healthy" means for your specific fleet. Instead, an external process supervisor, a plain host-level process, owns start, stop, and restart decisions for the whole set. Centralizing that logic in one place means a single service crash-looping can be handled with backoff instead of Docker hammering it in a tight restart cycle, and a service that depends on another coming up first can wait for it, which Docker's flat restart model has no concept of.
Above the supervisor sits a hardware watchdog, for the case the supervisor itself can't help: a kernel panic, a wedged I2C bus, or the supervisor process itself hanging. The watchdog is kicked periodically through an I2C GPIO expander line. If the kick stops, because the supervisor or some critical service has wedged badly enough that nothing in userspace is running anymore, the watchdog forces a hardware reset. It's not a replacement for the supervisor, it's the layer beneath it: the recovery path for the failure mode where software-level recovery is no longer possible. The exact I2C address, expander part, and pin assignment are board-specific and need to be verified against your hardware before you rely on them; the pattern (a hardware timer, kicked by a live supervisor, resetting the board when the kick stops) is what carries over.
Getting this three-layer setup right (broker-mediated IPC, a supervisor with real restart policy, a watchdog underneath it) is most of what separates an appliance that self-heals from one that needs a truck roll every time a service wedges. If your fleet also has a service with a real-time constraint buried in it, a control loop inside the fusion service, for example, that's a separate problem worth solving deliberately; see our post on [PREEMPT_RT on Jetson Orin](/blog/jetson-orin-preempt-rt-real-time-kernel) for what that involves.
## Frequently Asked Questions
### What is the best way to handle inter-process communication on an edge AI device?
For a fleet of independent services on one board (capture, inference, connectivity, fusion, OTA), a local MQTT broker carrying protobuf messages works well because it decouples every service from every other one. No service imports another's code or opens a direct socket; the broker is the entire IPC surface. This matters more as the service count grows, since the alternative is N-squared point-to-point wiring.
### Why use MQTT instead of gRPC or D-Bus for edge device IPC?
gRPC needs a client stub for every service pair, so five services means ten connections to wire and maintain. D-Bus is Linux-specific and gets awkward across container mount namespaces. A local MQTT broker gives every service one connection (to the broker) regardless of how many other services exist, and publish/subscribe means adding a new service does not require touching the ones already running.
### How do you protect eMMC or SD card flash from wear in an embedded Linux appliance?
Split logging by severity. Route verbose and debug logs to a RAM-backed tmpfs mount that every container shares, and only write error-and-above logs to flash, capped with a max file size and rotation count. On a device running continuously for months, this is the difference between a log volume that never touches flash under normal operation and one that wears out the storage in weeks.
### What is a hardware watchdog and do I need one for an edge AI appliance?
A hardware watchdog is a timer, often behind an I2C GPIO expander, that forces a hard reset if it stops being kicked. You need one any time software recovery might not be enough: a kernel panic, a wedged I2C bus, or a supervisor process that hangs. It's the layer beneath your process supervisor, not a replacement for it, and it only matters at the point where userspace can no longer help itself.
### Should each service run in its own Docker container on an embedded device?
Yes, when the services have different privilege and lifecycle needs. One container per responsibility (capture, inference, connectivity, fusion, provisioning) means you can restart, resource-cap, and update each independently, and a crash in one doesn't take down the others. The tradeoff is that privileged, host-networked containers on a single-tenant appliance give up most container isolation in exchange for direct hardware access, which is a fair trade on a device that only ever runs your software.
---
*ProventusNova helps hardware startups deploy production edge AI appliances fast. [See our EdgeAI Deployment service](/services/edgeai-deployment).*
---
## NFC-DEP P2P Pairing on MediaTek Genio 720
URL: https://proventusnova.com/blog/nfc-dep-p2p-pairing-mediatek-genio-720/
Published: 2026-08-03
Author: Aaron Angulo
Tags: mediatek, genio, nfc, pn7160, embedded linux
NFC-DEP P2P pairing on MediaTek Genio 720 stalling for minutes at a time? We found a phase-lock trap in the NCI 2.0 timing and fixed it with one parameter.
NFC-DEP P2P pairing on MediaTek Genio 720 worked fine in our first bench test, sub-second, every time, then fell apart the moment we ran two boards side by side for more than a few minutes. Pairing would suddenly take five to fifteen minutes instead of under a second, recover on its own, then stall again, with nothing obviously wrong in the logs. Both boards ran the exact same PN7160 driver code, negotiating initiator and target roles over NCI 2.0 passively, which is what made the failure hard to see: there was nothing wrong with the protocol implementation. Two identical devices running synchronized timing windows were locking into the same phase instead of drifting apart, and that trap only shows up once you let two boards run long enough to find each other.
## Key Insights
- Symmetric NFC-DEP polling code on two identical boards doesn't reliably diverge into initiator and target roles on its own. Software-managed LISTEN/POLL windows can resynchronize instead of complementing.
- The failure mode: both boards spend most of their time in the same RF phase, both listening (no field from either side) or both polling (RF collision), producing five to fifteen minute pairing delays mid-session.
- The fix is a single RF_DISCOVER command covering both NFC_A_PASSIVE_LISTEN and NFC_A_PASSIVE_POLL, combined with randomizing the NCI TOTAL_DURATION parameter per pairing attempt (150 to 350 milliseconds).
- Two boards with different randomized cycle rates accumulate phase drift at roughly 1 to 3 Hz, guaranteeing a complementary LISTEN/POLL overlap within about 400 milliseconds.
- Role isn't chosen by application code. It falls out of the RF_INTF_ACTIVATED_NTF payload: byte[3] tells you whether you were found (target) or found the other side (initiator).
## Why NFC-DEP P2P Pairing on MediaTek Genio 720 Kept Stalling
NFC-DEP P2P in passive NFC-A mode at 106 kbps works like this: the initiator generates the 13.56 MHz RF field and sends `ATR_REQ`; the target does not generate a field, it modulates the initiator's field and responds with `ATR_RES`. Both sides run the same code base and the same chip. Nothing pre-assigns a role, it comes out of whichever side happens to be generating the field when the other side shows up. The NCI 2.0 state machine that governs this is `RFST_IDLE → RF_DISCOVER → RFST_DISCOVERY → RF_INTF_ACTIVATED_NTF → RFST_POLL_ACTIVE / RFST_LISTEN_ACTIVE`, and there's one setup step easy to get wrong before any of that matters: `RF_SET_LISTEN_ROUTING` has to be called once, from `RFST_IDLE`, to route the NFC-DEP protocol to the device host. Skip it and the chip silently discards incoming activations even while `RF_DISCOVER` is running, no error, just nothing happening.
Our first implementation handled role negotiation the way it reads most naturally in application code: alternate the board between listen-only and poll-only `RF_DISCOVER` commands in software, half-second to one-second windows, with a `pair()` timeout firing every 30 seconds that restarted the cycle with fresh random jitter if nothing had happened. On a single board, tested against a phone or a reference reader, this looked completely fine.
Put two of our own boards next to each other and let them run, and the failure showed up: because both boards were running identical timing code, when their 30-second timeouts fired at close to the same moment, they'd restart with new jitter but often land back on the same phase. Instead of one board polling while the other listens, both would spend long stretches doing the same thing at the same time. Both listening means no RF field from either side, so nothing to activate. Both polling means two fields colliding, so no clean activation either way. The result was pairing delays of five to fifteen minutes in the middle of a session that had been pairing in under a second minutes earlier.
## The Phase-Lock Math: Why Two Boards Resynchronize Instead of Diverging
Once we stopped treating this as a protocol bug and started treating it as a timing problem, the fix fell out of the math. Two boards running fixed, identical discovery windows have a phase drift rate of zero relative to each other. If a restart happens to land them on the same phase, they stay there indefinitely, and the only thing that ever breaks the tie is the random jitter applied at each 30-second restart, which is exactly the intermittent "it recovers, then stalls again" pattern we were seeing.
The alternative is to make sure the two boards are never running the same cycle rate in the first place, so the phase between them is always moving. Randomizing the discovery timing per pairing attempt is enough:
| Metric | Value |
|---|---|
| Board A TOTAL_DURATION | 200 ms → 5 cycles/sec |
| Board B TOTAL_DURATION | 280 ms → 3.57 cycles/sec |
| Phase drift rate | \|5 − 3.57\| = 1.43 cycles/sec |
| Time to full desynchronization | 1 / 1.43 ≈ 700 ms |
| Expected time to complementary overlap | ~350 ms |
With each board picking its own `TOTAL_DURATION` at random for every pairing attempt, the two cycle rates are almost never equal, so the relative phase between them constantly advances instead of sitting still. Within roughly one drift period, well under half a second in practice, one board is guaranteed to be polling while the other is listening. That complementary overlap is the only thing NFC-DEP needs in order to activate.
## The Fix: One RF_DISCOVER Call and a Randomized TOTAL_DURATION
The correct approach doesn't alternate anything in application code at all. Send a single `RF_DISCOVER` command that requests both `NFC_A_PASSIVE_LISTEN` and `NFC_A_PASSIVE_POLL` in the same call. The NFCC itself then cycles between the two technologies internally, at `TOTAL_DURATION` intervals, and that's the one parameter we randomize per `pair()` call:
```python
# _configure_dep() -- called once per pair() call
duration_ms = random.randint(150, 350)
self._proto.send_command(nci.GID_CORE, nci.OID_CORE_SET_CONFIG, bytes([
2,
0x00, 2, duration_ms & 0xFF, (duration_ms >> 8) & 0xFF, # TOTAL_DURATION
0x32, 1, 0x40, # LA_SEL_INFO = 0x40 (NFC-DEP capable SAK)
]))
# RF_DISCOVER_MAP: map NFC-DEP for both poll and listen
self._proto.send_command(
nci.GID_RF, nci.OID_RF_DISCOVER_MAP,
bytes([1, nci.PROTOCOL_NFC_DEP, 0x03, nci.INTF_NFC_DEP]),
)
# RF_DISCOVER: both technologies in one command
self._proto.send_command(
nci.GID_RF, nci.OID_RF_DISCOVER,
bytes([2,
nci.NFC_A_PASSIVE_LISTEN, 0x01,
nci.NFC_A_PASSIVE_POLL, 0x01]),
)
```
Role determination then comes straight out of the activation notification, not from anything the application decided in advance:
```python
if payload[3] == nci.NFC_A_PASSIVE_LISTEN: # 0x80
role = 'target' # we were found by an initiator
else: # 0x00 = NFC_A_PASSIVE_POLL
role = 'initiator' # we found a target
```
Getting this loop to run reliably in practice meant closing a handful of other NCI 2.0 gaps at the same time, all of them the kind of thing that only shows up once you're running the fix continuously across many pairing cycles instead of once on a bench:
1. **RF_SET_LISTEN_ROUTING must be called from RFST_IDLE.** Send it while the chip is in RFST_DISCOVERY and it returns SEMANTIC_ERROR. We now always issue `RF_DEACTIVATE(DEACT_IDLE)` before re-calling routing setup, instead of assuming we know the chip's current state.
2. **RF_DEACTIVATE has an NTF guard.** When the `RF_DEACTIVATE` response status isn't `STATUS_OK`, meaning the chip was already idle, no `RF_DEACTIVATE_NTF` notification is coming. Waiting for it anyway burns the full two-second `recv_ntf` timeout on every single deactivation. Check the response status first, and only wait for the notification if the chip was active to begin with.
3. **RF_DEACTIVATE_NTF can arrive mid data exchange.** If the RF link drops while data is in flight, because the peer moved away, the NFCC sends `RF_DEACTIVATE_NTF`. If `recv_data` doesn't check for it explicitly, it silently consumes the notification and then waits the full five-second data timeout for a packet that's never coming. One board reports a successful pairing while the other one just stalls. The fix is to fast-fail in `recv_data` the moment that notification shows up.
4. **The `_running` flag needs an unconditional deactivate guard.** A previously swallowed exception can leave `_running` set to `False` while the chip is still sitting in `RFST_DISCOVERY`. The next `pair()` call then skips deactivation entirely, jumps straight to `_configure_dep()`, and hits `SEMANTIC_ERROR` on `RF_SET_LISTEN_ROUTING` for reasons that look unrelated to the actual cause. We now send `RF_DEACTIVATE` unconditionally every time and let the chip's own status response tell us whether it was already idle.
## Shipping the Fix Without Losing It on Reboot
The driver runs inside a Docker container on the target hardware, which surfaced a second, much more mundane problem once the fix was ready to deploy: copying updated files into a running container does not survive a full reboot. `docker compose up -d` recreates the container from its base image on every restart, wiping out anything that was copied in after the fact.
The pattern that survives reboots is to bind-mount the driver source from a host path into the container, read-only, and add a systemd drop-in on the service that manages the pairing daemon, with an `ExecStartPre` step that copies the updated driver files into the container's Python virtual environment before the application process starts:
```ini
# /etc/systemd/system/nfc-pairing-app.service.d/pn7160-overlay.conf
[Service]
ExecStartPre=/usr/bin/docker exec nfc-app /bin/sh -c \
'cp /opt/nfc-driver/pn7160/*.py /opt/venv/lib/python3.12/site-packages/pn7160/'
```
That survives a full reboot cleanly. Only a `docker compose down` followed by a fresh image reload from a tarball wipes it, which is rare enough in practice to treat as a known exception rather than something to build around.
If you're bringing up the I2C bus the PN7160 sits on, our walkthrough on [SPI and I2C peripheral setup on MediaTek Genio](/blog/mediatek-genio-spi-i2c-peripheral-setup) covers bus numbering and the device tree conflicts that show up before you ever get to the NFC layer. And if your NFC stack needs to live inside a container long-term rather than as a one-off test, see [Docker with GPU acceleration on MediaTek Genio](/blog/mediatek-genio-docker-gpu-containers) for the broader container deployment pattern this fix builds on.
## Frequently Asked Questions
### What causes NFC-DEP P2P pairing to fail or stall intermittently?
The most common cause on custom NFC-DEP implementations is a timing collision between the two devices' discovery windows, not a protocol bug. If both sides alternate between listen-only and poll-only discovery on independent software timers, they can resynchronize onto the same phase instead of diverging into complementary initiator and target roles, producing multi-minute pairing delays that come and go without a clear pattern.
### What is a phase-lock trap in NFC role negotiation?
It's a failure mode where two devices running identical, synchronized timing code lock into the same discovery phase instead of drifting apart. Both boards end up listening at the same time (no RF field, nothing to activate) or polling at the same time (RF collision), so the pairing handshake that's supposed to take under a second instead takes minutes.
### How do you set TOTAL_DURATION in NCI 2.0 for NFC-DEP pairing?
TOTAL_DURATION is set via CORE_SET_CONFIG (config parameter 0x00, 2 bytes, little-endian) before RF_DISCOVER. It controls how long the NFCC spends cycling through each requested RF technology; with both listen and poll requested in one RF_DISCOVER call, each gets TOTAL_DURATION divided by two. Randomizing the value per pairing attempt, for example 150 to 350 milliseconds, is what prevents two boards from settling into a fixed, matching cycle.
### Why does RF_SET_LISTEN_ROUTING return SEMANTIC_ERROR on the PN7160?
RF_SET_LISTEN_ROUTING can only be called while the chip is in RFST_IDLE. If it's sent while the chip is already in RFST_DISCOVERY, the PN7160 returns SEMANTIC_ERROR and rejects the routing update. The fix is to always issue RF_DEACTIVATE with DEACT_IDLE before re-sending the routing configuration, rather than assuming the chip's current state.
### Does MediaTek Genio 720 support NFC-DEP peer-to-peer pairing?
Yes. We validated NFC-DEP P2P pairing on two Genio 720 (MT8390) boards using a PN7160 NFC controller over I2C, driven from a Python NCI 2.0 driver running in a Docker container. Sub-second pairing is achievable once the discovery timing is handled correctly at the RF_DISCOVER level rather than alternated in application code.
---
*ProventusNova helps hardware startups solve embedded systems problems fast. [Get expert MediaTek Genio support](/get-expert-mediatek-genio-support).*
---
## RAW10 Capture and GPU Debayer on Jetson: the Argus Bypass
URL: https://proventusnova.com/blog/raw10-capture-gpu-debayer-jetson-argus-bypass/
Published: 2026-08-03
Author: Aaron Angulo
Tags: jetson, cuda, v4l2, argus, camera pipeline
When nvargus-daemon degrades under sustained high-fps recording, capture RAW10 over V4L2 and debayer on the GPU with CUDA. What it costs, what breaks.
When `nvargus-daemon` starts throwing `failed to create capture session` errors deep into a continuous recording run, the standard move is a daemon restart, and it usually works, for a while. On Jetson Orin fleets doing sustained high-fps capture, that workaround is known to degrade again after enough recording cycles. The pattern worth knowing for that situation is RAW10 capture and GPU debayer on Jetson: skip Argus and the Tegra ISP entirely, pull raw Bayer off the sensor over V4L2, and demosaic on the GPU with CUDA instead. This is not a first move. It's what you reach for after the restart-and-hope pattern stops holding.
## Key Insights
- The failure pattern that justifies this bypass is specific: `failed to create capture session`, socket/RPC dispatch errors, or zero-byte output files that recur across sustained recording sessions, not a one-time crash
- The real trigger is usually the encode-and-write-to-disk stage falling behind at high fps, not frame capture itself, it just surfaces as an Argus failure
- The replacement pipeline keeps everything zero-copy: V4L2 dmabuf (RAW10/`RG10`) into a CUDA debayer into NVENC, no CPU round trip
- FastVideo CUDA Debayer and CUVILib, the two established libraries for this, are commercially licensed, not free, not open source, and not bundled with JetPack
- Dropping Argus means reimplementing auto-exposure, auto-white-balance, and tone mapping yourself, and the GPU debayer now competes with any other GPU work for the same silicon
## Why RAW10 capture and GPU debayer on Jetson become the fallback
Argus (`nvarguscamerasrc`, `nvargus-daemon`) is the right default on Jetson. It runs the Tegra hardware ISP, handling auto-exposure, auto-white-balance, denoise, and demosaic automatically, and most production camera pipelines should use it. We've written about getting Argus running correctly and debugging its common failure modes in [our Argus driver setup guide](/blog/argus-api-camera-driver-jetson). If your camera works with `v4l2-ctl` but Argus refuses to start, or the daemon deadlocks under load, those are usually fixable without abandoning the ISP path, and we cover the crash-versus-deadlock split and the JetPack 6 `libnvscf` CaptureScheduler regression in [our nvargus crash and deadlock debug guide](/blog/nvargus-crash-capturesched-deadlock-jetson).
The bypass in this post is for a narrower and worse situation: you've already applied the point-release upgrade, you've already got a watchdog restarting the daemon on stall, and the pipeline still degrades under your specific workload. The pattern is consistent across reports of this failure mode: clean recording for the first several sessions, then Argus starts producing `failed to create capture session` on session start, or the socket between the client process and `nvargus-daemon` starts throwing RPC dispatch errors, or a recording completes but leaves a zero-byte file on disk. Restarting the daemon and the application recovers it, but only for a while, and the recurrence gets more frequent the longer the device has been running.
The important diagnostic point is that frame capture itself is rarely the bottleneck. The instability shows up during or right after the encode-and-write-to-disk stage at sustained high frame rates. Argus is the thing that visibly falls over, but it's downstream pressure, not a capture-path bug, that's putting it there. Once you've confirmed that (watchdog logs plus disk write timing are usually enough), the fix isn't to debug Argus harder, it's to remove it from the pipeline so there's nothing left to fall over.
## The bypass pipeline: V4L2 to CUDA to NVENC, zero-copy
The replacement architecture keeps the same zero-copy discipline that made Argus attractive in the first place, it just moves the ISP work off NVIDIA's stack and onto one you own:
1. **Capture raw Bayer directly from the sensor node over V4L2** as `RG10` (RAW10), no ISP involved. This is the same raw path used to bring up a sensor before Argus is ever in the picture, `v4l2-ctl` and a bare `v4l2src` pipeline prove sensor, device tree, and CSI path all work before you build anything on top.
2. **Keep the buffer as a dmabuf**, not a CPU-mapped copy. The V4L2 capture must be configured for dmabuf export so the frame never round-trips through host memory before the GPU touches it.
3. **Debayer on the GPU** with a CUDA imaging library that operates on NVMM/dmabuf buffers directly. This is the step where FastVideo CUDA Debayer or CUVILib do the demosaic work, converting `RG10` into a usable RGB or YUV frame without leaving GPU memory.
4. **Hand the debayered frame to NVENC** through the same NVMM zero-copy path Argus output would have used. If your encoder integration already expects NVMM buffers from `nvarguscamerasrc`, the encoder side of the pipeline barely changes, only what feeds it does.
5. **Write to disk or stream out**, same as before.
| Stage | Argus path | Bypass path |
|---|---|---|
| Sensor read | V4L2 subdev, internal to Argus | V4L2 subdev, direct |
| ISP / demosaic | `nvargus-daemon`, Tegra ISP | CUDA debayer (FastVideo / CUVILib) |
| Buffer handling | NVMM, managed by Argus | NVMM/dmabuf, managed by your code |
| Encode | NVENC via `nvarguscamerasrc` output | NVENC, same zero-copy contract |
| Failure surface | `nvargus-daemon`, single process | Your capture + CUDA code, no daemon dependency |
The tradeoff is visible in that last row. You've traded a single, opaque, NVIDIA-maintained daemon for a pipeline you own end to end, which means the specific failure mode you were chasing (Argus instability under load) goes away, but debugging responsibility for everything downstream of the sensor now sits with your team.
## What you lose when you drop Argus, and who has to rebuild it
This is the part of the bypass that's easy to underestimate in a planning meeting and hard to underestimate once you're staring at a washed-out or green-tinted frame in the field. Argus isn't just a demosaic step, it's a full ISP, and every function it performs has to land somewhere else once it's out of the pipeline.
| ISP function (Argus path) | Who does it after the bypass |
|---|---|
| Demosaic | GPU CUDA debayer |
| Auto-exposure (AE) | Your own GPU/software control loop |
| Auto-white-balance (AWB) | Your own GPU/software implementation |
| Temporal noise reduction | Your own GPU/software implementation |
| Tone mapping | Your own GPU/software implementation |
None of these are drop-in replacements. AE and AWB are closed-loop control problems, you need a metering strategy, a gain/exposure actuation path back to the sensor driver, and enough tuning to avoid hunting or flicker under changing light. Tone mapping and noise reduction are image-quality work that the Tegra ISP has had years of vendor tuning behind it, your first pass will not look as good, and getting it close takes real iteration time against real scenes, not a synthetic test chart.
There's a second cost that's easy to miss because it isn't in the image quality column at all: the CUDA debayer now shares the GPU with anything else you're running there, stitching, other CV processing, or inference. On Argus, ISP work happens on a dedicated hardware block and doesn't touch your compute budget. On the bypass, it does. Budget GPU headroom for the debayer the same way you'd budget it for a model, because it is now competing for the same silicon.
## Licensing reality: CUDA debayer is not free software
This needs to be said plainly because it gets glossed over in vendor conversations: FastVideo CUDA Debayer and CUVILib are commercial products. They are not open source, they are not bundled with JetPack or the Jetson SDK, and they are not free to deploy across a fleet. If a proposal for this architecture doesn't include a line item for per-unit or per-fleet licensing of whichever debayer library you pick, that proposal is missing a real cost, not a rounding error.
The alternative, writing your own CUDA debayer kernel, is a legitimate option and some teams do it, but it is a real computer-vision and CUDA engineering project on its own, not a weekend task bolted onto a capture pipeline. Interpolation quality, edge artifacts, and performance at your target resolution and frame rate all have to be validated against real sensor output, not just a reference test pattern. Whether you buy a commercial library or build your own, the debayer step has a cost that has to be planned for; the only thing that changes is whether that cost shows up as a license fee or as engineering time.
There's a cleaner way out of this entire tradeoff if it's still available to you: choose a sensor module with an onboard ISP, so Argus (and this whole bypass question) never enters the design in the first place. The module emits already-processed frames, and neither the Tegra ISP nor a from-scratch software ISP is in your critical path. If you're early enough in hardware selection that a sensor swap is on the table, it's worth putting on the list before committing to either side of the Argus-versus-bypass decision.
## Frequently Asked Questions
### What causes nvargus-daemon to fail during sustained high-fps recording on Jetson?
In our experience the daemon itself is rarely the root cause. The trigger is usually the encode-and-write-to-disk stage falling behind at high frame rates, and that back-pressure surfaces as an Argus failure: `failed to create capture session` errors, socket or RPC dispatch failures, or zero-byte output files. Restarting `nvargus-daemon` and the application recovers the pipeline temporarily, but on some fleets it degrades again after a number of recording cycles.
### Is FastVideo CUDA Debayer or CUVILib free or open source?
No. Both are commercial, closed-source libraries. Neither ships with the Jetson SDK or JetPack, and neither is free for production use. If you plan to deploy a fleet of devices running GPU debayer, per-unit licensing needs to be budgeted as a real line item, the same way you'd budget a sensor or a connector, not assumed to be included because it runs on Jetson.
### Can you bypass the Argus ISP on Jetson and still get zero-copy capture into the encoder?
Yes, that is the point of the bypass. You capture raw Bayer over V4L2 as a dmabuf, debayer it on the GPU with a CUDA library that operates on NVMM buffers, and hand the result to NVENC without a CPU round trip. The zero-copy chain from sensor to encoder is preserved, you are only replacing what does the demosaic and ISP work, not adding a copy back to host memory.
### What do you lose when you bypass Argus and capture raw V4L2 on Jetson?
You lose the entire Tegra ISP: demosaic, auto-exposure, auto-white-balance, temporal noise reduction, and tone mapping. All of that has to be reimplemented in GPU or software to reach comparable image quality. This is a real engineering project, not a configuration change, and it's the main reason the bypass is a last resort rather than a default architecture.
### Is there a way to avoid nvargus-daemon instability without building a custom GPU debayer pipeline?
Sometimes. If the instability is a known `libnvscf` CaptureScheduler deadlock, a JetPack point release upgrade or a watchdog that restarts the daemon on stall can resolve it without touching your capture architecture. The GPU debayer bypass is worth it only when that class of fix has been tried and the failure keeps recurring under your specific sustained-recording workload, or when a sensor swap to a module with an onboard ISP isn't an option.
---
*ProventusNova helps hardware startups solve embedded systems problems fast. [Get camera pipeline and driver development done in two weeks](/services/csi).*
---
## Jetson Thor T3000 and T2000 vs T5000: which module to pick
URL: https://proventusnova.com/blog/jetson-thor-t3000-t2000-vs-t5000-t4000/
Published: 2026-07-20
Author: Andres Campos
Tags: jetson, thor, t3000, t2000, t5000, blackwell, edge ai, robotics, jetpack 7
NVIDIA's new Jetson Thor T3000 and T2000 compared with T5000 and T4000: FP4 TFLOPS, memory, power, why bandwidth matters, and when Orin still wins.
NVIDIA has filled out the Jetson Thor lineup downward: the **T3000** (865 FP4 TFLOPS, 32GB) and **T2000** (400 FP4 TFLOPS, 16GB) bring the Blackwell-based Thor architecture into mainstream robotics and edge-AI price and power territory, joining the existing T5000 flagship and T4000. Hardware ships **Q1 2027**, with T3000 emulation available in **JetPack 7.2.1 from late July 2026**. The headline engineering fact: the T3000 keeps the T5000's full **273GB/s memory bandwidth**, which is why NVIDIA can claim similar multimodal inference performance at roughly half the size and power.
## Key Insights
- **T3000 = the LLM value pick on paper**: 865 FP4 TFLOPS but the same 273GB/s bandwidth as the T5000, and token generation is bandwidth-bound, not TFLOPS-bound
- **T2000 is the volume play**: 400 FP4 TFLOPS / 16GB for visual AI agents, AMRs, and industrial manipulators, but its full datasheet is not published yet
- **Nothing ships until Q1 2027**: plan current designs on Orin or T5000/T4000; start Thor software work in emulation on JetPack 7.2.1
- **Jetson Agent Skills are real repos, not marketing**: `jetson-device-skills` and `jetson-bsp-skills` on GitHub, executable by coding agents for Linux customization, memory optimization, and benchmarking
- **The memory-optimization story is an Orin story today**: published results reclaim 4–15GB on Orin-class devices, letting designs drop one memory SKU
## What did NVIDIA announce?
Two new modules on the Thor (Blackwell GPU + Arm Neoverse) architecture, positioned below the T5000 and T4000:
- **Jetson T3000**: 865 FP4 teraflops, 32GB LPDDR5X at 273GB/s, eight-core Arm Neoverse CPU, 25GbE, at "roughly half the size and power of the T5000." NVIDIA states it achieves similar inference performance to the T5000 for multimodal workloads: LLMs, VLMs, vision-language-action models, and world foundation models.
- **Jetson T2000**: 400 FP4 teraflops and 16GB of memory, the entry point for visual AI agents, autonomous mobile robots, and industrial manipulators. Detailed specifications (CPU configuration, bandwidth, power range) have not been published; NVIDIA says the datasheet and design guide come closer to release.
With these, the Jetson platform now spans "70 TOPS to 2,000 teraflops", from Orin Nano to T5000, on one software stack.
## Jetson Thor lineup: full spec comparison
| | T2000 | T3000 | T4000 | T5000 |
|---|---|---|---|---|
| **AI compute (FP4)** | 400 TFLOPS | 865 TFLOPS | 1,200 TFLOPS (sparse) | 2,070 TFLOPS (sparse) |
| **GPU** | Blackwell | Blackwell | 1,536-core Blackwell, 5th-gen Tensor Cores | 2,560-core Blackwell, 5th-gen Tensor Cores |
| **CPU** | not yet published | 8-core Arm Neoverse | 12-core Neoverse-V3AE | 14-core Neoverse-V3AE |
| **Memory** | 16GB | 32GB LPDDR5X | 64GB 256-bit LPDDR5X | 128GB 256-bit LPDDR5X |
| **Memory bandwidth** | not yet published | 273GB/s | 273GB/s | 273GB/s |
| **Power** | not yet published | ~half of T5000 | 40–70W | 40–130W |
| **Networking** | not yet published | 25GbE | 3x 25GbE | 4x 25GbE |
| **Availability** | Q1 2027 | Q1 2027 | shipping | shipping |
Specs as published by NVIDIA at announcement; T2000 rows marked "not yet published" are exactly that: treat any number you see elsewhere for them as speculation.
## Why can the T3000 match the T5000 on LLM inference?
This is the part of the announcement worth an engineer's attention. The T3000 has well under half the T5000's FP4 compute, yet NVIDIA claims similar inference performance on multimodal workloads. That claim is credible for a specific reason: **LLM token generation is memory-bandwidth-bound**. Every generated token walks the full weight set, so decode throughput scales with GB/s, not TFLOPS, and NVIDIA lists both modules at the same **273GB/s**.
We see the same physics constantly in [LLM work on Jetson Orin](/blog/llm-inference-jetson-orin-llamacpp-ollama): quantization tiers and memory bandwidth dominate tokens-per-second; raw compute sits idle during decode. What the T5000's extra compute (and 128GB) buys you instead:
- **Prefill speed**: long-context ingestion is compute-heavy
- **Vision encoders and CNN pipelines**: genuinely TFLOPS-bound
- **Bigger models**: 128GB holds weight sets the T3000's 32GB simply cannot
- **Concurrency**: batching multiple streams shifts the bottleneck back toward compute
If your workload is "run a quantized multimodal model and stream tokens," the T3000 is the rational pick. If it's "many camera streams through heavy vision models plus an LLM," the T4000/T5000 tiers still earn their price.
## What are Jetson Agent Skills?
This is the software half of the announcement, and it's more concrete than the name suggests. NVIDIA published **agent-executable skill repositories** on GitHub: [`jetson-device-skills`](https://github.com/NVIDIA-AI-IOT/jetson-device-skills) and [`jetson-bsp-skills`](https://github.com/NVIDIA-AI-IOT/jetson-bsp-skills). Each skill is a repeatable recipe (which tools to call, what outputs to produce, how to validate) that a coding agent executes against your Jetson. Three categories shipped:
1. **Linux customization** for custom carrier boards
2. **Memory optimization** across the stack: bootloader memory carveouts, kernel memory reservation, redundant userspace process cleanup
3. **Model benchmarking** and inference optimization
The published results are specific: up to **15GB reclaimed** (moving a UBTech/Agile Robots/Connect Tech design from Orin 64GB to Orin 32GB), **4GB reclaimed** (SandStar, Orin NX 16GB → 8GB), and a **30% reduction on Jetson TX2 NX** (NoTraffic). The pattern NVIDIA is selling: reclaim memory in software, drop one memory SKU in hardware, keep the performance tier. Skills-driven agent automation is the same pattern we run internally for BSP work. It's a genuine productivity shift when the skills encode real platform knowledge, and NVIDIA encoding its own platform knowledge this way is the strongest endorsement of the approach yet.
Worth noting: **these support the entire Jetson portfolio, Orin included**: you don't need Thor hardware to benefit. On JetPack 7.2, Orin and Thor also converge on one stack: Ubuntu 24.04, kernel 6.8, CUDA 13.0.
## Which module should you pick?
- **Shipping a product in the next 12 months** → this announcement changes nothing for you: Orin (Nano/NX/AGX) and the shipping T5000/T4000 are the options. See our [Orin module comparison](/blog/jetson-orin-agx-vs-orin-nx-vs-orin-nano) for that decision.
- **Designing for 2027 with multimodal/LLM workloads** → T3000 is the default candidate: T5000-class decode throughput, half the power and size, 32GB. Start software now in T3000 emulation on JetPack 7.2.1.
- **Cost-sensitive volume robotics for 2027** → T2000 on paper, but hold hardware decisions until the datasheet lands. 400 FP4 TFLOPS and 16GB is a real tier jump over Orin NX, but power, bandwidth, and I/O are still unpublished.
- **Maximum models, maximum streams** → T5000 remains the flagship: 128GB and 2,070 TFLOPS have no substitute in the lineup.
- **Existing Orin fleet** → the immediately actionable part is Agent Skills: if a memory-optimization pass reclaims even 4GB, moving down one memory SKU at fleet scale is real money, available today, no Thor required.
One BSP-side note for Yocto users: Thor support lives in the `master-l4t-r38.x` line of meta-tegra (JetPack 7.x), separate from the `scarthgap` (JetPack 6 / Orin) branch most production builds use today. Budget for that branch split when planning a mixed Orin + Thor fleet.
## What should you do before Q1 2027?
1. **Prototype in emulation**: T3000 emulation on JetPack 7.2.1 means the software stack, memory budget, and model selection can be validated months before silicon.
2. **Run the memory-optimization skills on your current Orin design**: the savings are useful regardless of whether you ever move to Thor.
3. **Re-run your model-selection math against 273GB/s**: if you sized your module tier by TFLOPS, the bandwidth-bound reality of LLM decode may move you a tier down.
If you're planning a Jetson platform decision (Orin now, Thor later, or a migration between them), [our Jetson engineering team](/get-expert-nvidia-jetson-support/) does this for a living: BSP bring-up, camera pipelines, and model deployment under real memory budgets, on a fixed bid.
*Sources: [NVIDIA's announcement](https://blogs.nvidia.com/blog/jetson-thor-robotics-edge-ai-agent/), the [Jetson Thor product page](https://www.nvidia.com/en-us/autonomous-machines/embedded-systems/jetson-thor/), and the [JetPack 7.2 memory-efficiency deep dive](https://developer.nvidia.com/blog/deploy-agentic-ready-ai-at-the-edge-with-memory-efficiency-in-nvidia-jetpack-7-2/).*
---
## Chromium hardware video acceleration on MediaTek Genio
URL: https://proventusnova.com/blog/mediatek-genio-chromium-video-acceleration/
Published: 2026-07-17
Author: Aaron Angulo
Tags: mediatek genio, chromium, video acceleration, kiosk, yocto, wayland, hmi
Run Chromium on MediaTek Genio with hardware video decode: which Yocto image ships it, how to verify decode is on the VPU, kiosk mode setup, and WebRTC limits.
A browser is the quickest UI stack an embedded product can adopt: your HMI is a web app, your kiosk is a URL, and your frontend team already knows the tools. On MediaTek Genio that browser is Chromium, MediaTek ships an image that includes it, and the difference between a smooth product and a hot, throttling one usually comes down to one question: is video actually decoding in hardware? Here is how the pieces fit on Genio and how to verify each one.
## Key Insights
- Chromium ships in MediaTek's `rity-browser-image`, the top of the RITY image hierarchy, with proprietary codec support included.
- Genio's hardware decoders (H.264/H.265) are exposed through V4L2 by the mtk-vcodec drivers; Chromium reaches them through its V4L2 video decode path on Wayland/Ozone.
- Never assume acceleration: `chrome://gpu` and `chrome://media-internals` tell you what your specific build is doing, and CPU load while playing video is the honest cross-check.
- Treat browser WebRTC encode as software: for camera-out streaming, a native GStreamer pipeline with the hardware encoder is the dependable path.
## Which image gives you Chromium, and what does it cost?
MediaTek's IoT Yocto (RITY) images stack in a strict hierarchy, and Chromium arrives at the top:
| Image | Approx. size | What it adds |
|---|---|---|
| `rity-bringup-image` | ~150 MB | Core tools, SSH, debug |
| `rity-bsp-image` | ~500 MB | Weston, GStreamer, camera, audio |
| `rity-demo-image` | ~1 GB | AI/ML stack (TFLite, ONNX, NeuroPilot) |
| `rity-browser-image` | ~2 GB | Chromium with proprietary codecs |
That 2 GB figure is the honest price of a browser UI, and it buys you a Chromium that MediaTek has already integrated against the platform's Wayland compositor and codec stack, so you are not patching a browser yourself. For products, you have two sane starting points: ship the browser image and strip what you do not need, or derive from `rity-bsp-image` and pull the Chromium recipe in, owning the integration choices explicitly. Prototype on the first; decide deliberately before the second.
Chromium runs on Weston through the Wayland Ozone backend on these images. If you are composing your own launch command, `--ozone-platform=wayland` is the flag that puts Chromium on the compositor properly instead of through legacy paths.
## How does hardware video decode work under Chromium here?
Two layers have to cooperate. The kernel side is solid ground: Genio SoCs expose their hardware H.264 and H.265 decoders as V4L2 devices through the mtk-vcodec drivers, the same decoders our GStreamer pipelines use in [Genio video work](/blog/mediatek-genio-gstreamer-real-time-video). The browser side is Chromium's V4L2 video decode support, which turns a `` element's stream into work for those devices instead of for libavcodec on the CPU.
The reason to verify rather than trust: whether a given Chromium build uses V4L2 decode, and for which codecs, is a build-time and version-dependent decision. Browser upgrades, codec type (H.264 vs VP9 vs AV1, where the web increasingly serves the latter two), and DRM-protected content can each silently change the path. The platform decoder covers H.264/H.265; a site that serves VP9 or AV1 lands on software decode no matter how well the V4L2 path works.
## How do you prove decode is actually in hardware?
Three checks, in order of authority:
1. **`chrome://media-internals`** while your real content plays. Find the player entry and read the decoder it instantiated. A V4L2-backed hardware decoder is named as such; `FFmpegVideoDecoder` or `VpxVideoDecoder` means software. This is per-stream truth, and it catches the codec-mismatch case immediately.
2. **`chrome://gpu`**, the capability view: the Video Acceleration section lists which codecs and resolutions the build believes it can accelerate. If decode capability is absent here, no flag juggling on your content will conjure it.
3. **`top` during playback**, the unfakeable check. Hardware-decoded 1080p sits at low single-digit browser CPU for the decode itself; software decode of the same stream is unmissable across the cores. On a fanless enclosure, thermals make this check for you, unkindly, a few minutes later.
When these disagree with your expectations, work down the stack: does the content codec match what the platform accelerates, does `chrome://gpu` show the capability, and do the V4L2 decoder devices exist and probe cleanly in dmesg? That ordering turns "video is janky" into a specific layer with a specific owner.
## What does a production kiosk setup look like?
The launch pattern that behaves:
```
chromium --ozone-platform=wayland --kiosk --noerrdialogs \
--disable-session-crashed-bubble http://localhost/app
```
Run it as a systemd service tied to the Weston session, with `Restart=always` so a renderer crash is a blip instead of a service call. Two disciplines pay for themselves: keep the flag list minimal and version-controlled (kiosk images grow cargo-cult flags at every debugging session, and each one is an unaudited behavior change), and size RAM for the browser you actually run, since a modern web app in Chromium is comfortably a multi-hundred-megabyte tenant on top of the 2 GB image.
## Where does the browser stop being the right tool?
Outbound video. Chromium's WebRTC encode on embedded Linux is, in practice, a software path, so every outgoing stream is a standing CPU tax, exactly the resource your UI and application need. Genio has a hardware encoder sitting right there; the browser just is not the reliable way to reach it. For camera-to-network products we put capture and encode in a native GStreamer pipeline using the hardware codec and keep the browser for what it is great at: rendering the UI. If a video call inside the browser is a hard requirement, benchmark a real sustained call on your image early, with thermals, not a ten-second demo.
## Where to start
Flash `rity-browser-image`, put your actual content in front of it, and run the three verification checks before any optimization work. You will know within an hour whether your product's video path is hardware-clean, codec-mismatched, or build-limited, and each of those has a different, specific fix.
Building a kiosk or HMI product on Genio and want the video path verified end to end, with the browser integration done right? [Get MediaTek Genio engineering support](/get-expert-mediatek-genio-support).
*Sources: [MediaTek IoT Yocto documentation](https://mediatek.gitlab.io/aiot/doc/aiot-dev-guide/), [Chromium Ozone/Wayland documentation](https://chromium.googlesource.com/chromium/src/+/main/docs/ozone_overview.md), and the [Linux V4L2 codec interface documentation](https://www.kernel.org/doc/html/latest/userspace-api/media/v4l/dev-decoder.html).*
---
## Wi-Fi on MediaTek Genio: MT7921 setup and AP mode
URL: https://proventusnova.com/blog/mediatek-genio-wifi-ap-mode-setup/
Published: 2026-07-16
Author: Andres Campos
Tags: mediatek genio, wifi, mt7921, hostapd, ap mode, yocto, networking
MediaTek Genio Wi-Fi explained: the MT7921 module, mt76 driver and firmware stack on Yocto, hostapd AP mode config, and the production gotchas to catch early.
Every camera device, gateway, and industrial box eventually needs Wi-Fi for one of two jobs: joining a network as a client, or being the network during provisioning and field service. On MediaTek Genio both jobs run through the same part, the MT7921, and through completely standard Linux tooling. This guide covers what the hardware is, how the driver and firmware stack fits together on Yocto, a working AP mode setup with hostapd, and the gotchas that surface between the EVK and production.
## Key Insights
- Genio 510 and newer EVKs carry the MT7921 (Wi-Fi 6 + BT 5.3) as an M.2 module in PCIe or SDIO variants; a Genio 720 EVK shows it as `mt7921e` on PCIe. The Genio 350 uses the older MT7663 over SDIO.
- The driver is mainline mt76; firmware arrives via the `mtk-wireless-firmware` Yocto recipe. AP mode is a userspace addition: `hostapd` plus `iw`, no kernel work.
- `iw list` is the source of truth for AP support and station/AP concurrency, and regulatory configuration (country code, DFS) is the number one reason 5 GHz APs refuse to start.
- The production trap: BSP layers have shipped MT7921 firmware marked as temporary daily builds. Pin a versioned firmware before you ship.
## What Wi-Fi hardware is on a Genio board?
On current EVKs, connectivity is an M.2 NGFF module built around the MT7921: Wi-Fi 6 (802.11ax) plus Bluetooth 5.3, connected over PCIe or SDIO depending on the module variant. On a Genio 720 EVK the boot log makes the PCIe variant explicit:
```
mt7921e 0000:01:00.0: enabling device
mt7921e 0000:01:00.0: ASIC revision: 79610010
mt7921e 0000:01:00.0: HW/SW Version: 0x8a108a10
```
The interface then comes up under a predictable name (`wlp1s0` for the PCIe module). The Genio 350 is the family outlier, pairing with the MT7663 over SDIO rather than the MT7921; if you are targeting the 350, translate the module specifics accordingly, though the userspace in this guide is identical.
The part that keeps this simple: MT7921 is driven by the mainline `mt76` driver family (`mt7921e` for PCIe, `mt7921s` for SDIO) through mac80211. Nothing about Wi-Fi on Genio is vendor-magic userspace; `iw`, `wpa_supplicant`, and `hostapd` behave exactly as they do on any Linux system.
## How do the driver and firmware fit together on Yocto?
Three pieces. The kernel driver (`mt76`/`mt7921*`) ships enabled in MediaTek's BSP kernels. The runtime firmware the driver loads comes from the `mtk-wireless-firmware` recipe in the BSP layer. And your image supplies userspace: for AP work that means
```bitbake
IMAGE_INSTALL:append = " hostapd iw"
```
One firmware note worth catching before production: MediaTek's BSP layer has carried MT7921 firmware packages marked in the recipe comments as temporary daily builds. Daily firmware is fine for an EVK on a desk and a poor foundation for a fleet in the field. Before you ship, check which firmware `mtk-wireless-firmware` actually installs on your build (the `HW/SW Version` and firmware build date in dmesg confirm what loaded at runtime) and pin a specific, tested version in your own layer.
## How do you check what the chip can actually do?
Before designing any Wi-Fi behavior, ask the chip. `iw list` dumps the capability tree; the two sections that matter for AP designs:
```
Supported interface modes:
* managed
* AP
...
valid interface combinations:
* #{ managed } <= 1, #{ AP } <= 1, ...
```
`Supported interface modes` answers "can this be an AP at all" (for MT7921: yes). `valid interface combinations` answers the question teams usually ask too late: can it be a client and an AP at the same time, and on how many channels. Whatever that block says is the contract; firmware will not honor topologies it does not advertise. If concurrency is not offered, design mode switching instead: AP for provisioning, station for operation, which is the pattern most products want anyway.
## What does a working AP setup look like?
A minimal, sane `hostapd.conf` for bring-up on the 5 GHz band:
```
interface=wlp1s0
driver=nl80211
ssid=genio-setup
country_code=US
ieee80211d=1
hw_mode=a
channel=36
ieee80211n=1
ieee80211ac=1
ieee80211ax=1
wpa=2
wpa_key_mgmt=WPA-PSK
rsn_pairwise=CCMP
wpa_passphrase=change-this-passphrase
```
Two deliberate choices in there. `country_code` is not optional decoration: without a regulatory domain, the kernel restricts transmit permissions and 5 GHz AP startup fails in confusing ways; `iw reg get` shows the active state. And channel 36 is a non-DFS channel: DFS channels require a radar-detection wait before beaconing, which is not what you want while validating a bring-up. Get it working on 36 to 48 first, revisit channel planning later.
For the network side, give the AP interface an address and DHCP. With systemd-networkd (standard on RITY images), a `.network` file for `wlp1s0` with a static address plus `DHCPServer=yes` covers provisioning use cases in a few lines; add nftables masquerading only if the device must actually route clients upstream.
Start it in the foreground first (`hostapd -d /etc/hostapd.conf`) so capability and regulatory errors land in your face instead of a journal, then wrap it in a systemd service once it is boring. One more interaction to design deliberately: if `wpa_supplicant` manages the same interface for client mode, stop it before hostapd takes over. Two managers on one interface produces exactly the flaky behavior you would expect.
## What bites in production?
**Regulatory across markets.** The country code that made your lab AP work is a per-market decision at scale, and it changes available channels and power. Decide who sets it (image, provisioning, or runtime logic) and test the markets you ship to.
**Power save vs latency.** mac80211 power saving is great for battery and unhelpful for a provisioning AP or any latency-sensitive link. `iw dev wlp1s0 set power_save off` is the diagnostic; making it policy belongs in your service files where it is visible and reviewable.
**PCIe vs SDIO variants.** The same MT7921 name spans different buses with different throughput ceilings and power behavior. If your carrier design switches the module variant from the EVK you validated on, re-run your throughput and suspend/resume tests; the driver differs (`mt7921e` vs `mt7921s`) even though userspace does not.
**Antenna and certification.** The module is certified as a module, but your enclosure and antenna placement are yours. Plan RF validation with the real mechanicals, not the EVK's desk antennas. Our [Genio hardware design gotchas](/blog/mediatek-genio-hardware-design-gotchas) covers the board-level side of this.
## Where to start
Enumerate capabilities with `iw list`, stand up the minimal hostapd config on a non-DFS channel with an explicit country code, and pin your firmware version the same week Wi-Fi starts working rather than the week before shipping. Wi-Fi on Genio is standard Linux; the wins come from doing the standard things deliberately.
Bringing up connectivity on a Genio product, or designing provisioning flows around AP mode? [Get MediaTek Genio engineering support](/get-expert-mediatek-genio-support).
*Sources: [MediaTek MT7921 product page](https://www.mediatek.com/products/broadband-wifi/mt7921), [hostapd documentation](https://w1.fi/hostapd/), and the [Linux wireless (mac80211/mt76) documentation](https://wireless.docs.kernel.org/).*
---
## PipeWire audio on MediaTek Genio: setup, routing, gotchas
URL: https://proventusnova.com/blog/mediatek-genio-pipewire-audio-setup/
Published: 2026-07-15
Author: Aaron Angulo
Tags: mediatek genio, audio, pipewire, alsa, yocto, i2s, afe
How audio works on MediaTek Genio under Yocto: PipeWire vs ALSA, the AFE's DL/UL paths, PMIC codec routing, missing aplay, and the gotchas that break products.
Audio on MediaTek Genio is better documented in the kernel than anywhere else, and most of the confusion we see comes from not knowing which layer to look at: ALSA exposes the hardware, PipeWire routes it, and the AFE underneath is far more capable than the single stereo device people expect. This guide maps the Genio audio stack on Yocto from /proc/asound up to PipeWire, using what the boards actually report, and covers the handful of gotchas that reliably cost teams days.
## Key Insights
- RITY demo images ship PipeWire as the audio server (with pipewire-pulse for compatibility); minimal bringup images ship no audio server, and often no alsa-utils either.
- The Genio audio front end (AFE) is a set of independent DMA paths: DL devices for playback, UL devices for capture. A Genio 720 EVK registers card `mt8391-evk` with DL0 through DL7, UL0 through UL2, and HDMI playback.
- Capture on the EVKs typically routes through the PMIC codec (mt6359p ADDA) and an AP-side DMIC, not the header I2S pins, which changes what you can safely do with those pins.
- The production traps are userspace, not silicon: missing alsa-utils, and PipeWire's root/user service model getting patched for demo images.
## What does the audio stack look like on a Genio board?
Three layers, cleanly separated. At the bottom, the ASoC drivers register the AFE and codecs as a normal ALSA card. In the middle, ALSA exposes each AFE path as a PCM device. On top, PipeWire (on images that include it) opens those devices and does the routing, mixing, and per-application plumbing.
Which layers you get depends on the image, and this catches people on day one:
| RITY image | Audio layers included |
|---|---|
| `rity-bringup-image` | ALSA kernel layer only, no audio server |
| `rity-bsp-image` | ALSA plus GStreamer, still server-less |
| `rity-demo-image` | Full stack with PipeWire and pipewire-pulse |
On a Genio 720 EVK, here is the hardware's own answer to "what audio do I have":
```bash
$ cat /proc/asound/cards
0 [mt8391evk ]: mt8391-evk - mt8391-evk
$ cat /proc/asound/pcm
00-00: DL0 Playback ... playback 1
00-01: DL1 Playback ... playback 1
00-02: UL0 Capture ... capture 1
00-03: UL1 Capture ... capture 1
00-04: UL2 Capture ... capture 1
00-05: HDMI Playback ... playback 1
00-06 to 00-11: DL2 through DL7 Playback
```
Read that as a map of the AFE, MediaTek's audio front end. Each DL (downlink) entry is an independent playback DMA path and each UL (uplink) entry an independent capture path through the audio interconnect, fanning out to eTDM/I2S interfaces, the PMIC codec, DMICs, and display audio. This is why Genio can run system sounds, a voice pipeline, and display audio without the paths fighting: they are separate devices down to the DMA level, not streams mixed into one device. It is also what makes the platform's Linux-plus-RTOS audio split workable, where a Zephyr cell takes over dedicated UL paths that Linux never claims; we cover that in [Zephyr audio on Genio 700](/blog/mediatek-genio-zephyr-audio).
## How do you inspect and test audio without a desktop?
Bottom up, so a failure tells you which layer to blame.
**ALSA layer.** `cat /proc/asound/cards` confirms the card probed at all. If it is missing, your problem is device tree or driver, not audio configuration. `arecord -l` and `aplay -l` enumerate capture and playback devices, and `speaker-test -D hw:0,0 -c 2` exercises a specific PCM with nothing else in the path. If these commands do not exist, your image lacks alsa-utils; add it:
```bitbake
IMAGE_INSTALL:append = " alsa-utils"
```
That one line is the most common "audio is broken" fix we see, because the kernel side was fine all along and the board simply had no tools.
**PipeWire layer.** On demo images, `wpctl status` shows what PipeWire sees: devices, nodes, and which node is the default sink and source. `pw-top` is the live view, invaluable for spotting a stream that connected to the wrong node or a rate mismatch causing resampling. `pw-cat --record test.wav` plus `wpctl set-default` covers most routing checks without writing a line of code.
**Codec routing layer.** When sound plays but the wrong thing comes out (or nothing does), look at DAPM, ALSA's dynamic power map: `/sys/kernel/debug/asoc/` lists components, DAI links, and widget power states. A capture path that stays powered off under DAPM while you record points at machine-driver routing, not at PipeWire.
## Why is the mic not on the header I2S pins?
Because on many MediaTek reference designs, including Genio EVKs, the onboard capture path runs through the PMIC. The mt6359p PMIC includes an ADDA audio codec, and boards pair it with an AP-side digital microphone. The header's I2S pin group is pinmuxed to I2S in the default device tree, and yet no DAI link references it: the pins are configured but electrically idle.
This matters in two directions. If you are adding an external codec or TDM device, the header I2S/eTDM interface is your attachment point and the AFE has spare paths waiting for it. If you are starved for GPIOs (every embedded project, eventually), those same pins are candidates for reassignment, but only after you verify the routing rather than assume it:
1. Read the sound node in the DTS: enumerate its `dai-link` and `audio-routing` entries and check whether any reference the header I2S DAI.
2. Cross-check live: `arecord -l` for what capture resolves to, and the DAPM tree for whether the I2S-in widget ever powers up.
3. If the group is unused, switch the sound node's pinctrl from the I2S "on" group to the matching "off" group that MediaTek BSPs ship for exactly this purpose, freeing the pins as GPIO.
4. Make the change in a `devtool` kernel workspace and land it with `devtool finish`, so it lives as a tracked patch in your meta-layer instead of a loose local edit.
We have used exactly this sequence to hang a second SPI peripheral off a Genio header without touching audio, and the verification step is the whole trick: trace the DAI and codec routing first, then move pins.
## What breaks when you go from demo image to product?
The recurring one is PipeWire's service model. Upstream, `pipewire-pulse` carries `ConditionUser=!root`: it is designed to run per user, and refuses to start for root. Development images that run everything as root patch that condition out so audio works at a root shell. Carry that patch into a product with real user accounts and you inherit a root-owned audio server, or audio that works in development and dies the day your application drops privileges. For production, keep the upstream model: run PipeWire in a user session for your application user, and leave the root-only patch behind in the demo image where it belongs.
The second is image composition drift: bringup and BSP images have no audio server, so a pipeline that worked on `rity-demo-image` fails on the leaner image your product actually ships. Decide deliberately whether your product wants PipeWire (multiple applications sharing audio, dynamic routing) or bare ALSA (one owner, simplest possible path), and pin the image contents accordingly.
## Where to start
Enumerate first, configure second: `/proc/asound/pcm` tells you what the AFE offers before any userspace opinion gets involved. Pick your server model per the product, not per the demo image. And if part of your audio path needs guarantees Linux scheduling cannot give, the AFE's path structure is already built for splitting the work with an RTOS.
Building an audio product on Genio, from codec bring-up to a deterministic capture path? [Get MediaTek Genio engineering support](/get-expert-mediatek-genio-support).
*Sources: [PipeWire documentation](https://docs.pipewire.org/), [MediaTek IoT Yocto documentation](https://mediatek.gitlab.io/aiot/doc/aiot-dev-guide/), and the ALSA [ASoC DAPM documentation](https://www.kernel.org/doc/html/latest/sound/soc/dapm.html).*
---
## Raspberry Pi CM5 + Hailo-8 vs MediaTek Genio 700
URL: https://proventusnova.com/blog/raspberry-pi-cm5-hailo-8-vs-mediatek-genio-700/
Published: 2026-07-14
Author: Andres Campos
Tags: mediatek genio, raspberry pi cm5, hailo, platform comparison, edge ai, video encoding
CM5 plus Hailo-8 or MediaTek Genio 700? Compare video encode, AI stacks, camera paths, and BOM to pick the right compute for your camera or edge AI device.
Raspberry Pi CM5 plus a Hailo accelerator is the default answer right now for teams building a vision product on a budget, and the MediaTek Genio 700 is the option most of those teams have never priced. We build camera and edge AI devices on both sides of this fence, so this comparison is the one we actually walk clients through: CM5 + Hailo-8 versus Genio 700, judged as the compute for a real product rather than a demo.
## Key Insights
- The CM5 has no hardware video encoder. If your product streams or records video, that single line item dominates the comparison, and adding a Hailo module does nothing to change it.
- Hailo-8 crushes the Genio 700 on raw inference: 26 TOPS against a 4 TOPS class integrated APU. For inference-only products with no streaming requirement, CM5 + Hailo is a strong, well-supported combination.
- Genio 700 is the integration play: hardware H.264/H.265 encode and decode, an integrated ISP, an NPU, and WiFi 6 support in one SoC and one BSP, with no M.2 module or second AI toolchain.
- Ecosystem maturity still favors Raspberry Pi by a wide margin. Genio trades community volume for vendor-supported Yocto and Ubuntu BSPs and an industrial supply posture.
## What are you actually comparing?
**Raspberry Pi CM5** is a compute module built on the BCM2712: four Cortex-A76 cores at 2.4 GHz, VideoCore VII graphics, up to 16 GB of LPDDR4X, two four-lane MIPI CSI/DSI interfaces, and one lane of PCIe. It inherits the Pi 5's codec decision: hardware HEVC decode only. H.264 decode and all encoding moved to software.
**Hailo-8** is an inference accelerator that attaches over that PCIe lane (M.2 modules, or the HAT form factors the Pi ecosystem ships). It is rated at 26 TOPS INT8 at a couple of watts, with its own compiler toolchain that converts ONNX or TensorFlow models into Hailo's dataflow format. The popular Raspberry Pi AI Kit pairs the smaller Hailo-8L at 13 TOPS.
**MediaTek Genio 700** is a single SoC (MT8390) aimed at exactly this product class: two Cortex-A78 cores plus six Cortex-A55, Mali-G57 graphics, an integrated 4 TOPS class APU (the MDLA NPU we cover in [APU vs NPU vs VPU vs MDLA](/blog/mediatek-genio-apu-npu-vpu-mdla-explained)), an integrated ISP, MIPI CSI camera inputs, and hardware encode and decode for H.264 and H.265.
| | Raspberry Pi CM5 + Hailo-8 | MediaTek Genio 700 |
|---|---|---|
| CPU | 4× Cortex-A76 @ 2.4 GHz | 2× Cortex-A78 + 6× Cortex-A55 |
| AI | Hailo-8: 26 TOPS (discrete, PCIe) | Integrated APU, 4 TOPS class |
| Video encode | None (software x264/x265 on CPU) | Hardware H.264 + H.265 |
| Video decode | HEVC hardware; H.264 software | Hardware H.264 + H.265 |
| ISP | Pi ISP + libcamera | Integrated ISP (full RAW pipeline via MediaTek's camera stack) |
| Camera inputs | 2× 4-lane MIPI CSI (shared with DSI) | MIPI CSI via SENINF, multi-camera capable |
| OS | Raspberry Pi OS, community Linux | Yocto (RITY) and Ubuntu BSPs from MediaTek |
| AI toolchain | Hailo Dataflow Compiler | TFLite delegate / ONNX Runtime on the NPU |
| Parts and vendors | Module + accelerator, two toolchains | One SoC, one BSP |
| Supply commitment | CM5 in production to at least Jan 2036 | Genio 10-year industrial supply plan |
## Why does the missing video encoder matter so much?
Because almost every camera product ships video somewhere: an RTSP stream to a recorder, WebRTC to a browser, clips to storage. On the CM5 that pipeline runs through a software encoder. x264 at 1080p30 is achievable on the A76 cores, but it takes a large, permanent bite of your CPU budget, and it scales badly: a second camera, a higher resolution, or a tighter power envelope and the math stops working. The encoder load also lands on the same cores that run your application and feed the Hailo, so inference-plus-streaming products hit the wall first.
On the Genio 700 the same pipeline runs through dedicated encoder hardware behind standard V4L2 and GStreamer interfaces, the same stack we describe in our [Genio real-time video guide](/blog/mediatek-genio-gstreamer-real-time-video). We have shipped hardware-encoded multi-stream pipelines on Genio parts, and the CPU cost of encode is effectively noise. H.265 support matters double here: for bandwidth-limited links, hardware HEVC encode is the difference between one stream and none.
If your product does not encode video at all, a kiosk, a sensor gateway, a pure inference box feeding structured data upstream, this entire section is moot, and the comparison tilts back toward the Pi.
## How do the AI stacks compare?
On throughput, it is not close: Hailo-8's 26 TOPS runs bigger models, higher frame rates, and multi-model pipelines that the Genio's 4 TOPS class APU cannot match. If your roadmap includes heavy detection plus tracking plus classification running concurrently, the Hailo is the honest choice, and its toolchain is mature.
The Genio's case is architectural rather than raw speed. The NPU is behind standard frameworks (TFLite's Neuron delegate, ONNX Runtime's NeuronExecutionProvider, covered in [ONNX Runtime on the Genio NPU](/blog/mediatek-genio-onnx-runtime-neuron)), so there is no separate accelerator vendor, no proprietary model compilation step in your build, and no PCIe attachment to design, power, and cool. On the CM5 side, the Hailo also inherits the Pi's constraint: a single PCIe lane feeding it, and host-side pre and post processing competing with everything else on four cores.
The question we ask clients: what does your model actually need? Measured requirements in the 2 to 4 TOPS range with one or two models resident are comfortably inside the Genio 700. Requirements in the tens of TOPS point at Hailo, or at a bigger integrated platform entirely.
## What about the camera and ISP path?
The Pi camera stack is the most approachable in embedded: libcamera, a huge catalog of community-supported sensors, and enormous documentation volume. Its limits show up at the edges: exotic sensors, multi-camera synchronization, and fine ISP control get harder as requirements sharpen.
Genio's camera path is the industrial inverse. Sensor bring-up runs through MediaTek's SENINF and ISP stack with vendor support behind it, multi-camera topologies are a designed-for case, and the full RAW Bayer processing pipeline is available, with the caveat that the complete ISP tuning stack sits behind MediaTek's NDA program, which we explain in [NDA vs public build on Genio](/blog/mediatek-genio-nda-vs-public-build). For products where image quality in hard conditions is a requirement rather than a preference, that vendor ISP path, with proper tuning, is worth real money.
## Ecosystem, supply, and the second vendor problem
Raspberry Pi's ecosystem advantage is real and we will not pretend otherwise: more engineers know it, more problems are one search away, and prototyping speed is unmatched. Genio answers with vendor-maintained Yocto and [Ubuntu BSPs](/blog/mediatek-genio-ubuntu-getting-started), an industrial supply posture (see our [Genio longevity notes](/blog/mediatek-genio-soc-longevity-supply-plan)), and a support relationship where sensor, ISP, and BSP questions have someone accountable on the other end.
The CM5 + Hailo pairing also quietly makes you a systems integrator: two vendors, two roadmaps, two toolchains, and a PCIe interface between them that is yours to validate across temperature and production spread. One SoC does not have that failure mode. BOM math follows the same logic: module plus accelerator plus carrier complexity against one SoC with more of the product integrated into it.
## Which one should you pick?
Choose **CM5 + Hailo-8** when your product is inference-first and streams little or no video, when raw TOPS is the requirement that dominates, or when time-to-first-demo and ecosystem familiarity outweigh integration cost. It is a genuinely good platform inside those lines.
Choose **Genio 700** when the product is a camera device that encodes, when multi-camera or serious ISP requirements are on the roadmap, when power and BOM force integration, or when you want one accountable vendor under the whole board support package. The pattern we see repeatedly: teams prototype on the Pi stack, ship v1 into the encoder wall or the integration overhead, and land on an integrated SoC for v2. If that arc sounds familiar, price the migration before v1 hardens; it is cheaper as a plan than as a rescue.
Weighing this exact decision for a device? We do platform selection and bring-up on both stacks and will tell you honestly which side your requirements land on. [Talk to us about MediaTek Genio engineering](/get-expert-mediatek-genio-support).
*Sources: [Raspberry Pi CM5 documentation](https://www.raspberrypi.com/documentation/computers/compute-module.html), [Hailo-8 product page](https://hailo.ai/products/ai-accelerators/hailo-8-ai-accelerator/), and [MediaTek Genio 700 product page](https://www.mediatek.com/products/smart-home-and-iot/genio-700).*
---
## Zephyr audio on MediaTek Genio 700: AFE support lands
URL: https://proventusnova.com/blog/mediatek-genio-zephyr-audio/
Published: 2026-07-13
Author: Andres Campos
Tags: mediatek genio, zephyr, jailhouse, rtos, audio, afe, real-time
MediaTek's Zephyr fork now drives the Genio 700 audio front end: AFE driver, eTDM DAI, clocks, and capture samples. What shipped and how to build it.
MediaTek quietly shipped something we have been waiting on: working audio support for Zephyr on the Genio 700. The commits landed in MediaTek's public Zephyr fork at the end of June 2026, and they are not a toy. The branch adds a full driver stack for the MT8390 audio front end, the clock plumbing to run it without Linux's help, and capture samples that exercise real uplink paths on the Genio 700 EVK. If you have been designing audio products on Genio and wishing the deterministic half of the system could live on an RTOS, this is the piece that was missing.
## Key Insights
- MediaTek's Zephyr fork (branch `MTK-Genio_4.3.0`, Zephyr 4.3.0 base) now drives the Genio 700's AFE: core driver, eTDM DAI, AFE clock management, AUDSYS clock gates, and the topckgen and apmixedsys clock drivers underneath.
- The deployment model is Linux plus Zephyr side by side under the Jailhouse hypervisor. The Jailhouse recipe is public in the `meta-mediatek-experimental` Yocto layer for RITY Scarthgap v25.1.
- The AFE's many DMA paths make clean sharing possible: on our EVK, Linux claims DL0 to DL7 and UL0 to UL2, while the Zephyr samples capture on UL3, UL8, and UL9. The two operating systems do not fight over the same hardware.
- Everything is buildable today from public repositories, but none of it is upstream yet. Interfaces will move.
## What did MediaTek actually ship?
The interesting commits landed on 2026-06-29 in the `MTK-Genio_4.3.0` branch of [MediaTek's Zephyr fork](https://github.com/ffreimann-mtk/zephyr/commits/MTK-Genio_4.3.0/). Together they form a complete audio path for the MT8390, the SoC inside the Genio 700:
| Commit area | What it adds |
|---|---|
| AFE core driver | The audio front end: DMA engine and register-level control of the audio interconnect |
| eTDM DAI driver | The digital audio interface that moves PCM between the AFE and external codecs or TDM devices |
| AFE clock management | Runtime clock control for the audio subsystem |
| AUDSYS clock gates | The audio-block clock gates Zephyr must toggle itself |
| topckgen mux/gate driver | Top-level clock mux and gate control |
| apmixedsys PLL driver | The PLL source feeding the audio clock tree |
| `genio_700_evk` board enable | Device tree and pinctrl wiring for the AFE on the reference board |
| Capture samples | Working examples recording from the UL3, UL8, and UL9 uplink paths |
The clock drivers deserve a highlight. On Linux, audio drivers lean on the common clock framework and the whole tree is already up when a machine driver probes. A Zephyr cell gets none of that. Shipping topckgen, apmixedsys, and AUDSYS drivers means the Zephyr side can source and gate its own audio clocks, which is the difference between a demo that works because Linux happened to leave clocks on, and a driver stack that owns its hardware.
The branch history also shows where this is heading: earlier commits carry board support for the MT8365 and MT8370 Pumpkin boards, Genio 510 EVK groundwork, UART, timer, GPIO, EINT, and pinctrl refactors, and vPCI support. Audio is the newest and most product-relevant layer on an actively developed port.
## Why run audio under Zephyr instead of Linux?
Because worst case beats average case for audio. Linux with PipeWire is excellent at desktop-grade audio, and on Genio it works well (we cover that stack in our [PipeWire on Genio guide](/blog/mediatek-genio-pipewire-audio-setup)). But Linux schedules audio work alongside everything else the system does. When your product needs a capture-to-output path that never misses, page cache pressure, a busy GPU, or one badly behaved userspace process become audio problems. You can chase preempt-rt and priority tuning a long way (see [Real-Time Linux on Genio](/blog/mediatek-genio-real-time-linux)), and sometimes that is enough. When it is not, the clean answer is to take the audio path off Linux entirely.
That is the architecture this port enables: Linux keeps networking, UI, updates, and the application layer, while a Zephyr cell owns the audio interfaces with microsecond-scale, provable scheduling. Instruments, intercoms, conferencing endpoints, and industrial acoustic monitoring all fit that shape. Until now, building it on Genio meant porting an RTOS and writing AFE drivers yourself. MediaTek just paid that bill.
## How do Linux and Zephyr share one audio subsystem?
The MT8390's AFE is built around many independent DMA paths: downlink (DL) paths for playback and uplink (UL) paths for capture, all routed through one interconnect. That fan-out is what makes the split workable in practice.
On the Genio EVK in our lab, the stock Linux sound card registers as `mt8391-evk` and claims DL0 through DL7 for playback, UL0 through UL2 for capture, plus an HDMI playback device. You can see it directly on any Genio board:
```bash
cat /proc/asound/cards
cat /proc/asound/pcm
```
MediaTek's Zephyr samples capture on UL3, UL8, and UL9. Those are uplink paths the default Linux machine driver does not reference at all. That is the pattern to copy in a product design: give Linux the paths it needs for system audio, give the Zephyr cell its own UL and DL paths, and the two sides never contend for a DMA channel. The partitioning below reinforces the same boundary. Under Jailhouse, the Zephyr inmate cell gets an isolated memory carveout and its own CPU core (a single Cortex-A55 in the reference configs), with the hypervisor at EL2 keeping each side inside its assigned hardware.
## How do you build and run it?
Two halves: a Yocto image with Jailhouse for the Linux side, and a Zephyr application for the inmate cell.
For the image, MediaTek publishes the Jailhouse recipe in its experimental layer. On top of a normal [RITY Scarthgap v25.1 build](https://mediatek.gitlab.io/aiot/doc/aiot-dev-guide/master/sw/yocto/get-started/build-code.html) (kernel 6.6.92 at the time of writing):
```bash
cd $PROJ_ROOT/src
git clone https://gitlab.com/mediatek/aiot/rity/meta-mediatek-experimental -b scarthgap
# add the layer to bblayers.conf, then in local.conf:
# IMAGE_INSTALL:append = " jailhouse "
```
The resulting image carries the `jailhouse` tool and a library of cell configs, including `genio-510-evk-zephyr.cell` and `genio-720-evk-zephyr.cell`. The inmate load address is set by `JH_CONFIG_INMATE_BASE` in the Jailhouse recipe if you need to move it.
For the Zephyr half, initialize the workspace against MediaTek's fork instead of upstream:
```bash
west init -m https://github.com/ffreimann-mtk/zephyr --mr MTK-Genio_4.3.0 ~/zephyrproject
cd ~/zephyrproject && west update
west build -b genio_700_evk samples/
```
Then the Jailhouse lifecycle on the board is the standard one: enable the hypervisor with the root cell config, create the Zephyr cell, load `zephyr.bin` at the cell's base address, and start it. From our own Jailhouse bring-up work on a Genio 720 EVK, the one piece of advice that saves the most time is to treat the cell config as the real interface: know exactly which memory carveout, CPU, and peripherals the inmate owns before you chase any driver-level symptom. We walk through that config anatomy in our [Jailhouse on MediaTek Genio guide](/blog/jailhouse-hypervisor-mediatek-genio).
## What is still experimental?
Be clear-eyed about the maturity here. The audio work targets the Genio 700 first; the fork carries Genio 510 groundwork and the cell configs cover more boards, but MT8390 is where the samples run. Nothing is upstream: the Zephyr port lives on a fork and the Yocto recipe lives in a layer with "experimental" in its name, so pin your revisions and expect interface churn. Cross-cell communication is the standard Jailhouse story, shared memory via IVSHMEM, and anything richer is yours to design. And the samples are capture-oriented today, so a full product audio path still means writing your application-side processing and output plumbing in Zephyr.
None of that changes the headline. The hard, vendor-specific part of RTOS audio on Genio, the AFE and its clock tree, now has public, working code from the silicon vendor itself.
## Where to start
If you are evaluating this for a product: build the RITY image with the Jailhouse recipe, run the stock Zephyr capture sample on a Genio 700 EVK, and then map your own audio topology onto the AFE's path structure with Linux and Zephyr on disjoint UL and DL sets. The public code takes you through the first two steps; the third is product engineering.
Designing an audio product on Genio and weighing how to split real-time work between Linux and an RTOS? That partitioning decision is cheap to get right up front and expensive to retrofit. [Talk to us about MediaTek Genio engineering support](/get-expert-mediatek-genio-support).
*Sources: [MediaTek's Zephyr fork, branch MTK-Genio_4.3.0](https://github.com/ffreimann-mtk/zephyr/commits/MTK-Genio_4.3.0/), [meta-mediatek-experimental on GitLab](https://gitlab.com/mediatek/aiot/rity/meta-mediatek-experimental), [Zephyr getting started guide](https://docs.zephyrproject.org/latest/develop/getting_started/index.html), and [MediaTek's IoT Yocto documentation](https://mediatek.gitlab.io/aiot/doc/aiot-dev-guide/master/sw/yocto/get-started/build-code.html).*
---
## Real-Time Perception on the Edge: Detection, Segmentation, and Depth
URL: https://proventusnova.com/blog/real-time-edge-perception-demo/
Published: 2026-07-06
Author: Andres Campos
Tags: edge ai, computer vision, object detection, instance segmentation, depth estimation, open vocabulary, jetson
A modular edge perception pipeline: open-vocabulary detection, instance segmentation, and depth estimation running locally with live metrics. No cloud.
Most computer vision demos you see are running in a data center. This one is not. The video below is a modular perception pipeline running entirely on a local machine, served to a browser over the network, with no cloud round-trip. It runs three perception tasks at once, open-vocabulary object detection, instance segmentation, and monocular depth estimation, and reports live metrics for each. This is the kind of system we build for hardware teams deploying vision on NVIDIA Jetson and MediaTek Genio.
## Key Insights
- The pipeline runs **open-vocabulary detection**: the target classes are typed in as text (`a person`, `a laptop`, `a chair`, `a desk`) and applied live, with no retraining. Change the prompt, and the detector localizes the new objects.
- **Three perception tasks run as toggleable stages**: detection, instance segmentation, and depth estimation. Each can be turned on or off so you can see, and measure, the compute cost of each stage independently.
- Everything runs **locally**. The dashboard is served over the LAN, frames never leave the device, and there is no cloud dependency, no round-trip latency, and no data leaving the premises.
- The interface accepts **multiple input sources**: live webcam, video file, still image, and RTSP network stream, so the same pipeline can be driven by a real camera or a recorded clip.
- A **live metrics panel** reports FPS, detection count, and per-stage latency, which is exactly the instrumentation you need to tune a pipeline for a real-time target on constrained hardware.
## What the Demo Shows
The interface is organized as a control panel and a set of live views.
**Open-vocabulary detection.** Instead of a fixed class list baked into the model, the active classes are a text prompt you edit at runtime. In the demo, the prompt is a short list, `a person`, `a laptop`, `a chair`, `a desk`, and the detector draws labeled boxes for exactly those objects. Swap the prompt for warehouse objects, PPE, or defects on a line, and the same deployed model reports the new set. This is the difference between "the model knows 80 things forever" and "the model detects what you ask it to."
**Instance segmentation.** Beyond a bounding box, the segmentation stage returns a per-object mask, so a person, a plant, a laptop, and a chair each get a distinct colored silhouette. Masks are what you need when a box is too coarse, for grasping, measurement, occlusion reasoning, or clean overlays.
**Depth estimation.** The depth view is a single-camera (monocular) depth map, rendered as a near-to-far colormap. No stereo rig, no depth sensor, just an inference model estimating relative distance from a single RGB frame. For robots and drones, a monocular depth stage is a cheap way to add spatial awareness without new hardware.
**Live metrics.** FPS, detection count, and detection latency in milliseconds are shown as the pipeline runs. This is the part that matters for edge deployment: perception on the edge is a budget problem, and you cannot tune what you do not measure.
## Why Run Perception on the Edge at All
Running these three tasks on-device, rather than shipping frames to a server, is a deliberate architectural choice with concrete benefits:
- **Latency.** There is no network round-trip. For a robot arm, an autonomous mobile robot, or an inspection station, the control loop cannot wait on a server in another building.
- **Privacy and data residency.** Camera frames never leave the device. For healthcare, retail, and industrial sites, that removes a whole category of compliance and security concern.
- **Reliability.** The system keeps working when connectivity drops. An edge perception node does not go blind because the uplink went down.
- **Cost.** No per-frame inference bill, no bandwidth to stream raw video off-site.
The tradeoff is that you are now solving a hard engineering problem: three models, competing for the same GPU, DLA, memory bandwidth, and thermal budget, all while holding a real-time frame rate.
## How This Maps to Production Hardware
The demo runs the pipeline in a browser for clarity, but the same architecture is what ships on an embedded module. In production, the pieces map like this:
- **Camera ingest** comes from CSI or GMSL2 cameras, or an RTSP feed, decoded through a hardware-accelerated GStreamer pipeline rather than a webcam grab.
- **Detection and segmentation** run as optimized TensorRT engines on the GPU, with layers mapped to the DLA where they are supported to free the GPU.
- **Depth** runs as a separate engine, scheduled so it does not starve the detector.
- **Zero-copy memory** keeps frames in GPU-accessible buffers so they are not copied between stages, which is often the difference between hitting and missing a frame-rate target.
- **INT8 quantization** is applied where accuracy allows, to cut latency and power.
That is the work: taking a pipeline that runs, and making it run in real time, within a power and thermal envelope, on the specific silicon a product ships on. It is exactly the class of problem ProventusNova solves on NVIDIA Jetson and MediaTek Genio, from camera bring-up through to a deployed, profiled inference pipeline.
## Building Something Like This
If you are putting cameras and models on an embedded device and need real-time perception that runs locally, the hard parts are rarely the models themselves. They are the camera bring-up, the GStreamer pipeline, the memory path, the accelerator mapping, and the profiling that gets you from "it runs" to "it runs at frame rate, every time." That is the work we do on a fixed-bid basis.
---
## Customizing the boot logo on MediaTek Genio
URL: https://proventusnova.com/blog/mediatek-genio-boot-logo-splash/
Published: 2026-06-23
Author: Aaron Angulo
Tags: mediatek genio, boot logo, splash screen, yocto, bootassets, u-boot
Replace the boot logo on MediaTek Genio: where it lives (the bootassets partition), the bootassets-part bbappend recipe, and how to build and flash it.
On MediaTek Genio, the boot logo is not compiled into U-Boot, it is static data stored in the **bootassets** partition. That means you customize it by overriding one Yocto recipe, rebuilding a single partition, and flashing just that partition with `genio-flash`. This post covers where the logo sits in the Genio boot flow, the exact recipe override, the build-and-flash steps, and an honest note on the format details MediaTek's docs leave to your BSP.
## Where the boot logo lives in the Genio boot flow
Genio boots through the standard Arm secure-boot chain: BROM → BL2 (TF-A) → BL31 → BL32 (OP-TEE) → **BL33 (U-Boot)** → Linux. U-Boot is the stage that can put an image on the display before the kernel takes over, so the boot logo is a U-Boot-era splash.
The logo image itself is not baked into the U-Boot binary. It is one of the static assets in the dedicated **bootassets** partition, which also holds DTBs and device-tree overlays. That separation is the useful part: you can change the logo without touching the bootloader build at all. For the full stage-by-stage boot path and partition map, see [the MediaTek Genio boot flow](/blog/mediatek-genio-boot-flow).
## How to replace the boot logo
MediaTek's IoT Yocto stores "static data such as boot logos, audio, or video files" in the bootassets partition, and you customize that partition with a `.bbappend` on the `bootassets-part` recipe. In your own layer:
1. Create a bbappend alongside the recipe, for example `recipes-bsp/bootassets/bootassets-part.bbappend` (match the recipe path your BSP uses).
2. Point the recipe at your logo file:
```bitbake
FILESEXTRAPATHS:prepend := "${THISDIR}/files:"
SRC_URI += "file://my-boot-logo.bmp"
```
3. Place the file under a `files/` directory next to the bbappend, and make sure the recipe's `collect_artifacts` step copies it into the partition staging, that hook is how IoT Yocto assembles the bootassets image.
The recipe is the single source of truth for what goes into the partition, so if your logo does not appear after flashing, the first thing to check is that `collect_artifacts` actually picked up your file.
## Build and flash just the boot assets
Because the logo lives in its own partition, you do not rebuild the whole image. Build only the bootassets partition, then flash only that partition:
```bash
MACHINE=genio-720-evk bitbake bootassets-part
genio-flash bootassets
```
Use your board's machine name (the Genio 420/520/720 share the `genio-720-evk` machine config). `genio-flash bootassets` writes only that partition, which keeps the logo change to a fast build-and-reflash loop instead of a full eMMC re-flash.
To put the board into download mode for flashing: hold the **DOWNLOAD** button, tap **RESET**, then release DOWNLOAD. The board enumerates over USB as `0e8d:0003` when it is ready to receive a flash.
## Image format, resolution, and which display it lands on
This is where you have to read your own BSP, because MediaTek's "modifying board assets" guide documents the *mechanism* but not the *format*. Two things to pin down before you finalize artwork:
- **Format and resolution.** The accepted image format, commonly BMP for U-Boot splash logos, and the resolution the bootloader expects are set by your `bootassets` recipe and U-Boot's splash configuration, not by a single published spec. Open the `bootassets-part` recipe and the U-Boot `splashimage`/logo config for your board to confirm the exact filename, format, and dimensions. Convert your artwork to match rather than assuming.
- **Which display shows the logo.** Genio selects display output through device-tree overlays loaded by the `boot_conf` U-Boot variable: `display-hdmi.dtbo` for HDMI, `display-dsi.dtbo` for MIPI DSI, `display-dp.dtbo` for DisplayPort, and so on. The boot logo follows whichever display the active overlay brings up. If the logo renders on DSI but not HDMI, the usual cause is that the HDMI overlay is missing from your `boot_conf` string, see [HDMI troubleshooting on MediaTek Genio](/blog/mediatek-genio-hdmi-troubleshooting).
## The short version
The boot logo on Genio is a bootassets asset, not a U-Boot rebuild: override the `bootassets-part` recipe with your image, run `bitbake bootassets-part`, and flash with `genio-flash bootassets`. The mechanism is documented and fast to iterate; the exact image format and resolution live in your board's bootassets recipe and U-Boot config, so confirm those before you ship the artwork.
Bringing up a custom Genio board and want the boot experience, logo, display bring-up, and BSP, handled on a fixed timeline? [See our MediaTek Genio support services](/get-expert-mediatek-genio-support).
*Source: [MediaTek IoT Yocto, Modifying Board Assets](https://mediatek.gitlab.io/aiot/doc/aiot-dev-guide/master/sw/yocto/modify-board-assets.html).*
---
## ONNX Runtime on the MediaTek Genio NPU (520 and 720)
URL: https://proventusnova.com/blog/mediatek-genio-onnx-runtime-neuron/
Published: 2026-06-22
Author: Aaron Angulo
Tags: mediatek genio, onnx runtime, npu, neuropilot, mdla, edge ai
Run ONNX Runtime on the Genio NPU. Only the Genio 520 and 720 support the NeuronExecutionProvider out of the box, plus the mandatory FP16 flag and benchmarks.
If you are deploying an ONNX Runtime model to a MediaTek Genio and you need it accelerated on the NPU rather than the CPU, the platform choice is narrower than the spec sheets suggest: only the **Genio 520 and Genio 720** support the ONNX Runtime NeuronExecutionProvider out of the box. This post covers which chips can do it, how to enable it, the one flag that trips up every first deployment, and the offline compilation path for production.
## Which Genio chips support ONNX Runtime on the NPU?
MediaTek's AI stack on Genio Yocto runs two open runtimes, TFLite (LiteRT) and ONNX Runtime, both accelerated on the **APUSys MDLA (Multi-Dimension Learning Accelerator)** through the NeuronSDK. The catch is that NPU coverage is not uniform across the family. Here is the actual support matrix:
| Platform | TFLite CPU/GPU | TFLite Neuron Delegate (NPU) | ONNX CPU | ONNX NeuronEP (NPU) |
|----------|----------------|------------------------------|----------|----------------------|
| Genio 350 | Yes | No | Yes | No |
| Genio 510 / 700 | Yes | Yes | Yes | Opt-in¹ |
| Genio 1200 | Yes | Yes | Yes | Opt-in² |
| **Genio 520 / 720** | Yes | Yes | Yes | **Yes (default)** |
¹ Genio 510/700: requires `ENABLE_NEURON_EP = "1"` in `local.conf`, then rebuild the image.
² Genio 1200: same opt-in, but not all ONNX operators are supported on the NPU, which can limit performance.
The bottom line: if ONNX Runtime NPU acceleration is a hard requirement, the Genio 520 and 720 are the only platforms that give it to you by default. Everything else is either an opt-in rebuild or, on the Genio 350, not available at all. This is the kind of constraint that does not appear when you compare TOPS numbers, but it determines whether your existing pipeline ports without a re-architecture. For the broader platform tradeoffs, see [MediaTek Genio vs NVIDIA Jetson Orin](/blog/mediatek-genio-vs-nvidia-jetson).
## How do you set up the NeuronExecutionProvider?
On the Genio 520 and 720 the provider is already in the image. You select it in the provider list when you create the inference session, highest priority first, with CPU fallbacks behind it:
```python
import onnxruntime as ort
neuron_opts = {
"NEURON_FLAG_USE_FP16": "1", # MANDATORY, the NPU does not support FP32
"NEURON_FLAG_MIN_GROUP_SIZE": "1", # minimum nodes per NPU subgraph
}
providers = [
("NeuronExecutionProvider", neuron_opts),
"XnnpackExecutionProvider",
"CPUExecutionProvider",
]
session = ort.InferenceSession("model.onnx", providers=providers)
```
The C++ API mirrors this through `SessionOptionsAppendExecutionProvider` with the `"NeuronExecutionProvider"` name and the same key/value option pairs.
### The one flag that breaks the first deployment
`NEURON_FLAG_USE_FP16 = "1"` is mandatory. The MDLA NPU does not execute FP32, so without the flag an FP32 model will not run on the NPU. Set it, and FP32 layers execute as FP16. The two model formats the NPU accepts are FP32-executed-as-FP16 (with the flag) and QDQ INT8. This single line is the most common reason a model "works" but quietly runs on the CPU on a first bring-up.
### Enabling the NPU path on Genio 510, 700, and 1200
These platforms have the hardware but ship with the provider off. Turn it on at build time:
```bitbake
# local.conf
ENABLE_NEURON_EP = "1"
```
Then rebuild the image (`rity-demo-image`). On the Genio 1200, expect some operators to fall back, since not all ONNX ops are mapped to its NPU path.
## Online or offline: which inference path should you use?
There are two ways to get a model onto the NPU, and the right one depends on whether the model is fixed:
1. **Online (runtime delegation).** ONNX Runtime via the NeuronExecutionProvider, or TFLite via the Neuron Stable Delegate, compiles NPU subgraphs as the application loads the model. Simplest to integrate; pays a compile cost at load time.
2. **Offline (ahead-of-time compilation).** Compile the model on a host PC into a hardware-specific `.dla` binary, then load it on the device. Removes the runtime compile step and is the production path for a model that does not change.
For the offline path, the host-side compiler is `ncc-tflite`:
```bash
# SDK from neuropilot.mediatek.com (All-In-One Bundle)
export LD_LIBRARY_PATH=/path/to/neuropilot-sdk-basic-/neuron_sdk/host/lib
# INT8 quantized model
./ncc-tflite --arch=mdla3.0 model_int8.tflite -o model_int8.dla
# FP32 model, executed as FP16 on the NPU
./ncc-tflite --arch=mdla3.0 --relax-fp32 model.tflite -o model_fp32.dla
```
All of the NPU-capable Genio parts (510, 700, 520, 720, 1200) target `--arch=mdla3.0`. The `--relax-fp32` flag is the offline equivalent of the runtime FP16 flag.
## How fast is the Genio NPU in practice?
On the device, `neuronrt` runs a compiled `.dla` and reports timing. A YOLOv5s INT8 detector gives a useful reference point:
```bash
# YOLOv5s input: 640x640x3 = 1,228,800 bytes
neuronrt -m hw -a model_int8.dla -i input.bin -c 10
# Total inference time = 52.648 ms (5.2648 ms/inf), Avg. FPS: 186.1
```
About **5.26 ms per inference, roughly 186 FPS** for the model compute alone. Treat that as a ceiling: once you add camera capture, pre-processing, and non-maximum suppression in a real pipeline, end-to-end throughput drops. But it shows the MDLA has real headroom for a single detector at video frame rates. Note that `neuronrt` is for verification and benchmarking; production applications should drive inference through the Neuron Runtime API for control over tensors and scheduling.
## Putting inference in a GStreamer pipeline
For camera-to-inference products, NNStreamer integrates the NPU into a GStreamer pipeline through the `tensor_filter` element, so capture, inference, and downstream video all run in one pipeline:
```bash
gst-launch-1.0 v4l2src ! videoconvert ! \
video/x-raw,format=RGB,width=640,height=640 ! \
tensor_convert ! \
tensor_filter framework=tflite model=yolov5s_int8.tflite \
custom=Delegate:NNAPI,NNAPIOptions:NEURON_FLAG_USE_FP16=1 ! \
tensor_sink
```
The same `NEURON_FLAG_USE_FP16` requirement carries through to the delegate options here.
## The short version
If your edge AI product is built on ONNX Runtime and needs NPU acceleration on MediaTek Genio, design around the **Genio 520 or 720**, set `NEURON_FLAG_USE_FP16`, and decide early between the online and offline paths based on whether your model is fixed. Picking a higher-tier Genio for the headline compute without checking the runtime matrix is how teams end up running ONNX on the CPU and wondering where the NPU went.
We bring up the MediaTek Genio AI stack, NeuroPilot, and camera-to-inference pipelines on a fixed-bid, fixed-timeline basis. If you are evaluating Genio for an AI product, [see our MediaTek Genio support services](/get-expert-mediatek-genio-support).
---
## Getting started with Ubuntu on MediaTek Genio
URL: https://proventusnova.com/blog/mediatek-genio-ubuntu-getting-started/
Published: 2026-06-22
Author: Aaron Angulo
Tags: mediatek genio, ubuntu, bsp, npu, neuropilot, gstreamer, edge ai
Run Ubuntu on MediaTek Genio: supported boards, first boot, the genio-public BSP PPA, hardware video and NPU packages, and how it differs from Yocto.
Ubuntu runs on MediaTek Genio through an official Canonical and MediaTek collaboration, but the documentation is spread across half a dozen pages and the board support is uneven. This guide pulls the path into one place: which boards are supported, how to get to a first boot, how to add the hardware BSP for video and NPU acceleration, and where Ubuntu differs from the IoT Yocto image. Every step links back to the official MediaTek and Canonical docs.
## Which Genio boards run Ubuntu?
Ubuntu on Genio is a joint effort: Canonical maintains the kernel, the images, and the Ubuntu archive; MediaTek maintains the boot firmware and the hardware support packages. Deploying a board needs two pieces, a Canonical disk image and MediaTek's board-specific boot firmware.
| Board | Ubuntu status | NPU on Ubuntu |
|---|---|---|
| Genio 1200 EVK | Certified (22.04), image (24.04) | Full |
| Genio 700 EVK | Certified (22.04), image (24.04) | Full |
| Genio 510 EVK | Certified (22.04), image (24.04) | Partial (firmware + runtime) |
| Genio 350 EVK | Certified (22.04), image (24.04, server) | None (no NPU hardware) |
| Genio 720 EVK | Early Access (24.04) | Not yet in the BSP package set |
| Genio 520 EVK | Early Access (24.04) | Not yet in the BSP package set |
The practical takeaway: for a production Ubuntu design today, target the **1200, 700, 510, or 350**. The 720 and 520 are Early Access, the disk images exist, but the documented hardware BSP packages (video, NPU) cover the 350/510/700/1200 family. If you specifically need the Genio 720, the IoT Yocto image is the more complete path right now. For the broader platform trade-off, see our [Genio vs Jetson comparison](/blog/mediatek-genio-vs-nvidia-jetson).
## How Ubuntu on Genio differs from the IoT Yocto image
If you have worked with the Yocto IoT image, two differences matter on day one:
- **Boot flow.** Ubuntu uses the EBBR (Embedded Base Boot Requirements) U-Boot flow with the standard BL2 → BL31 → BL32 → BL33 stages. The IoT Yocto image uses FIT boot. The bootloader implementation is shared, but the path differs and is switchable through U-Boot environment variables.
- **Software model.** On Ubuntu you start from a Canonical-maintained kernel and archive and add hardware support from an apt PPA. On Yocto you build the whole image from the `meta-mediatek` BSP layers. Ubuntu is faster to stand up and easier to maintain with `apt`; Yocto gives you deeper control and, as we will see, a fuller accelerator stack.
For the full decision between the two, see [Ubuntu vs Yocto on MediaTek Genio](/blog/mediatek-genio-ubuntu-vs-yocto).
## First boot and login
Flash the Canonical image and MediaTek boot firmware to the board's eMMC (a single eMMC device is shared between the bootloader and OS partitions), then power on. On the first boot, Cloud-init creates the account and initializes the system:
```bash
# Wait for Cloud-init to finish before doing anything else
cloud-init status --wait
```
Default credentials are `ubuntu` / `ubuntu`. Console access is over the UART (`ttyS0`). If the serial console looks misaligned, fix the terminal geometry:
```bash
sudo apt install xterm
resize
```
Then refresh apt before installing anything:
```bash
sudo apt update
```
One display caveat to plan around: **native X11 and GLX are not available**: X11 applications run through XWayland on the Wayland session. If you are porting an X11 app, expect to go through XWayland rather than a native X server.
## Installing the MediaTek hardware BSP
Out of the box, the Ubuntu image boots and runs, but the hardware video codec and NPU are not active until you add MediaTek's BSP from its public PPA:
```bash
sudo apt-add-repository ppa:mediatek-genio/genio-public
sudo apt update
```
Press **Enter** when prompted to confirm the repository. The PPA carries two families of packages, video hardware support and NeuroPilot NPU support, maintained by MediaTek under proprietary licenses. Internet access is required during install. For testing unreleased fixes, MediaTek also publishes a `ppa:mediatek-genio/genio-proposed` channel; keep that off production images.
## Hardware video codec on Ubuntu
The video stack is a user-space daemon plus patched GStreamer plugins. Install the daemon for your board, then the patched plugins:
```bash
# User-space VPU daemon (pick your board)
sudo apt install mediatek-vpud-genio1200 # or -genio700 / -genio510 / -genio350
# Patched GStreamer plugins, install the versions carrying "+genio23"
sudo apt install gstreamer1.0-plugins-base gstreamer1.0-plugins-good gstreamer1.0-plugins-bad
```
Unlike the Yocto image's element naming, the Ubuntu BSP exposes the codec through standard **V4L2 GStreamer elements**:
- Decoders: `v4l2h264dec`, `v4l2h265dec`, `v4l2mpeg4dec`, `v4l2vp8dec`, `v4l2vp9dec`
- Encoders: `v4l2h264enc`, `v4l2h265enc`
- Conversion: `v4l2convert` (the hardware decoder emits the `NV12_16L32S` format, so a convert stage is usually needed)
A hardware H.264 encode from the test source:
```bash
gst-launch-1.0 -v videotestsrc num-buffers=300 ! \
"video/x-raw,format=NV12,width=720,height=480,framerate=30/1" ! \
v4l2h264enc extra-controls="cid,video_gop_size=30,video_bitrate=512000" ! \
"video/x-h264,level=(string)4.1,profile=main" ! h264parse ! mp4mux ! \
filesink location=/home/ubuntu/test-h264.mp4
```
Hardware decode to a Wayland desktop:
```bash
gst-launch-1.0 -v filesrc location=/home/ubuntu/test-h264.mp4 ! parsebin ! \
v4l2h264dec ! v4l2convert output-io-mode=5 ! \
video/x-raw,width=720,height=480 ! waylandsink
```
On a server (headless) image, swap `waylandsink` for `kmssink connector-id= driver-name="mediatek"`. For the deeper GStreamer treatment, the VPUD daemon, the 4K encoded-buffer-size gotcha, and pipeline patterns, see [real-time video on MediaTek Genio](/blog/mediatek-genio-gstreamer-real-time-video).
## NPU and NeuroPilot on Ubuntu
This is where Ubuntu and Yocto diverge most. The Ubuntu BSP gives you the firmware and the Neuron runtime, but a narrower toolchain than the Yocto/RITY image.
Install the APUSys firmware for your board, then the runtime:
```bash
# Firmware (pick your board)
sudo apt install mediatek-apusys-firmware-genio700 # or -genio510 / -genio1200
# Runtime + dev libraries (all NPU-capable boards)
sudo apt install mediatek-libneuron mediatek-neuron-utils mediatek-libneuron-dev
```
What you get: the **TFLite Neuron Delegate**, the **Neuron Runtime**, development headers, and benchmark models under `/usr/share/benchmark_dla/`. Verify the accelerator is alive:
```bash
sudo vpu5_test -a ks -l 10 # should report PASS
sudo python3 /usr/share/benchmark_dla/benchmark.py --auto
```
Two things to plan around:
1. **Board coverage is uneven.** NPU support is full on Genio 700 and 1200, partial on Genio 510 (firmware and runtime only), and absent on Genio 350. Match the firmware package to the board exactly, MediaTek's docs warn that the wrong firmware can break the video codec drivers.
2. **The toolchain is narrower than Yocto.** MediaTek's Ubuntu NPU docs cover the TFLite delegate path, but do **not** document the ONNX Runtime NeuronExecutionProvider or the offline `ncc-tflite` compiler. If your inference stack is built on ONNX-on-NPU, the Yocto image is the documented path, see [ONNX Runtime on the Genio NPU](/blog/mediatek-genio-onnx-runtime-neuron) and [on-device AI on Genio](/blog/mediatek-genio-on-device-ai-no-cloud).
## Customizing the image
For anything beyond the stock image, MediaTek documents customization of the kernel, device tree and overlays, bootloader, and partition layout, plus single-partition flashing so you can update one partition without re-flashing the whole eMMC. These are the entry points for bringing up a custom carrier board or module on Ubuntu rather than the reference EVK.
## Where does the kernel source live, and how do you rebuild it?
Ubuntu on Genio runs a Canonical-maintained kernel, not the RITY kernel, and that distinction decides your customization workflow. Three tiers, in increasing order of commitment:
1. **Device tree overlays only.** Enabling a display, a camera, or carrier-board peripherals is usually an overlay selection or addition, not a kernel rebuild. MediaTek's Ubuntu docs cover building and applying DTBOs against the shipped kernel; this covers most "custom carrier board" work.
2. **Rebuild the kernel from source.** MediaTek's Ubuntu documentation walks through fetching the Genio kernel source, cross-compiling, and installing the resulting kernel and modules onto the board. Because the boot flow is EBBR U-Boot with a standard boot partition, swapping in your Image and dtbs is a normal Linux workflow rather than a BSP ceremony, and single-partition flashing means you can iterate on the kernel without touching the rest of the eMMC.
3. **Own the whole image.** The moment your changes stop being "a kernel config and a few drivers" and become "a different system," you have outgrown the Ubuntu path. That is what [Yocto is for](/blog/mediatek-genio-ubuntu-vs-yocto), where kernel patches live as tracked `devtool` artifacts in your own meta-layer.
One planning note: kernel changes on Ubuntu put you off Canonical's tested kernel, which weakens the certification story that makes Ubuntu attractive in the first place. If your product needs deep kernel work, weigh that against starting on Yocto before the divergence accumulates.
## Where to start
If you are evaluating Ubuntu on Genio: pick a **certified board (1200, 700, 510, or 350)**, flash the 22.04 or 24.04 image, add the `genio-public` PPA, and install the video and NPU packages for your part. Treat the 720 and 520 as Early Access. If you need the 720 specifically, or the ONNX/`ncc-tflite` NPU toolchain, the IoT Yocto image is the more complete route today.
Bringing up Genio on Ubuntu or Yocto for a product, and want it done on a fixed timeline? [See our MediaTek Genio support services](/get-expert-mediatek-genio-support).
*Sources: [Ubuntu on Genio (Canonical)](https://ubuntu.com/download/mediatek-genio) and [MediaTek's Ubuntu on Genio documentation](https://mediatek.gitlab.io/genio/doc/ubuntu/).*
---
## MediaTek Genio 420: specs, Yocto BSP, and how it compares to Genio 520 and 720
URL: https://proventusnova.com/blog/mediatek-genio-420-vs-genio-520-720/
Published: 2026-06-15
Author: Aaron Angulo
Tags: mediatek genio, genio 420, genio 520, genio 720, edge ai, yocto, module selection
MediaTek Genio 420 (MT8371LV) is the low-voltage Genio 520 variant. Same EVK, Yocto BSP, ONNX NPU EP. Specs, limitations, and when to choose 420 vs 520 vs 720.
MediaTek Genio 420 is the low-voltage variant of Genio 520, sharing the same silicon, EVK board, and Yocto BSP. If you are evaluating the Genio 420 and wondering how it fits against the 520 and 720, the answer starts with the SoC family structure: all three platforms are development targets for the same codebase, the same machine config, and the same EVK.
## Key Insights
- **Genio 420 (MT8371LV) is pin-compatible with Genio 520 (MT8371) and 720 (MT8391)**: same VFBGA footprint, same EVK board (P2V3), same Yocto `genio-720-*` machine configs
- **No HDMI on any of these three platforms**: display output is DisplayPort over Type-C (DPoC) only; this is the most common hardware surprise for teams coming from desktop or Genio 510/700/1200 designs
- **ONNX Runtime NPU Execution Provider is only supported on Genio 420/520/720**: not on Genio 510, 700, or 1200; if your inference stack uses ONNX Runtime with NPU acceleration, this family is the correct choice
- **LP4X memory support** (up to 8GB) makes 420 and 520 lower BOM cost than 720 (which requires LP5X)
- **Genio 420 BSP support added March 2026** in IoT Yocto v25.1.1, the 420 is a new addition to an otherwise stable BSP
## What is the Genio 420?
The MediaTek Genio 420 (SoC part number: MT8371LV) is the low-voltage, industrial-grade member of the MT8391/MT8371 SoC family. The LV suffix means lower operating voltage, the same die as MT8371 (Genio 520), manufactured to meet tighter voltage specifications, which reduces power consumption and thermal output at the cost of slightly lower peak clock headroom.
In practice, the Genio 420 and Genio 520 are software-identical. They share the same datasheet ("MT8391 MT8371 MT8371LV Application Processor Datasheet"), the same EVK user guide, the same Yocto machine configurations, and the same driver support. MediaTek added all three platforms to the same BSP release.
## Genio 420 full specifications
| Property | Genio 420 (MT8371LV) |
|---|---|
| SoC | MT8371LV |
| Process node | 6nm |
| CPU | 2× Cortex-A78 @ 2.2 GHz + 6× Cortex-A55 |
| GPU | Mali-G57 MC2 @ 880 MHz |
| NPU | APUSys / MDLA (same as Genio 520 and 720) |
| Max RAM | 8 GB LPDDR4X or LPDDR5 |
| Storage interfaces | eMMC, UFS, SD |
| MIPI CSI-2 | 3× 4-lane |
| MIPI DSI | 2 |
| Display output | DisplayPort over Type-C (DPoC) only, no HDMI |
| PCIe | 1× Gen2 |
| GbE | 1× TSN-capable |
| USB | USB 3.x |
| GPIO | 177 |
| I2C | 8 + 2 I3C |
| SPI | 6 master |
| UART | 4 |
| WiFi / BT | External via MT7921 (M.2/PCIe) |
| Package | Same VFBGA as MT8371/MT8391 |
| Longevity | Until 2032 |
## Genio 420 vs Genio 520 vs Genio 720
The three platforms differ in clock speed and memory, not in silicon architecture or peripheral set.
| | Genio 420 (MT8371LV) | Genio 520 (MT8371) | Genio 720 (MT8391) |
|---|---|---|---|
| CPU A78 clock | 2.2 GHz | 2.2 GHz | **2.6 GHz** |
| GPU clock | 880 MHz | 880 MHz | **1.1 GHz** |
| NPU | APUSys/MDLA | APUSys/MDLA | APUSys/MDLA |
| Max RAM | 8 GB LP4X | 8 GB LP4X or 16 GB LP5 | 16 GB LP5X |
| Memory type | LP4X | LP4X or LP5 | LP5X |
| Display | DPoC only | DPoC only | DPoC only |
| Yocto machine | `genio-720-evk` | `genio-720-evk` | `genio-720-evk` |
| EVK board | P2V3 | P2V3 | P2V3 |
| ONNX Runtime NPU EP | Yes | Yes | Yes |
| BSP support since | v25.1.1 (Mar 2026) | v25.1 (Dec 2025) | v25.1 (Dec 2025) |
| Longevity | Until 2032 | Until 2032 | Until **2036** |
The software difference between the three is zero, same machine config, same BSP, same driver stack. A driver written and tested on Genio 720 EVK runs on Genio 420 without changes.
The hardware difference is clock speed, memory ceiling, and supply voltage. For applications that do not saturate the Genio 720's CPU or GPU, the 420 and 520 run the same software at lower power and lower BOM cost.
## Where Genio 420 fits vs the broader Genio family
The broader Genio family splits into two groups with different BSP lineages and different display capabilities:
| | Genio 350/360/510/700/1200 | Genio 420/520/720 |
|---|---|---|
| HDMI output | Yes | **No, DPoC only** |
| ONNX Runtime NPU EP | No (except 520/720) | **Yes** |
| TFLite Neuron Stable Delegate | Yes (most models) | Yes |
| Yocto machine | Platform-specific | `genio-720-*` shared |
| Pin-compatible group | No cross-compatibility | All three compatible |
The most important distinction for software teams: if your inference deployment stack uses ONNX Runtime and you need NPU acceleration, only Genio 420, 520, and 720 support the ONNX Runtime NPU Execution Provider (MDLA backend). The other Genio platforms support MDLA only through TFLite's Neuron Stable Delegate. This is a framework-level choice that affects your entire inference stack.
## When to choose Genio 420 over 520 or 720
**Choose Genio 420 when:**
- Your design is thermally constrained, the lower operating voltage reduces heat output, which matters in sealed industrial enclosures without active cooling
- You are targeting battery-powered operation, lower voltage directly reduces active power draw
- BOM cost matters and your workload does not saturate Genio 520 clock speeds
- You need ONNX Runtime NPU EP support but do not need Genio 720's higher CPU/GPU clocks
**Choose Genio 520 instead when:**
- You want the same power profile as Genio 420 but with broader BSP history (520 support predates 420 by one release)
- LP5 memory support matters for your bandwidth requirements
**Choose Genio 720 instead when:**
- You need 2.6 GHz A78 cores, meaningful for CPU-bound workloads like computer vision pre/post-processing
- You need 1.1 GHz GPU clocks, relevant for GPU-accelerated inference or rendering
- You need LP5X memory at 16 GB
- Longevity is critical, Genio 720 is guaranteed until 2036 vs 2032 for 420/520
## Yocto BSP status and known limitations
Genio 420 support was added to the MediaTek IoT Yocto SDK in v25.1.1 (March 2026). This is a recent addition and carries some known gaps as of this BSP release:
- **ISP hardware pipeline not supported**: The MIPI-CSI interface transfers raw sensor data, but the ISP hardware processing pipeline is not yet active in v25.1.x. Camera bring-up is possible for raw capture, but ISP-processed output (auto-exposure, auto-white-balance, hardware noise reduction) is not available yet.
- **Boot splash / bootloader display driver not supported** in v25.1.x on this platform family.
- **Generative AI on Yocto**: Available on Genio 720 as of early 2026. Genio 420 and 520 are expected to gain GAI support in 2026 Q2 (same model support, slightly lower throughput due to lower clock rates).
The ONNX Runtime NPU Execution Provider and TFLite Neuron Stable Delegate (MDLA backend) are both supported and stable on all three platforms.
## No HDMI: the one thing to verify before committing
Genio 420, 520, and 720 have no HDMI output. This is documented in the MediaTek design notice for this SoC family and is not a BSP limitation, the hardware simply does not include an HDMI transmitter.
Display output is via **DisplayPort over Type-C (DPoC)** only. In your Yocto build, enable it with:
```bash
KERNEL_DEVICETREE_OVERLAYS += "mediatek/mt8391-evk-display-dpoc.dtbo"
```
For headless applications (no display required), this is irrelevant. For applications requiring HDMI output to a monitor or TV, choose Genio 510, 700, or 1200 instead. For applications requiring MIPI DSI to a panel, Genio 420/520/720 expose two DSI interfaces.
## Developing on Genio 420
Because Genio 420 shares its EVK board and Yocto machine config with Genio 520 and 720, you develop on the P2V3 EVK regardless of which target SoC you plan to use in production. Build with the `genio-720-evk` machine:
```bash
MACHINE=genio-720-evk bitbake core-image-base
```
The bootloader auto-detects DRAM type (LP4X or LP5X) and capacity at runtime, so the same image boots across all three platforms without modification. Flash with genio-flash as you would for Genio 720.
For a comparison of the broader Genio family against NVIDIA Jetson for edge AI applications, see [MediaTek Genio vs NVIDIA Jetson Orin](/blog/mediatek-genio-vs-nvidia-jetson).
MediaTek's official Genio product pages are at [iot.mediatek.com/genio](https://iot.mediatek.com/genio). The MT8391/MT8371/MT8371LV datasheet is available through the MediaTek developer portal after registration.
---
## Jetson camera works with v4l2-ctl but fails to launch argus_camera, debug guide
URL: https://proventusnova.com/blog/jetson-camera-v4l2-works-argus-fails-debug/
Published: 2026-06-12
Author: Andres Campos
Tags: jetson, orin, argus, v4l2, camera, debugging, device tree, embedded linux
Why your Jetson camera works with v4l2-ctl but argus_camera fails, tegra-camera DT node issues, sensor mode tables, and the V4L2-to-Argus fault path.
The V4L2-works, Argus-fails failure mode is one of the most common Jetson camera bring-up issues because it's easy to misread as a hardware problem when it's purely a device tree metadata problem. V4L2 needs only CSI/VI hardware configuration. Argus needs additional software metadata, sensor dimensions, pixel format, clock rates, to initialize its ISP pipeline. Both read from device tree, but different nodes.
## Key Insights
- **V4L2 and Argus use different DT nodes**: V4L2 uses the sensor and VI/NVCSI hardware nodes; Argus additionally requires `tegra-camera-platform`
- **`sensor_modes` must match V4L2 format exactly**: if `active_w` × `active_h` × `pixel_t` doesn't match what V4L2 reports, Argus fails at mode selection
- **`LIBARGUS_ENABLE_LOGS=1` is mandatory for debugging**: without it, Argus failures produce only `Failed to create capture session` with no root cause
- **`physical_w` and `physical_h` in mm are required**: Argus uses physical sensor dimensions for ISP calibration; missing or zero values cause silent failures
- **The sensor_modes `cil_settletime` must be non-zero**: a zero value causes NVCSI timing errors that appear during Argus but not V4L2 capture
## The two-stack architecture
```
v4l2-ctl path:
Sensor I2C driver → VI/NVCSI DT nodes → /dev/videoN → v4l2-ctl
↑ Works if CSI/VI config is correct
argus_camera path:
Sensor I2C driver → VI/NVCSI DT nodes → /dev/videoN
↓
tegra-camera-platform node (Argus-specific)
↓
libargus / argus_daemon
↓
ICameraProvider → ICaptureSession
↑ Fails if tegra-camera-platform is missing or sensor_modes are wrong
```
## The 5 most common root causes, ranked
From bring-up work, when `v4l2-ctl` streams but Argus fails, the cause is almost always one of these, in this order of likelihood:
1. **Missing or wrong `tegra-camera-platform` module entry**: the `badge`, `position`, and `proc-device-tree` path must match the sensor node exactly; V4L2 doesn't read this node, Argus does.
2. **`sensor_modes` timing that doesn't match the sensor's real output**: `pix_clk_hz`, `line_length`, and lane count off by even one mode breaks Argus while raw V4L2 capture still works.
3. **Missing V4L2 controls Argus requires**: without exposure, gain, and frame-rate controls, the AE loop cannot initialize and capture-session creation fails.
4. **`embedded_metadata_height` mismatch**: the sensor emits (or doesn't emit) embedded metadata lines that the mode table doesn't declare.
5. **Stale `nvargus-daemon` state**: after any DTB or driver reload: `sudo systemctl restart nvargus-daemon`. A surprising share of "broken" setups is just a daemon holding old state.
Work the list top-down before deep-diving the logs, the sections below show how to confirm each one.
## Diagnosing with LIBARGUS_ENABLE_LOGS
```bash
# Always enable logs before running argus_camera
LIBARGUS_ENABLE_LOGS=1 argus_camera 2>&1 | tee /tmp/argus_debug.log
# Also useful: verbose logging
LIBARGUS_ENABLE_LOGS=3 argus_camera 2>&1 | head -100
# Key log entries to look for:
grep -E "sensor|mode|failed|error|tegra.camera|CameraProvider" /tmp/argus_debug.log
```
Common failure log messages and their causes:
| Log message | Root cause |
|---|---|
| `No cameras available` | `tegra-camera-platform` node missing from DT |
| `Failed to get sensor modes` | `sensor_modes` node missing under camera module in DT |
| `Sensor mode is incompatible` | `active_w`/`active_h`/`pixel_t` don't match V4L2 format |
| `Failed to create capture session` | Any of the above, or `argus_daemon` not running |
| `Invalid sensor mode` | `cil_settletime = "0"` or missing clock fields |
## The tegra-camera-platform node
This node lives in the device tree overlay alongside your sensor node:
```dts
/ {
tegra-camera-platform {
compatible = "nvidia, tegra-camera-platform";
/* Global parameters, size these to your pipeline */
num_csi_lanes = <4>;
max_lane_speed = <1500000>;
min_bits_per_pixel = <10>;
vi_peak_byte_per_pixel = <2>;
vi_bw_margin_pct = <25>;
max_pixel_speed = <7680000>;
isp_peak_byte_per_pixel = <5>;
isp_bw_margin_pct = <25>;
modules {
module0 {
status = "okay";
badge = "imx219_topleft"; /* unique identifier */
position = "topleft"; /* display position */
orientation = "1";
drivernode0 {
status = "okay";
pcl_id = "v4l2_sensor";
/* Path to your sensor I2C node in DT */
sysfs-device-tree = "/sys/firmware/devicetree/base/i2c@3160000/imx219@10";
is_silicon = "1";
};
};
};
};
};
```
## The sensor_modes table
Each `sensor_mode` entry maps to an Argus capture mode. The fields must match your actual sensor output:
```dts
/* In the sensor node itself (not tegra-camera-platform) */
imx219@10 {
/* ... other fields ... */
mode0 { /* Argus mode index 0 */
num_lanes = "4";
tegra_sinterface = "serial_a";
phy_mode = "DPHY";
discontinuous_clk = "no";
dpcm_enable = "false";
cil_settletime = "100"; /* MUST be non-zero */
/* These must match v4l2-ctl --get-fmt-video output exactly */
active_w = "1920";
active_h = "1080";
pixel_t = "bayer_rggb10"; /* match pixelformat */
readout_orientation = "0";
line_length = "3448"; /* active_w + horizontal blanking */
inherent_gain = "1";
mclk_multiplier = "25.0";
pix_clk_hz = "182400000"; /* pixel clock from datasheet */
min_gain_val = "1.0";
max_gain_val = "16.0";
min_hdr_ratio = "1";
max_hdr_ratio = "1";
min_framerate = "30.000000";
max_framerate = "30.000000";
min_exp_time = "34";
max_exp_time = "550385";
};
};
```
## Cross-checking sensor_modes against V4L2
```bash
# Step 1: Get V4L2 format info
v4l2-ctl -d /dev/video0 --list-formats-ext
# Note: width, height, pixel format
# Step 2: Get exact frame byte count
v4l2-ctl -d /dev/video0 \
--set-fmt-video=width=1920,height=1080,pixelformat=RG10 \
--stream-mmap --stream-count=1 --stream-to=/tmp/test.raw
wc -c /tmp/test.raw
# For RG10 (BAYER RAW10): 1920 * 1080 * 2 = 4,147,200 bytes
# If size doesn't match, active_w or active_h in sensor_modes is wrong
# Step 3: Run Argus with matching mode
# If mode 0 fails, try mode 1, 2 etc.
LIBARGUS_ENABLE_LOGS=1 argus_camera --sensor-id=0
```
## Quick checklist for V4L2-works, Argus-fails
1. `tegra-camera-platform` node exists in DT and `status = "okay"`
2. `modules/module0/drivernode0/sysfs-device-tree` path is correct (verify with `ls` on the running system)
3. `sensor_modes/mode0/active_w` and `active_h` match V4L2 reported resolution
4. `sensor_modes/mode0/pixel_t` matches V4L2 pixel format (`bayer_rggb10`, `yuv_uyvy8`, etc.)
5. `cil_settletime` is non-zero
6. `argus_daemon` is running: `systemctl status argus-daemon`
7. No LIBARGUS errors in `journalctl -u argus-daemon`
For the broader Argus camera driver documentation, see [Argus API and camera driver setup on Jetson](/blog/argus-api-camera-driver-jetson). For nvargus crash and deadlock debugging after session creation succeeds, see [nvargus crash and CaptureScheduler deadlock debugging](/blog/nvargus-crash-capturesched-deadlock-jetson).
## FAQ
### If v4l2-ctl works on my Jetson camera, why does argus_camera fail?
V4L2 only needs CSI/VI hardware configuration. Argus additionally requires a `tegra-camera-platform` device tree node with a `sensor_modes` table matching the V4L2 pixel format. A working V4L2 camera with a missing or mismatched `tegra-camera-platform` node will fail for Argus every time.
### What does argus_camera 'Failed to create capture session' mean?
Missing `tegra-camera-platform` node, no matching sensor modes, zero `physical_w`/`physical_h`, or `argus_daemon` not running. Enable `LIBARGUS_ENABLE_LOGS=1` to see the specific failure point.
### What is the tegra-camera-platform node and why does Argus need it?
An NVIDIA-specific DT node with sensor metadata, physical dimensions, sensor modes, clock rates, that Argus uses to configure the ISP. V4L2 doesn't use it; Argus cannot function without it.
### How do I find the correct sensor_modes values for my camera?
From the sensor datasheet: active pixel dimensions, pixel clock, horizontal blanking (for `line_length`). Verify by cross-checking raw frame byte count from `v4l2-ctl` against `active_w * active_h * bytes_per_pixel`.
---
---
## PREEMPT_RT real-time kernel on Jetson Orin, build, latency, and thread setup
URL: https://proventusnova.com/blog/jetson-orin-preempt-rt-real-time-kernel/
Published: 2026-06-12
Author: Aaron Angulo
Tags: jetson, orin, preempt-rt, real-time, linux, latency, cyclictest, embedded linux
Build and run a PREEMPT_RT real-time kernel on Jetson Orin for low-latency control, cyclictest, isolcpus, and SCHED_FIFO thread setup.
Jetson Orin with PREEMPT_RT is capable of running 1kHz control loops in production. The PREEMPT_RT kernel makes nearly all kernel code preemptible, reducing worst-case interrupt latency from 5-30ms on standard L4T to 50-200µs on a properly configured system. The setup requires building a custom kernel (NVIDIA does not ship a pre-built RT kernel) and configuring CPU isolation for your real-time threads.
## Key Insights
- **PREEMPT_RT requires building the L4T kernel yourself**: NVIDIA does not ship a pre-built RT variant; apply the PREEMPT_RT patchset to the L4T 5.15 kernel source
- **CPU isolation is required for predictable latency**: without `isolcpus`, the Linux scheduler will put housekeeping tasks on your RT core and spike latency
- **`mlockall(MCL_CURRENT | MCL_FUTURE)` is mandatory**: without it, page faults in your RT thread can stall for milliseconds during memory access
- **Worst-case latency is what matters for control loops, not average**: use `cyclictest` with `--mlockall --smp --priority=99` to measure worst-case under realistic load
- **CUDA workloads on other cores can cause DMA-related IRQ latency spikes**: if running CV inference alongside RT control, pin CUDA work to non-RT cores and IRQ-affinity the GPU interrupt away from the RT core
## The JetPack 6 shortcut: install the RT kernel via apt
Before building anything from source: on JetPack 6 (L4T r36), NVIDIA ships a prebuilt PREEMPT_RT kernel as Debian packages, installable over the air. If you're on JetPack 6 and don't need custom kernel config, this is the supported path:
```bash
# Enable the NVIDIA L4T apt repo (present by default on JetPack 6 systems)
sudo apt update
# Install the real-time kernel packages
sudo apt install nvidia-l4t-rt-kernel nvidia-l4t-rt-kernel-headers \
nvidia-l4t-rt-kernel-oot-modules nvidia-l4t-display-rt-kernel
# Reboot, the RT kernel is selected as the boot target
sudo reboot
# Verify
uname -a # should show PREEMPT_RT in the version string
```
NVIDIA documents this in the Jetson Linux Developer Guide under "Real-Time Kernel Using OTA Update". The source build below is still the right path on JetPack 5, in Yocto-based images, or when you need to change kernel configuration beyond what the prebuilt RT kernel ships with.
## Applying PREEMPT_RT to L4T kernel
### Via Yocto (meta-tegra, recommended for production)
```bitbake
# In your machine .conf or local.conf:
LINUX_KERNEL_TYPE = "preempt-rt"
# Or add the RT SCC to your kernel features:
KERNEL_FEATURES:append = " features/preempt-rt/preempt-rt.scc"
```
This uses the OE4T/meta-tegra layer's built-in PREEMPT_RT support for the `scarthgap` (JetPack 6.x) branch.
### Manual patch application
```bash
# Download L4T kernel sources
# From NVIDIA Jetson Linux page: Public_Sources.tbz2
tar xf Jetson_Linux_R36.x.0_aarch64.tbz2
source_sync.sh -k 5.15
# Find matching PREEMPT_RT patch
# kernel.org preempt-rt/patches/v5.15/
# Use the latest 5.15.x-rt patch matching your L4T minor version
wget https://cdn.kernel.org/pub/linux/kernel/projects/rt/5.15/patch-5.15.71-rt51.patch.gz
# Apply
cd kernel/kernel-5.15
zcat ../patch-5.15.71-rt51.patch.gz | patch -p1
# Configure
make tegra_defconfig
scripts/config --enable PREEMPT_RT
scripts/config --disable PREEMPT_LAZY
scripts/config --enable CPU_FREQ_DEFAULT_GOV_PERFORMANCE
# Build
make -j$(nproc) Image dtbs modules
```
## Verifying RT kernel is running
```bash
uname -r
# Should include "rt" in version string
# e.g., 5.15.71-tegra-rt51-v8+
# Check preemption model
grep PREEMPT_RT /boot/config-$(uname -r)
# CONFIG_PREEMPT_RT=y
# Verify no PREEMPT_LAZY (defeats RT preemptability)
grep PREEMPT_LAZY /boot/config-$(uname -r)
# Should be: # CONFIG_PREEMPT_LAZY is not set
```
## CPU isolation setup
```bash
# Add to /boot/extlinux/extlinux.conf APPEND line:
# isolcpus=3 nohz_full=3 rcu_nocbs=3 irqaffinity=0-2
# After reboot, verify CPU 3 is isolated
cat /sys/devices/system/cpu/isolated
# 3
# Move all non-RT IRQs away from CPU 3
for i in /proc/irq/*/smp_affinity; do
echo 7 > $i 2>/dev/null # CPUs 0,1,2 only (bitmask 0b111 = 7)
done
```
## Writing an RT control thread
```c
#include
#include
#include
#include
#include
#define PERIOD_NS 1000000 /* 1ms = 1kHz control loop */
#define RT_PRIORITY 90 /* 1-99; higher = higher priority */
void *rt_control_loop(void *arg) {
struct sched_param param = { .sched_priority = RT_PRIORITY };
struct timespec next, now;
/* Lock all memory, prevents page faults in RT context */
mlockall(MCL_CURRENT | MCL_FUTURE);
/* Set SCHED_FIFO, preempts all non-RT threads */
pthread_setschedparam(pthread_self(), SCHED_FIFO, ¶m);
/* Pin to isolated CPU core */
cpu_set_t cpuset;
CPU_ZERO(&cpuset);
CPU_SET(3, &cpuset);
pthread_setaffinity_np(pthread_self(), sizeof(cpuset), &cpuset);
clock_gettime(CLOCK_MONOTONIC, &next);
while (1) {
/* ── Your 1ms control work here ── */
read_sensors();
compute_pid();
write_actuators();
/* ── End control work ── */
/* Advance deadline by one period */
next.tv_nsec += PERIOD_NS;
if (next.tv_nsec >= 1000000000LL) {
next.tv_nsec -= 1000000000LL;
next.tv_sec++;
}
/* Sleep until absolute time, avoids drift accumulation */
clock_nanosleep(CLOCK_MONOTONIC, TIMER_ABSTIME, &next, NULL);
}
return NULL;
}
int main(void) {
pthread_t rt_thread;
pthread_attr_t attr;
pthread_attr_init(&attr);
pthread_attr_setschedpolicy(&attr, SCHED_FIFO);
/* Stack size: preallocate to prevent page faults */
pthread_attr_setstacksize(&attr, 1024 * 1024); /* 1MB */
pthread_create(&rt_thread, &attr, rt_control_loop, NULL);
pthread_join(rt_thread, NULL);
return 0;
}
```
Compile with:
```bash
gcc -O2 -o rt_control rt_control.c -lpthread -lrt
```
## Measuring latency with cyclictest
```bash
# Install rt-tests
apt install rt-tests
# Run cyclictest, 1000Hz on isolated CPU 3, 60 second test
sudo cyclictest \
--mlockall \
--smp \
--priority=99 \
--interval=1000 \ # 1ms interval
--distance=0 \
--affinity=3 \ # isolated CPU
--duration=60 \
--histogram=200 # build latency histogram up to 200µs
# Good result on Jetson Orin with PREEMPT_RT:
# T: 0 ( 3) P:99 I:1000 C: 60000 Min: 18 Act: 24 Avg: 21 Max: 87
# Worst-case: 87µs at 60000 samples
```
## Latency comparison: standard vs PREEMPT_RT
| Kernel | Idle worst-case | Under load worst-case | Suitable for |
|---|---|---|---|
| Standard L4T 5.15 | 2-5ms | 15-30ms | Applications without hard timing |
| PREEMPT_RT L4T 5.15 | 50-120µs | 150-500µs | Control loops ≥500Hz |
| Jailhouse RTOS core | 10-30µs | 10-30µs | Hard real-time <100µs |
## FAQ
### Does Jetson Orin support PREEMPT_RT?
Yes. Apply the PREEMPT_RT patchset to the L4T 5.15 kernel source, or use `LINUX_KERNEL_TYPE = "preempt-rt"` in meta-tegra. NVIDIA does not ship a pre-built RT kernel.
### What is the typical worst-case latency with PREEMPT_RT on Jetson Orin?
50–120µs on a quiet system with an isolated core. Under load (USB, PCIe, CUDA activity), 150–500µs. Use `cyclictest` to measure your specific workload.
### How is PREEMPT_RT different from standard Linux for real-time tasks?
PREEMPT_RT converts kernel spinlocks and interrupt handlers to preemptible mutexes, allowing RT threads to preempt nearly anywhere in kernel code. Worst-case latency drops from 5–30ms to 50–300µs.
### Is PREEMPT_RT on Jetson Orin suitable for hard real-time control?
PREEMPT_RT is soft real-time, excellent typical latency and much better worst-case than standard Linux, but no hard guarantees. For hard real-time (<100µs guaranteed), use Jailhouse with a dedicated bare-metal RTOS core.
---
---
## Jetson Orin silent GPU hang under sustained compute, host1x debug
URL: https://proventusnova.com/blog/jetson-orin-silent-gpu-hang-host1x/
Published: 2026-06-12
Author: Aaron Angulo
Tags: jetson, orin, gpu, cuda, debugging, host1x, compute, embedded linux
Debug silent GPU hangs on Jetson Orin AGX under sustained compute, host1x interrupt stalls, tegrastats, and known JP 6.x mitigation steps.
Silent GPU hangs on Jetson Orin are distinct from application crashes, the process stays alive, tegrastats shows high GPU utilization, and your compute pipeline simply stops making progress with no error message. The root cause in most reported cases is a host1x interrupt servicing stall: the GPU command FIFO fills up because the driver's interrupt handler is not running promptly enough, triggering a timeout recovery that resets the GPU state.
## Key Insights
- **Silent hang ≠ crash**: check if your CUDA process is still alive in `ps aux`; if alive and stuck in a CUDA call, it's a hang, not a crash
- **`host1x channel timeout` in dmesg confirms the stall path**: if you see this, the GPU driver triggered a recovery sequence
- **JP 6.2.2 reduces but may not eliminate the issue**: upgrade first; measure improvement before looking for other workarounds
- **IRQ affinity matters**: if the `host1x` interrupt is sharing a core with high-frequency other IRQs, latency spikes can trigger timeouts; pin it to a dedicated core
- **Unified memory workloads are most vulnerable**: large unified memory allocations (typical in LLM/vLLM) trigger more host1x DMA activity than discrete allocations
## Identifying a GPU hang
```bash
# 1. Check if the CUDA process is alive
ps aux | grep your_compute_app
# If alive and CPU usage is low but GPU is high → hang
# 2. Check tegrastats
tegrastats --interval 500
# GR3D_FREQ shows 95-100% but your benchmark has stalled
# EMC_FREQ is also high (DMA traffic ongoing)
# 3. Check dmesg for host1x events
dmesg | grep -E "host1x|gk20a|nvgpu|fifo|timeout|hung|gpu" | tail -30
# Common hang signatures:
# "host1x: gk20a: channel 1: timeout"
# "nvgpu: fifo error"
# "host1x: channel X job timed out after 10000ms"
# 4. Check if nvtop shows the hang
sudo apt install nvtop
nvtop
# MEM% and GPU% stuck at 100% with no change → confirmed hang
```
## host1x interrupt affinity
Moving the `host1x` IRQ to a dedicated CPU core reduces contention:
```bash
# Find the host1x IRQ number
grep -E "host1x|tegra" /proc/interrupts | head -20
# Example output shows IRQ 123 for host1x
# Set affinity to CPU 2 (bitmask 0x4)
echo 4 > /proc/irq/123/smp_affinity
# Also set GPU interrupt affinity
grep -E "nvidia|gk20a|nvgpu" /proc/interrupts
# Set those to the same core
echo 4 > /proc/irq//smp_affinity
```
Make persistent across reboots with a systemd service:
```ini
# /etc/systemd/system/irq-affinity.service
[Unit]
Description=Set host1x and GPU IRQ affinity
After=multi-user.target
[Service]
Type=oneshot
ExecStart=/usr/local/bin/set-irq-affinity.sh
RemainAfterExit=yes
[Install]
WantedBy=multi-user.target
```
## Timeout tuning
The default host1x job timeout is 10 seconds. For workloads that legitimately take longer (large model inference), increase the timeout:
```bash
# Check current timeout
cat /sys/kernel/debug/host1x/*/timeout
# or
cat /sys/module/nvgpu/parameters/jobstate_timeout_ms
# Increase to 60 seconds
echo 60000 > /sys/module/nvgpu/parameters/jobstate_timeout_ms
```
This prevents the driver from incorrectly triggering a recovery on legitimately long-running kernels.
## Recovery from a GPU hang
When a hang occurs, the host1x driver triggers a GPU reset and attempts to recover the channel:
```bash
# The driver recovery log looks like:
# nvgpu: gr: gr recovery started
# nvgpu: mm: mmu fault
# nvgpu: fifo reset runlist 0
# After recovery, the CUDA context is invalid
# The safest recovery is to restart the application
sudo kill -9 $(pidof your_compute_app)
# If the driver did not recover cleanly, rmmod and modprobe the GPU driver
sudo rmmod nvgpu
sudo modprobe nvgpu
```
## Upgrading to JetPack 6.2.2
```bash
# Verify current JetPack version
cat /etc/nv_tegra_release
# Should show R36 REVISION: 5.0 for JP 6.2.2
# If on older version, upgrade via SDK Manager or apt (if NVIDIA apt repo is configured)
sudo apt update
sudo apt upgrade
# Check for nvgpu driver version
modinfo nvgpu | grep version
```
For general GPU utilization monitoring tools on Jetson, see [Jetson Orin high RAM usage at idle](/blog/jetson-orin-high-ram-usage-idle) which covers `tegrastats` and `jtop` usage. For CUDA-accelerated LLM inference workloads that can trigger this issue, see [Running LLMs on Jetson Orin](/blog/llm-inference-jetson-orin-llamacpp-ollama).
## FAQ
### What is a silent GPU hang on Jetson Orin?
The GPU stops processing CUDA work, kernels don't complete, but the process stays alive and no error is raised. Caused by a host1x interrupt servicing stall where the GPU command FIFO fills and the driver triggers a timeout recovery.
### What is host1x on Jetson Orin?
The hardware bus coordinating DMA and interrupt delivery for all Jetson accelerators. GPU work is submitted through host1x channels; completion interrupts come back through host1x. Interrupt stalls here cause GPU hangs.
### How do I confirm a GPU hang is caused by host1x on Jetson Orin?
Look for `host1x: channel X job timed out` or `nvgpu: fifo error` in dmesg, combined with tegrastats showing 100% GR3D utilization and no application progress.
### Has NVIDIA addressed the host1x stall bug in JetPack 6.x?
JetPack 6.2.2 includes mitigation for the most common case (mixed CUDA + unified memory workloads). Upgrade to JP 6.2.2 first. Persistent cases may require IRQ affinity tuning or job timeout adjustments.
---
---
## C-PHY and D-PHY routing on Jetson Orin custom carrier boards, hardware design guide
URL: https://proventusnova.com/blog/mipi-cphy-dphy-routing-design-jetson-carrier-board/
Published: 2026-06-12
Author: Andres Campos
Tags: jetson, orin, mipi, cphy, dphy, hardware design, carrier board, pcb, embedded
Hardware routing guide for C-PHY and D-PHY MIPI lanes on Jetson Orin custom carrier boards, trace length, impedance, and layout rules.
MIPI CSI-2 routing failures on custom carrier boards almost never show up in electrical tests, the traces look fine on a VNA, the signal looks clean on a differential probe, and yet the camera driver won't lock or produces intermittent errors. The failure mode is almost always a combination of lane length mismatch, via discontinuities, and stacked-up impedance errors that only manifest at the 1–2.5Gbps data rates used in production.
## Key Insights
- **Length matching is more critical than absolute trace length**: intra-pair skew (between + and - of a differential pair) must be < 5mm; inter-lane skew (between data lanes) must be < 10mm
- **Vias destroy impedance continuity**: each via adds 0.5–1pF capacitance; minimize vias on MIPI lanes, and back-drill or use microvia stacks if vias are unavoidable
- **Reference plane continuity matters**: do not route MIPI traces over split or interrupted ground planes; every gap in the reference plane causes a localized impedance change
- **C-PHY requires symmetrical 3-conductor routing**: all three conductors in a trio must be identical in length and impedance; asymmetry degrades the eye opening
- **The Jetson module connector defines the impedance reference**: traces must maintain 100Ω differential from the module connector to the camera connector with no discontinuities
## D-PHY lane structure
```
Jetson Orin Module
(CSI0, 4 lanes)
│
├── CLK_P / CLK_N (clock lane, differential pair)
├── DATA0_P / DATA0_N (data lane 0)
├── DATA1_P / DATA1_N (data lane 1)
├── DATA2_P / DATA2_N (data lane 2)
└── DATA3_P / DATA3_N (data lane 3)
│
│ ← PCB traces (must maintain 100Ω differential)
│
Camera connector / flex
```
## C-PHY trio structure
```
Jetson Orin Module
(CSI0, 3 trios = 6 lanes equivalent)
│
├── TRIO0_A / TRIO0_B / TRIO0_C (3 conductors per trio)
├── TRIO1_A / TRIO1_B / TRIO1_C
└── TRIO2_A / TRIO2_B / TRIO2_C
│
│ ← PCB traces (60Ω single-ended each conductor)
│
Camera connector
```
## PCB stackup recommendation
For a 4-layer carrier board carrying MIPI signals:
```
Layer 1: Signal (MIPI traces, component side)
Layer 2: Ground plane (continuous, no splits under MIPI)
Layer 3: Power planes (split OK, away from MIPI)
Layer 4: Signal (other signals, opposite side)
```
Target trace parameters (FR4, 4-layer, 1oz copper):
- Trace width: 0.1mm (4 mil)
- Trace spacing: 0.1mm intra-pair, 0.3mm inter-pair
- Differential impedance: 100Ω ± 10%
For 6-layer boards with blind/buried vias (recommended for multi-CSI carrier boards):
```
Layer 1: Signal (MIPI)
Layer 2: Ground
Layer 3: Signal (other)
Layer 4: Ground
Layer 5: Power
Layer 6: Signal (other)
```
## Length matching rules
| Constraint | Required tolerance | Notes |
|---|---|---|
| Intra-pair (P vs N) | < 5mm | Use serpentine near the connector |
| Inter-lane (DATA0 vs DATA1 vs ...) | < 10mm | Clock and data can differ more |
| Clock vs data (D-PHY) | < 20mm | Clock is recovered separately |
| C-PHY trio conductors (A, B, C) | < 2mm | Tighter than D-PHY due to trio encoding |
```
Good: serpentine length-matching on the P trace to match N
┌──────────────────────────────────────────────────┐
│ DATA0_P: ───────────────────────────────────── │
│ DATA0_N: ─────┬──┬─────────────────────────── │
│ └──┘ (serpentine adds ~3mm) │
└──────────────────────────────────────────────────┘
Bad: sharp bends on differential pairs
DATA0_P: ───────┐ (adds stub and impedance change)
└──────
DATA0_N: ─────────────
```
## Via minimization
Each via on a MIPI lane adds capacitance that causes a local impedance dip. At 2.5Gbps:
- 0 vias: minimal signal degradation
- 1 via per lane: ~0.5–1% reflections (usually acceptable)
- 2+ vias per lane: significant eye closure, increased BER
If vias are unavoidable:
1. Use microvia stacks (buried/blind) instead of through-hole vias, smaller capacitance
2. Back-drill through-hole vias to remove the stub below the exit layer
3. Place vias in pairs (one on P, one on N at the same location) to maintain pair balance
## Connector selection
| Connector type | Max data rate | Notes |
|---|---|---|
| Molex FPC 0.5mm pitch | 2.5Gbps/lane | Standard for sensor flex connections |
| Hirose FH52 0.5mm | 2.5Gbps/lane | Lower profile than Molex |
| JAE FI-XB 0.3mm | 4Gbps/lane | Higher density, harder to assemble |
| Board-to-board (Samtec) | 6Gbps+ | For rigid PCB-to-PCB MIPI |
For CSI-2 connections requiring hot-pluggable or field-replaceable cameras, avoid standard FPC connectors, they are not rated for frequent insertion cycles. Use a locking FFC connector rated for 50+ cycles minimum.
## Common routing mistakes and fixes
| Mistake | Effect | Fix |
|---|---|---|
| Routing MIPI over split ground plane | Impedance spike at gap, reflections | Move split plane gap away from MIPI traces |
| Asymmetric intra-pair length (> 10mm) | Phase error, reduced noise margin | Serpentine the shorter trace |
| Via under differential pair (not both) | Single-ended spike | Via both P and N at same location |
| 90° bends on differential pairs | Impedance mismatch at corner | Use 45° bends or curved routing |
| Pull-up/pull-down resistors on MIPI lines | Impedance distortion, DC offset | Remove, MIPI has on-die termination |
| Mixing layers without via pairs | Broken reference plane continuity | Keep MIPI on one layer or use matched via pairs |
For carrier board hardware design considerations including power sequencing and connector placement, see [Jetson carrier board hardware design mistakes to avoid](/blog/jetson-carrier-board-hardware-design-mistakes). For enabling the CSI interface in device tree after hardware bring-up, see [How to enable CSI0 on Jetson Orin](/blog/jetson-orin-csi0-enable-device-tree).
## FAQ
### What is the difference between C-PHY and D-PHY for Jetson Orin camera interfaces?
D-PHY uses differential pairs (clock + data lanes). C-PHY uses 3-wire trios that encode clock and data together, achieving higher bandwidth per pin. Jetson Orin AGX supports both. Most camera sensors use D-PHY; choose based on your sensor's physical interface.
### What trace impedance should I use for MIPI D-PHY on a Jetson carrier board?
100Ω differential (50Ω each trace to ground). For C-PHY, 60Ω single-ended per conductor. Tolerance: ±10%.
### How long can MIPI traces be on a Jetson carrier board?
Under 150mm for rates above 1Gbps, under 100mm for 2.5Gbps lanes on standard FR4. Use low-loss PCB material for longer runs.
### Do I need termination resistors on MIPI D-PHY lanes on a carrier board?
No. Both Jetson NVCSI and standard camera sensors have on-die 100Ω differential termination. Adding external resistors creates impedance discontinuities.
---
---
## Flashing a custom Yocto image to Jetson Orin Nano Super, NVMe and eMMC
URL: https://proventusnova.com/blog/yocto-custom-image-flash-jetson-orin-nano-super/
Published: 2026-06-12
Author: Andres Campos
Tags: jetson, orin, yocto, flash, orin-nano-super, nvme, emmc, embedded linux
Flash a custom Yocto image to Jetson Orin Nano Super, NVMe and eMMC targets, flash.sh options, and partition layout for custom Yocto builds.
Flashing a custom Yocto image to Jetson Orin Nano Super involves a few specific choices around MACHINE name, storage target, and flash.sh flags that trip up engineers coming from other Jetson platforms. The Orin Nano Super uses the same MACHINE as the original Orin Nano in meta-tegra, the devkit has NVMe as primary storage (not eMMC), and the rootfs must be a compatible .ext4 image built with the `scarthgap` branch of meta-tegra.
## Key Insights
- **MACHINE = `jetson-orin-nano-devkit-nvme`** for the standard Orin Nano Super devkit setup with NVMe rootfs
- **`scarthgap` branch of meta-tegra is required**: JP 6.2+ / L4T R36.x; do not use the `kirkstone` branch
- **flash.sh needs sudo and the L4T host tools**: install from the BSP tarball or via SDK Manager; the Yocto build does not produce flash.sh
- **`BOOTDEV_ROOTFS`** in the Yocto build controls which storage device the rootfs goes to, set to `nvme0n1` for NVMe
- **First flash must be done via USB-C recovery mode**: subsequent rootfs updates can use `ota-update` or A/B partition switching, but the initial flash requires recovery mode
## Prerequisites
```bash
# Host requirements (Ubuntu 20.04 or 22.04 x86_64)
apt install -y python3 python3-distutils abootimg simg2img \
libxml2-utils xxd img2simg bc cpp dtc
# Download L4T R36.x BSP (host tools for flash.sh)
# From developer.nvidia.com/embedded/jetson-linux
tar xf Jetson_Linux_R36.x.0_aarch64.tbz2 # extracts Linux_for_Tegra/
# Download rootfs tarball (only if not using custom Yocto image)
# tar xf Tegra_Linux_Sample-Root-Filesystem_R36.x.0_aarch64.tbz2 \
# -C Linux_for_Tegra/rootfs/
```
## Building the Yocto image for Orin Nano Super
```bash
# Clone tegra-demo-distro (includes meta-tegra as submodule)
git clone https://github.com/OE4T/tegra-demo-distro
cd tegra-demo-distro
git checkout scarthgap # JetPack 6.x branch
git submodule update --init
# Set up build environment for Orin Nano NVMe
. ./setup-env --machine jetson-orin-nano-devkit-nvme
# Build the image
bitbake demo-image-full # or your custom image
# Output: build/tmp/deploy/images/jetson-orin-nano-devkit-nvme/
# Key files:
# - demo-image-full-jetson-orin-nano-devkit-nvme.ext4 ← rootfs
# - tegra234-p3767-0000-p3768-0000-orin.dtb ← device tree
# - Image ← kernel
```
## Flashing to NVMe (standard devkit setup)
```bash
cd Linux_for_Tegra/
# Put Orin Nano into recovery mode:
# 1. Power off
# 2. Hold Force Recovery button (button near USB-C port)
# 3. Apply power (or press Reset while holding Force Recovery)
# 4. Release Force Recovery after 2 seconds
# Verify device is in recovery mode
lsusb | grep NVIDIA
# Bus 001 Device XXX: ID 0955:7523 NVIDIA Corp. APX
# Copy Yocto rootfs image to Linux_for_Tegra/rootfs
sudo mount -o loop \
../build/tmp/deploy/images/jetson-orin-nano-devkit-nvme/demo-image-full-jetson-orin-nano-devkit-nvme.ext4 \
/mnt/rootfs_tmp
sudo rsync -a /mnt/rootfs_tmp/ rootfs/
sudo umount /mnt/rootfs_tmp
# Run apply_binaries.sh to inject NVIDIA binaries into rootfs
sudo ./apply_binaries.sh
# Flash to NVMe
sudo ./flash.sh jetson-orin-nano-devkit-nvme nvme0n1p1
```
## Faster: direct .ext4 image flash
For repeated development flashes, use the `--direct-block-device` method to write the rootfs image directly without rsync:
```bash
# Generate the flash package (does not actually flash)
sudo ./flash.sh --no-flash jetson-orin-nano-devkit-nvme nvme0n1p1
# The prepared package is in mnt/
# Now flash with your Yocto rootfs directly
sudo ./flash.sh \
--no-root-check \
-r \ # reuse existing package (skip re-preparation)
-k APP \ # update only the rootfs partition
--image ../build/tmp/deploy/images/jetson-orin-nano-devkit-nvme/demo-image-full-jetson-orin-nano-devkit-nvme.ext4 \
jetson-orin-nano-devkit-nvme nvme0n1p1
```
The `-k APP` flag flashes only the rootfs partition, skipping bootloader/UEFI re-flash. This takes 3-4 minutes instead of 8-10 for a full flash.
## Partition layout verification
```bash
# After flashing and booting, verify partition layout
lsblk
# nvme0n1
# ├─nvme0n1p1 ← rootfs (APP partition)
# └─nvme0n1p2 ← var
# Check rootfs is mounted
df -h /
# /dev/nvme0n1p1 xxx G xxx G xxx G xx% /
# Verify L4T version
cat /etc/nv_tegra_release
# # R36 (release), REVISION: 4.0 ...
```
## Troubleshooting common flash failures
| Error | Cause | Fix |
|---|---|---|
| `No NVIDIA device found` | Not in recovery mode | Hold Force Recovery, power cycle |
| `Partition APP not found` | Wrong MACHINE name | Use `jetson-orin-nano-devkit-nvme` not `jetson-orin-nano-devkit` |
| `Error: NVMe device not detected` | NVMe not installed in M.2 slot | Insert NVMe SSD before flashing |
| `apply_binaries.sh: rootfs not extracted` | Skipped rootfs step | Extract Sample-Root-Filesystem or sync Yocto rootfs first |
| `Flash failed: protocol timeout` | USB-C cable issue | Use a known-good USB-C cable; avoid USB 3.x hubs |
For flash.sh options and partition layout details, see [flash.sh on Jetson Orin, complete guide](/blog/flash-sh-jetson-orin-guide).
## FAQ
### What is the Jetson Orin Nano Super?
A refreshed Orin Nano module with higher performance unlocked at 25W (MAXN mode), using the same T234 SoC as other Orin modules. Same carrier board as the original Orin Nano devkit. Requires JetPack 6.2+.
### How do I flash a custom Yocto image to Jetson Orin Nano Super?
Build with `MACHINE = jetson-orin-nano-devkit-nvme` on the `scarthgap` meta-tegra branch, then flash with `sudo ./flash.sh jetson-orin-nano-devkit-nvme nvme0n1p1` from the L4T host tools directory with the device in recovery mode.
### What MACHINE name does Jetson Orin Nano Super use in meta-tegra?
`jetson-orin-nano-devkit-nvme` for NVMe rootfs. The Super uses the same MACHINE as the original Orin Nano, no separate name.
### What is the difference between flashing to NVMe vs eMMC on Jetson Orin Nano?
The Orin Nano devkit uses NVMe as primary storage (no on-board eMMC). Use `nvme0n1p1` as the rootfs target. microSD is available as an alternative with a different configuration.
---
---
## GMSL YUV422 capture and FORCE_FE errors on Jetson Orin, debug guide
URL: https://proventusnova.com/blog/gmsl2-yuv422-force-fe-errors-jetson/
Published: 2026-06-11
Author: Andres Campos
Tags: jetson, orin, gmsl, yuv422, camera, max9296, csi, v4l2, embedded linux
Debug GMSL YUV422 capture issues on Jetson Orin, FORCE_FE decoder config, partial frame faults, and MAX9295/MAX9296 YUV format setup.
GMSL YUV422 capture problems on Jetson trace almost exclusively to a mismatch between what the MAX9296 deserializer outputs on the MIPI bus and what the Jetson NVCSI driver expects. The partial-frame symptom, top portion valid, bottom black, is the signature of a per-line byte count mismatch: the CSI receiver thinks each line is shorter than it actually is and closes frames early.
## Key Insights
- **YUV422 8-bit outputs 2 bytes per pixel**: vs RAW8's 1 byte per pixel at the same resolution; the CSI configuration must account for this
- **The `FORCE_FE` register forces a Frame End on the MIPI output**: when configured, the deserializer inserts an end-of-frame marker after a fixed pixel count; if this doesn't match the sensor output, frames are truncated
- **`MEDIA_BUS_FMT_UYVY8_1X16` is the correct format enum** for YUV422 8-bit in the Jetson camera DT
- **MAX9296 data type register must be set to `0x1E`** for YUV422, the default (RAW12 = `0x2C`) will cause the MIPI receiver to misinterpret the data
- **dmesg `crc error` or `force-fe triggered`** confirms the deserializer output doesn't match NVCSI expectations
## The YUV422 bandwidth math
At 1920×1080:
- RAW12: 1920 × 1080 × 12 bits = 24.9 Mbytes/frame
- YUV422 8-bit: 1920 × 1080 × 16 bits = 33.2 Mbytes/frame
For the same framerate, YUV422 requires ~33% more lane bandwidth. A 4-lane GMSL2 link at 3Gbps/lane can sustain 1080p60 in YUV422 comfortably. The issue is not bandwidth, it's the data type mismatch in the MIPI header.
## MIPI data type configuration on MAX9296
The MAX9296 transmits a MIPI CSI-2 packet header with a Data Type field on every line. The Jetson NVCSI uses this header to determine how to parse incoming data.
```
MIPI CSI-2 Short Packet Header:
[ Virtual Channel | Data Type | Word Count | ECC ]
─────────
0x2C = RAW12 (default MAX9296)
0x1E = YUV422 8-bit ← must set this
0x1F = YUV422 10-bit
```
Setting the correct data type in the MAX9296 (via I2C on the serializer/deserializer):
```c
/* MAX9296 I2C writes to configure YUV422 8-bit output */
/* Register 0x0313 = DATA_TYPE_SEL for PIPE_X */
i2c_write(max9296_addr, 0x0313, 0x5E); /* YUV422 8-bit, VC=0 */
/* Register 0x031C = MIPI output format for pipe X */
i2c_write(max9296_addr, 0x031C, 0x1E); /* 0x1E = YUV422 */
/* Verify PIPE_X is configured for 8-bit YUV */
i2c_read(max9296_addr, 0x0313, &val);
/* val should be 0x5E */
```
In the MAX9296 kernel driver (max9296.c), these registers are typically set in the `max9296_set_pipe_settings` function. If using a vendor-provided driver that hardcodes RAW12, you need to patch the register write sequence.
## Device tree configuration for YUV422
```dts
/* In your camera module node */
&i2c_camera {
your_sensor@42 {
compatible = "your-sensor";
reg = <0x42>;
/* This must match the deserializer data type output */
sensor_modes {
mode0 {
num_lanes = "4";
tegra_sinterface = "serial_a";
phy_mode = "DPHY";
discontinuous_clk = "no";
dpcm_enable = "false";
cil_settletime = "0";
active_w = "1920";
active_h = "1080";
pixel_t = "yuv_uyvy8"; /* YUV422 format */
readout_orientation = "0";
line_length = "2200";
inherent_gain = "1";
mclk_multiplier = "25";
pix_clk_hz = "297000000";
min_gain_val = "1";
max_gain_val = "16";
min_hdr_ratio = "1";
max_hdr_ratio = "1";
min_framerate = "30";
max_framerate = "30";
min_exp_time = "34";
max_exp_time = "550385";
};
};
};
};
/* tegra-camera-platform media bus format override */
&cam_i2cmux {
drivernode0 {
pcl_id = "v4l2_sensor";
/* Override default RAW12 with YUV422 */
physical_w = "5.095";
physical_h = "4.930";
};
};
```
The `pixel_t = "yuv_uyvy8"` entry is critical, it sets the `MEDIA_BUS_FMT_UYVY8_1X16` bus format in the Tegra camera platform, which controls what NVCSI expects.
## Diagnosing the partial frame issue
```bash
# 1. Check dmesg for MIPI framing errors
dmesg | grep -E "nvcsi|crc|force.fe|overflow|frame.start" | tail -30
# 2. Capture a test frame and check the frame size
v4l2-ctl -d /dev/video0 \
--set-fmt-video=width=1920,height=1080,pixelformat=UYVY \
--stream-mmap --stream-count=1 --stream-to=/tmp/frame.raw
# YUV422 8-bit frame should be exactly:
# 1920 * 1080 * 2 = 4,147,200 bytes
ls -la /tmp/frame.raw
# If size is ~2MB (half), you have a RAW8 config on a YUV422 stream
# 3. Check what pixel format the driver reports
v4l2-ctl -d /dev/video0 --get-fmt-video
# Should show UYVY or YUYV, not RG10/BA10
# 4. Read the MAX9296 data type register over I2C
i2cget -y 2 0x48 0x0313
# Expected: 0x5e (YUV422 8-bit)
# If: 0x5f (RAW12) → this is the root cause
```
## FORCE_FE register usage
The FORCE_FE register on MAX9296 is sometimes used to work around sensors that don't generate proper MIPI end-of-frame packets:
```c
/* MAX9296 register 0x01CE: FORCE_FE_TIMEOUT */
/* Set to 0 to disable forced frame end (let sensor control it) */
i2c_write(max9296_addr, 0x01CE, 0x00);
/* If sensor requires FORCE_FE, set timeout to match frame period:
For 1080p30, frame period = ~33ms = 33000µs */
i2c_write(max9296_addr, 0x01CE, 0x04); /* unit-specific, check MAX9296 datasheet */
```
Forcing frame end at the wrong time produces the partial frame symptom even with correct data type configuration.
For the complete GMSL2 camera bring-up workflow including MAX9295/MAX9296 initialization sequence, see [GMSL2 camera bring-up on Jetson Orin with MAX9295/MAX9296](/blog/gmsl2-camera-bringup-jetson-orin-max9295-max9296). For GMSL serializer comparison and use case guidance, see [GMSL2 vs FPD-Link III on Jetson, SerDes comparison](/blog/gmsl2-vs-fpd-link-iii-jetson-serdes-comparison).
## FAQ
### What is a FORCE_FE error in GMSL camera capture on Jetson?
A MIPI protocol error where the deserializer inserts a forced Frame End marker that doesn't align with the actual frame data length. Caused by a mismatch between the deserializer output format (YUV422) and the CSI receiver configuration (RAW8/RAW12).
### Why does GMSL YUV422 capture show only the top portion of the frame?
The deserializer is outputting YUV422 (2 bytes/pixel) but the driver expects RAW8 (1 byte/pixel). The CSI receiver closes the frame after half the data arrives, producing a partial image.
### How do I configure MAX9295/MAX9296 for YUV422 output on Jetson Orin?
Set MAX9296 register 0x031C to 0x1E (YUV422 data type), set the DT pixel format to `yuv_uyvy8`, and verify `MEDIA_BUS_FMT_UYVY8_1X16` is in the tegra-camera-platform node.
### What dmesg messages indicate a GMSL MIPI framing error?
`nvcsi: vc0 crc error`, `nvcsi: force-fe triggered`, `vi: frame start timeout`, and `vi: overflow error`.
---
---
## nvcompositor vs parallel GStreamer pipelines on Jetson Orin, when each is slower
URL: https://proventusnova.com/blog/jetson-nvcompositor-vs-parallel-gstreamer/
Published: 2026-06-11
Author: Andres Campos
Tags: jetson, orin, gstreamer, nvcompositor, video, pipeline, performance, embedded linux
When to use nvcompositor vs parallel GStreamer pipelines on Jetson Orin, why compositor is slower, and how to choose the right path for your workload.
nvcompositor and parallel GStreamer pipelines both handle multi-stream video on Jetson, but they are optimized for different goals. nvcompositor is for synchronized multi-stream display compositing, the VIC engine guarantees all input streams are aligned to the same output frame. Parallel pipelines are for independent per-stream processing, each pipeline runs without waiting for others. Choosing wrong costs you 30–60ms of added latency per stream.
## Key Insights
- **nvcompositor synchronizes by design**: it waits for all input pads to have a buffer before compositing; this is a feature when sync is needed, a liability when it's not
- **VIC is a single-instance hardware block**: all nvcompositor instances share one VIC; if VIC is saturated, additional compositor inputs queue up
- **Parallel pipelines use independent buffer queues**: no cross-pipeline synchronization, each stream processes at its own pace
- **`nvmultistreamtiler` is faster than nvcompositor for display tiling**: it uses the same VIC but with an optimized batch path designed for the N-up tiling use case
- **The performance crossover depends on stream count**: for 1–2 streams, nvcompositor overhead is negligible; for 4+ streams at 1080p+, parallel pipelines become noticeably faster
## nvcompositor: how it works internally
```
Stream 0 ──► nvcompositor pad 0 ─┐
Stream 1 ──► nvcompositor pad 1 ─┤
Stream 2 ──► nvcompositor pad 2 ─┤──► VIC ──► Composited output
Stream 3 ──► nvcompositor pad 3 ─┘
▲
Waits for all pads
to have a buffer
```
The compositor's sync mechanism:
1. Wait for all input pads to have a buffer at the same (or close) PTS
2. Pass all buffers to VIC in one batch
3. Output the composited frame
If any one input stream stalls or runs slow, all output stalls.
## Parallel pipelines: how they differ
```
Stream 0 ──► Pipeline 0 ──► Sink 0 (independent)
Stream 1 ──► Pipeline 1 ──► Sink 1 (independent)
Stream 2 ──► Pipeline 2 ──► Sink 2 (independent)
Stream 3 ──► Pipeline 3 ──► Sink 3 (independent)
```
Each pipeline runs in its own GLib main loop thread. A slow stream affects only its own output.
## Benchmark comparison
Testing on AGX Orin with 4× 1080p30 NV12 streams:
| Approach | Throughput | End-to-end latency | CPU overhead |
|---|---|---|---|
| nvcompositor (sync=true) | All streams at 28fps (bottleneck = slowest) | ~95ms | Low (VIC-bound) |
| nvcompositor (sync=false) | Each stream at its native rate | ~45ms | Low (VIC-bound) |
| Parallel pipelines (no display) | Each stream at native rate | ~20ms | Medium (per-stream) |
| nvmultistreamtiler (display) | All streams at 30fps tiled | ~35ms | Low (VIC-optimized) |
## When to use nvcompositor
**Use nvcompositor when:**
- You need synchronized multi-stream compositing for display
- Streams must share the same output timestamp (surveillance mosaic, robotics multi-camera sync)
- You want a single HDMI/DSI output surface with all streams composed
```bash
# 4-camera mosaic with nvcompositor
gst-launch-1.0 \
nvcompositor name=comp \
sink_0::xpos=0 sink_0::ypos=0 sink_0::width=960 sink_0::height=540 \
sink_1::xpos=960 sink_1::ypos=0 sink_1::width=960 sink_1::height=540 \
sink_2::xpos=0 sink_2::ypos=540 sink_2::width=960 sink_2::height=540 \
sink_3::xpos=960 sink_3::ypos=540 sink_3::width=960 sink_3::height=540 ! \
nvvidconv ! \
'video/x-raw(memory:NVMM),width=1920,height=1080' ! \
nvdrmvideosink \
v4l2src device=/dev/video0 ! nvvidconv ! 'video/x-raw(memory:NVMM)' ! comp.sink_0 \
v4l2src device=/dev/video2 ! nvvidconv ! 'video/x-raw(memory:NVMM)' ! comp.sink_1 \
v4l2src device=/dev/video4 ! nvvidconv ! 'video/x-raw(memory:NVMM)' ! comp.sink_2 \
v4l2src device=/dev/video6 ! nvvidconv ! 'video/x-raw(memory:NVMM)' ! comp.sink_3
```
## When to use parallel pipelines
**Use parallel pipelines when:**
- Each stream goes to an independent output (separate inference, separate RTSP stream)
- Streams have different resolutions or framerates
- Latency per stream matters more than synchronized output
- One stream may stall intermittently without affecting others
```python
import gi
gi.require_version('Gst', '1.0')
from gi.repository import Gst, GLib
Gst.init(None)
def make_pipeline(device, stream_id):
pipeline = Gst.parse_launch(
f"v4l2src device={device} ! "
f"video/x-raw,format=NV12,width=1920,height=1080,framerate=30/1 ! "
f"queue max-size-buffers=2 leaky=downstream ! "
f"nvvidconv ! video/x-raw(memory:NVMM) ! "
f"nvinfer config-file-path=infer_config_{stream_id}.txt ! "
f"nvdsosd ! fakesink"
)
return pipeline
pipelines = [
make_pipeline("/dev/video0", 0),
make_pipeline("/dev/video2", 1),
make_pipeline("/dev/video4", 2),
make_pipeline("/dev/video6", 3),
]
for p in pipelines:
p.set_state(Gst.State.PLAYING)
loop = GLib.MainLoop()
loop.run()
```
## nvmultistreamtiler: the right tool for tiled display
For multi-camera display (the most common nvcompositor use case), `nvmultistreamtiler` is purpose-built and faster:
```bash
gst-launch-1.0 \
nvstreammux name=mux batch-size=4 \
width=1920 height=1080 ! \
nvmultistreamtiler rows=2 columns=2 \
width=1920 height=1080 ! \
nvvidconv ! \
'video/x-raw(memory:NVMM),format=NV12' ! \
nvdrmvideosink \
v4l2src device=/dev/video0 ! nvvidconv ! 'video/x-raw(memory:NVMM)' ! mux.sink_0 \
v4l2src device=/dev/video2 ! nvvidconv ! 'video/x-raw(memory:NVMM)' ! mux.sink_1 \
v4l2src device=/dev/video4 ! nvvidconv ! 'video/x-raw(memory:NVMM)' ! mux.sink_2 \
v4l2src device=/dev/video6 ! nvvidconv ! 'video/x-raw(memory:NVMM)' ! mux.sink_3
```
`nvmultistreamtiler` uses VIC's batch tiling path directly, bypassing the general compositor synchronization logic.
## Profiling your pipeline
```bash
# Enable GStreamer pipeline profiling
GST_DEBUG="GST_PERFORMANCE:5" gst-launch-1.0 ...
# Measure buffer latency per element
GST_DEBUG="GST_TRACER:7" \
GST_TRACERS="latency(flags=pipeline+element)" \
gst-launch-1.0 ...
# Check VIC utilization with tegrastats
tegrastats --interval 500 | grep VIC
```
For GStreamer pipeline latency reduction techniques beyond compositor choice, see [Reducing GStreamer pipeline latency on Jetson](/blog/reduce-gstreamer-pipeline-latency-jetson). For GStreamer pipeline examples including live streaming, see [GStreamer pipeline examples for Jetson](/blog/gstreamer-pipeline-examples-jetson).
## FAQ
### Why is nvcompositor slower than running parallel GStreamer pipelines on Jetson?
nvcompositor waits for all input streams to have synchronized buffers before compositing, this adds latency proportional to the slowest stream. Parallel pipelines run independently with no cross-stream synchronization.
### When should I use nvcompositor on Jetson?
When you need synchronized multi-stream compositing onto a single output surface, a camera mosaic where all streams must appear at the same timestamp. If streams are independent, parallel pipelines are faster.
### What hardware does nvcompositor use on Jetson Orin?
The VIC (Video Image Compositor) hardware block, a dedicated fixed-function engine for scaling, colorspace conversion, and compositing. VIC is single-instance; all compositor traffic shares it.
### Is there a way to use nvcompositor without synchronization overhead?
Set `sync=false` on compositor input pads for asynchronous compositing. For display tiling specifically, `nvmultistreamtiler` is a faster purpose-built alternative.
---
---
## GPIO and PWM configuration on Jetson Orin, pinmux, sysfs, and device tree
URL: https://proventusnova.com/blog/jetson-orin-gpio-pwm-pinmux-configuration/
Published: 2026-06-11
Author: Aaron Angulo
Tags: jetson, orin, gpio, pwm, pinmux, device tree, sysfs, embedded linux
Configure GPIO output and PWM on Jetson Orin using sysfs, the pinmux spreadsheet, and device tree overlays, with working examples for each approach.
GPIO and PWM configuration on Jetson Orin involves three layers: the pinmux spreadsheet that decides pin function, a device tree overlay that applies it, and either sysfs or libgpiod for runtime control. Skipping the pinmux step is the most common cause of "GPIO not working" issues, if the pin mux is set to I2C or UART function, sysfs GPIO writes are silently ignored.
## Key Insights
- **Pinmux must be set before GPIO/PWM works**: each pin has a hardware mux selecting its function (GPIO, SPI, I2C, UART, PWM); the mux defaults to non-GPIO on most pins
- **Use `gpiod` tools, not `/sys/class/gpio`**: the legacy sysfs GPIO interface is deprecated in kernel 5.x; `gpioget`/`gpioset`/`gpiomon` are the correct tools
- **40-pin header pin numbers ≠ Linux GPIO numbers**: header pin 7 is not GPIO 7; use the pinmux spreadsheet to find the correct `gpiochipX` line number
- **PWM period and duty cycle are in nanoseconds** in sysfs, a 1kHz signal is `period=1000000` (1,000,000 ns = 1ms)
- **The fan PWM is pre-configured** on devkits, `/sys/class/hwmon/hwmon*/pwm1` controls the fan without any DT changes
## Pinmux spreadsheet workflow
1. Download **Jetson Orin Series Pinmux** from [developer.nvidia.com/jetson-downloads](https://developer.nvidia.com/embedded/downloads)
2. Open in Excel or LibreOffice
3. Find your target pin (by module pin number or header position)
4. Change the "Customer Usage" column to your desired function (GPIO, PWM, etc.)
5. Set pull (Pull-Up/Pull-Down/None) and drive strength
6. Run the provided Python script to generate a `.dtsi` file
7. Compile to `.dtbo` and deploy as a device tree overlay
## 40-pin header GPIO map (Orin NX / Nano devkit)
| Header Pin | Module Pin | GPIO chip | Line | Default function |
|---|---|---|---|---|
| 3 | 191 | gpiochip1 | 0 | I2C1_SDA |
| 5 | 189 | gpiochip1 | 1 | I2C1_SCL |
| 7 | 164 | gpiochip0 | 164 | SPI1_SCK / GPIO |
| 11 | 136 | gpiochip0 | 136 | UART1_RTS / GPIO |
| 12 | 148 | gpiochip0 | 148 | I2S0_SCLK / GPIO |
| 13 | 194 | gpiochip0 | 194 | SPI1_SCK / GPIO |
| 15 | 106 | gpiochip0 | 106 | GPIO |
| 16 | 112 | gpiochip0 | 112 | GPIO |
| 18 | 118 | gpiochip0 | 118 | GPIO |
| 19 | 140 | gpiochip0 | 140 | SPI1_MOSI / GPIO |
Check the pinmux spreadsheet for the authoritative mapping for your carrier board.
## GPIO control with libgpiod
```bash
# Install gpiod tools
apt install gpiod
# List all GPIO chips
gpiodetect
# gpiochip0 [tegra234-gpio] (164 lines)
# gpiochip1 [tegra234-gpio-aon] (32 lines)
# List lines and their current state
gpioinfo gpiochip0
# Set a GPIO high (output)
gpioset --mode=signal gpiochip0 164=1
# Read a GPIO (input)
gpioget gpiochip0 164
# Monitor for edge events
gpiomon --num-events=10 --rising-edge gpiochip0 164
```
### C program using libgpiod
```c
#include
#include
int main(void) {
struct gpiod_chip *chip;
struct gpiod_line *line;
chip = gpiod_chip_open_by_name("gpiochip0");
if (!chip) {
perror("gpiod_chip_open_by_name");
return 1;
}
line = gpiod_chip_get_line(chip, 164);
/* Request as output, initial value = 0 */
gpiod_line_request_output(line, "my-app", 0);
/* Set high */
gpiod_line_set_value(line, 1);
gpiod_chip_close(chip);
return 0;
}
```
Compile:
```bash
gcc -o gpio_example gpio_example.c -lgpiod
```
## Device tree overlay for GPIO pinmux
Generated by the pinmux spreadsheet, or written manually:
```dts
/dts-v1/;
/plugin/;
/ {
overlay-name = "GPIO pin 15 as output";
compatible = "nvidia,p3767";
fragment@0 {
target = <&pinmux>;
__overlay__ {
/* Header pin 15 = TEGRA_MAIN_GPIO(A, 6) */
pinctrl-names = "default";
pinctrl-0 = <&gpio_pin15_config>;
gpio_pin15_config: gpio-pin-15 {
nvidia,pins = "soc_gpio41_pq5";
nvidia,function = "rsvd1"; /* GPIO mode */
nvidia,pull = ;
nvidia,tristate = ;
nvidia,enable-input = ;
};
};
};
};
```
Load for development:
```bash
# Compile
dtc -I dts -O dtb -o gpio-pin15.dtbo gpio-pin15.dts
# Add to /boot/extlinux/extlinux.conf:
# FDT_OVERLAYS gpio-pin15.dtbo
# Reboot
```
## PWM configuration
Jetson Orin has 8 PWM controllers. On the 40-pin header of the devkit:
| Header Pin | PWM chip | Channel | Period range |
|---|---|---|---|
| 32 | pwmchip1 | 0 | 1µs – 10s |
| 33 | pwmchip2 | 0 | 1µs – 10s |
```bash
# Export PWM channel 0 on pwmchip1
echo 0 > /sys/class/pwm/pwmchip1/export
# Set period to 1ms (1kHz)
echo 1000000 > /sys/class/pwm/pwmchip1/pwm0/period
# Set duty cycle to 50%
echo 500000 > /sys/class/pwm/pwmchip1/pwm0/duty_cycle
# Enable
echo 1 > /sys/class/pwm/pwmchip1/pwm0/enable
# Verify
cat /sys/class/pwm/pwmchip1/pwm0/enable
# 1
# Disable and unexport when done
echo 0 > /sys/class/pwm/pwmchip1/pwm0/enable
echo 0 > /sys/class/pwm/pwmchip1/unexport
```
The pin must be configured for PWM function in the pinmux overlay before these sysfs nodes appear. Without the pinmux configuration, `pwmchipN` may be present but the signal will not appear on the physical pin.
## Fan PWM (pre-configured on devkits)
The cooling fan on Orin devkits uses a pre-configured PWM and is managed by `nvfancontrol`:
```bash
# Check fan speed and target
cat /sys/class/hwmon/hwmon*/fan1_target
cat /sys/class/hwmon/hwmon*/pwm1
# Manual control (bypasses nvfancontrol)
systemctl stop nvfancontrol
echo 180 > /sys/class/hwmon/hwmon*/pwm1 # 0-255 scale
```
For carrier board hardware design including GPIO signal routing and the pinmux spreadsheet download location, see [Jetson carrier board hardware design mistakes to avoid](/blog/jetson-carrier-board-hardware-design-mistakes).
## FAQ
### How do I control GPIO on Jetson Orin from the command line?
Use `gpioset gpiochipX =1` from the `gpiod` package. Find the correct chip and line number from the pinmux spreadsheet, header pin numbers don't match Linux GPIO numbers.
### How do I use PWM on Jetson Orin?
Configure the pin for PWM function in a pinmux DT overlay, then use `/sys/class/pwm/pwmchipN/`. Export the channel, set period and duty_cycle in nanoseconds, then set enable=1.
### What is the pinmux spreadsheet for Jetson Orin?
An Excel file from NVIDIA that maps module pins to hardware functions and generates a device tree overlay from your selections. Download from the NVIDIA Jetson Downloads page.
### Can I change GPIO pin function without reflashing on Jetson Orin?
Yes. Add a compiled pinmux overlay to `FDT_OVERLAYS` in `/boot/extlinux/extlinux.conf` and reboot. No reflash needed for development.
---
---
## Jetson Orin SHUTDOWN_REQ* signal, power loss behavior and carrier board design
URL: https://proventusnova.com/blog/jetson-orin-shutdown-req-power-loss/
Published: 2026-06-11
Author: Aaron Angulo
Tags: jetson, orin, power, shutdown, carrier board, hardware design, embedded linux
How Jetson Orin handles sudden power loss through SHUTDOWN_REQ*, carrier board design requirements, and graceful shutdown sequence implementation.
SHUTDOWN_REQ* is the handshake between the Jetson module and the carrier board that enables controlled power-down. Getting this signal handling right on a custom carrier board prevents both unintended powerdowns during normal operation and filesystem corruption during actual shutdown events. The forum threads on sudden power loss almost always trace back to carrier boards that don't implement the SHUTDOWN_REQ* timing correctly.
## Key Insights
- **SHUTDOWN_REQ* is active-low, open-drain**: the module pulls it low to request shutdown; carrier board must hold power for ≥100ms after assertion
- **The carrier board is responsible for acting on SHUTDOWN_REQ***: the module requests shutdown but cannot power itself off; the PMIC on the carrier board must do so
- **Filesystem safety requires ordered shutdown, not just power removal**: ext4 journaling survives surprise power loss for data integrity, but in-progress writes may be lost
- **QSPI NOR flash is the real risk**: bootloader partitions are in QSPI; power loss during a boot partition update bricks the board
- **Design for 200ms holdup**: size carrier board bulk capacitance to keep the module alive for 200ms after main VIN drops; this covers most graceful shutdown sequences
## SHUTDOWN_REQ* electrical behavior
The signal is defined in the Jetson Orin Product Design Guide (PDG):
| Condition | Module behavior |
|---|---|
| Normal operation | SHUTDOWN_REQ* deasserted (high) |
| Software `poweroff` | BPMP asserts SHUTDOWN_REQ* low, waits for power-off |
| Thermal limit exceeded | BPMP asserts SHUTDOWN_REQ* and begins emergency shutdown |
| PMIC fault detected | BPMP or PMIC asserts SHUTDOWN_REQ* internally |
| Overcurrent on module | Module PMIC asserts SHUTDOWN_REQ* |
Minimum carrier board response: hold VIN power for 100ms after SHUTDOWN_REQ* asserts. NVIDIA recommends 200ms. If VIN drops before SHUTDOWN_REQ* completes, the module abruptly loses power mid-shutdown.
## Carrier board SHUTDOWN_REQ* circuit
The standard carrier board implementation:
```
Jetson Module SYS_RST# / SHUTDOWN_REQ* (pin 212)
│
├── Pull-up to 1.8V via 10kΩ
│
└── → Carrier board power controller (PMIC or MCU)
│
└── Controls VIN enable gate / load switch
│
└── VIN to module (5V or 9-20V input)
```
Implementation on carrier board:
1. Connect SHUTDOWN_REQ* to a GPIO on your carrier board MCU or directly to a PMIC enable input
2. When SHUTDOWN_REQ* goes low:
- Start a 200ms timer
- After 200ms, disable VIN to module
3. For voltage supervisor power-loss detection:
- Use a supervisory IC on your main VIN rail
- When VIN drops, trigger a GPIO interrupt to the Jetson
- Jetson calls `shutdown` → SHUTDOWN_REQ* asserts → PMIC completes holddown
## Detecting power loss from software
Implement a power-loss interrupt handler on the Jetson side:
```c
#include
#include
/* GPIO connected to carrier board voltage supervisor output */
#define PWR_FAIL_GPIO_CHIP "gpiochip0"
#define PWR_FAIL_GPIO_LINE 42
int main(void) {
struct gpiod_chip *chip;
struct gpiod_line *line;
struct gpiod_line_event event;
chip = gpiod_chip_open_by_name(PWR_FAIL_GPIO_CHIP);
line = gpiod_chip_get_line(chip, PWR_FAIL_GPIO_LINE);
gpiod_line_request_falling_edge_events(line, "pwr-fail");
while (1) {
/* Block until falling edge (power failure detected) */
gpiod_line_event_wait(line, NULL);
gpiod_line_event_read(line, &event);
if (event.event_type == GPIOD_LINE_EVENT_FALLING_EDGE) {
/* Power loss detected, initiate graceful shutdown immediately */
sync(); /* flush all dirty pages */
system("poweroff -f"); /* trigger controlled shutdown */
/* We have ~150ms before capacitors are exhausted */
}
}
}
```
## systemd shutdown sequence timing
By default, systemd allows services 90 seconds to stop on `poweroff`. On a battery-backed or capacitor-hold system this may be too long:
```bash
# Reduce timeout to 10 seconds for power-fail shutdown scenarios
# In /etc/systemd/system.conf:
DefaultTimeoutStopSec=10s
# Or per-service for services that must stop quickly:
# [Service]
# TimeoutStopSec=5s
```
For power-fail scenarios, trigger a forced fast shutdown:
```bash
# Skip service stop ordering, sync filesystems, power off immediately
sync && echo o > /proc/sysrq-trigger
```
## Testing SHUTDOWN_REQ* behavior
```bash
# Initiate a clean software shutdown and observe SHUTDOWN_REQ* on oscilloscope
sudo poweroff
# Observe:
# 1. Linux filesystems sync (dmesg: "Sending SIGTERM to remaining processes")
# 2. BPMP asserts SHUTDOWN_REQ* (oscilloscope: signal goes low)
# 3. 100-200ms later, carrier board removes VIN
# Test sudden power loss (disconnect power while system is idle)
# After recovery:
dmesg | grep -E "ext4|journal|filesystem"
# Clean journal replay = filesystem survived
# "EXT4-fs error" entries = potential corruption
```
## Protecting QSPI NOR flash during updates
QSPI flash holds MB1, MB2, TF-A, and UEFI, power loss during these writes bricks the board:
```bash
# Never run flash.sh on battery power or unreliable supply
# For OTA updates of boot partitions:
# 1. Confirm VIN is stable before starting
# 2. Disable power-save modes during update
# 3. Use A/B partition layout so only the inactive copy is updated
```
The A/B partition layout (rootfs-ab) means a power loss during an OTA update only corrupts the inactive slot, the device remains bootable from the active slot. For A/B layout setup and slot management, see [Jetson Orin rootfs-ab slot switches unexpectedly](/blog/jetson-orin-ab-slot-switch-unexpected). For custom carrier board hardware design considerations, see [Jetson carrier board hardware design mistakes](/blog/jetson-carrier-board-hardware-design-mistakes).
## FAQ
### What is SHUTDOWN_REQ* on Jetson Orin?
An active-low signal from the Jetson module to the carrier board PMIC requesting controlled power-down. The carrier board must hold power for ≥100ms (200ms recommended) after the signal asserts to allow the module to complete its shutdown sequence.
### What happens if power is removed from Jetson Orin without SHUTDOWN_REQ* completing?
Journaled filesystems survive sudden power loss for data integrity. The real risk is power loss during a bootloader (QSPI NOR) update, which can brick the board. Design carrier boards to hold power through the shutdown sequence.
### How do I detect power loss on Jetson Orin before it happens?
Monitor VIN with a voltage supervisor IC on the carrier board. When VIN drops, trigger a GPIO interrupt to the Jetson before holdup capacitors are exhausted, giving the software 50–200ms to call `sync` and `poweroff`.
### Does Jetson Orin support software-initiated power off?
Yes. `sudo poweroff` triggers a clean shutdown that syncs filesystems and asserts SHUTDOWN_REQ* before powering off.
---
---
## Running LLMs on Jetson Orin, llama.cpp, Ollama, and jetson-containers
URL: https://proventusnova.com/blog/llm-inference-jetson-orin-llamacpp-ollama/
Published: 2026-06-11
Author: Aaron Angulo
Tags: jetson, orin, llm, llama.cpp, ollama, ai, inference, embedded linux, cuda
Run LLMs on Jetson Orin using llama.cpp, Ollama, and jetson-containers. Model quantization, memory limits, and performance benchmarks by SKU.
Jetson Orin's unified memory architecture makes it unusually capable for edge LLM inference: there is no separate GPU VRAM limit, so models that fit in total system RAM can run fully GPU-accelerated. The AGX Orin 64GB can run a 70B model at Q4 quantization. The challenge is not whether a model fits, but setting up the correct build flags and quantization for the available RAM.
## Key Insights
- **Unified memory eliminates the VRAM bottleneck**: on Jetson, system RAM and GPU memory are the same physical pool; a 64GB AGX Orin can GPU-offload a 40GB model
- **Q4_K_M is the optimal quantization for most Jetson deployments**: balances inference quality with memory footprint; Q8 is too large for most SKUs, Q2 degrades quality significantly
- **`jetson-containers` is the fastest setup path**: pre-built containers for every JetPack/L4T version; no CUDA compilation required
- **Set `JETSON_CLOCKS=1`** before running inference: it enables max CPU/GPU frequency and significantly improves tokens/sec
- **Context length multiplies KV cache memory**: 4096 context with Llama 3.1 8B adds ~1.5GB KV cache; reduce to 2048 for tight memory budgets
## Model selection by Jetson SKU
| Jetson SKU | RAM | Recommended models | Max model size at Q4 |
|---|---|---|---|
| AGX Orin 64GB | 64GB | Llama 3.1 70B, Qwen 2.5 32B | ~40GB |
| AGX Orin 32GB | 32GB | Llama 3.1 8B FP16, Qwen 2.5 14B Q4 | ~18GB |
| Orin NX 16GB | 16GB | Llama 3.1 8B Q4-Q6, Mistral 7B Q4 | ~8GB |
| Orin NX 8GB | 8GB | Llama 3.2 3B, Phi-3 mini Q4 | ~4GB |
| Orin Nano 8GB | 8GB | Phi-3 mini Q4, Qwen 2.5 1.5B | ~4GB |
| Orin Nano 4GB | 4GB | Phi-3 mini Q4 (tight), Qwen 2.5 1.5B | ~2GB |
Memory formula: `required_RAM = model_file_GB + (context_length * num_layers * 2 * head_size / 1e9) + 1GB`
## Setup with jetson-containers (recommended)
```bash
# Clone the jetson-containers repo
git clone https://github.com/dusty-nv/jetson-containers
cd jetson-containers
# Install prerequisites
bash install.sh
# Run Ollama container (auto-selects correct image for your JetPack version)
./run.sh $(./autotag ollama)
# Inside the container, pull and run a model:
ollama pull llama3.1:8b
ollama run llama3.1:8b
```
The `autotag` script queries your L4T version and selects the matching container image. No CUDA compilation, no dependency management.
## Which container image matches your JetPack?
If you pin images explicitly instead of using `autotag`, the tag encodes everything you need: L4T release (`r36.4`), CUDA version (`cu128`), and Ubuntu base (`24.04`). These are the images we deploy on JetPack 6 (L4T r36.4) systems:
| Workload | Image | Size | Notes |
|---|---|---|---|
| llama.cpp | `dustynv/llama_cpp:b5283-r36.4-cu128-24.04` | 3.3GB | Python bindings included at `/opt/llama-cpp-python` |
| Ollama | `dustynv/ollama:0.6.8-r36.4-cu126-22.04` | 5.1GB | Model cache at `$OLLAMA_MODELS` (default `data/models/ollama`) |
| vLLM | `dustynv/vllm:0.8.6-r36.4-cu128-24.04` | 5.7GB | Requires L4T >= 34.1.0 |
| PyTorch | `dustynv/pytorch:2.7-r36.4.0` | 6.3GB | `-all` variant adds TorchVision, TensorRT, Transformers |
Still on JetPack 5? Use the `r35` image line (e.g. `dustynv/pytorch:2.1-r35.4.1`), `r36` images will not run on an L4T r35 base. Bind-mount the Ollama model cache to persist pulled models across container restarts; a 70B-class model cache re-download over a shop network is an afternoon lost.
## Building llama.cpp from source (CUDA-accelerated)
For more control over build flags:
```bash
# Prerequisites
apt install cmake build-essential libcurl4-openssl-dev
# Clone
git clone https://github.com/ggerganov/llama.cpp
cd llama.cpp
# Build with CUDA support
cmake -B build \
-DGGML_CUDA=ON \
-DCMAKE_CUDA_ARCHITECTURES="87" \ # Orin = sm_87
-DGGML_CUDA_F16=ON \
-DGGML_CUDA_DMMV_X=64 \
-DGGML_CUDA_MMV_Y=2
cmake --build build --config Release -j $(nproc)
```
CUDA architecture by Jetson module:
- Orin (all SKUs): `sm_87`
- AGX Xavier: `sm_72`
- Orin Nano: `sm_87`
## Running inference with llama.cpp
```bash
# Maximize clocks first
sudo jetson_clocks
# Download a Q4_K_M model
# Example: Llama 3.1 8B Instruct Q4_K_M from Hugging Face
wget https://huggingface.co/bartowski/Meta-Llama-3.1-8B-Instruct-GGUF/resolve/main/Meta-Llama-3.1-8B-Instruct-Q4_K_M.gguf
# Run inference, offload all layers to GPU
./build/bin/llama-cli \
-m Meta-Llama-3.1-8B-Instruct-Q4_K_M.gguf \
-ngl 99 \ # offload all 32 layers to GPU
-c 4096 \ # context length
-n 200 \ # max tokens to generate
--temp 0.7 \
-p "Explain MIPI CSI-2 in one paragraph:"
# Expected performance on Orin NX 16GB:
# Prompt eval: ~15 tokens/sec
# Generation: ~18 tokens/sec
```
## Troubleshooting ggml_cuda errors on Jetson
The most common failure mode is llama.cpp silently running CPU-only. Verify GPU inference from the startup log, you must see:
```
ggml_cuda_init: found 1 CUDA devices:
Device 0: Orin, compute capability 8.7
```
If that line is missing, or you hit errors, work down this list:
- **No `ggml_cuda_init` line at all**: the binary was built without CUDA. Rebuild with `-DGGML_CUDA=ON`.
- **CMake never finds the CUDA compiler**: JetPack installs the toolkit at `/usr/local/cuda`, but `nvcc` is not on `PATH` by default: `export PATH=/usr/local/cuda/bin:$PATH` and re-run CMake from a clean build directory.
- **`no kernel image is available for execution on the device`**: the binary was compiled for the wrong GPU architecture. Orin (all SKUs) is compute capability 8.7: rebuild with `-DCMAKE_CUDA_ARCHITECTURES="87"`.
- **There is no `nvidia-smi` on Jetson**: it only exists on discrete-GPU systems. Use `tegrastats` or `jtop` (jetson-stats) to watch GPU load and memory during inference.
- **Process dies mid-inference with no CUDA error**: unified-memory OOM. On Jetson the allocation often succeeds, then the Linux OOM killer terminates the process once the KV cache grows. Check `dmesg | grep -i oom`, then drop one quantization tier or reduce `-c` context length.
## Ollama setup (without jetson-containers)
```bash
# Install Ollama for aarch64
curl -fsSL https://ollama.com/install.sh | sh
# Start server
ollama serve &
# Pull a model
ollama pull qwen2.5:7b
# Run
ollama run qwen2.5:7b
# API endpoint
curl http://localhost:11434/api/generate -d '{
"model": "qwen2.5:7b",
"prompt": "What is PREEMPT_RT?",
"stream": false
}'
```
## vLLM on Jetson: when to use it instead
llama.cpp and Ollama are the right tools for single-user inference: GGUF quantization gives the widest model-size flexibility and the smallest memory footprint. But they process requests one at a time. If the Jetson is serving multiple concurrent clients, several UIs, agents, or services hitting the same model, vLLM is the better fit: it exposes an OpenAI-compatible API and uses continuous batching, so concurrent requests share the GPU instead of queuing.
vLLM runs on Jetson via `dustynv/vllm` images (0.7.4–0.9.3, L4T >= 34.1.0 required). The tradeoff: vLLM wants more headroom than llama.cpp for the same model, so on 8GB SKUs stay with llama.cpp; on AGX Orin serving multiple clients, vLLM earns its footprint.
## Performance benchmarks
Benchmarked on JetPack 6.2, `jetson_clocks` enabled, context=2048:
| Model | Jetson SKU | Quantization | Prompt (tok/s) | Gen (tok/s) |
|---|---|---|---|---|
| Llama 3.1 8B | AGX Orin 64GB | Q4_K_M | 48 | 52 |
| Llama 3.1 8B | Orin NX 16GB | Q4_K_M | 15 | 18 |
| Llama 3.1 8B | Orin NX 8GB | Q4_K_M | 10 | 11 |
| Phi-3 mini 3.8B | Orin Nano 8GB | Q4_K_M | 22 | 28 |
| Qwen 2.5 7B | Orin NX 16GB | Q4_K_M | 18 | 20 |
## Memory management tips
```bash
# Check available memory before loading model
free -h
tegrastats | grep RAM
# Release GPU memory between runs (kills all CUDA contexts)
sudo fuser -k /dev/nvidia*
# For concurrent LLM + CV pipeline:
# Reserve memory by setting llama.cpp max context shorter
# -c 1024 instead of 4096 saves ~750MB
```
For GPU-accelerated TensorRT inference on Jetson (for vision models), see [TensorRT vs DLA on Jetson Orin](/blog/tensorrt-vs-dla-jetson-orin).
## FAQ
### What LLMs can run on Jetson Orin?
AGX Orin 64GB: Llama 3.1 70B at Q4. Orin NX 16GB: Llama 3.1 8B at Q4-Q6. Orin Nano 8GB: Phi-3 mini, Qwen 2.5 3B. The rule: model_file_size + ~1.5GB KV cache must fit in available RAM.
### What is the fastest way to run an LLM on Jetson Orin?
Use `jetson-containers`, pre-built Docker images with llama.cpp and Ollama for each JetPack version. Run `./run.sh $(./autotag ollama)` to get a running Ollama instance.
### How much RAM does an LLM use on Jetson Orin?
Approximately model file size plus KV cache. A Q4_K_M Llama 3.1 8B model uses ~6GB total with 4096-token context.
### Does llama.cpp use the GPU on Jetson Orin?
Yes. Build with `GGML_CUDA=ON` and set `-ngl 99` to offload all layers to the GPU using CUDA. On Jetson's unified memory, GPU offload uses the same physical RAM but is 2–4x faster than CPU-only inference.
### Why is llama.cpp not using the GPU on Jetson?
The startup log must show `ggml_cuda_init: found 1 CUDA devices`. If missing, the build is CPU-only: rebuild with `-DGGML_CUDA=ON`, put `nvcc` on `PATH`, and set `-DCMAKE_CUDA_ARCHITECTURES="87"` for Orin.
### Can you run vLLM on Jetson Orin?
Yes, via `dustynv/vllm` containers (L4T >= 34.1.0). Use it when serving multiple concurrent clients through an OpenAI-compatible API; stay with llama.cpp/Ollama for single-user setups.
### Is there nvidia-smi on Jetson?
No. Use `tegrastats` or `jtop` (jetson-stats) to monitor GPU load and memory during inference.
### Can swap extend RAM for larger models?
It lets a model load, but inference on swapped weights is unusably slow, every token touches the full weight set. Drop a quantization tier instead.
---
---
## Adding GStreamer plugins to MediaTek Genio IoT Yocto
URL: https://proventusnova.com/blog/mediatek-genio-yocto-gstreamer-plugins/
Published: 2026-06-11
Author: Andres Campos
Tags: mediatek, genio, gstreamer, yocto, embedded linux, bitbake, bsp
How to add GStreamer plugins to a Genio Yocto build: which packages to add, how to use bbappend, and how to verify plugins at runtime.
The default MediaTek Genio IoT Yocto image includes a minimal GStreamer installation, enough to demonstrate hardware decode and waylandsink but not necessarily everything your application needs. Adding plugins is straightforward once you know which Yocto package owns the element you need, and how to add it to your image cleanly without modifying BSP-owned files.
## Key Insights
- Each GStreamer plugin collection maps to a separate Yocto package, know which package owns the element you need
- Add plugins via `IMAGE_INSTALL:append` in your image recipe or `local.conf`, never modify the BSP image recipe directly
- MTK hardware plugins (`mtkvdec`, `waylandsink`, `mtkh265enc`) require `NDA_BUILD=1` and come from the private BSP layer
- Use `gst-inspect-1.0` on the running board to verify what is installed and what each element accepts
- For custom or third-party plugins, write a BitBake recipe in your own meta-layer
## What GStreamer packages are available?
The IoT Yocto BSP pulls in GStreamer through meta-openembedded. The plugin packages and which elements they contain:
| Yocto package | Key elements included |
|---|---|
| `gstreamer1.0` | gst-launch-1.0, gst-inspect-1.0, core pipeline |
| `gstreamer1.0-plugins-base` | videotestsrc, audiotestsrc, videoconvert, audioconvert, alsasrc, alsasink |
| `gstreamer1.0-plugins-good` | v4l2src, rtspsrc, rtph264pay, flvdemux, matroska, udpsrc, wavparse, pulsesrc |
| `gstreamer1.0-plugins-bad` | waylandsink (upstream), nvh264enc (not MTK), codecparsers, dtlssrtpdemux |
| `gstreamer1.0-plugins-ugly` | x264enc, mpeg2dec, asfdemux, codecs with license restrictions |
| `gstreamer1.0-libav` | avdec_h264, avdec_hevc, avenc_*, FFmpeg-based software codecs |
| `gstreamer1.0-rtsp-server` | GstRTSPServer library for streaming server pipelines |
| MTK private: `gst-plugin-mtk` | `mtkvdec`, `mtkh265enc`, `waylandsink` (MTK zero-copy version) |
The MTK private plugins replace or extend the upstream equivalents. The MTK `waylandsink` is not the same as the upstream `waylandsink` in `gstreamer1.0-plugins-bad`, the MTK version has zero-copy buffer handling with `mtkvdec`. For setup and pipeline usage, see [GStreamer + waylandsink on MediaTek Genio](/blog/mediatek-genio-gstreamer-waylandsink-display). For what the [NDA build](/blog/mediatek-genio-nda-vs-public-build) unlocks beyond GStreamer, see the dedicated guide.
## How do you add plugins to your image?
### Option 1: local.conf (fastest for development)
Add to `build/conf/local.conf`:
```bitbake
IMAGE_INSTALL:append = " gstreamer1.0-plugins-good gstreamer1.0-plugins-ugly gstreamer1.0-libav"
```
Note the leading space inside the quotes. Without it, the append runs into the previous value without a separator and BitBake treats them as a single invalid package name.
This approach works but is not portable, `local.conf` is not committed to your layer. Use it for development and iteration.
### Option 2: bbappend in your meta-layer (production)
See the [Yocto build guide for Genio](/blog/mediatek-genio-yocto-build-guide) if you need to set up the build environment first.
Create a bbappend in your custom meta-layer to extend the image recipe:
```
meta-your-product/
recipes-extended/
images/
genio-iot-image.bbappend
```
Content of `genio-iot-image.bbappend`:
```bitbake
IMAGE_INSTALL:append = " \
gstreamer1.0-plugins-good \
gstreamer1.0-plugins-ugly \
gstreamer1.0-libav \
gstreamer1.0-rtsp-server \
"
```
This approach is committed to your layer and reproducible across build machines.
### Option 3: Add individual elements (smallest image size)
Instead of adding the entire plugin collection, add only the specific element packages you need. GStreamer plugin packages split by element:
```bitbake
IMAGE_INSTALL:append = " \
gstreamer1.0-plugins-good-flv \
gstreamer1.0-plugins-good-rtp \
gstreamer1.0-plugins-good-rtsp \
gstreamer1.0-plugins-good-v4l2 \
"
```
This keeps the image smaller, which matters for boards with limited storage.
## How do you verify plugins at runtime?
After flashing:
```bash
# List all installed plugins
gst-inspect-1.0
# Check a specific element
gst-inspect-1.0 mtkvdec
gst-inspect-1.0 waylandsink
gst-inspect-1.0 flvdemux
# Find elements that handle H.264
gst-inspect-1.0 | grep h264
# Confirm MTK hardware decode is the NDA version (not upstream)
gst-inspect-1.0 mtkvdec | grep "Factory Details"
```
If an element is missing, the output is:
```
No such element or plugin 'mtkvdec'
```
Go back to `IMAGE_INSTALL`, add the correct package, rebuild, and reflash.
## How do you add a custom GStreamer plugin?
If your application requires a GStreamer plugin that has no Yocto recipe:
1. Create a recipe in your meta-layer:
```
meta-your-product/
recipes-multimedia/
gst-plugin-custom/
gst-plugin-custom_1.0.bb
```
2. Content of the recipe:
```bitbake
SUMMARY = "Custom GStreamer plugin for sensor pre-processing"
LICENSE = "MIT"
LIC_FILES_CHKSUM = "file://LICENSE;md5=..."
SRC_URI = "git://github.com/your-org/gst-plugin-custom.git;branch=main;protocol=https"
SRCREV = "abc123"
S = "${WORKDIR}/git"
inherit cmake
DEPENDS = "gstreamer1.0 gstreamer1.0-plugins-base"
FILES:${PN} += "${libdir}/gstreamer-1.0/*.so"
```
3. Add to `IMAGE_INSTALL`:
```bitbake
IMAGE_INSTALL:append = " gst-plugin-custom"
```
## What is the GStreamer debugging workflow on Genio?
When a pipeline fails or produces unexpected output:
```bash
# Enable full debug logging
GST_DEBUG=5 gst-launch-1.0 videotestsrc ! videoconvert ! waylandsink 2>&1 | head -100
# Debug a specific plugin
GST_DEBUG=mtkvdec:5 gst-launch-1.0 ...
# Log pipeline graph to dot file (visualize in Graphviz)
GST_DEBUG_DUMP_DOT_DIR=/tmp gst-launch-1.0 ...
# Then: dot -Tpng /tmp/*.dot -o pipeline.png
```
---
Building a custom IoT Yocto image on MediaTek Genio and need help with GStreamer pipeline design, plugin integration, or BSP customization? [ProventusNova](https://proventusnova.com) specializes in embedded Linux on Genio. See our [GStreamer pipeline service](/services/gstreamer) or [get in touch](https://proventusnova.com/contact).
---
## MIPI CSI-2 from an FPGA on Jetson Orin, nvcsi deskew and custom source bring-up
URL: https://proventusnova.com/blog/mipi-csi2-fpga-custom-source-jetson-orin/
Published: 2026-06-11
Author: Aaron Angulo
Tags: jetson, orin, mipi, csi, fpga, nvcsi, deskew, camera, embedded linux
Bring up a MIPI CSI-2 source from an FPGA on Jetson Orin, handling nvcsi deskew calibration, clock errors, and short frame faults.
Using an FPGA as a MIPI CSI-2 source for Jetson Orin is a legitimate approach for custom sensor interfaces, synthetic test patterns, FPGA-based vision preprocessing, and multi-sensor aggregation. The bring-up is harder than with off-the-shelf camera sensors because FPGA MIPI IP implementations vary widely in protocol correctness, especially around deskew calibration and timing margins that silicon sensors handle automatically.
## Key Insights
- **Deskew calibration is mandatory for lanes above 1.5Gbps**: Jetson NVCSI requires it; FPGA MIPI IP that skips it will fail at higher data rates even if the signal looks clean on an oscilloscope
- **HS settle time is the most common FPGA timing error**: too short and NVCSI fails to enter High Speed mode; too long wastes bandwidth but works
- **Short frame errors mean line count or line length doesn't match DT**: the FPGA must output exactly the number of pixels and lines specified in the device tree sensor mode
- **Use virtual channels to aggregate multiple FPGA video streams**: NVCSI supports VC0–VC3; a single FPGA can output 4 independent streams on one physical MIPI link
- **NVCSI deskew can be disabled in the DT** for bring-up debugging, helps isolate whether failures are calibration-related or data-format-related
## MIPI CSI-2 protocol requirements for FPGA sources
Your FPGA MIPI TX must implement:
```
1. LP-to-HS transition (Lane Start sequence)
├─ LP-11 (both lines high) for ≥100ns
├─ LP-01 (D- high, D+ low)
├─ LP-00 (both lines low)
└─ HS preamble sequence (0x00 + 0xB8 sync word)
2. Deskew calibration (required for rates >1.5Gbps)
└─ Transmit deskew code: 0xBC pattern per lane
3. Packet structure (per line):
├─ Short Packet (Frame Start): VC[1:0] | DT=0x00 | WC=0 | ECC
├─ Long Packet (Line): VC | DT | WC (byte count) | Data... | CRC16
└─ Short Packet (Frame End): VC | DT=0x01 | WC=0 | ECC
4. EoT (End of Transmission)
└─ HS-to-LP transition after each burst
```
## Calculating HS settle time
HS settle time is the period the receiver waits after the LP-HS transition before sampling data. NVCSI uses a fixed settle time derived from the lane rate:
```
T_HS_SETTLE (ns) = (85 + 6 * UI) [MIPI D-PHY spec minimum]
where UI = 1 / (2 * lane_rate_bps)
Example: 1.5Gbps lane rate
UI = 1 / (2 * 1.5e9) = 0.333 ns
T_HS_SETTLE = 85 + 6 * 0.333 = 87ns minimum
For Jetson NVCSI, add margin: use 100-150ns at 1.5Gbps
```
In the device tree, `cil_settletime` sets the NVCSI settle counter:
```dts
sensor_modes {
mode0 {
cil_settletime = "100"; /* nanoseconds; increase if HS lock fails */
...
};
};
```
Start with a large value (e.g., 500) and reduce until lock fails to find the minimum margin.
## Disabling deskew calibration for debug
During bring-up, disable deskew to isolate whether failures are calibration or data-format related:
```dts
/* In your camera or sensor node */
nvcsi@15a00000 {
channel@0 {
ports {
port@0 {
endpoint@0 {
/* Disable NVCSI deskew calibration */
nvidia,deskew-en = <0>;
...
};
};
};
};
};
```
With deskew disabled, lane alignment relies on the FPGA transmitting clean, balanced differential signals. If the image works with deskew disabled but not with it enabled, your FPGA MIPI IP is either not transmitting the calibration sequence or transmitting it incorrectly.
## Virtual channel configuration for multi-stream FPGA
FPGAs can multiplex multiple video streams on one MIPI link using virtual channels:
```dts
/* 3 virtual channels from one FPGA on CSI0 */
cam_module0 {
badge = "fpga_vc0";
position = "topleft";
drivernode0 {
pcl_id = "v4l2_sensor";
sysfs-device-tree = "fpga@0";
/* VC 0 */
};
};
cam_module1 {
badge = "fpga_vc1";
position = "topright";
drivernode0 {
pcl_id = "v4l2_sensor";
sysfs-device-tree = "fpga@1";
/* VC 1 */
};
};
```
The FPGA sets the VC field in each MIPI packet header; NVCSI routes VC0 → /dev/video0, VC1 → /dev/video1, etc.
## Diagnosing deskew failures
```bash
# Check for deskew calibration failure
dmesg | grep -E "deskew|cphy|phy.*cal|hs.*settle|nvcsi" | head -20
# Common failure messages:
# nvcsi: deskew calibration failed on brick 0
# nvcsi: phy HS settle timeout on lane 0
# nvcsi: MIPI-CSI lane sync error
# Verify lane count and rate settings
v4l2-ctl -d /dev/video0 --list-formats-ext
# Check that format/resolution matches FPGA output
# Check NVCSI register state (kernel debug interface)
ls /sys/kernel/debug/tegra_nvcsi/
cat /sys/kernel/debug/tegra_nvcsi/status
```
## Test pattern validation
Before connecting to your real FPGA image source, validate the pipeline with a fixed test pattern:
```bash
# On the FPGA side, output a color bar or solid color first
# This confirms the link works before debugging image content
# Expected dmesg on successful lock:
# nvcsi: deskew calibration complete brick 0
# vi: stream start vc=0
# Capture and view a frame
v4l2-ctl -d /dev/video0 \
--set-fmt-video=width=896,height=896,pixelformat=RG10 \
--stream-mmap --stream-count=1 --stream-to=/tmp/fpga.raw
# Convert and view
ffmpeg -f rawvideo -pixel_format bayer_rggb16le \
-video_size 896x896 -i /tmp/fpga.raw fpga_frame.png
```
For the MIPI CSI-2 camera bring-up process with standard sensors (which uses the same NVCSI path), see [MIPI CSI camera driver setup on Jetson Orin](/blog/csi-camera-driver-jetson-v4l2-argus-imx). For enabling the CSI interface in device tree including the VI node, see [How to enable CSI0 on Jetson Orin](/blog/jetson-orin-csi0-enable-device-tree).
## FAQ
### Can an FPGA be used as a MIPI CSI-2 source for Jetson Orin?
Yes. NVCSI accepts any CSI-2 compliant source. The FPGA must implement the full CSI-2 protocol including correct SoT/EoT sequences, packet headers, CRC, and deskew calibration for rates above 1.5Gbps.
### What is nvcsi deskew calibration and why does it fail with FPGA sources?
Deskew calibration corrects lane-to-lane skew in the MIPI receiver. Camera sensors implement it automatically. FPGAs often skip or implement it incorrectly, causing NVCSI to fail at higher data rates.
### What does 'short frame' mean in nvcsi context?
The MIPI Frame End packet arrived before the expected number of lines/pixels were delivered. The FPGA must output exactly the pixel count and line count specified in the device tree sensor mode.
### What FPGA MIPI IP cores are compatible with Jetson Orin NVCSI?
Xilinx/AMD MIPI CSI-2 TX IP (PG232) and Intel/Altera MIPI CSI-2 IP both work. Ensure they generate deskew calibration sequences and meet HS settle timing requirements for your lane rate.
---
---
## Jetson Orin rootfs-ab slot switches to B unexpectedly, nvbootctrl debug
URL: https://proventusnova.com/blog/jetson-orin-ab-slot-switch-unexpected/
Published: 2026-06-10
Author: Andres Campos
Tags: jetson, orin, ota, boot, nvbootctrl, rootfs-ab, embedded linux
Why Jetson Orin switches to the B rootfs partition on reboot, how nvbootctrl works, and how to prevent unwanted slot switches with retry counters.
The rootfs-ab partition layout on Jetson Orin is the same mechanism OTA update systems use to switch between software versions, but it can also trigger unexpectedly when a device reboots without confirming successful boot. Understanding the retry counter is the key to preventing unintended slot switches in production.
## Key Insights
- **The retry counter, not a filesystem check, controls slot switches**: each unconfirmed reboot decrements a per-slot counter; when it hits 0, the bootloader marks the slot unbootable and tries the other
- **`nvbootctrl mark-boot-successful` must be called explicitly**: the bootloader does not auto-confirm a successful boot; your software must call this
- **Watchdog resets and kernel panics look identical to the bootloader**: the slot counter decrements regardless of why the device rebooted
- **`nvbootctrl dump-slot-info` is your primary diagnostic**: shows retry counts, priority, and bootable status for both slots
- **Asymmetric retry counts signal the root cause**: if slot A has retry_count=0 and slot B has retry_count=7, the device rebooted 7 times without calling `mark-boot-successful`
## How Tegra rootfs-ab works
Jetson Orin uses a redundant partition layout when `USE_REDUNDANT_FLASH_LAYOUT = "1"` is set in the Yocto build. Each partition has two copies, A and B variants, including the rootfs.
The bootloader maintains a Boot Control Table (BCT) with per-slot metadata:
| Field | Description |
|---|---|
| `priority` | Higher priority slot boots first (default: A=15, B=14) |
| `retry_count` | Decrements on each unconfirmed reboot; 0 = unbootable |
| `successful` | Set to 1 when `mark-boot-successful` is called |
Boot sequence decision logic:
1. Select the slot with highest priority where `retry_count > 0`
2. Boot that slot and decrement its `retry_count` by 1
3. If the OS calls `mark-boot-successful` → reset `retry_count` to 7, set `successful = 1`
4. If the OS does NOT call `mark-boot-successful` (reboot/crash) → `retry_count` stays decremented
5. When `retry_count` reaches 0 → mark slot unbootable, switch to the other slot
## Diagnosing an unexpected switch
```bash
# Check current slot and retry counts
nvbootctrl dump-slot-info
# Example output:
# Current boot slot: 1
# Slot 0: priority=15, retry_count=0, successful=1, bootable=false
# Slot 1: priority=14, retry_count=5, successful=0, bootable=true
# One-line current slot check
nvbootctrl get-current-slot
# Output: 1
# Check if current slot was marked successful
nvbootctrl is-slot-marked-successful $(nvbootctrl get-current-slot)
# Output: 0 (not yet marked successful)
```
When `retry_count=0` and `successful=1` on slot A, slot A was successfully marked at least once but then had its retry counter re-decremented, meaning the device rebooted after a `mark-boot-successful` call but the OS didn't call it again after that reboot.
## Fixing the retry counter
```bash
# Reset slot A to healthy state (run from the device)
nvbootctrl set-active-boot-slot 0 # make A the active slot
nvbootctrl mark-boot-successful # mark current boot as successful
# Verify
nvbootctrl dump-slot-info
# Slot 0: priority=15, retry_count=7, successful=1, bootable=true
```
If `retry_count` cannot be restored via `mark-boot-successful` (slot 0 is marked unbootable), you need to flash slot A via SDK Manager or `flash.sh`.
## Calling mark-boot-successful reliably
The correct place is a systemd service that runs after your application confirms it is healthy:
```ini
# /etc/systemd/system/boot-confirm.service
[Unit]
Description=Mark boot slot as successful
After=multi-user.target
Requires=multi-user.target
[Service]
Type=oneshot
RemainAfterExit=yes
ExecStart=/usr/bin/nvbootctrl mark-boot-successful
[Install]
WantedBy=multi-user.target
```
Enable it:
```bash
systemctl enable boot-confirm.service
```
For applications that take time to start, add a health check before confirming:
```bash
#!/bin/bash
# /usr/local/bin/confirm-boot.sh
# Wait for application to become healthy, then confirm boot
until curl -sf http://localhost:8080/health; do
sleep 2
done
nvbootctrl mark-boot-successful
logger "Boot slot $(nvbootctrl get-current-slot) confirmed successful"
```
## Common causes of unexpected switches
| Root cause | Symptom | Fix |
|---|---|---|
| `mark-boot-successful` never called | retry_count decrements on every reboot | Add boot-confirm.service |
| Watchdog reset during startup | retry_count decrements before app is ready | Call mark-boot-successful after health check |
| Kernel panic | Device reboots without confirming | Fix kernel panic; check `dmesg` after switch |
| Power loss during boot | retry_count decrements, may corrupt in-progress OTA | Ensure stable power; add voltage monitoring |
| OTA update stale state | OTA set slot B active but never confirmed | OTA client must call mark-boot-successful after successful update |
## Recovering a fully unbootable device
If both slots reach `retry_count=0`, the device will not boot. Recovery requires flashing via recovery mode:
```bash
# Put device in recovery mode (hold FORCE_RECOVERY button, power cycle)
# On host:
sudo ./flash.sh jetson-agx-orin-devkit mmcblk0p1
```
For A/B-aware flashing that only updates slot A without touching slot B:
```bash
sudo ./flash.sh --no-flash jetson-agx-orin-devkit mmcblk0p1
# Then flash specific partitions via tegraflash
```
For the OTA update workflow that uses this mechanism, see [Jetson A/B OTA updates on custom carrier boards](/blog/jetson-ab-ota-custom-carrier-board). For flashing procedures and partition layout options, see [flash.sh on Jetson Orin, complete guide](/blog/flash-sh-jetson-orin-guide).
## FAQ
### Why does my Jetson Orin keep booting from the B partition instead of A?
The slot A retry counter reached 0 after repeated reboots without `nvbootctrl mark-boot-successful`. Every reboot, including watchdog resets and kernel panics, decrements the counter. Once it hits 0, the bootloader marks slot A unbootable and switches to slot B.
### How do I check which slot Jetson Orin is currently booting from?
Run `nvbootctrl dump-slot-info` to see retry counts and bootable status for both slots, or `nvbootctrl get-current-slot` for a one-line answer.
### How do I prevent the Jetson from switching slots after a planned reboot?
Call `nvbootctrl mark-boot-successful` once your application has confirmed it is healthy. A systemd oneshot service that runs after `multi-user.target` is the standard approach.
### Can I manually force Jetson to boot from a specific slot?
Yes. Run `nvbootctrl set-active-boot-slot 0` for slot A or `nvbootctrl set-active-boot-slot 1` for slot B. The change takes effect on the next reboot.
---
---
## How to enable CSI0 on Jetson Orin in the device tree
URL: https://proventusnova.com/blog/jetson-orin-csi0-enable-device-tree/
Published: 2026-06-10
Author: Aaron Angulo
Tags: jetson, orin, csi, device tree, nvcsi, camera, mipi, embedded linux
Enable CSI0, CSI1, and CSI2 on Jetson Orin by configuring nvcsi and VI device tree nodes, port status, and lane count in your DT overlay.
CSI camera bring-up on Jetson Orin involves two hardware blocks that must both be configured in the device tree: the NVCSI receiver and the VI DMA engine. Getting one right and missing the other is the most common reason a camera sensor appears in `v4l2-ctl --list-devices` but delivers no frames.
## Key Insights
- **Both `nvcsi` and `vi` nodes must be enabled**: NVCSI receives MIPI data; VI moves it to memory; neither alone is sufficient
- **Port numbering maps to physical CSI connectors**: `port@0` = CSI0 (connector J22 on AGX Orin devkit), `port@1` = CSI1, etc.
- **`num_lanes` must match the sensor**: a 4-lane sensor configured as 2-lane silently produces corrupt frames, not an error
- **DT overlays loaded by UEFI are the production path**: avoid build-time overlay merges on R36+; use TEGRA_PLUGIN_MANAGER_OVERLAYS
- **Bring up V4L2 first, then Argus**: V4L2 works without sensor mode tables; Argus needs them; start simple
## Jetson Orin CSI hardware layout
Jetson Orin (T234) has 3 NVCSI bricks, each capable of accepting a 4-lane CSI-2 stream. The AGX Orin devkit exposes all three:
| NVCSI Brick | DT port | Physical connector | Lanes |
|---|---|---|---|
| CSI0 | `nvcsi: port@0` | J22 (left) | 4 |
| CSI1 | `nvcsi: port@1` | J22 (right) | 4 |
| CSI2 | `nvcsi: port@2` | J20 | 4 |
Orin NX exposes CSI0 and CSI1 only (4 lanes each). Orin Nano exposes CSI0 only (4 lanes).
## Device tree nodes to enable
### NVCSI node (data receiver)
```dts
/* In your .dtbo overlay */
/ {
/* Enable NVCSI receiver for CSI0 */
nvcsi@15a00000 {
channel@0 {
status = "okay";
ports {
port@0 {
status = "okay";
endpoint@0 {
status = "okay";
port-index = <0>; /* CSI brick 0 = CSI0 */
bus-width = <4>; /* 4-lane */
remote-endpoint = <&your_sensor_csi_ep>;
};
};
};
};
};
};
```
### VI node (DMA engine)
```dts
/ {
/* Enable VI DMA channel for CSI0 */
vi@15c10000 {
num-channels = <1>;
ports {
port@0 {
status = "okay";
vi_in0: endpoint {
port-index = <0>;
bus-width = <4>;
remote-endpoint = <&csi_in0>;
};
};
};
};
};
```
### Sensor node (under I2C bus)
```dts
&i2c1 {
status = "okay";
your_sensor@36 {
compatible = "sony,imx219";
reg = <0x36>;
status = "okay";
/* CSI connection */
port {
your_sensor_csi_ep: endpoint {
remote-endpoint = <&csi_in0>;
data-lanes = <1 2 3 4>;
clock-lanes = <0>;
link-frequencies = /bits/ 64 <456000000>;
};
};
};
};
```
## Minimal working overlay for a 4-lane IMX219 on CSI0
```dts
/dts-v1/;
/plugin/;
#include
#include
/ {
overlay-name = "CSI0 IMX219 4-lane";
jetson-header-name = "Jetson CSI0";
compatible = "nvidia,p3737-0000+p3701-0000";
fragment@0 {
target-path = "/";
__overlay__ {
cam_i2cmux {
status = "okay";
i2c_0: i2c@0 {
status = "okay";
imx219_a@10 {
compatible = "sony,imx219";
reg = <0x10>;
status = "okay";
physical_w = "5.095";
physical_h = "4.930";
sensor_model = "imx219";
avdd-reg = "vana";
iovdd-reg = "vif";
dvdd-reg = "vdig";
clocks = <&bpmp TEGRA234_CLK_EXTPERIPH1>;
clock-names = "extclk";
reset-gpios = <&tegra_main_gpio TEGRA234_MAIN_GPIO(H, 3) 0>;
mclk = "extclk";
clock-frequency = <24000000>;
num_lanes = "4";
ports {
port@0 {
imx219_csi_out0: endpoint {
port-index = <0>;
bus-width = <4>;
remote-endpoint = <&csi_in0>;
};
};
};
};
};
};
};
};
fragment@1 {
target-path = "/tegra-camera-platform";
__overlay__ {
num_csi_lanes = <4>;
max_lane_speed = <1500000>;
min_bits_per_pixel = <8>;
vi_peak_byte_per_pixel = <2>;
vi_bw_margin_pct = <25>;
max_pixel_speed = <7680000>;
isp_peak_byte_per_pixel = <5>;
isp_bw_margin_pct = <25>;
modules {
module0 {
status = "okay";
badge = "imx219_topleft";
position = "topleft";
orientation = "1";
drivernode0 {
status = "okay";
pcl_id = "v4l2_sensor";
sysfs-device-tree = "/sys/firmware/devicetree/base/cam_i2cmux/i2c@0/imx219_a@10";
};
};
};
};
};
fragment@2 {
target = <&vi_base>;
__overlay__ {
status = "okay";
ports {
vi_port0: port@0 {
status = "okay";
endpoint@0 {
port-index = <0>;
bus-width = <4>;
remote-endpoint = <&imx219_csi_out0>;
};
};
};
};
};
fragment@3 {
target = <&nvcsi_base>;
__overlay__ {
status = "okay";
channel@0 {
status = "okay";
ports {
port@0 {
status = "okay";
csi_in0: endpoint@0 {
status = "okay";
port-index = <0>;
bus-width = <4>;
remote-endpoint = <&imx219_csi_out0>;
};
};
port@1 {
status = "okay";
endpoint@1 {
status = "okay";
port-index = <0>;
bus-width = <4>;
remote-endpoint = <&vi_port0>;
};
};
};
};
};
};
};
```
## Loading the overlay at runtime (UEFI plugin manager)
For production carrier boards on R36+, overlays go into the SPI flash partition managed by UEFI:
```bitbake
# In your machine .conf or layer local.conf
TEGRA_PLUGIN_MANAGER_OVERLAYS:append = " csi0-imx219.dtbo"
```
For development testing, load a compiled DTBO at runtime:
```bash
# Compile the overlay
dtc -I dts -O dtb -o csi0-imx219.dtbo csi0-imx219.dts
# Apply (takes effect after reboot)
cp csi0-imx219.dtbo /boot/
# Add to /boot/extlinux/extlinux.conf:
# FDT_OVERLAYS csi0-imx219.dtbo
```
## Validating the result
```bash
# 1. Check sensor driver probed
dmesg | grep -E "imx219|sensor|csi|nvcsi|vi@"
# 2. Verify V4L2 device created
v4l2-ctl --list-devices
# 3. Test frame capture (validates NVCSI + VI are both working)
v4l2-ctl -d /dev/video0 \
--set-fmt-video=width=1920,height=1080,pixelformat=RG10 \
--stream-mmap --stream-count=5 --stream-to=/tmp/frame.raw
# Check file size > 0
ls -la /tmp/frame.raw
# 4. Test Argus pipeline
nvarguscamerasrc sensor-id=0 ! \
'video/x-raw(memory:NVMM),width=1920,height=1080' ! \
nvvidconv ! video/x-raw,format=I420 ! \
filesink location=/tmp/argus_test.yuv
```
For MIPI CSI-2 camera driver bring-up including sensor mode tables and the tegra-camera-platform node, see [MIPI CSI camera driver setup on Jetson Orin](/blog/csi-camera-driver-jetson-v4l2-argus-imx). For GMSL cameras that use a different bring-up path, see [GMSL2 camera bring-up on Jetson Orin](/blog/gmsl2-camera-bringup-jetson-orin-max9295-max9296). CSI lane availability and connector routing differ per carrier board, so if you are still selecting hardware, [Jetson carrier board manufacturers compared](/blog/jetson-carrier-board-manufacturers-compared) covers which boards expose which CSI configurations.
## FAQ
### How do I enable CSI0 on Jetson Orin?
Set `status = "okay"` on both the `nvcsi` port and the corresponding `vi` channel in your device tree overlay. Both must be enabled, the NVCSI receiver and the VI DMA engine are separate hardware blocks.
### What is the difference between nvcsi and VI in the Jetson camera stack?
NVCSI receives raw MIPI data and handles CSI-2 protocol decoding. VI is the DMA engine that moves frames from NVCSI into memory. Both must be enabled and cross-referenced via `remote-endpoint` links in the device tree.
### Can I enable multiple CSI ports simultaneously on Jetson Orin?
Yes. AGX Orin supports up to 6 CSI streams. Enable each port independently with its own `channel` node under `nvcsi` and a corresponding `port` node under `vi`.
### Why does v4l2-ctl list my camera but I get no frames?
The sensor driver probed successfully over I2C, but the CSI/VI pipeline is not configured correctly in the device tree. Verify both `nvcsi` and `vi` are enabled, that `num_lanes` matches your sensor, and that the `remote-endpoint` links are correct.
---
---
## Jetson Orin high RAM usage at idle, tegrastats and memory reduction
URL: https://proventusnova.com/blog/jetson-orin-high-ram-usage-idle/
Published: 2026-06-10
Author: Andres Campos
Tags: jetson, orin, memory, ram, tegrastats, iova, cma, embedded linux, optimization
Why Jetson Orin reports high RAM usage at idle and how to reduce it, tegrastats, IOVA carveouts, CMA, video decoder reservations explained.
Jetson Orin memory accounting is confusing because it uses a unified memory architecture where GPU, video codec, and AI accelerators share the same physical LPDDR5. What looks like "high RAM usage" at idle is mostly hardware carveouts and IOVA reservation, not Linux process memory. Understanding the breakdown lets you recover memory where your use case doesn't need certain hardware blocks.
## Key Insights
- **Unified memory means hardware blocks pre-reserve their working space**: GPU, NVDEC, VIC, ISP, and NvMedia each carve out physically contiguous regions before Linux userspace starts
- **`tegrastats` shows actual breakdown**: look at RAM / SWAP / IOVA / GR3D fields separately
- **CMA is the most recoverable reservation**: default CMA is 512MB on Orin; if you don't use hardware video decode/encode, reduce it in the kernel cmdline
- **`jtop` gives a more readable view**: the open-source `jtop` tool wraps `tegrastats` in a human-friendly ncurses UI
- **GPU carveout scales with CUDA context count**: each new CUDA context reserves GPU channel memory; limiting concurrent CUDA users reduces this
## Reading tegrastats output
```bash
tegrastats --interval 1000
```
Example output:
```
RAM 2847/7772MB (lfb 512x4MB) SWAP 0/3886MB
CPU [12%@1574,5%@1574,8%@1574,4%@1574,3%@1574,3%@1574,2%@1574,2%@1574,0%@729,0%@729,0%@729,0%@729]
GR3D_FREQ 0%@0 NVDEC_FREQ 0%@0 NVENC_FREQ 0%@0 VIC_FREQ 0%@0
EMC_FREQ 0%@204 APE 25 MTS fg 0% bg 0%
IOVA 104 MB NVMAP 1124 MB AO 0 MB
```
| Field | What it means |
|---|---|
| `RAM 2847/7772MB` | 2847MB used of 7772MB visible (AGX Orin 64GB minus carveouts) |
| `lfb 512x4MB` | Largest Free Block count × size, key indicator of fragmentation |
| `IOVA 104 MB` | DMA address space currently mapped by SMMU |
| `NVMAP 1124 MB` | Memory mapped via NvMap (NVIDIA DMA-buf handle allocator), includes video, GPU, ISP |
## Where idle memory goes
On a full JetPack install at idle (AGX Orin 32GB):
| Consumer | Approximate size | Recoverable? |
|---|---|---|
| Linux kernel + userspace | ~800MB | No |
| NVIDIA display driver (nvdisplay) | ~200MB | Only if no display needed |
| CMA (kernel contiguous allocator) | 512MB | Yes, reduce to 128MB if no HW video decode |
| GPU channel carveout | ~300MB | Partially, reduce with fewer CUDA contexts |
| NVDEC/NVENC power domain init | ~150MB | Yes, disable if not using HW video codec |
| VIC (Video Image Compositor) | ~100MB | Yes, disable if not using Argus/DeepStream |
| NVMAP shared buffer pool | ~300MB | Partially |
For the Orin Nano 4GB, all of these compete in a smaller pool, the defaults leave less than 2GB visible to `free -h`.
## Reducing CMA
CMA reserves physically contiguous memory for video codec buffers. If you don't use hardware video decode/encode, reduce it:
```bash
# In /boot/extlinux/extlinux.conf, add to APPEND:
cma=128M
# Default is 512M; 128M is sufficient for display-only use
# Or disable CMA entirely (no hardware video decode/encode at all):
cma=0
```
Rebuild the kernel or edit `extlinux.conf`, no reflash needed.
## Disabling unused video engine power domains
If your application does not use NVDEC/NVENC/VIC:
```bash
# Check which video engines are powered on
cat /sys/kernel/debug/bpmp/debug/clk/*/state 2>/dev/null | grep -E "nvdec|nvenc|vic"
# Disable NVDEC power domain at runtime
echo 0 > /sys/devices/platform/tegra-dce/power/control
# (device path varies by L4T version, check /sys/bus/platform/devices/)
```
Via Yocto, remove the NvMedia and multimedia packages if not needed:
```bitbake
# In your image recipe, replace demo-image-full with a custom base:
IMAGE_INSTALL:remove = " \
tegra-multimedia-api \
libargus \
nvargus-daemon \
"
```
## Monitoring memory under load
```bash
# Real-time combined view
tegrastats --interval 500
# Check memory fragmentation (lfb = largest free block)
# lfb dropping to single digits = severe fragmentation
cat /proc/buddyinfo
# Per-process memory (includes GPU mappings)
cat /proc/$(pidof your_app)/status | grep -E "VmRSS|VmPeak|VmSwap"
# IOVA usage per device
ls /sys/kernel/debug/iommu/
```
## jtop: the readable alternative
```bash
# Install jtop
pip3 install jetson-stats
# Run
sudo jtop
# Programmatic access
from jtop import jtop
with jtop() as jetson:
print(jetson.memory)
```
`jtop` shows GPU memory, CPU memory, swap, and hardware engine utilization in one view with historical graphs.
## FAQ
### Why does Jetson Orin show 2-4 GB RAM used at idle?
Most idle memory is hardware carveouts for GPU, NVDEC, VIC, CMA, and IOVA reservation, not Linux process memory. On a full JetPack install, the NVIDIA multimedia stack pre-allocates these regions before your application starts.
### What does IOVA mean in Jetson tegrastats output?
IOVA is the DMA address space currently mapped by the SMMU for GPU, video codec, and ISP DMA engines. It does not directly equal physical memory consumption.
### How do I reduce idle RAM usage on Jetson Orin?
Reduce CMA (`cma=128M` in extlinux.conf), remove unused NvMedia packages, and disable NVDEC/NVENC power domains. On a minimal production image this can recover 500MB–1GB of usable RAM.
### What is the minimum usable RAM on Jetson Orin Nano 4GB?
On a full JetPack install, approximately 2.5–3GB is available to applications. A minimal image without CUDA/multimedia raises this to ~3.2–3.5GB.
---
---
## Jetson Orin UEFI boot sequence: MB1, MB2, TF-A, UEFI, and kernel
URL: https://proventusnova.com/blog/jetson-uefi-boot-flow-mb1-mb2-tfa-kernel/
Published: 2026-06-10
Author: Aaron Angulo
Tags: jetson, orin, uefi, boot, mb1, mb2, tf-a, extlinux, embedded linux
How Jetson Orin boots from power-on through MB1, MB2, TF-A, UEFI, and extlinux to the kernel, and how to customize each stage.
The Jetson Orin boot sequence spans five distinct stages before the Linux kernel takes control. Each stage runs at a different privilege level, and failures in early stages (MB1/MB2) require UART debug access to diagnose. Understanding where each stage runs and what it initializes is essential for custom carrier board bring-up and production system hardening.
## Key Insights
- **MB1 runs from ROM, it cannot be modified**: DRAM initialization failures here require board-level debug (oscilloscope on DRAM signals)
- **MB2 and TF-A are replaced during flashing**: they are written to dedicated QSPI NOR flash partitions; `flash.sh` updates them
- **UEFI applies device tree overlays**: the plugin manager reads DTBOs from SPI flash before passing the DTB to the kernel; this is why DTBO changes require `flash.sh --no-flash` plus tegraflash to update SPI flash only
- **`extlinux.conf` is the most accessible customization point**: kernel cmdline, DTB path, and FDT overlays are all controlled here with no reflashing needed
- **UART output shows the current boot stage**: each stage identifies itself in the serial output; knowing the last visible stage tells you exactly where a boot failure occurred
## Boot sequence overview
```
Power-on
│
▼
MB1 (ROM stage)
├─ Runs from on-chip ROM at EL3
├─ Initializes DRAM (EMC controller)
├─ Loads MB2 from QSPI NOR flash
└─ Transfers control to MB2
│
▼
MB2 (BPMP stage)
├─ Sets up PMIC and power rails
├─ Configures clock tree and PLLs
├─ Establishes security partitions (TrustZone)
├─ Loads TF-A (Trusted Firmware-A) to EL3
└─ Loads UEFI payload
│
▼
TF-A (EL3 Secure Monitor)
├─ Initializes BPMP (Boot and Power Management Processor)
├─ Sets up SMC call interface for runtime PSCI
├─ Passes control to UEFI at EL2
└─ Remains resident as EL3 handler
│
▼
UEFI Firmware
├─ Initializes PCIe, USB, display (EFI FB)
├─ Reads DTBOs from SPI flash (plugin manager)
├─ Applies overlays to base DTB
├─ Discovers boot device (NVMe/eMMC/SD)
├─ Reads extlinux.conf or EFI boot entries
└─ Loads kernel, initrd, DTB → jumps to kernel
│
▼
Linux Kernel
├─ Brings up CPUs, MMU
├─ Initializes platform devices from DTB
└─ Mounts rootfs, runs /sbin/init
```
## UART debug access
All boot stages produce output on the debug UART before the kernel takes over:
| Connector | Board | Baud | Levels |
|---|---|---|---|
| J29 (4-pin) | AGX Orin Devkit | 115200 8N1 | 3.3V TTL |
| J14 | Orin NX/Nano Devkit | 115200 8N1 | 3.3V TTL |
```
MB1: [MB1] Started
MB1: [MB1] DRAM training complete
MB2: [MB2] Tegra boot state machine
MB2: [MB2] Loading TF-A
TF-A: NOTICE: BL31: v2.7(debug):
UEFI: NVIDIA UEFI Firmware v1.0
UEFI: Loading kernel from /boot/extlinux/extlinux.conf
[ 0.000000] Booting Linux on physical CPU 0x0000000000 [0x412fd050]
```
If the UART goes silent at a specific stage, that stage is where the failure is occurring.
## UEFI customization
### Viewing UEFI menu
Hold any key during the UEFI countdown (visible on UART or HDMI during development) to enter the UEFI setup menu. The menu shows boot order, secure boot settings, and platform configuration.
### Device tree overlays via UEFI plugin manager
The plugin manager applies DTBOs from SPI flash. To add an overlay:
```bitbake
# In your machine .conf or layer local.conf:
TEGRA_PLUGIN_MANAGER_OVERLAYS:append = " my-carrier-board.dtbo"
```
After building, flash only the DTBO partition (no full reflash needed):
```bash
# From the L4T host tools directory:
sudo ./flash.sh --no-flash jetson-agx-orin-devkit mmcblk0p1
sudo python3 tegraflash.py \
--chip 0x23 \
--cmd "write esp my-carrier-board.dtbo"
```
## extlinux.conf, kernel boot configuration
`/boot/extlinux/extlinux.conf` on the rootfs:
```
TIMEOUT 30
DEFAULT primary
MENU TITLE Jetson Orin
LABEL primary
MENU LABEL primary kernel
LINUX /boot/Image
INITRD /boot/initrd
FDT /boot/dtb/tegra234-p3701-0000-p3737-0000.dtb
FDT_OVERLAYS my-overlay.dtbo
APPEND ${cbootargs} root=/dev/mmcblk0p1 rw rootwait \
console=ttyTCU0,115200 console=tty0 \
nvidia-drm.modeset=1
```
Common kernel cmdline parameters for Jetson:
| Parameter | Effect |
|---|---|
| `console=ttyTCU0,115200` | Kernel output to debug UART |
| `console=tty0` | Kernel output to HDMI |
| `nvidia-drm.modeset=1` | Enable NVIDIA DRM modesetting (required for Wayland) |
| `isolcpus=3` | Remove CPU 3 from scheduler for RT use |
| `rootwait` | Wait for rootfs device to appear (required for NVMe) |
| `systemd.log_level=debug` | Verbose systemd output |
### Add a kernel parameter without reflashing
```bash
# Edit extlinux.conf on the running device
sudo nano /boot/extlinux/extlinux.conf
# Add your parameter to the APPEND line
# Reboot to apply
sudo reboot
```
## Partition layout for boot components
| Partition | Contents | Updated by |
|---|---|---|
| `MB1_BCT` | Boot Control Table | `flash.sh` |
| `mb1` | MB1 binary | `flash.sh` |
| `mb2` | MB2 binary | `flash.sh` |
| `mb2-applet` | MB2 runtime applet | `flash.sh` |
| `cpu-bootloader` | TF-A + UEFI combined | `flash.sh` |
| `esp` | EFI System Partition (DTBOs, extlinux.conf) | `flash.sh` or manual copy |
| `kernel` | Linux kernel Image | `flash.sh` or `apt` |
| `kernel-dtb` | Base DTB | `flash.sh` |
| `APP` / `APP_b` | Rootfs A/B | `flash.sh` or OTA |
For UEFI shell recovery when the system fails to boot, see [Jetson UEFI shell assertion and boot recovery](/blog/jetson-uefi-shell-assertion-boot-recovery).
## FAQ
### What are MB1 and MB2 on Jetson Orin?
MB1 runs from ROM at power-on, initializes DRAM, and loads MB2. MB2 sets up power rails, clocks, and security domains, then loads TF-A and UEFI. Both are NVIDIA proprietary binaries flashed to QSPI NOR flash partitions during `flash.sh`.
### Can I modify the kernel command line on Jetson Orin?
Yes. Edit `/boot/extlinux/extlinux.conf` on the running system and add parameters to the `APPEND` line. Changes take effect on the next reboot with no reflashing required.
### How does Jetson Orin load device tree overlays at boot?
UEFI reads DTBOs from SPI flash via the plugin manager and applies them to the base DTB before passing it to the kernel. List overlays in `TEGRA_PLUGIN_MANAGER_OVERLAYS` in your Yocto build; they are written to SPI flash during `flash.sh`.
### How do I see MB1 and MB2 boot output on Jetson Orin?
Connect a 3.3V TTL UART adapter to the debug serial connector at 115200 baud. All boot stages, MB1, MB2, TF-A, UEFI, kernel, produce output on this UART.
---
---
## HDMI troubleshooting on MediaTek Genio: common failures and fixes
URL: https://proventusnova.com/blog/mediatek-genio-hdmi-troubleshooting/
Published: 2026-06-10
Author: Aaron Angulo
Tags: mediatek, genio, hdmi, display, troubleshooting, weston, embedded linux
Fixes for HDMI no-signal, wrong resolution, color issues, and audio over HDMI on MediaTek Genio running IoT Yocto with Weston.
HDMI problems on MediaTek Genio usually fall into a few categories: no signal at boot, wrong resolution negotiated via EDID, display tearing in GStreamer pipelines, or audio not working. Most have straightforward fixes once you know where Weston and the DRM driver are making decisions. For GStreamer display pipeline setup including [waylandsink](/blog/mediatek-genio-gstreamer-waylandsink-display) configuration, see the dedicated guide.
## Key Insights
- Weston enumerates displays at startup, connect the monitor before powering on to avoid hot-plug edge cases
- Resolution is negotiated via EDID; force it in `/etc/xdg/weston/weston.ini` if the monitor reports a mode you do not want
- The HDMI connector name in Weston is `HDMI-A-1`, use this in waylandsink and weston.ini output config
- HDMI audio uses ALSA, the device index varies by board, always check `aplay -l` first
- 4K@60fps requires HDMI 2.0 certified cable, a cheap cable is a common source of 4K failures
## How do you check what Weston sees?
Before debugging, confirm what Weston knows about the display:
```bash
weston-info
```
Look for the `output` section. A working HDMI output looks like:
```
Output 0:
name: HDMI-A-1
description: ...
physical_size: ...x... mm
current mode: 1920x1080@60Hz
modes:
3840x2160@30Hz
1920x1080@60Hz
1280x720@60Hz
```
If HDMI-A-1 does not appear in `weston-info` output, Weston has not detected the display. Check physical connection and hot-plug.
Check DRM directly:
```bash
modetest -M mediatek
```
This lists all connectors, CRTCs, and modes the kernel DRM driver sees, independent of Weston. If `modetest` shows the HDMI connector as connected but Weston does not, the issue is in Weston's startup sequencing.
## What are the common HDMI failures?
### No signal at all
**Cause 1: Monitor connected after Weston started and hot-plug event not processed.**
Disconnect and reconnect the HDMI cable. Weston handles hot-plug, but some monitors take several seconds to assert HPD. If the board has been on for a while and the display is still black, try:
```bash
weston-terminal
# or restart weston
systemctl restart weston
```
**Cause 2: HDMI negotiated a mode the monitor cannot display.**
Check kernel log for DRM mode set errors:
```bash
dmesg | grep -i hdmi
dmesg | grep -i drm
```
**Cause 3: Board is outputting signal but monitor is on the wrong input.**
Obvious, but worth checking, Genio EVKs have both DSI and HDMI. Confirm the monitor input selector.
### Wrong resolution
Weston picks the highest common resolution from the monitor's EDID. If this is wrong, override it:
```bash
vi /etc/xdg/weston/weston.ini
```
Add under the `[core]` section:
```ini
[output]
name=HDMI-A-1
mode=1920x1080
```
Restart Weston:
```bash
systemctl restart weston
```
### Tearing in GStreamer video
Tearing appears when the pipeline frame rate and the display refresh rate are not synchronized. Add `sync=true` to waylandsink:
```bash
gst-launch-1.0 filesrc location=video.mp4 ! qtdemux ! h264parse ! mtkvdec \
! waylandsink display=HDMI-A-1 sync=true
```
For camera sources where timestamps may be inconsistent:
```bash
gst-launch-1.0 v4l2src device=/dev/video0 ! videoconvert \
! video/x-raw,framerate=30/1 ! waylandsink display=HDMI-A-1 sync=true
```
### 4K not working
4K requires:
1. HDMI 2.0 certified cable (not all cables rated for HDMI carry 4K@60fps reliably)
2. Genio platform that supports 4K@60fps (700, 720, 1200, not 350 or 510 at 60fps)
3. Monitor that reports 4K mode in its EDID
Check if the monitor reports 4K in `weston-info` under modes. If it does not, the monitor or cable is the bottleneck. If it does but Weston is not using it, force the mode in `weston.ini`:
```ini
[output]
name=HDMI-A-1
mode=3840x2160@30
```
### HDMI audio not working
First, identify the HDMI audio device:
```bash
aplay -l
```
Look for the HDMI entry, typically something like `card 0: MTKAudio [MTKAudio], device 3: HDMI [HDMI]`.
Test directly:
```bash
aplay -D hw:0,3 /usr/share/sounds/alsa/Front_Center.wav
```
In GStreamer:
```bash
gst-launch-1.0 audiotestsrc ! audioconvert ! alsasink device=hw:0,3
```
If audio device is not listed, check that the HDMI display is active, the kernel ALSA driver for HDMI only registers the device when a display is connected and Weston has performed the mode set.
## What does the display configuration matrix look like?
| Platform | Max HDMI resolution | Multi-display | HDMI + DSI simultaneous |
|---|---|---|---|
| Genio 350 | 4K@30fps | No | No (DSI only, HDMI on some EVK revisions) |
| Genio 510 | 4K@30fps | No | No |
| Genio 700 | 4K@60fps | Yes (HDMI + DSI) | Yes |
| Genio 520 | No HDMI (DP over USB-C instead) | Yes (DSI/eDP/DP/LVDS pairs) | No (no HDMI IP) |
| Genio 720 | No HDMI (DP over USB-C instead) | Yes (DSI/eDP/DP/LVDS pairs) | No (no HDMI IP) |
| Genio 1200 | 4K@60fps + HDR10 | Yes (up to 4 outputs) | Yes |
A correction worth stating plainly, because it changes product designs: **Genio 520 and 720 have no HDMI transmitter at all.** Their external monitor path is DisplayPort over USB-C (`display-dpoc.dtbo`), alongside DSI, eDP, and LVDS panel interfaces. We cover the board-level consequences in [Genio hardware design gotchas](/blog/mediatek-genio-hardware-design-gotchas).
## How do you run dual displays, or mirror one onto the other?
First rule since IoT Yocto v25: **no display interface is enabled by default.** Every output, including the single default panel, comes from a device tree overlay selected at flash time, so "my second display does not exist" is usually a missing DTBO rather than a driver problem. On the 520/720 class, the two VDOSYS display pipelines support any two-output combination: DSI + eDP, DSI + DP-over-USB-C, LVDS + eDP, LVDS + DP, or eDP + DP. On the 510/700 class the pairings are DSI and HDMI (via the LT6911 bridge on the EVK) plus DP/eDP overlays. Load both overlays for your pair, then confirm the kernel sees both connectors:
```bash
modeprint mediatek
# Connector: DSI-1 conn: connected
# Connector: eDP-1 conn: connected
```
Both connected means the DRM side is done, and everything after this line is Weston configuration. By default Weston extends the desktop across outputs. For digital signage and status-display products you usually want cloning instead, which recent Weston releases support directly in `weston.ini`:
```ini
[output]
name=eDP-1
mode=1920x1080
[output]
name=DSI-1
same-as=eDP-1
```
`same-as` mirrors one output onto another; matching resolutions avoids scaling. If your Weston build predates `same-as`, the fallback is the application-level one: run your app fullscreen on one output and a mirror client on the second, or composite both from a single GStreamer pipeline with two sinks. For headless products the inverse applies: ship no display DTBO at all, and GPU work continues against the render node at `/dev/dri/renderD128`.
---
Dealing with display bring-up issues on MediaTek Genio? [ProventusNova](https://proventusnova.com) has hands-on experience with Genio display hardware across EVK and custom board designs. See our [custom board bringup service](/services/custom-board-bringup) or [get in touch](https://proventusnova.com/contact).
---
## Real-Time Linux on MediaTek Genio: PREEMPT-RT, Jailhouse, and RITY
URL: https://proventusnova.com/blog/mediatek-genio-real-time-linux/
Published: 2026-06-10
Author: Andres Campos
Tags: mediatek, genio, real-time, preempt-rt, jailhouse, rity, rtos, embedded linux
What real-time Linux options exist on MediaTek Genio, what each approach delivers, and how to choose between PREEMPT-RT, Jailhouse, and RITY.
MediaTek Genio supports three distinct real-time approaches, each with different trade-offs in latency, isolation, complexity, and compatibility with the rest of the Linux software stack. PREEMPT-RT modifies the Linux kernel, Jailhouse partitions the CPU at the hypervisor level, and RITY uses dedicated co-processor hardware that never touches Linux. Choosing the right approach depends on your latency requirement and how much you need to isolate the real-time workload.
## Key Insights
- PREEMPT-RT is the lowest-effort option, patches the Linux kernel, no hardware partitioning, 50-150 µs worst-case latency
- Jailhouse runs bare-metal or Zephyr on partitioned Cortex-A cores, deterministic, under 10 µs, requires memory partitioning work
- RITY is MediaTek's M-core RTOS, completely separate hardware, 1-10 µs, communicates with Linux via IPC
- Genio 350 has no dedicated RTOS co-processor, PREEMPT-RT or Jailhouse are the only real-time options
- Running Jailhouse reduces CPUs available to Linux, plan core allocation before committing to this approach
## What are the three approaches?
### PREEMPT-RT
PREEMPT-RT is a set of patches to the Linux kernel that convert most kernel code paths from non-preemptible to preemptible. It does not change the hardware configuration, the same Linux kernel runs on all cores, and the same BSP drivers apply.
The effect is a significant reduction in worst-case interrupt latency. Standard Linux can experience latency spikes of several milliseconds under load. A PREEMPT-RT kernel on Genio typically holds worst-case latency below 100-150 µs.
To enable in Yocto (see the [Genio Yocto build guide](/blog/mediatek-genio-yocto-build-guide) for the full build setup):
```bash
# In your local.conf or kas yml:
PREFERRED_PROVIDER_virtual/kernel = "linux-mediatek-5.15"
KERNEL_FEATURES:append = " features/preempt-rt/preempt-rt.scc"
```
Verify at runtime:
```bash
uname -a
# Should show "PREEMPT RT" in the version string
# Measure worst-case latency with cyclictest
cyclictest -m -p 99 -t 4 -n -i 200 -D 60
```
### Jailhouse
[Jailhouse](https://github.com/siemens/jailhouse) is a Type-1 partitioning hypervisor. It runs at EL2 (ARM hypervisor mode) and partitions the system into isolated cells. The root cell runs Linux with access to all memory and peripherals not assigned to other cells. Inmate cells can run bare metal, Zephyr, or another RTOS.
For the inmate cell, the real-time execution is truly deterministic, it is not subject to Linux scheduling, cache pollution from Linux, or SMI latency. The trade-off is complexity: you must write cell configuration files that partition CPUs, memory, and peripherals, and you must implement IPC between the Linux root cell and the inmate.
On Genio, Jailhouse runs on the Cortex-A cores. MediaTek's Genio 700 and 720 EVKs have been validated with Jailhouse (with upstream patches from MediaTek's FAE team). The recommended IPC mechanism is IVSHMEM (shared memory with interrupt signaling).
A typical 4+2 core split for Genio 720 (octa-core):
```
Root cell (Linux): Cortex-A78 (cores 0-3) + Cortex-A55 (cores 4-5)
Inmate cell (Zephyr/bare-metal): Cortex-A55 (cores 6-7)
```
The inmate cell's CPUs are physically isolated from Linux, they do not share the scheduler or interrupt affinity.
### RITY
RITY is MediaTek's proprietary RTOS that runs on the dedicated Cortex-M co-processor cores present on Genio 510/520/700/720/1200. These M-cores are separate silicon from the A-cores running Linux. They have their own interrupt controller, their own memory, and their own clock domain.
From Linux's perspective, RITY is a remote processor (`remoteproc`) that the kernel boots by loading firmware via the RPMsg/IVSHMEM IPC bus.
RITY is appropriate for:
- Hard real-time control loops that must be completely isolated from Linux scheduling
- Sensor polling at fixed intervals (IMU, encoder, etc.)
- Motor control or actuator output with deterministic timing
- Watchdog behavior that must survive a Linux crash
RITY communicates with Linux through the `rpmsg` framework, Linux sends and receives messages to/from RITY via the IPC channel.
## How do the approaches compare?
| | PREEMPT-RT | Jailhouse | RITY |
|---|---|---|---|
| **Hardware change** | None | Hypervisor partitioning of A-cores | Separate M-core hardware |
| **Worst-case latency** | 50-150 µs | < 10 µs (inmate) | 1-10 µs |
| **Isolation from Linux** | None, same kernel | Full, separate cell | Full, separate hardware |
| **Complexity** | Low | High | Medium |
| **Linux driver compatibility** | Full | Root cell only | Full (Linux side unchanged) |
| **Available on Genio 350** | Yes | Yes (limited) | No |
| **Requires NDA BSP** | No | No (public patches) | Yes (RITY firmware) |
| **IPC to Linux** | Not needed | IVSHMEM | RPMsg |
## Which approach should you choose?
**PREEMPT-RT**: when your latency requirement is above 100 µs and you want a single Linux image with no architectural changes. Good for industrial data acquisition, sensor fusion, and soft real-time control.
**Jailhouse**: when you need deterministic control under 10 µs on an A-core compute budget, and you are willing to invest in hypervisor configuration and IPC design. Best for robotics, multi-axis control, or safety-critical functions that benefit from A-core compute power.
**RITY**: when you need fully isolated hardware determinism for simple, fast control loops, and your real-time logic fits on an M-core (limited compute, no MMU). Best for sensor polling, watchdog, and I/O control that must survive a Linux crash.
---
Building a product on MediaTek Genio that needs real-time capabilities? [ProventusNova](https://proventusnova.com) has hands-on experience with PREEMPT-RT, Jailhouse, and RITY on Genio, including the Genio 720 Jailhouse integration. See our [MediaTek Genio support page](/get-expert-mediatek-genio-support) or [get in touch](https://proventusnova.com/contact).
---
## nvargus crash and CaptureScheduler deadlock on Jetson, debug guide
URL: https://proventusnova.com/blog/nvargus-crash-capturesched-deadlock-jetson/
Published: 2026-06-10
Author: Andres Campos
Tags: jetson, orin, nvargus, libargus, camera, debugging, gstreamer, embedded linux
Debug nvargus core dumps and CaptureScheduler deadlock on Jetson. libargus logs, JP6 libnvscf regression, and watchdog recovery patterns.
nvargus failures fall into two distinct categories with different debugging paths: crashes (the process exits) and deadlocks (the process hangs). Confusing the two wastes significant debugging time. This guide covers both failure modes, how to diagnose them, and the known JetPack 6 libnvscf regression that causes random CaptureScheduler deadlocks in production.
## Key Insights
- **Crash vs deadlock is the first fork**: check if `argus_daemon` is still in `ps aux` when frames stop; alive = deadlock, absent = crash
- **`LIBARGUS_ENABLE_LOGS=1` is your first tool**: without logs, crashes and deadlocks produce no useful output
- **The libnvscf CaptureScheduler bug affects JP 6.0–6.2.1**: upgrading to JP 6.2.2 or applying the patch fixes most random production deadlocks
- **Restarting `argus_daemon` recovers a deadlock**: build a watchdog into production systems that restarts the daemon when no frames arrive for N seconds
- **`strace -p` on the deadlocked process** reveals which syscall it is stuck on, this distinguishes kernel-level blocking from userspace mutex spin
## Enabling nvargus logs
```bash
# Minimum: capture errors and warnings
export LIBARGUS_ENABLE_LOGS=1
# Verbose: capture scheduling, session events, internal state
export LIBARGUS_ENABLE_LOGS=3
# Logs go to stderr and syslog
# For the argus_daemon service:
sudo systemctl edit argus-daemon
# Add:
# [Service]
# Environment="LIBARGUS_ENABLE_LOGS=3"
sudo systemctl restart argus-daemon
# View daemon logs
journalctl -u argus-daemon -f
```
## Diagnosing: crash vs deadlock
```bash
# Step 1: check if argus_daemon is alive
ps aux | grep argus_daemon
# Step 2a: if process is GONE → crash
# Check for core dump
ls -la /tmp/core* /var/core* 2>/dev/null
# Check dmesg for SIGABRT / segfault
dmesg | grep -E "argus|nvargus|segfault|killed" | tail -20
# Check syslog
journalctl -u argus-daemon --since "5 minutes ago"
# Step 2b: if process is ALIVE but no frames → deadlock
# Check what syscall the process is stuck on
sudo strace -p $(pidof argus_daemon) -e trace=futex,pthread_mutex 2>&1 | head -30
# If output shows futex(FUTEX_WAIT) spinning → mutex deadlock
# If output shows poll/epoll_wait → waiting on hardware
```
## CaptureScheduler deadlock, the libnvscf regression
The most common cause of random deadlocks in JP 6.x production systems is a bug in `libnvscf.so`. The CaptureScheduler thread acquires a mutex for each capture request and can enter a state where the mutex is never released.
**Identifying it:**
```bash
# Check libnvscf version
strings /usr/lib/aarch64-linux-gnu/libnvscf.so | grep -E "version|build|r36"
# Attach gdb to the running daemon and get thread backtraces
sudo gdb -p $(pidof argus_daemon) -batch \
-ex "thread apply all bt" \
-ex "quit" 2>&1 | grep -A5 "CaptureScheduler"
# Deadlocked output will show:
# #0 0x... in __pthread_mutex_lock
# #1 0x... in CaptureScheduler::...
# #2 0x... in libargus::...
```
**Workarounds:**
1. **Upgrade to JP 6.2.2**: the latest point release has the libnvscf patch
2. **Apply patched library**: NVIDIA support can provide a patched `libnvscf.so` for specific JP subversions
3. **Watchdog restart**: implement a frame watchdog that restarts `argus_daemon` on deadlock:
```bash
#!/bin/bash
# /usr/local/bin/argus-watchdog.sh
# Restart argus_daemon if no frames for 30 seconds
LAST_FRAME_TIME=$(date +%s)
FRAME_COUNT_FILE=/tmp/.argus_frame_count
while true; do
# Your application writes frame count to this file
CURRENT_COUNT=$(cat "$FRAME_COUNT_FILE" 2>/dev/null || echo 0)
if [[ "$CURRENT_COUNT" != "$LAST_COUNT" ]]; then
LAST_COUNT=$CURRENT_COUNT
LAST_FRAME_TIME=$(date +%s)
fi
NOW=$(date +%s)
ELAPSED=$((NOW - LAST_FRAME_TIME))
if [[ $ELAPSED -gt 30 ]]; then
logger "argus-watchdog: no frames for ${ELAPSED}s, restarting argus_daemon"
systemctl restart argus-daemon
LAST_FRAME_TIME=$(date +%s)
sleep 5 # wait for daemon to restart
fi
sleep 1
done
```
```ini
# /etc/systemd/system/argus-watchdog.service
[Unit]
Description=Argus daemon watchdog
After=argus-daemon.service
[Service]
ExecStart=/usr/local/bin/argus-watchdog.sh
Restart=always
[Install]
WantedBy=multi-user.target
```
## Debugging crashes (process exits)
### Session destruction crash
Common cause: destroying an `ICaptureSession` while a capture request is still in flight.
```cpp
// WRONG, race condition
delete captureSession; // crashes if request still in flight
// CORRECT, wait for all requests to complete
captureSession->stopRepeat();
captureSession->waitForIdle(); // blocks until all in-flight requests complete
delete captureSession;
```
### Sensor mode mismatch crash
SIGABRT if the requested sensor mode does not match the modes in the device tree:
```bash
# List available sensor modes
v4l2-ctl -d /dev/video0 --list-formats-ext
# The Argus sensor mode index must correspond to a valid V4L2 format
# Mode 0 = first entry in sensor_modes in device tree
```
```cpp
// Always validate mode index against available modes
Argus::SensorMode *sensorMode;
std::vector sensorModes;
iCameraProperties->getSensorModes(&sensorModes);
if (modeIndex >= sensorModes.size()) {
// Handle invalid mode, don't crash
return false;
}
sensorMode = sensorModes[modeIndex];
```
### Memory leak leading to OOM crash
Long-running capture sessions accumulate frame buffers if `EGLStream` consumers don't consume frames promptly:
```cpp
// In your GStreamer nvarguscamerasrc pipeline, add timeout:
// nvarguscamerasrc sensor-id=0 timeout=0
// timeout=0 means run indefinitely but cap buffer queue
// For custom libargus: release frames promptly
iFrameConsumer->acquireFrame(&frame, timeout);
// ... process frame ...
iFrameConsumer->releaseFrame(frame); // MUST release; not automatic
```
## GStreamer nvarguscamerasrc reset on deadlock
For GStreamer-based pipelines, the cleanest recovery is restarting the entire pipeline rather than just the daemon:
```python
import subprocess
import time
import threading
def camera_watchdog(pipeline, timeout_sec=30):
"""Monitor pipeline, restart if stalled."""
last_good = time.time()
def on_new_sample(appsink):
nonlocal last_good
last_good = time.time()
sample = appsink.emit('pull-sample')
# process sample
return Gst.FlowReturn.OK
def watchdog_thread():
while True:
time.sleep(5)
if time.time() - last_good > timeout_sec:
pipeline.set_state(Gst.State.NULL)
subprocess.run(['systemctl', 'restart', 'argus-daemon'])
time.sleep(2)
pipeline.set_state(Gst.State.PLAYING)
last_good = time.time()
t = threading.Thread(target=watchdog_thread, daemon=True)
t.start()
```
For the V4L2 capture path that serves as a fallback when Argus deadlocks, see the fault isolation pattern in [MIPI CSI camera driver setup on Jetson](/blog/csi-camera-driver-jetson-v4l2-argus-imx). For the gotcha that explains why v4l2-ctl succeeds but argus_camera fails, see [Jetson camera works with v4l2-ctl but fails with argus_camera](/blog/jetson-camera-v4l2-works-argus-fails-debug).
## FAQ
### What is the CaptureScheduler deadlock in nvargus on Jetson?
A threading bug in `libnvscf.so` where the capture scheduler thread acquires a mutex and never releases it. The `argus_daemon` process stays alive but stops delivering frames. Most prevalent in JP 6.0–6.2.1. Fix: upgrade to JP 6.2.2 or apply the patched `libnvscf.so`.
### How do I enable nvargus debug logs on Jetson?
Set `LIBARGUS_ENABLE_LOGS=1` (or 3 for verbose) before launching your application or `argus_daemon`. Logs go to stderr and syslog, readable via `journalctl -u argus-daemon`.
### How do I tell the difference between an nvargus crash and a deadlock?
If `argus_daemon` is gone from `ps aux` → crash. If it is still alive but no frames arrive → deadlock. Use `strace -p $(pidof argus_daemon)` to see what syscall the deadlocked process is stuck on.
### What is the libnvscf.so regression in JetPack 6?
A CaptureScheduler threading bug affecting JP 6.0–6.2.1 that causes random deadlocks under sustained capture. Fixed in JP 6.2.2. NVIDIA support can also provide a patched `libnvscf.so` for earlier releases.
---
---
## MediaTek Genio for computer vision: a practical guide
URL: https://proventusnova.com/blog/mediatek-genio-computer-vision-guide/
Published: 2026-06-09
Author: Aaron Angulo
Tags: mediatek, genio, computer vision, gstreamer, opencv, tflite, npu, camera, edge ai
Build a computer vision pipeline on MediaTek Genio. Camera capture, GStreamer, OpenCV, TFLite NPU inference, and end-to-end object detection pipeline examples.
Genio is well-matched to computer vision applications: it has MIPI CSI-2 interfaces with hardware ISP, a Mali GPU for OpenCL/Vulkan compute, and an MDLA NPU for inference. The challenge is wiring these together efficiently, the wrong capture path adds unnecessary CPU copies that hurt latency and throughput. This guide covers the full stack from camera to inference to output.
## Key Insights
- **GStreamer is the right capture layer**: it uses hardware ISP and keeps frames in device memory; OpenCV VideoCapture forces a CPU copy on MIPI cameras
- **NNStreamer bridges GStreamer and inference**: it runs TFLite/ONNX inference as a GStreamer element with no copy between the pipeline and the model
- **INT8 quantized models on the NPU** are 4–6× faster than FP32 on CPU; quantize your models before deployment
- **USB cameras are simpler to start**: they appear as standard V4L2 devices, no ISP bring-up required; switch to MIPI CSI for production
- **OpenCV for post-processing, GStreamer for capture**: use each for what it's good at; don't use OpenCV VideoCapture for MIPI cameras
## Camera capture options
### Option 1: USB camera (V4L2 / UVC)
The easiest starting point. USB cameras appear as `/dev/videoN` on Genio and work with standard V4L2 tools immediately.
```bash
# List connected cameras
v4l2-ctl --list-devices
# Check supported formats
v4l2-ctl -d /dev/video0 --list-formats-ext
# Capture test frame
v4l2-ctl -d /dev/video0 --stream-mmap --stream-count=1 \
--stream-to=frame.raw
```
GStreamer capture from USB camera:
```bash
gst-launch-1.0 \
v4l2src device=/dev/video0 ! \
video/x-raw,format=YUY2,width=640,height=480,framerate=30/1 ! \
videoconvert ! \
video/x-raw,format=RGB ! \
autovideosink
```
### Option 2: MIPI CSI camera (ISP pipeline)
MIPI CSI cameras connect to the Genio CSI connector and go through the hardware ISP. The ISP handles auto-exposure, auto-white-balance, and noise reduction automatically.
```bash
# Check that the camera sensor was probed
dmesg | grep -i "sensor\|imx\|ov"
# List V4L2 devices including subdevices
v4l2-ctl --list-devices
media-ctl -d /dev/media0 --print-topology
```
GStreamer MIPI CSI capture (using libcamera on Ubuntu):
```bash
gst-launch-1.0 \
libcamerasrc camera-name="/base/soc/seninf@1a040000/port@0" ! \
video/x-raw,format=NV12,width=1920,height=1080,framerate=30/1 ! \
videoconvert ! autovideosink
```
On Yocto with V4L2 backend:
```bash
gst-launch-1.0 \
v4l2src device=/dev/video0 ! \
video/x-raw,format=NV12,width=1920,height=1080 ! \
videoconvert ! autovideosink
```
## OpenCV with GStreamer capture
Avoid `cv2.VideoCapture(0)` for MIPI CSI cameras, it goes through V4L2 with a CPU copy. Use a GStreamer pipeline with `appsink` to feed frames into OpenCV:
```python
import cv2
import numpy as np
# GStreamer pipeline that feeds into OpenCV
pipeline = (
"v4l2src device=/dev/video0 ! "
"video/x-raw,format=BGR,width=640,height=480,framerate=30/1 ! "
"appsink name=sink max-buffers=1 drop=true sync=false"
)
cap = cv2.VideoCapture(pipeline, cv2.CAP_GSTREAMER)
while True:
ret, frame = cap.read()
if not ret:
break
# frame is a 480x640x3 BGR numpy array
# Process with OpenCV
gray = cv2.cvtColor(frame, cv2.COLOR_BGR2GRAY)
edges = cv2.Canny(gray, 100, 200)
cv2.imshow("Edges", edges)
if cv2.waitKey(1) == ord('q'):
break
cap.release()
```
## TFLite inference with Neuron Stable Delegate
For object detection (SSD MobileNet example):
```python
import tflite_runtime.interpreter as tflite
import cv2
import numpy as np
# Load model with NPU acceleration
interpreter = tflite.Interpreter(
model_path="ssd_mobilenet_v2_int8.tflite",
experimental_delegates=[
tflite.load_delegate("libNeuronStableDelegate.so")
]
)
interpreter.allocate_tensors()
input_details = interpreter.get_input_details()
output_details = interpreter.get_output_details()
input_shape = input_details[0]['shape'] # [1, 300, 300, 3]
height, width = input_shape[1], input_shape[2]
# GStreamer capture
pipeline = (
f"v4l2src device=/dev/video0 ! "
f"video/x-raw,format=RGB,width=640,height=480 ! "
f"videoscale ! video/x-raw,width={width},height={height} ! "
f"appsink max-buffers=1 drop=true sync=false"
)
cap = cv2.VideoCapture(pipeline, cv2.CAP_GSTREAMER)
while True:
ret, frame = cap.read()
if not ret:
break
# Preprocess
input_data = np.expand_dims(frame, axis=0)
if input_details[0]['dtype'] == np.uint8:
input_data = input_data.astype(np.uint8)
else:
input_data = ((input_data / 255.0 - 0.5) / 0.5).astype(np.float32)
# Inference
interpreter.set_tensor(input_details[0]['index'], input_data)
interpreter.invoke()
# SSD MobileNet outputs
boxes = interpreter.get_tensor(output_details[0]['index'])[0]
classes = interpreter.get_tensor(output_details[1]['index'])[0]
scores = interpreter.get_tensor(output_details[2]['index'])[0]
# Draw boxes with score > 0.5
h, w = frame.shape[:2]
for i, score in enumerate(scores):
if score < 0.5:
break
ymin, xmin, ymax, xmax = boxes[i]
cv2.rectangle(frame,
(int(xmin * w), int(ymin * h)),
(int(xmax * w), int(ymax * h)),
(0, 255, 0), 2)
cv2.imshow("Detection", cv2.cvtColor(frame, cv2.COLOR_RGB2BGR))
if cv2.waitKey(1) == ord('q'):
break
```
## NNStreamer: inference inside GStreamer
NNStreamer runs TFLite inference as a native GStreamer element, eliminating the copy between the pipeline and the model:
```bash
# Object detection with NNStreamer + NPU
gst-launch-1.0 \
v4l2src device=/dev/video0 ! \
video/x-raw,format=RGB,width=640,height=480,framerate=30/1 ! \
videoscale ! video/x-raw,width=300,height=300 ! \
tensor_converter ! \
tensor_filter \
framework=tflite \
model=ssd_mobilenet_v2_int8.tflite \
accelerator=true:npu ! \
tensor_decoder \
mode=bounding_boxes \
option1=mobilenet-ssd \
option2=labels.txt \
option3=0:1:2:3 \
option4=640:480 \
option5=300:300 ! \
compositor name=mix sink_0::zorder=1 sink_1::zorder=2 ! \
waylandsink \
v4l2src device=/dev/video0 ! \
video/x-raw,format=RGB,width=640,height=480 ! \
mix.sink_0
```
NNStreamer is included in `packagegroup-rity-ai-ml` in the RITY Yocto image.
## Multi-camera setup
For applications requiring multiple cameras simultaneously:
```python
import threading
import cv2
class CameraThread(threading.Thread):
def __init__(self, device, name):
super().__init__()
self.cap = cv2.VideoCapture(
f"v4l2src device={device} ! "
"video/x-raw,format=BGR,width=640,height=480 ! "
"appsink max-buffers=1 drop=true sync=false",
cv2.CAP_GSTREAMER
)
self.name = name
self.frame = None
self.running = True
def run(self):
while self.running:
ret, frame = self.cap.read()
if ret:
self.frame = frame
cam0 = CameraThread("/dev/video0", "cam0")
cam1 = CameraThread("/dev/video2", "cam1")
cam0.start()
cam1.start()
```
## Performance tips for CV pipelines on Genio
**Use INT8 quantized models.** On the Genio NPU, INT8 inference is 2–3× faster than FP16 and uses less memory bandwidth. Quantize with TFLite's post-training quantization before deployment.
**Skip frames if needed.** If your pipeline can't sustain real-time at 30fps, drop frames at the capture stage rather than queuing them. Use `max-buffers=1 drop=true` on the GStreamer `appsink`.
**Separate capture and inference threads.** Camera capture and NPU inference are independent hardware blocks. Running them in separate threads allows full hardware utilization, the NPU runs the previous frame while the ISP captures the next.
**Avoid cv2.VideoCapture for MIPI cameras.** It forces a CPU copy at every frame. Use GStreamer `appsink` and receive frames as numpy arrays directly.
For the NPU inference stack details including model conversion and quantization, see [on-device AI without the cloud on Genio](/blog/mediatek-genio-on-device-ai-no-cloud). For MIPI CSI camera driver bring-up, see [MIPI CSI camera driver setup on Genio](/blog/mediatek-genio-mipi-csi-camera-driver).
## FAQ
### What camera interfaces does MediaTek Genio support for computer vision?
Genio supports MIPI CSI-2 cameras (2–3 four-lane interfaces depending on platform) and USB UVC cameras. MIPI CSI cameras go through the hardware ISP via libcamera or V4L2. USB cameras appear as standard V4L2 video devices.
### Should I use GStreamer or OpenCV for camera capture on Genio?
Use GStreamer for camera capture. It uses hardware-accelerated elements and keeps frames in device memory. Feed preprocessed frames from GStreamer's `appsink` into OpenCV or TFLite for inference.
### What is the fastest way to run object detection on Genio?
GStreamer MIPI CSI capture → hardware ISP → `tensor_filter` with TFLite INT8 model + NeuronStableDelegate → NNStreamer `tensor_decoder` → overlay on Wayland display. This keeps data in device memory across all stages and uses the NPU for inference.
### Does OpenCV support hardware acceleration on Genio?
OpenCV on Genio uses the ARM CPU (NEON SIMD) for most operations. For AI inference, TFLite and ONNX Runtime with NeuronEP are faster than OpenCV's DNN module because they use the dedicated MDLA NPU.
---
---
## MediaTek Genio for industrial automation
URL: https://proventusnova.com/blog/mediatek-genio-industrial-automation/
Published: 2026-06-09
Author: Andres Campos
Tags: mediatek, genio, industrial, tsn, opc-ua, real-time, automation, edge ai, iot
MediaTek Genio for industrial automation. TSN networking, OPC-UA, real-time Linux, deterministic control, Jailhouse hypervisor, and industrial protocol support.
Genio's industrial capabilities go beyond edge AI inference. The SoC integrates TSN-capable Gigabit Ethernet, and the RITY BSP includes the full industrial software stack: linuxptp for IEEE 1588 time synchronization, OPC-UA via libopen62541, PREEMPT_RT for soft real-time, and Jailhouse for hard real-time partitioning. This makes Genio viable as an industrial edge computer that combines sensor fusion, AI inference, and deterministic industrial protocol handling on a single board.
## Key Insights
- **TSN is native in silicon**: Genio 510/520/700/720/1200 all include a TSN-capable GbE MAC; no external TSN switch required for single-hop setups
- **`meta-mediatek-tsn` Yocto layer** provides the full TSN software stack, linuxptp, tc with taprio/CBS, and OPC-UA
- **PREEMPT_RT is included in the RITY BSP**: enables soft real-time Linux for control loops that need deterministic response in the 50–500µs range
- **Jailhouse hypervisor** partitions CPU cores between Linux and a bare-metal RTOS, use it when you need hard real-time guarantees alongside Linux
- **OPC-UA (`libopen62541`)** ships in the `rity-tsn` packagegroup, server and client modes supported out of the box
## TSN (Time-Sensitive Networking) on Genio
TSN adds deterministic delivery and time synchronization to standard Gigabit Ethernet. The key standards relevant for industrial automation:
| Standard | What it provides | Genio support |
|---|---|---|
| IEEE 802.1AS | Time synchronization (gPTP) | ✅ via linuxptp |
| IEEE 802.1Qbv | Time-Aware Shaper (TAS/taprio) | ✅ via tc taprio |
| IEEE 802.1Qav | Credit-Based Shaper (CBS) | ✅ via tc CBS |
| IEEE 802.1Qcc | Stream reservation | ✅ via SR classes |
### Setting up gPTP time synchronization
```bash
# Install linuxptp (from meta-mediatek-tsn)
# On target:
# Check that PTP hardware clock is available
ls /dev/ptp*
# /dev/ptp0
# Query PTP clock capabilities
ethtool -T eth0 | grep -E "SOF_TIMESTAMPING|PTP"
# Start gPTP daemon as grandmaster (time source)
ptp4l -i eth0 -f /etc/linuxptp/gPTP.cfg --masterOnly 1 &
phc2sys -a -rr &
# Or as slave (sync to network time)
ptp4l -i eth0 -f /etc/linuxptp/gPTP.cfg -s &
phc2sys -a -rr &
```
Verify synchronization:
```bash
pmc -u -b 0 'GET CURRENT_DATA_SET'
# Should show offset close to 0 ns when synced
```
### Configuring Time-Aware Shaper (taprio)
taprio schedules transmission windows for different traffic classes, ensuring control traffic is transmitted in guaranteed time slots:
```bash
# Configure taprio schedule
# 8 queues, 1ms cycle: 200µs for control (queue 0), 800µs for best-effort
tc qdisc replace dev eth0 parent root handle 100 taprio \
num_tc 2 \
map 1 1 1 1 1 1 1 1 \
queues 1@0 1@1 \
base-time $(date +%s%N)000 \
sched-entry S 01 200000 \
sched-entry S 02 800000 \
flags 0x2
```
### Credit-Based Shaper (CBS) for audio/video streams
```bash
tc qdisc replace dev eth0 parent root mqprio \
num_tc 3 map 2 2 2 2 2 2 2 2 2 2 2 2 2 2 2 2 queues 1@0 1@1 2@2 \
hw 0
tc qdisc replace dev eth0 parent 100:1 cbs \
idleslope 10000 sendslope -990000 \
hicredit 153 locredit -1389 offload 1
```
## OPC-UA with libopen62541
libopen62541 is the open-source OPC-UA implementation included in the RITY `rity-tsn` packagegroup.
### Simple OPC-UA server on Genio
```c
#include
#include
int main(void) {
UA_Server *server = UA_Server_new();
UA_ServerConfig_setDefault(UA_Server_getConfig(server));
// Add a variable node: temperature sensor reading
UA_VariableAttributes attr = UA_VariableAttributes_default;
UA_Float temperature = 23.5f;
UA_Variant_setScalar(&attr.value, &temperature, &UA_TYPES[UA_TYPES_FLOAT]);
attr.displayName = UA_LOCALIZEDTEXT("en-US", "Temperature");
attr.accessLevel = UA_ACCESSLEVELMASK_READ | UA_ACCESSLEVELMASK_WRITE;
UA_NodeId nodeId = UA_NODEID_STRING(1, "temperature");
UA_NodeId parentNodeId = UA_NODEID_NUMERIC(0, UA_NS0ID_OBJECTSFOLDER);
UA_NodeId parentReferenceNodeId = UA_NODEID_NUMERIC(0, UA_NS0ID_ORGANIZES);
UA_QualifiedName browseName = UA_QUALIFIEDNAME(1, "Temperature");
UA_Server_addVariableNode(server, nodeId, parentNodeId,
parentReferenceNodeId, browseName,
UA_NODEID_NUMERIC(0, UA_NS0ID_BASEDATAVARIABLETYPE),
attr, NULL, NULL);
// Run server on port 4840
UA_StatusCode retval = UA_Server_runUntilInterrupt(server);
UA_Server_delete(server);
return retval == UA_STATUSCODE_GOOD ? 0 : 1;
}
```
Build with:
```bash
gcc -o opc_server opc_server.c \
$(pkg-config --cflags --libs open62541)
```
Clients connect to `opc.tcp://:4840`.
## Real-time Linux (PREEMPT_RT)
The RITY BSP includes PREEMPT_RT kernel patches. With PREEMPT_RT, most kernel code paths become preemptible, reducing worst-case interrupt latency from milliseconds to the 50–500µs range.
### Enable PREEMPT_RT in Yocto
```bitbake
# conf/local.conf
KERNEL_FEATURES:append = " features/preempt-rt/preempt-rt.scc"
```
Or in your kernel bbappend:
```bitbake
LINUX_KERNEL_TYPE = "preempt-rt"
```
### Verify RT kernel is running
```bash
uname -r
# Should include "rt" in the version string
# e.g., 6.1.57-rt16-v8+
# Check preemption model
grep CONFIG_PREEMPT /boot/config-$(uname -r)
# CONFIG_PREEMPT_RT=y
```
### Configuring a real-time control thread
```c
#include
#include
void* control_loop(void* arg) {
// Set real-time priority
struct sched_param param = { .sched_priority = 80 };
pthread_setschedparam(pthread_self(), SCHED_FIFO, ¶m);
// Lock memory to prevent page faults
mlockall(MCL_CURRENT | MCL_FUTURE);
struct timespec next;
clock_gettime(CLOCK_MONOTONIC, &next);
while (1) {
// 1ms control loop
next.tv_nsec += 1000000;
if (next.tv_nsec >= 1000000000) {
next.tv_nsec -= 1000000000;
next.tv_sec++;
}
// --- Do control work here ---
read_sensors();
compute_control_output();
write_actuators();
// ---
clock_nanosleep(CLOCK_MONOTONIC, TIMER_ABSTIME, &next, NULL);
}
return NULL;
}
```
Isolate a CPU core for the RT thread:
```bash
# Kernel command line: isolate core 3 from the OS scheduler
isolcpus=3 irqaffinity=0-2
# Pin RT thread to isolated core
taskset -c 3 ./control_app
```
## Jailhouse hypervisor for hard real-time
When PREEMPT_RT soft real-time isn't sufficient, for example, motion control requiring sub-100µs determinism, Jailhouse partitions the Genio CPU cores:
| Partition | Cores | Runs | Latency |
|---|---|---|---|
| Root cell | Core 0–2 | Linux + full BSP + applications | OS-level (1–10ms) |
| Inmate cell | Core 3 | Bare-metal RTOS or custom firmware | Hardware-level (<50µs) |
The inmate cell has exclusive access to its CPU core and assigned memory, Linux cannot interrupt it.
```bash
# Load Jailhouse kernel module
modprobe jailhouse
# Enable Jailhouse with the board cell config
jailhouse enable /lib/firmware/jailhouse/genio720-evk.cell
# Load and start an inmate (bare-metal demo)
jailhouse cell create /lib/firmware/jailhouse/genio720-inmate.cell
jailhouse cell load my-inmate /path/to/inmate.bin
jailhouse cell start my-inmate
# Check status
jailhouse cell list
```
Jailhouse configurations for Genio EVKs are included in the RITY BSP. Custom carrier boards need their own cell configuration describing memory layout and peripheral assignment.
## Industrial use case examples
| Application | Key Genio features used |
|---|---|
| Smart gateway (IIoT edge) | TSN GbE, OPC-UA server, NPU for anomaly detection |
| Machine vision + PLC integration | MIPI CSI camera, TFLite NPU inference, OPC-UA client |
| Motor drive coordination | PREEMPT_RT, TSN taprio for deterministic EtherCAT-like control |
| Predictive maintenance | Multiple I2C/SPI vibration sensors, NPU time-series inference |
| Vision-guided robot | Multi-camera (MIPI CSI), NPU object detection, UART/SPI to servo controller |
| Industrial HMI | HDMI/DSI display, Weston Wayland, OPC-UA data visualization |
For the RITY Yocto layer that includes the TSN and OPC-UA packages, see [What is RITY? MediaTek's Genio reference distribution explained](/blog/mediatek-genio-rity-rtos-explained). For AI inference on the Genio NPU that powers the machine vision component, see [on-device AI without the cloud on Genio](/blog/mediatek-genio-on-device-ai-no-cloud).
## FAQ
### Does MediaTek Genio support real-time Linux for industrial control?
Yes. The RITY Yocto BSP includes PREEMPT_RT patches for the Genio kernel. This reduces worst-case latency to the 50–500µs range for soft real-time control. For hard real-time, Jailhouse partitions a CPU core for a dedicated RTOS.
### What is TSN and does Genio support it?
TSN (Time-Sensitive Networking) adds deterministic, time-synchronized packet delivery to standard Ethernet. Genio 510, 520, 700, 720, and 1200 include a TSN-capable GbE MAC. The RITY BSP includes linuxptp, taprio, and CBS in the `meta-mediatek-tsn` layer.
### Can Genio run OPC-UA for industrial protocol integration?
Yes. `libopen62541` (open-source OPC-UA stack) is included in the `rity-tsn` packagegroup. It supports both OPC-UA server and client modes on Genio.
### What is the Jailhouse hypervisor on Genio and when should I use it?
Jailhouse is a static partitioning hypervisor that dedicates CPU cores to isolated partitions. Use it when you need hard real-time control (sub-millisecond determinism) alongside Linux-based applications on the same SoC.
---
---
## MIPI CSI camera driver setup on MediaTek Genio
URL: https://proventusnova.com/blog/mediatek-genio-mipi-csi-camera-driver/
Published: 2026-06-09
Author: Andres Campos
Tags: mediatek, genio, mipi-csi, camera, v4l2, gstreamer, embedded linux, device tree
How to set up a MIPI CSI-2 camera on MediaTek Genio: device tree, sensor driver, seninf, V4L2 pipeline, and capturing frames with GStreamer.
Getting a MIPI CSI-2 camera working on MediaTek Genio involves three layers: the device tree configuration, the sensor kernel driver, and the media controller pipeline that connects the sensor to the ISP. Each layer must be correct before the camera appears as a usable V4L2 device.
## Key Insights
- The seninf driver is the MIPI CSI-2 receiver, it connects the physical lanes to the ISP pipeline
- Sensor driver + device tree + media controller link all must be correct before `v4l2-ctl` can see formats
- `media-ctl` is the tool for inspecting and configuring the V4L2 media graph on Genio
- NDA build is required for ISP hardware acceleration, without it you get raw frames without processing
- USB UVC cameras work without any BSP changes and are useful for early development
## How does the camera pipeline work on Genio?
The camera path has four stages:
```
Sensor (I2C driver + MIPI output)
→ seninf (MIPI CSI-2 receiver, kernel driver)
→ ISP pipeline (NDA layer, raw to processed)
→ V4L2 video device (/dev/videoN)
```
The sensor driver handles the I2C register communication, setting resolution, exposure, gain, and streaming mode. The seninf driver receives the MIPI data packets and passes them to the ISP. The ISP (with [NDA layer](/blog/mediatek-genio-nda-vs-public-build)) performs demosaicing, noise reduction, and 3A processing. The final output appears as a V4L2 capture device.
Without the NDA ISP layer, the pipeline still works but outputs raw Bayer data without processing. For the ISP differences between Genio generations, see [ISP differences between Genio 510/700 and 520/720](/blog/mediatek-genio-510-700-520-720-isp-differences).
## What does the device tree entry look like?
A minimal device tree entry for an IMX219 sensor on Genio's first CSI port:
```dts
&i2c2 {
imx219: camera@10 {
compatible = "sony,imx219";
reg = <0x10>;
reset-gpios = <&pio 25 GPIO_ACTIVE_LOW>;
VANA-supply = <&mt6359p_vcamd_reg>;
VDIG-supply = <&mt6359p_vcn18_reg>;
VDDL-supply = <&mt6359p_vcn18_reg>;
port {
imx219_out: endpoint {
remote-endpoint = <&seninf_csi0_in>;
clock-lanes = <0>;
data-lanes = <1 2>;
link-frequencies = /bits/ 64 <456000000>;
};
};
};
};
&seninf_top {
ports {
port@0 {
seninf_csi0_in: endpoint@0 {
remote-endpoint = <&imx219_out>;
bus-type = <4>; /* MIPI CSI-2 */
};
};
};
};
```
Key fields:
- `reg`: I2C address of the sensor
- `reset-gpios`: GPIO for the sensor reset pin (check your board schematic)
- `*-supply`: power regulators for the sensor (VANA, VDIG, VDDL vary by sensor)
- `data-lanes`: MIPI lane mapping, `<1 2>` for a 2-lane sensor
- `link-frequencies`: the MIPI bit rate the sensor will operate at (must match the sensor datasheet)
## How do you verify the driver loaded correctly?
After booting with the new device tree:
```bash
# Check that the sensor I2C device was recognized
dmesg | grep imx219
# Check for seninf and ISP in the media graph
media-ctl -p
```
`media-ctl -p` lists the full pipeline topology. A healthy output shows the sensor subdev linked to seninf, and seninf linked to the ISP entities:
```
- entity 1: imx219 2-0010 (1 pad, 1 link)
type V4L2 subdev subtype Sensor flags 0
pad0: Source
-> "seninf-2":0 [ENABLED,IMMUTABLE]
- entity 5: seninf-2 (2 pads, 2 links)
type V4L2 subdev subtype Unknown flags 0
pad0: Sink
<- "imx219 2-0010":0 [ENABLED,IMMUTABLE]
pad1: Source
-> "mtk-cam-dma":0 [ENABLED]
```
If the sensor pad shows `[ENABLED]` and the link to seninf is established, the pipeline is connected.
## How do you capture frames?
List available capture devices:
```bash
v4l2-ctl --list-devices
```
Set the format and query capabilities on the capture device:
```bash
v4l2-ctl -d /dev/video0 --list-formats-ext
v4l2-ctl -d /dev/video0 --set-fmt-video=width=1920,height=1080,pixelformat=NV12
```
Capture a single frame:
```bash
v4l2-ctl -d /dev/video0 --stream-mmap --stream-to=frame.raw --stream-count=1
```
Stream in GStreamer (for `waylandsink` setup details see [GStreamer + waylandsink on Genio](/blog/mediatek-genio-gstreamer-waylandsink-display)):
```bash
export WAYLAND_DISPLAY=wayland-0
gst-launch-1.0 v4l2src device=/dev/video0 \
! video/x-raw,width=1920,height=1080,framerate=30/1,format=NV12 \
! videoconvert \
! waylandsink
```
For a pipeline that also runs AI inference on the camera stream:
```bash
gst-launch-1.0 v4l2src device=/dev/video0 \
! video/x-raw,width=1920,height=1080,framerate=30/1,format=NV12 \
! tee name=t \
t. ! queue ! waylandsink \
t. ! queue ! videoconvert ! appsink name=inference_sink
```
## What are the common camera failures?
| Symptom | Likely cause | Fix |
|---|---|---|
| `/dev/video0` not present | seninf or sensor driver not loaded | Check `dmesg | grep -E "seninf|imx"` |
| `VIDIOC_S_FMT failed` | Pipeline not linked | Run `media-ctl -p` and check link status |
| Black frames | Sensor in reset or no power | Check reset GPIO and power regulators in dmesg |
| Noisy / raw frames | ISP not active (public build) | Use NDA build for ISP processing |
| Wrong resolution | `link-frequencies` mismatch | Match link-frequencies to sensor datasheet value |
| I2C probe fails | Wrong I2C address or wrong bus | Check schematic and verify `reg = ` value |
---
Bringing up a MIPI CSI-2 camera on MediaTek Genio and need help with device tree, sensor driver porting, or ISP integration? [ProventusNova](https://proventusnova.com) has hands-on experience with Genio camera bring-up. See our [CSI camera driver service](/services/csi) or [get in touch](https://proventusnova.com/contact).
---
## TFLite on the MediaTek Genio NPU: Neuron Stable Delegate
URL: https://proventusnova.com/blog/mediatek-genio-on-device-ai-no-cloud/
Published: 2026-06-09
Author: Andres Campos
Tags: mediatek, genio, ai, npu, neuropilot, tflite, onnx, edge ai, on-device
Run TFLite models on the MediaTek Genio NPU with the Neuron Stable Delegate: Python and C++ setup, INT8 quantization, NNStreamer pipelines, benchmarks.
TensorFlow Lite (LiteRT) with the Neuron Stable Delegate is the most mature path to NPU inference on MediaTek Genio. Every Genio SoC above the 350 includes the MDLA (Multi-Dimension Learning Accelerator) NPU, and the delegate routes supported TFLite ops to it without rewriting inference code, entirely on-device, no cloud connectivity required. This post covers the full TFLite path: loading the delegate from Python and C++, quantizing to INT8 for the best NPU performance, running inference inside GStreamer with NNStreamer, and what speedup to expect. For the ONNX Runtime path, see the dedicated [ONNX on the Genio NPU guide](/blog/mediatek-genio-onnx-runtime-neuron).
## Key Insights
- **`NEURON_FLAG_USE_FP16 = "1"` is mandatory** for NPU inference, the MDLA does not support FP32; without this flag models fall back to CPU silently
- **Two NPU paths**: TFLite with Neuron Stable Delegate, and ONNX Runtime with NeuronExecutionProvider, both work; TFLite is more mature
- **Genio 350 has no NPU**: it runs TFLite and ONNX on CPU/GPU only
- **ONNX NeuronExecutionProvider is default only on Genio 520/720**: other platforms need `ENABLE_NEURON_EP = "1"` in the Yocto build
- **CPU fallback is automatic**: ops unsupported by the NPU fall back to CPU within the same inference session; you don't need to handle it manually
## NPU support matrix
| Platform | TFLite (CPU/GPU) | TFLite Neuron Delegate | ONNX CPU | ONNX NeuronEP (NPU) |
|----------|-----------------|------------------------|----------|----------------------|
| Genio 350 | ✅ | ❌ | ✅ | ❌ |
| Genio 510 / 700 | ✅ | ✅ | ✅ | Opt-in¹ |
| Genio 520 / 720 | ✅ | ✅ | ✅ | **Default** |
| Genio 1200 | ✅ | ✅ | ✅ | Opt-in¹ |
¹ Requires `ENABLE_NEURON_EP = "1"` in `local.conf`, then rebuild image.
## TFLite inference with Neuron Stable Delegate
The Neuron Stable Delegate is the TFLite execution delegate that routes supported ops to the NPU.
### Python (recommended for prototyping)
```python
import tflite_runtime.interpreter as tflite
import numpy as np
# Load model with Neuron Stable Delegate for NPU acceleration
interpreter = tflite.Interpreter(
model_path="mobilenet_v2.tflite",
experimental_delegates=[
tflite.load_delegate("libNeuronStableDelegate.so")
]
)
interpreter.allocate_tensors()
# Get input/output details
input_details = interpreter.get_input_details()
output_details = interpreter.get_output_details()
# Prepare input (example: 224x224 RGB image)
input_data = np.expand_dims(image, axis=0).astype(np.float32)
input_data = (input_data / 255.0 - 0.5) / 0.5 # Normalize
# Run inference
interpreter.set_tensor(input_details[0]['index'], input_data)
interpreter.invoke()
# Get output
output = interpreter.get_tensor(output_details[0]['index'])
```
### C++ (production)
```cpp
#include "tensorflow/lite/interpreter.h"
#include "tensorflow/lite/delegates/external/external_delegate.h"
// Build external delegate options for Neuron
TfLiteExternalDelegateOptions opts =
TfLiteExternalDelegateOptionsDefault("libNeuronStableDelegate.so");
auto* delegate = TfLiteExternalDelegateCreate(&opts);
// Build interpreter and add delegate
tflite::ops::builtin::BuiltinOpResolver resolver;
tflite::InterpreterBuilder builder(*model, resolver);
builder.AddDelegate(delegate);
builder(&interpreter);
interpreter->AllocateTensors();
```
## ONNX Runtime with NeuronExecutionProvider
ONNX Runtime runs directly on the NPU through the NeuronExecutionProvider, enabled by default on Genio 520 and 720, opt-in on 510/700/1200 via `ENABLE_NEURON_EP = "1"`. The same `NEURON_FLAG_USE_FP16 = "1"` rule applies, and unsupported ops fall through to XNNPACK or CPU automatically within the session.
We cover the full ONNX path, provider setup, verifying NPU execution, online vs offline (`ncc-tflite`) compilation, the 520/720 distinction, and `neuronrt` benchmarks, in a dedicated guide: **[ONNX Runtime on the MediaTek Genio NPU](/blog/mediatek-genio-onnx-runtime-neuron)**.
## Model requirements for NPU acceleration
The NPU handles most standard CNN ops natively. Limitations to be aware of:
| Op category | NPU support |
|---|---|
| Conv2D, DepthwiseConv2D | ✅ Full |
| BatchNorm, ReLU, ReLU6 | ✅ Full |
| Add, Mul, Concat | ✅ Full |
| LSTM, GRU | ⚠️ Partial (some variants) |
| Transformer attention | ⚠️ Partial |
| Custom ops | ❌ CPU fallback |
| **FP32 weights** | ⚠️ Requires `NEURON_FLAG_USE_FP16=1` to run as FP16 |
| **INT8 quantized** | ✅ Best performance path |
**INT8 quantized models deliver the best NPU performance** and the smallest memory footprint. Use post-training quantization in TFLite or ONNX Runtime's quantization tools before deployment.
### Post-training quantization (TFLite)
```python
import tensorflow as tf
converter = tf.lite.TFLiteConverter.from_saved_model("saved_model/")
converter.optimizations = [tf.lite.Optimize.DEFAULT]
# Representative dataset for calibration
def representative_data_gen():
for sample in calibration_samples:
yield [sample.astype(np.float32)]
converter.representative_dataset = representative_data_gen
converter.target_spec.supported_ops = [tf.lite.OpsSet.TFLITE_BUILTINS_INT8]
converter.inference_input_type = tf.int8
converter.inference_output_type = tf.int8
tflite_model = converter.convert()
with open("model_int8.tflite", "wb") as f:
f.write(tflite_model)
```
## Practical deployment patterns
### Pattern 1: Continuous camera inference
```python
import tflite_runtime.interpreter as tflite
import cv2
# Load model once at startup
interpreter = tflite.Interpreter(
model_path="detect.tflite",
experimental_delegates=[tflite.load_delegate("libNeuronStableDelegate.so")]
)
interpreter.allocate_tensors()
input_details = interpreter.get_input_details()
output_details = interpreter.get_output_details()
# Open camera
cap = cv2.VideoCapture(0)
while True:
ret, frame = cap.read()
if not ret:
break
# Preprocess
resized = cv2.resize(frame, (300, 300))
input_data = np.expand_dims(resized, axis=0).astype(np.uint8)
# Infer
interpreter.set_tensor(input_details[0]['index'], input_data)
interpreter.invoke()
boxes = interpreter.get_tensor(output_details[0]['index'])
scores = interpreter.get_tensor(output_details[2]['index'])
# ... process results
```
### Pattern 2: GStreamer + NNStreamer pipeline
NNStreamer integrates TFLite inference directly into GStreamer pipelines for zero-copy frame processing:
```bash
gst-launch-1.0 \
v4l2src device=/dev/video0 ! \
video/x-raw,format=RGB,width=640,height=480 ! \
videoconvert ! \
tensor_converter ! \
tensor_filter \
framework=tflite \
model=mobilenet_v2_int8.tflite \
accelerator=true:npu ! \
tensor_decoder mode=image_labeling \
option1=labels.txt ! \
overlay ! waylandsink
```
NNStreamer is included in `packagegroup-rity-ai-ml` in the RITY Yocto image.
## Performance benchmarks on Genio 720
Approximate inference times on Genio 720 EVK with INT8 quantized models:
| Model | CPU (ms) | NPU (ms) | Speedup |
|---|---|---|---|
| MobileNetV2 | 45 | 8 | 5.6× |
| EfficientDet-Lite0 | 120 | 22 | 5.5× |
| YOLOv5s INT8 | 210 | 38 | 5.5× |
| BERT-base (text) | 850 | 180 | 4.7× |
NPU inference is 4–6× faster than CPU for typical vision models. Combined with the reduction in CPU load (CPU is free for other work during NPU inference), the real-world benefit is larger than the raw latency numbers suggest.
For the full NeuroPilot stack including Yocto packagegroups and NDA tier features, see [What is RITY? MediaTek's Genio reference distribution explained](/blog/mediatek-genio-rity-rtos-explained). For a complete computer vision pipeline from camera to inference to display, see [MediaTek Genio for computer vision](/blog/mediatek-genio-computer-vision-guide).
## FAQ
### What AI frameworks run on MediaTek Genio NPU?
TensorFlow Lite (LiteRT) via the Neuron Stable Delegate and ONNX Runtime via NeuronExecutionProvider both run on the Genio NPU (MDLA). TFLite is the more mature path. ONNX Runtime with NeuronExecutionProvider is available by default on Genio 520 and 720.
### Do I need cloud connectivity for AI inference on Genio?
No. The NeuroPilot NPU, TFLite, and ONNX Runtime all run entirely on-device. Models run locally with no network required after the model is loaded onto the device.
### What is the NEURON_FLAG_USE_FP16 flag and why is it mandatory?
`NEURON_FLAG_USE_FP16=1` tells the NeuroPilot runtime to execute FP32 model weights as FP16 on the NPU hardware. The Genio MDLA does not natively support FP32 inference, without this flag, FP32 models fail to run on the NPU and fall back to CPU.
### Which Genio platform has the strongest NPU for on-device AI?
Genio 1200 (MT8395) has the highest NPU TOPS. For the single-channel DDR platforms, Genio 720 (MT8391) has the best NPU-to-cost ratio with ONNX NeuronExecutionProvider enabled by default. Genio 350 has no NPU.
### What is the Neuron Stable Delegate?
MediaTek's TFLite external delegate (`libNeuronStableDelegate.so`) that routes supported ops to the Genio NPU at runtime, `tflite.load_delegate()` in Python, `TfLiteExternalDelegateCreate()` in C++. Unsupported ops fall back to CPU automatically.
### Should I use INT8 or FP16 models on the Genio NPU?
INT8 quantized models give the best latency and memory footprint. FP32 runs only as FP16 (`NEURON_FLAG_USE_FP16=1`), the MDLA has no native FP32 path. Quantize to INT8 with a representative calibration set when accuracy allows.
---
---
## Commercializing a product with Ubuntu on MediaTek Genio
URL: https://proventusnova.com/blog/mediatek-genio-ubuntu-commercialization/
Published: 2026-06-09
Author: Aaron Angulo
Tags: mediatek, genio, ubuntu, embedded linux, commercialization, ubuntu pro, snap, ota
Ship a product on Ubuntu on MediaTek Genio. Ubuntu Pro for Devices, snap packaging, OTA updates, Canonical certification, and long-term support.
Ubuntu makes commercial Genio product development accessible to teams without embedded Linux expertise. The Ubuntu BSP from MediaTek gives you hardware acceleration, the familiar `apt` ecosystem, and a known quantity for security updates. The commercialization path, long-term support, update mechanisms, regulatory compliance tooling, is well-defined through Canonical's Ubuntu Pro program.
## Key Insights
- **Ubuntu 22.04 LTS + MediaTek BSP** is the validated starting point, the BSP adds Mali GPU, NeuroPilot NPU, VPU, and camera ISP drivers on top of standard Ubuntu
- **Ubuntu Pro for Devices** extends security updates to 10 years and adds compliance tooling, relevant for products with 5+ year field life
- **Snap packages** are the Canonical-recommended application delivery mechanism for IoT, self-contained, automatically updated, confined
- **EFI capsule updates** in the MediaTek BSP enable firmware-level OTA without a custom bootloader update mechanism
- **Canonical certification** for Genio hardware is available and can be a differentiator for enterprise and industrial buyers
## MediaTek Ubuntu BSP
MediaTek distributes Ubuntu BSP packages for Genio through their partner portal. The BSP adds hardware driver packages on top of a standard Ubuntu 22.04 LTS ARM64 base:
| Package category | What it includes |
|---|---|
| GPU driver | Mali-G57 userspace libraries (EGL, OpenGL ES, OpenCL, Vulkan) |
| VPU | Hardware video decode/encode GStreamer plugins |
| NPU | NeuroPilot runtime (TFLite delegate, ONNX NeuronExecutionProvider) |
| Camera ISP | V4L2 + libcamera integration (public tier) |
| Display | Weston Wayland compositor with Mali acceleration |
| Tools | `genio-flash` firmware update tool |
Installation on a base Ubuntu 22.04 image:
```bash
# Add the MediaTek BSP apt repository
curl -fsSL https://mediatek-iot.ubuntu.com/key.gpg | sudo apt-key add -
echo "deb https://mediatek-iot.ubuntu.com/apt jammy main" | \
sudo tee /etc/apt/sources.list.d/mediatek-iot.list
sudo apt update
sudo apt install mtk-genio-bsp
```
## Ubuntu Pro for Devices
Standard Ubuntu 22.04 LTS support ends April 2027 (5 years). For products that ship today and stay in the field for 5–10 years, **Ubuntu Pro for Devices** is the commercial support tier.
**What Ubuntu Pro for Devices adds:**
| Feature | Standard Ubuntu | Ubuntu Pro for Devices |
|---|---|---|
| Security updates | 5 years | 10 years |
| Kernel live patching | No | Yes (Livepatch) |
| FIPS 140-2 compliance | No | Yes |
| CIS benchmark hardening | No | Tooling included |
| Canonical support SLA | Community | Commercial |
| Extended hardware security | No | Yes (ESM for all packages) |
**Pricing:** Ubuntu Pro for Devices is licensed per device. Contact Canonical for volume pricing. For low-volume products (<1000 units), the cost is typically a few dollars per device per year.
**When you need it:**
- Products with a field life past April 2027 (Ubuntu 22.04 standard EOL)
- Industrial, medical, or defense applications with compliance requirements (FIPS, IEC 62443)
- Products sold to enterprise buyers who require documented security maintenance
```bash
# Enable Ubuntu Pro on a deployed device
ubuntu-pro attach
ubuntu-pro status
```
## Application packaging with snap
Snap is Canonical's containerized application format for IoT. A snap is a compressed filesystem image with a manifest that defines interfaces (hardware access, network, files). Snap applications update automatically from the Snap Store or a private Snap Store.
### Why snap for IoT products
- **Self-contained**: all dependencies bundled, no apt dependency drift
- **Automatic updates**: devices check for updates on a schedule; rollback is automatic on failure
- **Confined**: snap interfaces control exactly what hardware and system resources the app can access
- **Private Snap Store**: for commercial products, a private store allows controlled deployments to registered devices only
### Build a snap for your Genio app
`snapcraft.yaml` at the root of your project:
```yaml
name: my-genio-app
base: core22
version: "1.0"
summary: My Genio application
description: |
Production app for Genio deployment
grade: stable
confinement: strict
parts:
my-app:
plugin: python
source: .
python-packages:
- numpy
- tflite-runtime
apps:
my-genio-app:
command: bin/my-app
daemon: simple
restart-condition: always
plugs:
- hardware-observe
- raw-usb
- camera
```
Build and install:
```bash
# Install snapcraft
snap install snapcraft --classic
# Build for arm64
snapcraft --target-arch arm64
# Install on device
snap install my-genio-app_1.0_arm64.snap --dangerous
```
### Private Snap Store setup
For a commercial product, you want control over which snap version is on which device. Canonical's IoT App Store (branded Snap Store) provides:
- Private channel management (stable/candidate/beta/edge)
- Device serial assertions for fleet management
- Over-the-air update control per device group
Contact Canonical to set up a private store. The setup involves registering your Genio device model and installing an IoT gateway snap.
## Ubuntu Core vs Ubuntu Server: which base should a Genio product ship?
Once snaps enter the picture, the next question is whether to go all the way: Ubuntu Core is Canonical's all-snap OS, where the kernel, the base system, and every application are snaps with transactional, automatically-rolled-back updates and strict confinement by default. It is a genuinely good fit for unattended fleets, and it comes with its own 10-year support window.
For Genio specifically, the honest picture has a constraint in the middle of it: **MediaTek's hardware enablement ships as apt packages.** The video codec daemons, GStreamer patches, and NPU runtime arrive through the `genio-public` PPA as debs on classic Ubuntu. That is what this whole post has assumed, and it is the path MediaTek documents and tests.
Putting Ubuntu Core on a Genio product therefore is not a flag flip; it is a porting project. Core requires the board's kernel as a kernel snap and the boot/partition specifics as a gadget snap, and the BSP userspace (codec daemons, NPU runtime) has to be repackaged into snaps with the right interfaces. All of it is doable, none of it is vendor-provided today.
Our recommendation pattern:
- **Ubuntu Server (classic) + your application as a snap** is the pragmatic default: you keep MediaTek's documented BSP path, apt for the hardware layer, and still get confined, auto-updating application delivery. Pair it with Ubuntu Pro for the 10-year window.
- **Ubuntu Core** earns its porting cost when the product is a locked-down appliance at fleet scale, where transactional OS updates, rollback, and strict confinement are requirements rather than preferences, and you have (or hire) the engineering to own kernel and gadget snaps for the board.
- If what you actually want from Core is "immutable OS with A/B updates" and you are already deep in kernel customization, compare against the Yocto route with a standard A/B update stack before committing either way; see [Ubuntu vs Yocto on Genio](/blog/mediatek-genio-ubuntu-vs-yocto).
## OTA firmware updates (EFI capsule)
The MediaTek Ubuntu BSP includes EFI capsule update support, which is the standard mechanism for updating U-Boot, TF-A, and the kernel from userspace without special recovery tooling.
```bash
# Install fwupd (EFI capsule update client)
apt install fwupd
# Check device firmware information
fwupdmgr get-devices
# Refresh firmware metadata
fwupdmgr refresh
# Install pending firmware updates
fwupdmgr update
```
For custom firmware images, create a capsule file from your BSP output:
```bash
# Generate capsule (MediaTek provides a capsule generation script in the BSP)
./gen_capsule.sh \
--input build/output/bl2.bin \
--guid \
--output my-firmware.cap
# Deploy to device
fwupdmgr install my-firmware.cap --allow-older
```
## Canonical hardware certification
Canonical's Ubuntu Certified Hardware program validates that Ubuntu runs correctly on a specific hardware platform. Certification is available for commercial Genio products.
**Benefits of certification:**
- Listed on ubuntu.com/certified (searchable by enterprise buyers)
- Canonical validates that Ubuntu updates don't break your hardware
- Required by some enterprise procurement processes
**The certification process:**
1. Run the Ubuntu Hardware Certification Test Suite on your board
2. Submit results to Canonical
3. Canonical reviews and issues certification
4. Certification is listed against your specific Ubuntu version
For products built on the Genio EVK with the MediaTek Ubuntu BSP, the base hardware is already certified, you may only need to certify carrier board modifications.
## Security hardening checklist for Ubuntu on Genio
Before shipping:
```bash
# 1. Disable root SSH login
sed -i 's/PermitRootLogin yes/PermitRootLogin no/' /etc/ssh/sshd_config
# 2. Enable UFW firewall
ufw enable
ufw default deny incoming
ufw allow ssh
# 3. Enable automatic security updates
apt install unattended-upgrades
dpkg-reconfigure unattended-upgrades
# 4. Remove development tools from production image
apt remove --purge build-essential gcc make git
# 5. Enable AppArmor
systemctl enable apparmor
systemctl start apparmor
```
For comparison with the Yocto-based approach and guidance on which to choose for your project, see [Ubuntu vs Yocto on MediaTek Genio](/blog/mediatek-genio-ubuntu-vs-yocto). For on-device AI deployment that works on both Ubuntu and Yocto, see [on-device AI without the cloud on Genio](/blog/mediatek-genio-on-device-ai-no-cloud).
## FAQ
### Can I ship a commercial product using Ubuntu on MediaTek Genio?
Yes. Ubuntu is commercially viable for embedded products. Canonical and MediaTek have a partnership that includes Ubuntu BSP support for Genio. For products requiring 10-year security support, Ubuntu Pro for Devices is the commercial offering.
### What is Ubuntu Pro for Devices and do I need it?
Ubuntu Pro for Devices extends Ubuntu LTS security updates from 5 years to 10 years and adds kernel live patching and compliance tooling. You need it if your product has a field life beyond 5 years or if your industry requires certified security maintenance.
### How do I update software on a shipped Genio Ubuntu product?
Snap packages with automatic updates are the recommended path for Canonical-supported IoT products. Alternatively, use apt with a private package mirror for controlled updates. The MediaTek Ubuntu BSP includes EFI capsule update support for firmware-level updates.
### Does MediaTek provide Ubuntu BSP support for all Genio platforms?
MediaTek provides Ubuntu BSP packages for Genio 510, 520, 700, 720, and 1200 targeting Ubuntu 22.04 LTS. Genio 350 and 360 have limited or community-only Ubuntu support.
---
---
## Ubuntu vs Yocto on MediaTek Genio: which to choose
URL: https://proventusnova.com/blog/mediatek-genio-ubuntu-vs-yocto/
Published: 2026-06-09
Author: Andres Campos
Tags: mediatek, genio, ubuntu, yocto, embedded linux, bsp, product development
Compare Ubuntu and Yocto for MediaTek Genio. Development speed, image size, BSP support, commercialization, and which fits your project stage and team.
Both Ubuntu and Yocto run well on MediaTek Genio. MediaTek provides BSP packages for both. The choice comes down to your team's workflow, your product's size constraints, and where you are in the development cycle. Getting this decision wrong early costs time, switching from Ubuntu to Yocto mid-project is a significant effort.
## Key Insights
- **Ubuntu is faster to start**: flash the BSP image, install packages with `apt`, and you're coding in hours instead of days
- **Yocto produces smaller, more controlled images**: no package manager at runtime, only what you explicitly include
- **MediaTek supports both**: Ubuntu 22.04 LTS BSP and the IoT Yocto BSP are both maintained by MediaTek; neither is second-class
- **Prototype on Ubuntu, ship on Yocto** is a common and reasonable pattern, the hardware drivers work the same on both
- **Ubuntu Pro for Devices** extends LTS support to 10 years, relevant for products with 5+ year field life
- **Yocto's learning curve is real**: a team without Yocto experience will take weeks to get productive
## What each OS gives you
### Ubuntu on Genio
MediaTek's Ubuntu BSP ships a standard Ubuntu 22.04 LTS image with hardware-accelerated driver packages installed on top. It behaves exactly like Ubuntu on any ARM64 server, `apt`, `systemd`, familiar package names, standard paths.
What the MediaTek Ubuntu BSP adds over plain Ubuntu:
- Mali GPU driver (`mali-t83x-rk-dkms` equivalent for Genio)
- NeuroPilot NPU runtime (TFLite delegate, ONNX NeuronExecutionProvider)
- GStreamer plugins for hardware video encode/decode (VPU)
- Camera ISP driver packages (public; NDA tier for full RAW pipeline)
- `genio-flash` tool for firmware updates
Getting started is fast:
```bash
# Flash Ubuntu BSP image (from MediaTek partner portal)
genio-flash --board-config boards/genio-720-evk.yaml
# SSH in and install packages
apt update
apt install python3-numpy python3-opencv gstreamer1.0-tools
```
### Yocto on Genio
The IoT Yocto BSP (RITY) produces custom Linux images with exactly the packages you specify. The build system resolves dependencies, cross-compiles everything, and produces a flashable image.
What Yocto gives you that Ubuntu doesn't:
- **No runtime package manager**: the final image has no `apt`, no package database, no updatable dependency tree
- **Bit-for-bit reproducibility**: same inputs always produce the same image
- **Full control over rootfs contents**: every file in the image came from a recipe you can inspect
- **Cross-compilation for everything**: the build runs on x86 but produces ARM64 binaries
- **sstate-cache**: incremental builds reuse previously built artifacts; rebuilding after a single change takes minutes, not hours
## Side-by-side comparison
| | Ubuntu | Yocto |
|---|---|---|
| **First boot time** (from flash to working system) | Hours | Days to weeks (first build) |
| **Package management** | `apt` | BitBake recipes + sstate-cache |
| **Rootfs size** | 2–8GB typical | 150MB–1GB depending on config |
| **Runtime package manager** | Yes (apt) | No (by default) |
| **Driver support** | MediaTek Ubuntu BSP packages | RITY / meta-mediatek-bsp |
| **Security updates** | `apt upgrade` | Rebuild + reflash |
| **Learning curve** | Low (standard Linux) | High (Yocto-specific tooling) |
| **Build reproducibility** | No (apt versions drift) | Yes (pinned layer refspecs) |
| **CI/CD integration** | Standard | Yocto-specific pipelines |
| **Commercial support** | Canonical + MediaTek | MediaTek (BSP) + community |
| **Best for** | Prototyping, software-heavy products | Production, constrained hardware |
## When to choose Ubuntu
**Choose Ubuntu when:**
- Your team doesn't have embedded Linux or Yocto experience
- You're in the prototype or MVP phase and need to move fast
- Your product runs on a board with enough storage that image size doesn't matter (eMMC 32GB+)
- You need to use standard Linux tooling (pip, apt, Docker from Ubuntu packages)
- The product ships with an application that updates frequently and uses `apt` for updates
- Your development timeline is weeks, not months
**Real example:** A computer vision startup building a Genio-based smart camera for retail analytics. The team knows Python and OpenCV well but has no Yocto experience. They prototype on Ubuntu, use `apt install python3-opencv`, iterate on the CV pipeline, and ship on Ubuntu for the first product revision. They plan a Yocto migration for v2.
## When to choose Yocto
**Choose Yocto when:**
- Your product ships to thousands of units and image size and boot time matter
- You need a hardened, minimal image, no unused binaries, no package manager attack surface
- Your update strategy requires bit-for-bit reproducible builds for rollback verification
- You're building on top of existing Yocto infrastructure in your organization
- The product has a 5+ year field life and you need controlled BSP maintenance
- Your team has Yocto experience or budget to build it
**Real example:** A robotics company shipping Genio-based perception modules in industrial equipment. 8GB eMMC, custom carrier board, 7-year support requirement. They use Yocto with a custom meta layer, a locked-down RITY-derived image, and an OTA update system built on EFI capsule updates.
## The prototype-on-Ubuntu, ship-on-Yocto pattern
This is the most common path for serious Genio products:
1. **Ubuntu phase (weeks 1–8):** Flash the MediaTek Ubuntu BSP, develop the application, validate that all hardware features (camera, NPU, GPU, display) work with your use case. Fix application-level bugs.
2. **Yocto migration (weeks 9–16):** Set up the RITY Yocto build, create a custom meta layer, port the application into Yocto recipes or containerize it, test on hardware.
3. **Production hardening (weeks 17+):** Strip unused packages, configure secure boot, set up OTA update pipeline, lock BSP refspecs.
The hardware drivers work identically on both, the porting effort is the application packaging and init system integration, not the driver layer. Plan for 2–4 weeks of Yocto migration work for a non-trivial application.
## BSP availability
| OS | BSP Source | JetPack/version equivalent |
|---|---|---|
| Ubuntu 22.04 LTS | MediaTek partner portal | Maintained per Genio SDK release |
| Yocto scarthgap | MediaTek GitLab (public + NDA) | Same SDK, different packaging |
Both BSPs track the same Genio SDK release cadence. A feature added in SDK 23.1 appears in both the Ubuntu BSP packages and the updated RITY layers at the same time.
For Ubuntu-specific commercialization details including Ubuntu Pro for Devices, see [commercializing a product with Ubuntu on Genio](/blog/mediatek-genio-ubuntu-commercialization). For the full Yocto build setup, see [Yocto build guide for MediaTek Genio](/blog/mediatek-genio-yocto-build-guide).
## The AI-stack difference nobody mentions
If your product uses the NPU, the OS choice is not neutral. Canonical's Ubuntu images for Genio ship the NPU driver and the TFLite path, but the full NeuroPilot tooling, ONNX Runtime NeuronExecutionProvider builds and the `ncc-tflite` offline compiler, is validated against the Yocto/RITY stack. If your inference pipeline depends on [ONNX on the NPU](/blog/mediatek-genio-onnx-runtime-neuron) or [offline model compilation](/blog/mediatek-genio-inference-offline-neuropilot), plan for Yocto in production or verify your exact path on Ubuntu early, not after the prototype works. The [TFLite/Neuron Stable Delegate path](/blog/mediatek-genio-on-device-ai-no-cloud) is the most portable across both.
## FAQ
### Does MediaTek officially support Ubuntu on Genio?
Yes. MediaTek and Canonical have a partnership for Ubuntu on Genio. MediaTek provides an Ubuntu BSP with hardware drivers for the Mali GPU, VPU, camera ISP, and NeuroPilot NPU. Ubuntu 22.04 LTS is the supported release for most current Genio platforms.
### Is Yocto or Ubuntu better for a production Genio product?
Yocto is better for most production products: smaller image, no runtime package manager, full control over every installed file, and reproducible builds. Ubuntu is better when your team needs faster iteration, uses apt-based tooling, or when image size is not constrained.
### Can I prototype on Ubuntu and ship on Yocto?
Yes, and this is a common pattern. Prototype on Ubuntu for fast iteration, validate the application and BSP, then port to Yocto for production. The hardware drivers work the same on both.
### How long does Ubuntu LTS support last for Genio products?
Ubuntu 22.04 LTS has 5 years of standard support (until April 2027) and 10 years with Ubuntu Pro (until April 2032). Ubuntu Pro for Devices extends this further for IoT deployments.
---
---
## Building a custom Yocto meta layer for MediaTek Genio
URL: https://proventusnova.com/blog/mediatek-genio-custom-yocto-meta-layer/
Published: 2026-06-08
Author: Aaron Angulo
Tags: mediatek, genio, yocto, meta-layer, embedded linux, bitbake, device tree, bsp
Create a custom Yocto meta layer for MediaTek Genio. layer.conf, kernel bbappend, DTS overlays, machine config, custom distro, and the RITY skeleton pattern.
Every Genio product that ships needs a custom Yocto layer for board-specific changes: kernel patches, device tree modifications, machine configuration, and product-specific packages. Putting these changes directly in `meta-mediatek-bsp` or `meta-rity` creates merge conflicts on every BSP update. A custom layer keeps your changes isolated and auditable.
## Key Insights
- **`conf/layer.conf` is the only required file**: without it, BitBake ignores the directory entirely
- **bbappend files are the right tool** for modifying upstream recipes, never edit source recipes in other layers
- **Scope SRC_URI patches to your machine name**: `SRC_URI:append:my-machine` prevents your DTS patch from applying to EVK builds
- **RITY skeleton (`meta-rity-skeleton`) is the correct starting point**: copy it rather than starting from scratch
- **Layer priority 9** overrides base RITY (8) and BSP (7), use it consistently across your custom layers
- **Use `LAYERSERIES_COMPAT = "scarthgap"`**: build fails at layer parse time if your Yocto version isn't listed
## Step 1: Create the layer structure
```bash
mkdir meta-myproduct
cd meta-myproduct
git init
# Minimum required structure
mkdir -p conf
touch conf/layer.conf
```
The directory name conventionally starts with `meta-`. It can be anything, but `meta-` is standard.
## Step 2: Write conf/layer.conf
This is the file BitBake checks first. Every field is required:
```bitbake
BBPATH .= ":${LAYERDIR}"
BBFILES += "${LAYERDIR}/recipes-*/*/*.bb \
${LAYERDIR}/recipes-*/*/*.bbappend"
BBFILE_COLLECTIONS += "myproduct"
BBFILE_PATTERN_myproduct = "^${LAYERDIR}/"
BBFILE_PRIORITY_myproduct = "9"
LAYERVERSION_myproduct = "1"
LAYERDEPENDS_myproduct = "rity core mediatek-bsp"
LAYERSERIES_COMPAT_myproduct = "scarthgap"
```
Key notes:
- `BBPATH .=`, note the `.=` and the leading `:`. This appends to the existing path. Using `=` instead breaks all other layers.
- `BBFILE_COLLECTIONS`, short identifier, no hyphens. Used internally by BitBake for priority resolution.
- `BBFILE_PRIORITY`, integer. 9 overrides RITY (8) and the MediaTek BSP (7). Use 9 for your product layer consistently.
- `LAYERDEPENDS`, lists layers this layer requires. Build fails at parse time if a dependency is missing.
- `LAYERSERIES_COMPAT`, space-separated. Build fails if the current Yocto version isn't in this list.
## Step 3: Add the layer to bblayers.conf
```bitbake
BBLAYERS += " \
${BSPDIR}/sources/meta-myproduct \
"
```
Layer order in `BBLAYERS` matters when priorities are equal, later entries win. Since your layer is priority 9, order is less critical, but put it after all MediaTek layers.
## Step 4: Machine configuration
Create a machine config that inherits from the appropriate SoC include:
```bash
mkdir -p conf/machine
```
```bitbake
# conf/machine/my-carrier-board.conf
require conf/machine/include/mt8391.inc # For Genio 520/720 SoC
KERNEL_DEVICETREE = "mediatek/my-carrier.dtb"
UBOOT_MACHINE = "my_carrier_defconfig"
MACHINE_FEATURES:append = " \
alsa bluetooth pci usbgadget usbhost wifi tsn \
"
MACHINEOVERRIDES =. "my-carrier-board:"
```
SoC include mapping:
| SoC | Include file |
|-----|-------------|
| MT8391 (Genio 720) | `mt8391.inc` |
| MT8371 (Genio 520) | `mt8391.inc` (same footprint) |
| MT8390 (Genio 700) | `mt8188.inc` |
| MT8370 (Genio 510) | `mt8188.inc` |
| MT8395 (Genio 1200) | `mt8395.inc` |
## Step 5: Kernel bbappend for patches and config fragments
```bash
mkdir -p recipes-kernel/linux
```
```bitbake
# recipes-kernel/linux/linux-mtk_%.bbappend
FILESEXTRAPATHS:prepend := "${THISDIR}/${PN}:"
# Only apply to your carrier board, not to EVK builds
SRC_URI:append:my-carrier-board = " \
file://0001-my-carrier-spi1-enable.patch \
file://my-carrier.cfg \
"
```
The `%` wildcard in `linux-mtk_%.bbappend` matches any version of the kernel recipe. `FILESEXTRAPATHS:prepend` tells BitBake to look in your `recipes-kernel/linux/linux-mtk/` directory for the patch files.
Generate the patch from your kernel source tree after making changes:
```bash
cd kernel-source
git diff arch/arm64/boot/dts/mediatek/mt8391-my-carrier.dts > \
../meta-myproduct/recipes-kernel/linux/linux-mtk/0001-my-carrier-spi1-enable.patch
```
## Step 6: DTS overlays
For overlay-based DTS (DTBO), add the overlay file and extend the DTBO recipe:
```bash
mkdir -p recipes-kernel/dtbo
```
```bitbake
# recipes-kernel/dtbo/dtbo.bbappend
FILESEXTRAPATHS:prepend := "${THISDIR}/${PN}:"
SRC_URI:my-carrier-board += " \
file://my-display.dts \
"
```
Use `SRC_URI:machine` (not `SRC_URI:append`) for overlays to keep them machine-scoped. The base DTBO recipe handles compilation and installation.
## Step 7: Custom distro (optional)
If you need to change `DISTRO_FEATURES` or add product-specific configuration:
```bash
mkdir -p conf/distro
```
```bitbake
# conf/distro/my-product-distro.conf
require conf/distro/rity.inc
DISTRO = "my-product-distro"
DISTRO_NAME = "My Product"
DISTRO_VERSION = "1.0"
# Add or remove features from base RITY
DISTRO_FEATURES:append = " virtualization"
DISTRO_FEATURES:remove = "x11"
```
Activate in `local.conf`:
```bitbake
DISTRO = "my-product-distro"
```
## Using the RITY skeleton pattern
`meta-rity-skeleton` in the RITY repo is a minimal template layer for exactly this use case. Clone it as your starting point:
```bash
# From within the RITY repo
cp -r meta-rity-skeleton ../../meta-myproduct
cd ../../meta-myproduct
# Update these in conf/layer.conf:
# - BBFILE_COLLECTIONS (change "rity-custom" to "myproduct")
# - BBFILE_PATTERN_* (match the new collection name)
# - LAYERDEPENDS (keep "rity core mediatek-bsp" at minimum)
```
The skeleton includes a machine config template, distro template, and example bbappend structure. It avoids the common mistake of copying too much from `meta-rity` itself.
## Common patterns
### Add product-specific packages
```bitbake
# recipes-myproduct/packagegroup-myproduct/packagegroup-myproduct.bb
DESCRIPTION = "My product runtime packages"
inherit packagegroup
RDEPENDS:${PN} = " \
my-app \
my-config \
python3-mylib \
"
```
```bitbake
# In your image or local.conf
IMAGE_INSTALL:append = " packagegroup-myproduct"
```
### Override a RITY recipe
```bitbake
# recipes-connectivity/wpa-supplicant/wpa-supplicant_%.bbappend
# Add your site-specific wpa_supplicant.conf
FILESEXTRAPATHS:prepend := "${THISDIR}/${PN}:"
SRC_URI:append:my-carrier-board = " file://wpa_supplicant.conf"
```
### Increase rootfs size
```bitbake
# conf/machine/my-carrier-board.conf
IMAGE_ROOTFS_EXTRA_SPACE = "2097152" # 2GB extra in KB
```
For the full RITY layer structure that your custom layer builds on top of, see [What is RITY? MediaTek's Genio reference distribution explained](/blog/mediatek-genio-rity-rtos-explained). For the full Yocto build workflow, see [Yocto build guide for MediaTek Genio](/blog/mediatek-genio-yocto-build-guide).
## FAQ
### What is the minimum required file for a Yocto meta layer?
A Yocto meta layer requires only `conf/layer.conf`. Without it, BitBake does not recognize the directory as a layer. The `layer.conf` must set `BBPATH`, `BBFILES`, `BBFILE_COLLECTIONS`, `BBFILE_PATTERN`, `BBFILE_PRIORITY`, `LAYERVERSION`, and `LAYERSERIES_COMPAT`.
### Should I modify meta-rity directly or create a custom layer?
Always create a custom layer. Use bbappend files to extend or override recipes. Direct modifications to upstream layers create merge conflicts on every BSP update.
### How do I apply a kernel DTS patch for a custom carrier board in Yocto?
Create a `linux-mtk_%.bbappend` in your layer's `recipes-kernel` directory. Add `FILESEXTRAPATHS:prepend` to point at your patch directory and scope the patch to your machine name with `SRC_URI:append:my-machine`.
### What is the RITY skeleton pattern for custom products?
`meta-rity-skeleton` is a minimal template layer in the RITY repo. Copy it, rename it, update `conf/layer.conf` with your collection name and layer dependencies, and add your product-specific recipes.
---
---
## Docker with GPU acceleration on MediaTek Genio
URL: https://proventusnova.com/blog/mediatek-genio-docker-gpu-containers/
Published: 2026-06-08
Author: Aaron Angulo
Tags: mediatek, genio, docker, gpu, yocto, mali, containers, embedded linux
Run GPU-accelerated Docker containers on MediaTek Genio. Add meta-virtualization to Yocto, pass Mali GPU and peripherals, and run inference in containers.
Docker on MediaTek Genio lets you isolate workloads, ship reproducible application environments, and run inference pipelines alongside BSP services without polluting the root filesystem. The setup requires adding `meta-virtualization` to your Yocto build, it is not included in the default RITY image. GPU passthrough for Mali acceleration takes one extra step: device nodes and matching userspace libraries must be visible inside the container.
## Key Insights
- **`meta-virtualization` is the layer to add**: it provides `docker-ce`, `containerd`, and `runc` for Yocto scarthgap; it is not in the default RITY stack
- **Mali GPU passthrough requires two things**: the `/dev/mali0` device node and matching Mali userspace libraries inside the container
- **NPU (MDLA) in containers is possible but version-sensitive**: the NeuroPilot runtime inside the container must match the `apusys` kernel driver on the host
- **SPI, I2C, and GPIO devices pass through cleanly**: use `--device` flags or the `devices:` key in Docker Compose
- **Privileged mode is a shortcut, not a solution**: `--privileged` works but exposes all host devices; prefer explicit device passthrough in production
## Adding Docker to a Genio Yocto image
### Step 1: Add meta-virtualization to bblayers.conf
```bash
git clone https://github.com/openembedded/meta-virtualization.git \
-b scarthgap sources/meta-virtualization
```
Add to `conf/bblayers.conf`:
```bitbake
BBLAYERS += " \
${BSPDIR}/sources/meta-virtualization \
"
```
### Step 2: Enable virtualization DISTRO_FEATURE
In `conf/local.conf` or your custom distro conf:
```bitbake
DISTRO_FEATURES:append = " virtualization"
```
This flag gates the cgroup v2, namespace, and overlay filesystem support that Docker depends on. Without it, Docker starts but container creation fails with cgroup errors.
### Step 3: Add Docker to IMAGE_INSTALL
```bitbake
IMAGE_INSTALL:append = " \
docker-ce \
docker-ce-cli \
containerd \
runc \
python3-docker \
"
```
For a minimal setup using only `containerd` and `nerdctl` (lighter than full Docker CE):
```bitbake
IMAGE_INSTALL:append = " containerd nerdctl"
```
### Step 4: Enable required kernel config
The Genio kernel config includes most required options, but verify these are set:
```bash
# Check from build directory
grep -E "CGROUPS|NAMESPACES|OVERLAY_FS|VETH" \
tmp/work/-poky-linux/linux-mtk/*/build/.config
```
Critical options:
| Config | Required for |
|---|---|
| `CONFIG_CGROUPS=y` | Container resource limits |
| `CONFIG_CGROUP_DEVICE=y` | Device cgroup (device whitelist) |
| `CONFIG_NAMESPACES=y` | Process/network/mount isolation |
| `CONFIG_OVERLAY_FS=y` | Union filesystem for container layers |
| `CONFIG_VETH=y` | Virtual Ethernet for container networking |
| `CONFIG_BRIDGE=y` | Docker bridge network (docker0) |
All of these are enabled in the default Genio kernel config. If you have a heavily stripped custom config, re-enable them.
### Step 5: Verify Docker starts on the board
```bash
# Check Docker daemon
systemctl status docker
# Run a test container (CPU only)
docker run --rm busybox echo "Docker is working"
# Check container runtime info
docker info | grep -E "Runtime|Driver|Cgroup"
```
## Mali GPU passthrough
The Genio Mali GPU (Mali-G57) appears as `/dev/mali0` on the target. Passing it to a container requires:
1. The device node
2. The Mali userspace libraries (EGL, OpenCL, OpenGL ES) that match the kernel driver
### Basic GPU passthrough
```bash
docker run --rm \
--device /dev/mali0:/dev/mali0 \
--device /dev/dri:/dev/dri \
your-image:latest
```
### Docker Compose
```yaml
services:
app:
image: your-image:latest
devices:
- "/dev/mali0:/dev/mali0"
- "/dev/dri:/dev/dri"
volumes:
- "/dev/dri:/dev/dri"
```
### Mali libraries inside the container
The Mali userspace libraries (`libmali.so`, EGL, OpenGL ES, OpenCL) must be present inside the container and must match the kernel driver version. The safest approach is to build your container image from the same Genio rootfs tarball:
```dockerfile
FROM scratch
ADD genio-rootfs.tar.gz /
# Your app layers on top
```
Alternatively, copy the Mali libraries from the host into the container at runtime using a volume mount:
```bash
docker run --rm \
--device /dev/mali0:/dev/mali0 \
-v /usr/lib/libmali.so:/usr/lib/libmali.so:ro \
-v /usr/lib/aarch64-linux-gnu/libEGL.so:/usr/lib/aarch64-linux-gnu/libEGL.so:ro \
your-image:latest
```
Version mismatch between the host driver and container userspace libraries produces `MALI: mali_kbase_open: version mismatch` errors in dmesg.
## NPU (MDLA / NeuroPilot) in containers
NPU acceleration from within a container requires passing the APUSys device nodes:
```bash
docker run --rm \
--device /dev/mali0:/dev/mali0 \
--device /dev/apusys:/dev/apusys \
--device /dev/mtk_mdla0:/dev/mtk_mdla0 \
your-inference-image:latest python3 run_model.py
```
The NeuroPilot runtime (`libNeuronRuntime.so`) inside the container must match the `apusys.ko` driver version loaded on the host. Check the host driver version:
```bash
cat /sys/kernel/debug/apusys/version
# Or check the loaded module
modinfo apusys | grep version
```
For TFLite CPU inference (no NPU), no special devices are needed, TFLite runs entirely in userspace:
```bash
docker run --rm your-inference-image:latest python3 -c "
import tflite_runtime.interpreter as tflite
interp = tflite.Interpreter('model.tflite')
interp.allocate_tensors()
print('TFLite loaded OK')
"
```
## Peripheral device passthrough
All peripheral devices on Genio follow the same pattern: pass the device node with `--device`:
```yaml
# docker-compose.yml
services:
app:
image: your-image:latest
devices:
- "/dev/mali0:/dev/mali0" # Mali GPU
- "/dev/apusys:/dev/apusys" # APU/NPU
- "/dev/spidev1.0:/dev/spidev1.0" # SPI
- "/dev/gpiochip0:/dev/gpiochip0" # GPIO
- "/dev/i2c-0:/dev/i2c-0" # I2C bus 0
- "/dev/video0:/dev/video0" # V4L2 camera
```
For camera pipelines using GStreamer inside a container, also mount the V4L2 and DRM devices and pass the Wayland socket if display output is needed:
```bash
docker run --rm \
--device /dev/video0:/dev/video0 \
--device /dev/dri:/dev/dri \
--device /dev/mali0:/dev/mali0 \
-v /run/user/0/wayland-0:/run/user/0/wayland-0 \
-e WAYLAND_DISPLAY=wayland-0 \
-e XDG_RUNTIME_DIR=/run/user/0 \
your-gstreamer-image:latest gst-launch-1.0 v4l2src ! waylandsink
```
## Common issues
**`docker: Error response from daemon: cgroups: cgroup mountpoint does not exist`**
cgroup v2 isn't mounted. Add to `/etc/fstab`: `cgroup2 /sys/fs/cgroup cgroup2 defaults 0 0` and remount. Or set `GRUB_CMDLINE_LINUX="systemd.unified_cgroup_hierarchy=1"` in the kernel command line.
**`MALI: mali_kbase_open: version mismatch`**
Mali userspace version in the container doesn't match the kernel driver. Use Mali libraries from the same BSP build.
**`/dev/mali0: no such file or directory` inside container**
Forgot `--device /dev/mali0`. The device node must be explicitly passed, it won't appear just because the container has root access.
**`apusys: failed to open device`**
APUSys device not passed, or kernel driver not loaded. Check `lsmod | grep apusys` on the host first.
For the Yocto layer setup that supports Docker on Genio, see [Yocto build guide for MediaTek Genio](/blog/mediatek-genio-yocto-build-guide). For adding custom Yocto layers on top of the RITY stack, see [building a custom Yocto meta layer for Genio](/blog/mediatek-genio-custom-yocto-meta-layer).
## FAQ
### Does Docker work on MediaTek Genio with Yocto?
Yes. Add `meta-virtualization` to your Yocto layer stack, add `virtualization` to `DISTRO_FEATURES`, and include `docker-ce` or `containerd` in `IMAGE_INSTALL`. Docker runs on top of the Linux kernel, Genio's kernel config includes the necessary cgroup and namespace support.
### How do I pass the Mali GPU into a Docker container on Genio?
Pass `/dev/mali0` as a device in your docker run command or compose file: `--device /dev/mali0:/dev/mali0`. Also pass `/dev/dri` if using DRM. The container process needs the same Mali userspace libraries as the host, use the same base rootfs or copy the Mali libs into the container image.
### Can I run AI inference in a Docker container on Genio?
Yes, with limitations. TFLite CPU inference works out of the box. NPU acceleration requires passing `/dev/apusys` and related firmware devices, and the NeuroPilot runtime inside the container must match the kernel driver version on the host.
### Which Yocto layer provides Docker for Genio?
`meta-virtualization` (from OpenEmbedded) provides the `docker-ce`, `containerd`, and `runc` recipes. Add it to `bblayers.conf` and add `virtualization` to `DISTRO_FEATURES`. It is compatible with the Yocto scarthgap release used by the MediaTek IoT Yocto BSP.
---
---
## What is RITY? MediaTek's Genio reference distribution explained
URL: https://proventusnova.com/blog/mediatek-genio-rity-rtos-explained/
Published: 2026-06-08
Author: Andres Campos
Tags: mediatek, genio, rity, yocto, embedded linux, bsp, aiot
RITY is MediaTek's reference Yocto distribution for Genio. Distro variants, layer structure, packagegroups, KAS build system, and what RITY is not.
RITY is the name MediaTek gives to their reference Yocto distribution for Genio AIoT boards. The name stands for Reference Implementation of Things in Yocto. It is not an RTOS, it is a standard Linux distribution that demonstrates how all of MediaTek's hardware IP blocks (GPU, NPU, VPU, camera ISP, audio) integrate into a complete Yocto image. Understanding RITY is the fastest way to understand how a production Genio image should be structured.
## Key Insights
- **RITY is not an RTOS**: it is a Yocto-based Linux distribution; the name causes consistent confusion
- **Three useful distro variants**: `rity-bringup` (minimal debug), `rity-demo` (full-featured), `rity-skeleton` (custom derivative template)
- **Packagegroup architecture** keeps hardware IP isolated, each MediaTek feature is in its own packagegroup, which makes it easy to include or exclude
- **KAS is the build tool**: `kas build kas/rity-demo.yml` is the single command that fetches all 8+ layer repos and builds the image
- **`nda-mtk` DISTRO_FEATURE** is the gate for proprietary content, ISP, NeuroPilot, and hardware codecs require it
- **`rity-skeleton` is the right starting point** for custom products, never modify `meta-rity` directly
## What RITY actually is
RITY is a collection of Yocto layers hosted on MediaTek's GitLab that demonstrate the full Genio software stack. It sits on top of:
- `poky`, Yocto reference distribution
- `meta-openembedded`, community package collection
- `meta-arm`, ARM toolchain and firmware
- `meta-mediatek-bsp`, MediaTek's hardware drivers and firmware
RITY adds the integration layer on top: it knows which MediaTek firmware files belong together, which GStreamer plugins work with the VPU, and how to assemble a working Wayland display stack with the Mali GPU.
## Layer structure
```
meta-rity/
├── kas/ # KAS YAML build configurations
├── meta/ # Base RITY layer (priority 8)
├── meta-rity-bringup/ # Minimal bringup variant (priority 9)
├── meta-rity-demo/ # Full demo variant (priority 9)
└── meta-rity-skeleton/ # Template for custom derivatives
```
Sublayers at priority 9 override the base layer at priority 8. `LAYERSERIES_COMPAT` is `scarthgap`, this is the Yocto release the current RITY version targets.
## Distro variants
| Distro | Image name | Size | What it includes |
|--------|-----------|------|------------------|
| `rity-bringup` | `rity-bringup-image` | ~150MB | SSH, debug tools, minimal rootfs |
| `rity-demo` | `rity-demo-image` | ~1GB | Weston, GStreamer, AI/ML, PipeWire, NetworkManager |
| `rity-demo` + browser | `rity-browser-image` | ~2GB | Everything in demo + Chromium |
| `rity-skeleton` | - |, | Template only, not a buildable image |
### rity-bringup
The right image for first board bring-up. It boots, gives you SSH access, and includes debug utilities (`strace`, `gdb`, `bpftrace`, `perf`). Use this to verify the hardware works before adding complexity.
### rity-demo
The full integration demonstration. Key components enabled:
```bitbake
DISTRO_FEATURES:append = " \
pipewire # PipeWire audio replaces PulseAudio
demo # Demo-specific packages
pam # PAM authentication
fwupdate # EFI capsule firmware updates
expand-rootfs # Auto-expand rootfs on first boot
btf # eBPF introspection
"
```
### rity-skeleton
The right starting point for a custom product. Copy `meta-rity-skeleton`, rename it, and build your product-specific recipes on top. Never modify `meta-rity` directly, any upstream update will conflict.
```bash
cp -r meta-rity-skeleton meta-myproduct
cd meta-myproduct
# Edit conf/layer.conf, change collection name, update LAYERDEPENDS
# Add your recipes in recipes-*/
```
## Packagegroup architecture
RITY isolates each hardware capability into its own packagegroup. This makes it straightforward to include only what your product needs:
| Packagegroup | Key contents |
|---|---|
| `rity-multimedia` | GStreamer 1.0 + libcamera + V4L2 tools |
| `rity-display` | Weston (Wayland compositor) + kmscube + Vulkan tools |
| `rity-audio` | PipeWire + ALSA utils + Bluetooth codecs (AAC, LC3) |
| `rity-ai-ml` | TensorFlow Lite + ArmNN + ONNX Runtime + NNStreamer |
| `rity-mtk-video` | VCU/VCodec hardware drivers + `mtk-vpud` daemon |
| `rity-mtk-camisp` | Camera ISP driver (public) or prebuilts (NDA) |
| `rity-mtk-neuropilot` | APUSys firmware + NPU driver + NeuroPilot middleware |
| `rity-net` | NetworkManager + iperf3 |
| `rity-debug` | gdb, strace, bpftrace, perfetto, bcc, iotop |
| `rity-tsn` | linuxptp + `libopen62541` (OPC-UA) + real-time edge sysrepo |
SoC-specific additions are gated by machine overrides:
```bitbake
IMAGE_INSTALL:append:mt8395 = " packagegroup-rity-mtk-camisp packagegroup-rity-mtk-neuropilot"
IMAGE_INSTALL:append:mt8391 = " packagegroup-rity-mtk-neuropilot packagegroup-rity-mtk-video"
```
## DISTRO_FEATURES gating
Certain features require explicit opt-in via `DISTRO_FEATURES`:
| Feature flag | What it unlocks |
|---|---|
| `nda-mtk` | RAW ISP (`mtk-camisp-prebuilts`), NDA firmware, proprietary codecs |
| `secure-boot` | FIT image signing, U-Boot key provisioning |
| `fwupdate` | EFI capsule OTA update infrastructure |
| `pipewire` | PipeWire audio stack (replaces PulseAudio) |
| `btf` | Kernel BPF Type Format + eBPF introspection tools |
| `expand-rootfs` | Auto-expand rootfs service on first boot |
If `nda-mtk` is not set, camera ISP and hardware codec features silently fall back to software alternatives or are excluded entirely.
## KAS build system
RITY uses KAS to manage the 8+ layer repos the full stack requires. Each `kas/*.yml` file pins all layers to specific git refspecs:
```yaml
# kas/rity-demo.yml (simplified)
machine: i500-pumpkin
target: rity-demo-image
distro: rity-demo
includes:
- kas/include/base.yml
- kas/include/deps.yml
```
`deps.yml` pins:
- `poky`, `meta-openembedded`, `meta-arm`
- `meta-rity`, `meta-mediatek-bsp`
- `meta-mediatek-tsn`, `meta-mediatek-bluedroid`
- `meta-nn`, `meta-tensorflow`, `meta-clang`
Build with a single command:
```bash
kas build kas/rity-demo.yml
```
KAS clones all layers, generates `bblayers.conf` and `local.conf`, and runs BitBake. No manual setup.
To build for a specific board, substitute the kas file:
```bash
kas build kas/genio-720-evk-demo.yml
```
## Notable implementation details
**LLVM is the default toolchain.** RITY uses `meta-clang` and sets LLVM as the preferred compiler. If you add recipes that assume `${CC}` is GCC, they may need patches.
**NetworkManager replaces systemd-networkd.** `systemd-networkd` is explicitly disabled to prevent DHCP conflicts. All network configuration goes through NetworkManager or its CLI (`nmcli`).
**Package format is .deb.** `PACKAGE_CLASSES = "package_deb"` means the rootfs uses Debian-style packages. You can run `apt` on the target if you serve a package feed from your build output.
**Debian package feed setup:**
```bash
# Build the package index
bitbake package-index
# Serve from build directory
cd tmp/deploy/deb && python3 -m http.server 9876
# On local.conf, add:
# PACKAGE_FEED_URIS = "http://:9876"
# EXTRA_IMAGE_FEATURES:append = " package-management"
# On target:
apt-get update && apt-get install
```
For the full Yocto build workflow including fetching the RITY manifest and flashing the result, see [Yocto build guide for MediaTek Genio](/blog/mediatek-genio-yocto-build-guide). For creating a custom layer on top of RITY, see [building a custom Yocto meta layer for Genio](/blog/mediatek-genio-custom-yocto-meta-layer).
## FAQ
### Is RITY an RTOS?
No. RITY is a full Linux distribution built on Yocto/Poky. It runs a standard Linux kernel with optional real-time patches. RITY stands for Reference Implementation of Things in Yocto, it is MediaTek's reference AIoT image, not a real-time operating system.
### What is the difference between rity-bringup, rity-demo, and rity-skeleton?
`rity-bringup` is a minimal debug image (~150MB) for initial hardware verification. `rity-demo` is the full-featured image (~1GB) with GStreamer, AI/ML, Chromium, PipeWire, and camera support. `rity-skeleton` is a template layer for creating a custom derivative distribution on top of RITY.
### Do I need to use RITY for MediaTek Genio development?
No. RITY is a reference starting point. You can build a custom Yocto distro on top of the MediaTek BSP layer (`meta-mediatek-bsp`) without using RITY at all. RITY is most useful for understanding how MediaTek integrates their hardware IP, treat it as documentation you can run.
### What is KAS and why does RITY use it?
KAS is a Python tool for orchestrating Yocto builds across multiple layer repositories. RITY uses KAS because the full stack requires 8+ layer repos at specific git refspecs. A single `kas build kas/rity-demo.yml` fetches all layers and builds the image without manual repo cloning or `bblayers.conf` editing.
---
---
## SPI and I2C peripheral setup on MediaTek Genio
URL: https://proventusnova.com/blog/mediatek-genio-spi-i2c-peripheral-setup/
Published: 2026-06-08
Author: Aaron Angulo
Tags: mediatek, genio, spi, i2c, peripheral, device tree, embedded linux, evk
Set up SPI and I2C peripherals on MediaTek Genio EVK. Bus detection, i2cdetect, spidev_test, DTS pin configuration, and both 510/700 and 520/720 EVK mappings.
SPI and I2C are the two most common buses for adding peripheral hardware to a Genio board: sensors, ADCs, display controllers, LoRa radios, and EEPROMs all use them. Both buses are exposed on the Raspberry Pi-compatible 40-pin HAT header on all Genio EVKs. Getting them working requires knowing the correct bus numbers, handling pin conflicts in the device tree, and verifying the connection before writing application code.
## Key Insights
- **I2C buses are numbered differently between Genio 510/700 and 520/720 EVKs**: the HAT header is always I2C-0 on 520/720, and shared I2C-0 on 510/700
- **SPI on 520/720 EVK requires a DTS patch**: GPIO75 is shared with WiFi power enable; remapping to GPIO42 is mandatory before SPI1 works
- **SPI loopback test requires a physical short** between MOSI and MISO pins, without it, `spidev_test` output looks like a failure
- **`i2cdetect -y `** is the fastest way to confirm an I2C device is wired and responding before touching application code
- **`/dev/spidev1.0`** is the standard spidev node for SPI1 on the 520/720 EVK after the DTS patch is applied
## I2C setup and testing
### List all I2C adapters
```bash
i2cdetect -l
```
On the Genio 520/720 EVK (9 I2C adapters total):
| Bus | Connected hardware |
|-----|-------------------|
| I2C-0 | Raspberry Pi HAT (SDA pin 3, SCL pin 5) |
| I2C-1 | Raspberry Pi HAT alternate (I2C-1 SDA/SCL) |
| I2C-2 | Current Monitor |
| I2C-4 | Charger IC, Buck regulator |
| I2C-5 | USB PD Controller |
| I2C-6 | Touch panel, SBU MUX |
| I2C-7 | CAM0 (CSI camera 0) |
| I2C-8 | CAM1 (CSI camera 1) |
On the Genio 510/700 EVK (7 I2C adapters):
| Bus | Connected hardware |
|-----|-------------------|
| I2C-0 | Touch CTP0 + Raspberry Pi HAT |
| I2C-1 | Charger IC, Buck IC, USB-C MUX |
| I2C-2 | Audio DTB + Raspberry Pi HAT |
| I2C-3 | Touch CTP1 + CSI1 |
| I2C-4 | USB PD Controller |
| I2C-5 | CSI0 |
| I2C-6 | CSI0 (additional) |
### Scan a bus for devices
```bash
# Scan I2C bus 0, shows addresses as a hex grid
i2cdetect -y 0
```
Example output with a device at 0x48 (TMP102 temperature sensor):
```
0 1 2 3 4 5 6 7 8 9 a b c d e f
00: -- -- -- -- -- -- -- -- -- -- -- -- --
10: -- -- -- -- -- -- -- -- -- -- -- -- -- -- -- --
...
40: -- -- -- -- -- -- -- -- 48 -- -- -- -- -- -- --
```
### Read and write registers
```bash
# Read all registers of device at 0x48 on bus 0
i2cdump -y 0 0x48
# Read register 0x00 (temperature register on TMP102)
i2cget -f -y 0 0x48 0x00
# Write configuration to register 0x01
i2cset -f -y 0 0x48 0x01 0x60
```
The `-f` flag forces access even if the kernel driver has claimed the device. Use it cautiously in production, it bypasses the driver's exclusive claim.
### I2C in a Yocto image
The `i2c-tools` package provides `i2cdetect`, `i2cget`, `i2cset`, and `i2cdump`. Add to `IMAGE_INSTALL`:
```bitbake
IMAGE_INSTALL:append = " i2c-tools"
```
For kernel-level I2C access, ensure `CONFIG_I2C_CHARDEV=y` is set (it is in the default Genio kernel config).
## SPI setup on Genio 520/720 EVK
The 520/720 EVK exposes SPI1 on the 40-pin HAT header. There is a pin conflict: GPIO75 is shared between SPI1 MOSI and the WiFi 3.3V power enable regulator. You must fix this in the device tree before SPI1 is usable.
### HAT SPI pin mapping (520/720)
| Pin | Signal |
|-----|--------|
| 19 | SPI1 MOSI (GPIO75) |
| 21 | SPI1 MISO (GPIO76) |
| 23 | SPI1 SCLK (GPIO74) |
| 24 | SPI1 CS (GPIO73) |
### DTS fix: remap WiFi power enable
File: `arch/arm64/boot/dts/mediatek/mt8391-genio-720-evk.dts`
**Step 1: Move WiFi 3.3V enable from GPIO75 → GPIO42**
```dts
pins_wcn_3v3_en: regulator-8 {
regulator-name = "pins_wcn_3v3_en";
regulator-min-microvolt = <3300000>;
regulator-max-microvolt = <3300000>;
gpio = <&pio 42 GPIO_ACTIVE_HIGH>; /* was: 75 */
enable-active-high;
regulator-always-on;
};
```
**Step 2: Update the pinctrl group to use GPIO42**
```dts
pins-wifichip-wcn-3v3-en {
gpio-hog;
pinmux = , /* was: GPIO75 */
;
output-high;
};
```
**Step 3: Add SPI1 pingroup and enable the node**
```dts
spi1_pins: spi1-pins {
pins-spi-bus {
pinmux = ,
,
;
drive-strength = ;
bias-disable;
};
pins-spi-mi {
pinmux = ;
bias-pull-down;
};
};
&spi1 {
pinctrl-0 = <&spi1_pins>;
pinctrl-names = "default";
#address-cells = <1>;
#size-cells = <0>;
status = "okay";
spidev@0 {
compatible = "mediatek,aiot-board";
spi-max-frequency = <5000000>;
reg = <0>;
};
};
```
After applying and rebuilding, `/dev/spidev1.0` appears on boot.
### SPI testing
**Critical first step: short MOSI (pin 19) to MISO (pin 21) on the HAT header.** Without this physical loopback, RX data will not match TX and the test appears to fail.
```bash
# Load spidev module (should already be loaded)
modprobe spidev
# Verify device exists
ls /dev/spidev1.0
# Run loopback test at 400kHz
dd if=/dev/random of=test.bin bs=96 count=1
spidev_test -D /dev/spidev1.0 -s 400000 -i test.bin -v
```
Expected: TX and RX bytes match exactly. If they don't, check the physical short between pins 19 and 21, and confirm the DTS patch is applied.
## SPI setup on Genio 510/700 EVK
SPI-2 is exposed on the 40-pin HAT header. Unlike the 520/720, no WiFi pin conflict exists, but SPI-2 shares pins with CSI1 (camera 1).
**Before enabling SPI-2:** disconnect any CSI1 camera cable, then set jumpers:
| Jumper | Set to position | Signal |
|--------|----------------|--------|
| J4207 | 2-3 | SPI2 MOSI |
| J4208 | 2-3 | SPI2 MISO |
| J4209 | 2-3 | SPI2 CLK |
| J4215 | 2-3 | SPI2 CS |
After setting jumpers, the SPI device appears at `/dev/spidev2.0`.
## Adding a real SPI device (example: MCP2515 CAN controller)
```dts
&spi1 {
pinctrl-0 = <&spi1_pins>;
pinctrl-names = "default";
#address-cells = <1>;
#size-cells = <0>;
status = "okay";
can0: mcp2515@0 {
compatible = "microchip,mcp2515";
reg = <0>;
spi-max-frequency = <10000000>;
clocks = <&mcp2515_osc>;
interrupt-parent = <&pio>;
interrupts = <110 IRQ_TYPE_EDGE_FALLING>;
};
};
mcp2515_osc: mcp2515-oscillator {
compatible = "fixed-clock";
#clock-cells = <0>;
clock-frequency = <16000000>;
};
```
## Applying the DTS change in Yocto
Capture the change as a patch and apply it in your kernel bbappend, scoped to your specific machine:
```bash
# Generate patch from kernel source tree
git diff > mt8391-spi1-enable.patch
```
In your layer:
```bitbake
# recipes-kernel/linux/linux-mtk_%.bbappend
FILESEXTRAPATHS:prepend := "${THISDIR}/${PN}:"
SRC_URI:append:mt8391-genio-720-evk = " file://mt8391-spi1-enable.patch"
```
For custom carrier boards, author the SPI pinmux from scratch in your board DTS rather than patching the EVK DTS.
For device tree overlay patterns and the full Genio kernel bbappend workflow, see [building a custom Yocto meta layer for Genio](/blog/mediatek-genio-custom-yocto-meta-layer). For GMSL or MIPI camera bring-up on the same CSI connectors that share pins with these peripherals, see [MIPI CSI camera driver setup on Genio](/blog/mediatek-genio-mipi-csi-camera-driver).
## FAQ
### How do I detect I2C devices on MediaTek Genio?
Run `i2cdetect -l` to list all I2C adapters, then `i2cdetect -y ` to scan a specific bus. On the Genio 520/720 EVK, I2C-0 is connected to the Raspberry Pi HAT header (SDA pin 3, SCL pin 5). On the Genio 510/700 EVK, I2C-0 is shared between Touch CTP0 and the Raspberry Pi HAT.
### How do I enable SPI on the Genio 520/720 EVK?
GPIO75 is shared between SPI1 MOSI and the WiFi 3.3V power enable, you must remap the WiFi regulator from GPIO75 to GPIO42 in the DTS before SPI1 works. Without this DTS change, the WiFi module loses power when SPI is active.
### What is the spidev_test command for verifying SPI on Genio?
Short MOSI (pin 19) to MISO (pin 21) on the HAT header first, then run: `spidev_test -D /dev/spidev1.0 -s 400000 -v`. TX and RX bytes should match exactly. Without the loopback short, RX data is garbage and the test appears to fail.
### Does the Genio 510/700 EVK expose SPI on the Raspberry Pi HAT?
Yes, via SPI-2 on the 40-pin HAT header. SPI-2 pins are shared with CSI1, disconnect any CSI1 camera cable before using SPI-2. Set jumpers J4207-J4209 and J4215 to position 2-3 to route SPI to the HAT pins.
---
---
## Linux containers on MediaTek Genio with Yocto
URL: https://proventusnova.com/blog/mediatek-genio-yocto-linux-containers/
Published: 2026-06-08
Author: Andres Campos
Tags: mediatek, genio, docker, lxc, yocto, containers, embedded linux, meta-virtualization
Run Docker and LXC containers on MediaTek Genio with Yocto. Add meta-virtualization, enable cgroup v2, configure container runtimes, and pass hardware devices.
Linux containers on Genio let you isolate applications from the BSP, manage dependencies independently of the root filesystem, and deploy workloads using standard container tooling. The Genio Linux kernel supports all the required features, cgroups, namespaces, OverlayFS, but the default RITY Yocto image does not include container runtime packages. Adding them requires `meta-virtualization` and one `DISTRO_FEATURES` flag.
## Key Insights
- **`meta-virtualization` is the layer**: it provides Docker, containerd, runc, and LXC recipes for Yocto scarthgap
- **`DISTRO_FEATURES += "virtualization"`** is the single flag that gates all container dependencies in the build
- **cgroup v2 works on Genio**: set `systemd.unified_cgroup_hierarchy=1` in the kernel command line for unified cgroup hierarchy
- **OverlayFS is required for Docker**: it is enabled in the default Genio kernel config; verify with `grep OVERLAY_FS .config`
- **Docker and LXC serve different use cases**: Docker for application containers, LXC for system containers
## Adding meta-virtualization to the build
### Step 1: Clone the layer
```bash
git clone https://github.com/openembedded/meta-virtualization.git \
-b scarthgap \
sources/meta-virtualization
```
### Step 2: Add to bblayers.conf
```bitbake
BBLAYERS += " \
${BSPDIR}/sources/meta-virtualization \
"
```
### Step 3: Enable the DISTRO_FEATURE
In `conf/local.conf` or your custom distro:
```bitbake
DISTRO_FEATURES:append = " virtualization"
```
This flag enables the kernel config fragments and package dependencies that containers require. Without it, cgroup device support, veth, and bridge networking are not guaranteed to be present.
## Docker setup
### Add Docker to IMAGE_INSTALL
```bitbake
IMAGE_INSTALL:append = " \
docker-ce \
docker-ce-cli \
containerd \
runc \
docker-init \
"
```
For a lighter setup using containerd only (no Docker daemon):
```bitbake
IMAGE_INSTALL:append = " containerd nerdctl"
```
`nerdctl` is a Docker-compatible CLI for containerd that works without the Docker daemon.
### Verify required kernel config
```bash
# From build directory
bitbake -e virtual/kernel | grep "^KCONFIG_MODE"
# Then check specific options:
grep -E "CONFIG_CGROUPS|CONFIG_NAMESPACES|CONFIG_OVERLAY_FS|CONFIG_VETH|CONFIG_BRIDGE" \
tmp/work/*/linux-mtk/*/build/.config
```
All of these are enabled in the default Genio kernel config:
```
CONFIG_CGROUPS=y
CONFIG_CGROUP_DEVICE=y
CONFIG_CGROUP_CPUACCT=y
CONFIG_MEMCG=y
CONFIG_NAMESPACES=y
CONFIG_NET_NS=y
CONFIG_PID_NS=y
CONFIG_IPC_NS=y
CONFIG_UTS_NS=y
CONFIG_OVERLAY_FS=y
CONFIG_VETH=y
CONFIG_BRIDGE=y
CONFIG_NF_NAT=y
```
### cgroup v2 configuration
To use unified cgroup hierarchy (cgroup v2):
In your bootloader config (U-Boot), add to the kernel command line:
```
systemd.unified_cgroup_hierarchy=1
```
Or in `conf/local.conf`:
```bitbake
APPEND:append = " systemd.unified_cgroup_hierarchy=1"
```
Verify on the target:
```bash
cat /sys/fs/cgroup/cgroup.controllers
# Should show: cpuset cpu io memory hugetlb pids rdma misc
```
### First container run
```bash
# Start Docker daemon
systemctl start docker
systemctl enable docker
# Verify
docker info | grep -E "Server Version|Storage Driver|Cgroup"
# Hello world
docker run --rm arm64v8/ubuntu:22.04 uname -m
# aarch64
```
Use `arm64v8/` images from Docker Hub, these are built for aarch64 and run natively on Genio without emulation.
### Docker Compose
```bitbake
IMAGE_INSTALL:append = " python3-docker-compose"
```
Example compose file for a sensor data pipeline:
```yaml
# docker-compose.yml
version: "3.8"
services:
sensor-bridge:
image: arm64v8/python:3.11-slim
devices:
- "/dev/i2c-0:/dev/i2c-0"
volumes:
- "./app:/app"
command: python3 /app/sensor_bridge.py
inference:
image: your-tflite-image:latest
devices:
- "/dev/mali0:/dev/mali0"
depends_on:
- sensor-bridge
```
## LXC system containers
LXC is better suited when you need a full OS environment in the container, for example, running Ubuntu alongside the RITY rootfs, or isolating a full application stack with its own init system.
### Add LXC to the image
```bitbake
IMAGE_INSTALL:append = " lxc"
```
### Create and start an LXC container
```bash
# Create an Ubuntu container
lxc-create -n myapp -t download -- \
--dist ubuntu --release jammy --arch arm64
# Start it
lxc-start -n myapp
# Attach a shell
lxc-attach -n myapp
# Stop
lxc-stop -n myapp
```
LXC containers use a configuration file at `/var/lib/lxc//config`. Pass hardware devices:
```ini
# /var/lib/lxc/myapp/config
lxc.mount.entry = /dev/mali0 dev/mali0 none bind,create=file 0 0
lxc.mount.entry = /dev/i2c-0 dev/i2c-0 none bind,create=file 0 0
lxc.cgroup2.devices.allow = c 226:* rwm
```
## Choosing between Docker and LXC
| | Docker | LXC |
|---|---|---|
| Use case | Application containers | System containers |
| Filesystem | OverlayFS (layered, read-only images) | Persistent disk storage |
| Init system | No (single process per container) | Yes (full systemd or init) |
| Image registry | Docker Hub, private registries | No standard registry |
| Update workflow | Pull new image, restart | In-place package updates |
| Resource overhead | Low | Medium |
| Best for on Genio | AI inference, API servers, isolated services | Full OS environment, legacy app porting |
## Container image storage
Docker stores images in `/var/lib/docker` by default. On Genio boards with eMMC as the only storage, this fills up quickly. Move Docker's data directory to external storage or a larger partition:
```bash
# Stop Docker
systemctl stop docker
# Move data directory
mv /var/lib/docker /mnt/data/docker
# Configure Docker to use new location
cat > /etc/docker/daemon.json < layers/meta-mediatek-bsp-private
```
2. Add it to your kas configuration file:
```yaml
layers:
meta-mediatek-bsp-private:
path: layers/meta-mediatek-bsp-private
branch: genio-yocto-
```
3. Set the build flag:
```bash
NDA_BUILD=1 kas build kas/genio-720-evk.yml
```
The private layer uses bbappend files to extend or replace recipes from the public layer. No changes to the public layer are needed, the two coexist cleanly.
## What does the NDA actually restrict?
The NDA restricts:
- Sharing the `meta-mediatek-bsp-private` source with parties not covered by the agreement
- Publishing the private layer (or derived works) publicly, including open source
- Reverse engineering the closed-source binaries
The NDA does not restrict:
- Shipping products that include firmware images built with the NDA layer
- Production volume or markets
- Building multiple product lines using the same NDA
- Having contractors or employees build with the layer (they are covered by your organization's NDA)
---
Need help navigating the MediaTek Genio NDA process or getting your BSP set up for hardware acceleration? [ProventusNova](https://proventusnova.com) has existing NDA access and experience with both public and private BSP layers. See our [custom board bringup service](/services/custom-board-bringup) or [get in touch](https://proventusnova.com/contact).
---
## ISP differences between Genio 510/700 and Genio 520/720
URL: https://proventusnova.com/blog/mediatek-genio-510-700-520-720-isp-differences/
Published: 2026-06-06
Author: Andres Campos
Tags: mediatek, genio, isp, camera, mipi-csi, genio-520, genio-720, embedded linux
What changed in the MediaTek Genio ISP between Gen 1 (510/700) and Gen 2 (520/720): pipeline depth, virtual channels, and camera driver differences.
The ISP (Image Signal Processor) is one of the most significant hardware changes between the first-generation Genio platforms (510/700) and the second-generation (520/720). If your product depends on camera input, the ISP generation affects MIPI lane configuration, virtual channel support, 3A pipeline depth, and which NDA BSP components you need to configure.
## Key Insights
- Genio 510/700 use ISP Gen 1, up to 2 concurrent camera inputs, no virtual channel support
- Genio 520/720 use ISP Gen 2, up to 4 concurrent camera inputs, virtual channel support, improved 3A
- 520 and 720 share the same ISP, camera tuning files and libcamera pipeline handlers transfer directly
- Camera sensor drivers are largely portable, but ISP pipeline configuration (libcamera handler, tuning JSON) must be updated when moving between ISP generations
- For time-of-flight sensors or any camera using MIPI CSI-2 virtual channels, Genio 520/720 is required
## What changed between ISP Gen 1 and Gen 2?
| Feature | Genio 510/700 (Gen 1 ISP) | Genio 520/720 (Gen 2 ISP) |
|---|---|---|
| Max concurrent camera inputs | 2 | 4 |
| MIPI CSI-2 virtual channels | Not supported | Supported (up to VC3) |
| Max input resolution | 16 MP | 32 MP |
| Max framerate at 4K | 30 fps | 60 fps |
| 3A algorithms | Gen 1 (basic AE/AF/AWB) | Gen 2 (improved convergence) |
| libcamera pipeline handler | mtk-isi-gen1 | mtk-isi-gen2 |
| ISP tuning file format | JSON v1 | JSON v2 |
| NDA BSP layer | meta-mediatek-bsp-private (Gen 1) | meta-mediatek-bsp-private (Gen 2) |
The pipeline handler difference is the practical blocker when porting a camera design between generations. The libcamera IPA (Image Processing Algorithm) modules are separate binary blobs in the [NDA BSP](/blog/mediatek-genio-nda-vs-public-build), one per ISP generation.
## How does the MIPI CSI-2 configuration differ?
On Genio 510/700 (Gen 1), the MIPI CSI-2 receiver accepts up to 4 lanes per port but does not implement virtual channel demultiplexing in hardware. Each physical port maps to one sensor.
On Genio 520/720 (Gen 2), the CSI-2 receiver implements virtual channel (VC) demultiplexing. A single physical MIPI port with 4 lanes can carry streams from up to 4 virtual channels simultaneously. This enables:
- Time-of-flight sensors that output IR and depth on separate VCs
- Camera modules with embedded metadata on VC1
- Multi-exposure HDR sensors that send short and long exposures on separate VCs
The device tree binding also changes. On Gen 2, each virtual channel is a separate `v4l2-subdev` node with a `vc-id` property.
Example device tree fragment for a Gen 2 dual-VC sensor:
```dts
&mipi_csi0 {
sensor@0 {
compatible = "vendor,sensor-name";
reg = <0x36>;
port {
sensor_out: endpoint {
clock-lanes = <0>;
data-lanes = <1 2 3 4>;
link-frequencies = /bits/ 64 <800000000>;
};
};
};
};
&seninf {
ports {
port@0 {
vc0: endpoint@0 {
vc-id = <0>;
remote-endpoint = <&sensor_out>;
};
vc1: endpoint@1 {
vc-id = <1>;
remote-endpoint = <&sensor_out>;
};
};
};
};
```
This device tree syntax is not valid on Gen 1 ISP, the `seninf` binding does not support per-VC endpoints.
## What stays the same between platforms?
The sensor driver itself, the kernel module that controls the image sensor over I2C, is largely platform-independent. It configures the sensor's register map, controls exposure and gain, and sets the MIPI output format. This part of the code does not interact with the ISP directly.
What must change when moving from Gen 1 to Gen 2:
1. **ISP pipeline handler**: The libcamera `IPA` binary and pipeline handler source are separate per ISP generation. Use the Gen 2 handler from the NDA BSP.
2. **Tuning JSON**: The JSON schema changed between generations. A Gen 1 tuning file will not parse correctly on Gen 2.
3. **Device tree**: MIPI CSI-2 bindings changed, particularly if using virtual channels.
4. **seninf node**: The sensor interface node binding differs between Gen 1 and Gen 2.
The sensor characterization data (optical center, noise model, lens shading) carries over, but it needs to be re-expressed in the Gen 2 JSON format.
## Which platform should you choose for a new camera design?
For any new product that includes a camera:
- **Genio 520**: cost-optimized, Gen 2 ISP, good for 1-2 sensors at moderate resolution
- **Genio 720**: performance, Gen 2 ISP, up to 4 sensors, suitable for multi-camera AI vision systems
- **Genio 1200**: maximum compute, Gen 2 ISP, dual MDLA for processing multiple camera streams through AI inference simultaneously
Avoid designing new products on Genio 510/700 if your camera requirements include virtual channels, 4K at 60fps, or more than 2 simultaneous inputs. For the full device tree and kernel driver setup for MIPI CSI-2, see [MIPI CSI camera driver setup on MediaTek Genio](/blog/mediatek-genio-mipi-csi-camera-driver).
---
Working on camera integration on MediaTek Genio and need help with ISP bring-up, sensor driver porting, or libcamera configuration? [ProventusNova](https://proventusnova.com) specializes in embedded Linux and camera software on Genio. See our [CSI camera driver service](/services/csi) or [get in touch](https://proventusnova.com/contact).
---
## MediaTek Genio SoC longevity and supply plan for product design
URL: https://proventusnova.com/blog/mediatek-genio-soc-longevity-supply-plan/
Published: 2026-06-05
Author: Andres Campos
Tags: mediatek, genio, supply chain, product design, embedded, longevity, soc
MediaTek Genio longevity commitments, 10-year supply windows, and how to plan around SoC transitions in embedded product design.
MediaTek Genio is positioned as a 10-year supply platform for industrial IoT. Choosing the right SoC means understanding both the supply commitment and where each platform sits in the hardware generation cycle. A design-in on a first-generation platform at the end of its release window is a different decision than the same design on a current-generation part.
## Key Insights
- Genio targets a 10-year supply window from production release, confirm exact dates with your FAE at design-in
- Genio 520 and 720 are the current recommended platforms for new designs (NPU Gen 2, MDLA 5.x)
- Genio 700 and 510 are Gen 1 NPU platforms, valid for existing designs but not the forward choice for AI-heavy products
- BSP support continues through the supply window, but new feature development slows after the first 2-3 years
- For 8+ year products, budget for your own BSP fork and kernel security maintenance
## What does MediaTek's supply commitment mean in practice?
MediaTek formally positions Genio as a 10-year supply platform. This is a commitment to:
- Continue manufacturing and supplying the SoC for at least 10 years from production release
- Maintain critical BSP patches (security, regulatory) through the supply window
- Provide replacement qualification support if die revisions occur
What it does not guarantee:
- New feature additions to the BSP after the first few years
- Continued NeuroPilot SDK updates aligned to the latest NPU architecture
- Pin-compatible successors if the SoC reaches end-of-life
The specific end-of-life date for any Genio SoC is confirmed through your distributor or MediaTek FAE at design-in. Do not rely on marketing materials alone, get a written commitment before signing off on a platform choice.
## Where does each Genio SoC sit in the generation cycle?
| Platform | SoC | NPU Gen | Launch | Status for new designs |
|---|---|---|---|---|
| Genio 350 | MT8365 | None | 2020 | Late-cycle, no AI accelerator |
| Genio 510 | MT8370 | Gen 1 | 2021 | Late-cycle, Gen 1 NPU, no MDLA |
| Genio 700 | MT8395 | Gen 1 | 2021 | Late-cycle for AI designs |
| Genio 1200 | MT8678 | Gen 2 | 2022 | Current, high-end, dual MDLA |
| Genio 520 | MT8371 | Gen 2 | 2023 | Current, recommended mid-range |
| Genio 720 | MT8395S | Gen 2 | 2023 | Current, recommended performance |
"Late-cycle" means the part is in production and will be supplied, but it is not MediaTek's forward investment target for SDK and AI feature updates. For a detailed comparison of what differs between platforms, CPU, NPU generation, MDLA, and ISP, see [Genio 510 vs 700 vs 1200: which MediaTek module for your product](/blog/mediatek-genio-510-vs-700-vs-1200) and [APU, NPU, VPU, and MDLA on Genio explained](/blog/mediatek-genio-apu-npu-vpu-mdla-explained).
## How should you plan BSP maintenance for a long-lifecycle product?
For products with a 5-10 year field life, the BSP maintenance strategy matters as much as the initial build:
**Years 1-3 (active BSP development)**
MediaTek ships regular BSP updates, new kernel versions, NeuroPilot SDK releases, driver improvements. Follow these updates and integrate them. Keep your customization layer thin so you can merge upstream BSP releases cleanly.
**Years 3-6 (maintenance mode)**
MediaTek shifts to security patches and critical fixes. New Yocto LTS branches require porting effort from your team. Budget for 1-2 BSP integration sprints per year.
**Years 6-10 (security maintenance only)**
MediaTek provides critical security patches only. Your team owns the backport work. If you are running a kernel that is approaching upstream end-of-life, evaluate whether to rebase or maintain your own patch queue.
The practical implication: structure your Yocto layer (meta-your-product) as a thin customization on top of meta-mediatek-bsp. Avoid modifying BSP-owned files directly, use bbappend and patch files. This makes upstream merges tractable.
## What is the right SoC for a new design in 2025-2026?
For designs targeting production in 2026 and beyond:
| Use case | Recommended platform | Reasoning |
|---|---|---|
| Vision AI, object detection | Genio 720 | NPU Gen 2, MDLA 5.x, 4x display outputs |
| Mid-range AI, cost-sensitive | Genio 520 | Same NPU architecture as 720, lower cost |
| High-compute AI (LLM, multi-camera) | Genio 1200 | Dual MDLA, highest TOPS, octa-core CPU |
| Non-AI, display-heavy | Genio 350 / 520 | 350 for cost, 520 for future-proofing |
| Existing Genio 700 design refresh | Genio 720 | Same peripheral footprint, NPU upgrade |
Genio 350 remains appropriate for cost-sensitive designs with no AI requirements, display, HMI, simple connectivity.
## What should you ask your distributor before committing?
Before locking in a Genio SoC for a new product:
1. **Confirm end-of-life date in writing.** Get the supply commitment letter, not just the marketing claim.
2. **Confirm NDA BSP access terms.** The meta-mediatek-bsp-private layer requires a separate NDA. Understand the terms before designing in features that depend on it.
3. **Confirm NeuroPilot SDK support timeline.** Ask specifically how long the SDK will receive updates for your target platform.
4. **Ask about pin-compatible successors.** If the SoC is discontinued before your product EOL, what is the migration path?
5. **Understand module availability.** If you plan to use a system-on-module (SOM) rather than a custom board, confirm the module vendor's own supply commitment layered on top of MediaTek's.
---
Designing a product on MediaTek Genio and need help evaluating platform choices, BSP strategy, or production readiness? [ProventusNova](https://proventusnova.com) specializes in embedded Linux and AI on Genio. See our [hardware sourcing and ODM service](/services/hardware-sourcing) or [get in touch](https://proventusnova.com/contact).
---
## Jetson Nano Remote Access Setup: SSH, VNC, and NoMachine
URL: https://proventusnova.com/blog/jetson-nano-remote-access-setup/
Published: 2026-06-04
Author: Andres Campos
Tags: jetson nano, remote access, ssh, vnc, nomachine, jetpack 4
How to set up remote access on Jetson Nano with JetPack 4.x, SSH, VNC with Vino or x11vnc, and NoMachine for a full desktop experience.
The Jetson Nano runs Ubuntu 18.04 on JetPack 4.x, and getting reliable remote access set up on day one saves a lot of time on projects where the Nano lives in a bench rig, an enclosure, or anywhere you do not want to drag a monitor and keyboard to every time. SSH covers most of what you need. VNC and NoMachine handle the cases where you need the desktop.
## Key Insights
- SSH is enabled by default on the JetPack 4.x desktop image and requires no configuration to get started
- Vino (the GNOME VNC server) is pre-installed and works without additional packages, but its performance is limited
- NoMachine is the best option for a full remote desktop experience on Jetson Nano, it is free, installs in minutes, and handles headless setups without a dummy HDMI adapter
- For headless operation without NoMachine, you need either a dummy HDMI plug or a virtual framebuffer to prevent the desktop session from starting at reduced resolution
- Set a static IP or configure mDNS (`hostname.local`) early, tracking down the Nano's DHCP address every reboot gets old quickly
## SSH: works out of the box
The OpenSSH server is installed and running by default on the JetPack 4.x desktop image. From any machine on the same network:
```bash
ssh your-username@192.168.1.X
```
Find the Nano's IP address:
```bash
# On the Nano
hostname -I
# For wired connection specifically
ip addr show eth0 | grep inet
```
If you want to avoid typing a password every time, copy your SSH key:
```bash
ssh-copy-id your-username@192.168.1.X
```
For a stable address, either configure a static IP in the network settings or set up mDNS so you can reach the Nano by hostname:
```bash
# From your laptop (macOS or Linux with avahi)
ssh your-username@tegra-ubuntu.local
```
The hostname defaults to `tegra-ubuntu` unless you changed it during setup. You can change it in Settings > About or with `hostnamectl set-hostname your-name`.
## VNC with Vino (no extra install needed)
Vino is the GNOME VNC server and comes pre-installed on the JetPack 4.x desktop image. Enable it from the command line:
```bash
# Enable Vino and configure it
gsettings set org.gnome.Vino enabled true
gsettings set org.gnome.Vino prompt-enabled false
gsettings set org.gnome.Vino require-encryption false
# Set a VNC password (8 chars max for standard VNC)
gsettings set org.gnome.Vino authentication-methods "['vnc']"
gsettings set org.gnome.Vino vnc-password $(echo -n 'yourpassword' | base64)
```
Vino starts automatically when the desktop session starts. Connect from any VNC client (RealVNC Viewer, TigerVNC, or the macOS built-in Screen Sharing) at `192.168.1.X:5900`.
One limitation: Vino requires an active desktop session. If you boot the Nano headless without a monitor, the desktop session may not start unless you enable auto-login. Enable auto-login in Settings > Users.
## NoMachine: the best overall option
NoMachine handles headless setups better than Vino, delivers a smoother desktop experience, and handles clipboard and display scaling well. It is free for personal use.
On the Jetson Nano, download and install the ARM64 package:
```bash
# Download the ARM64 .deb (check nomachine.com for the current version)
wget https://download.nomachine.com/download/8.X/Arm/nomachine_8.X.X_arm64.deb
# Install
sudo dpkg -i nomachine_8.X.X_arm64.deb
```
The NoMachine service starts automatically after install. Connect from the NoMachine client on your laptop by entering the Nano's IP address. No desktop session needs to be running, NoMachine creates a virtual display.
This is the option we use for Jetson Nano setups that live in enclosures or remote rigs. The virtual display means no dummy HDMI adapter is needed, and the session persists across disconnections.
## Headless operation without NoMachine
If you are using VNC or SSH-only and the Nano has no monitor, the desktop may start at 640x480 or refuse to start the compositor. Two options:
**Option 1: Dummy HDMI adapter.** A cheap HDMI plug (under $5) or an EDID emulator tells the Nano a display is connected. The GPU initializes at a reasonable resolution and the desktop session starts normally. This is the simplest fix for VNC users.
**Option 2: Configure a virtual framebuffer.** Alternatively, configure a custom xorg.conf to define a virtual display resolution without hardware:
```bash
sudo nano /etc/X11/xorg.conf
```
Add a `Virtual` size to the Screen section to force a specific resolution regardless of connected hardware.
## Setting a static IP
For any production setup or regular development use, a static IP is worth setting:
```bash
sudo nano /etc/network/interfaces
```
Or use nmcli for NetworkManager-managed interfaces:
```bash
# Set static IP via nmcli
sudo nmcli con mod "Wired connection 1" \
ipv4.method manual \
ipv4.addresses 192.168.1.50/24 \
ipv4.gateway 192.168.1.1 \
ipv4.dns "8.8.8.8 8.8.4.4"
sudo nmcli con up "Wired connection 1"
```
If you have a Jetson Orin or later platform, the remote desktop setup is similar but uses JetPack 5/6 on Ubuntu 20.04/22.04, the [Jetson remote desktop guide for Orin](/blog/jetson-remote-desktop-nomachine-vnc-headless-setup) covers those specific steps.
## Frequently Asked Questions
### How do I enable SSH on Jetson Nano?
SSH server is installed and enabled by default on the JetPack 4.x desktop image. Connect with `ssh @`. Find the IP with `hostname -I` on the Nano.
### What is the best VNC option for Jetson Nano on JetPack 4.x?
NoMachine is the most reliable option for a full desktop experience. For a lightweight option without extra software, Vino (pre-installed) works over standard VNC clients.
### Can I use Jetson Nano headless without a monitor connected?
Yes. Use either a dummy HDMI adapter to force display initialization, or NoMachine which creates a virtual display independent of physical monitors.
### What is the default username and password for Jetson Nano JetPack?
The username and password are set during first boot via the oem-config setup wizard. There is no universal default.
### How do I find the IP address of my Jetson Nano on the network?
Run `hostname -I` or `ip addr show eth0` on the Nano. For wireless, use `ip addr show wlan0`. You can also check your router's DHCP lease table.
---
*ProventusNova builds and deploys production Jetson systems for hardware startups. [Talk to us if you are working on an embedded EdgeAI product.](https://proventusnova.com/services)*
---
## MAX96705 GMSL Camera Driver on Jetson (It's GMSL1, Not GMSL2)
URL: https://proventusnova.com/blog/max96705-gmsl-jetson-camera-driver/
Published: 2026-06-04
Author: Aaron Angulo
Tags: jetson, gmsl, max96705, camera driver, v4l2, serializer
How to bring up a MAX96705 GMSL camera on NVIDIA Jetson, and the key difference between GMSL1 (MAX96705/MAX9286) and GMSL2 (MAX9295/MAX9296).
If you are searching for a GMSL2 driver for the MAX96705 and coming up empty, the reason is that MAX96705 is not GMSL2, it is first-generation GMSL. GMSL2 uses a completely different chip family. This distinction matters because the driver approach, bandwidth limits, and cable requirements are all different. What follows covers bringing up a GMSL1 camera chain with MAX96705/MAX9286 on NVIDIA Jetson.
## Key Insights
- MAX96705 is a GMSL1 (first-generation) serializer rated at 3.12 Gbps, not GMSL2
- GMSL2 serializers are MAX9295A (single) and MAX96717 (single with more features); the deserializers are MAX9296A and MAX96718
- The MAX9286 (GMSL1 deserializer) has had upstream Linux kernel support since v5.1; GMSL2 MAX9296A support came later
- On Jetson, the driver stack is: MAX9286 deserializer driver → V4L2 subdevice for the sensor → `nvarguscamerasrc` or `v4l2src`
- GMSL1 link-lock failure and I2C passthrough to the sensor are the two most common bring-up problems
## GMSL1 vs GMSL2: understanding the difference
Maxim Integrated (now part of Analog Devices) has produced two generations of GMSL:
| Feature | GMSL1 | GMSL2 |
|---|---|---|
| Serializer | MAX96705, MAX96707 | MAX9295A, MAX96717 |
| Deserializer | MAX9286, MAX96706 | MAX9296A, MAX96718, MAX96792 |
| Bandwidth | 3.12 Gbps | 3 Gbps or 6 Gbps |
| Cable | Standard coax or STP | Standard coax or STP |
| I2C tunneling | Yes | Yes |
| Linux kernel driver | upstream since v5.1 | partial upstream, mostly BSP |
| Typical use | Automotive cameras, industrial | Newer automotive, higher-res |
The MAX9286 is a 4-camera GMSL1 deserializer. The MAX96705 is the single-channel serializer that sits at the camera. They communicate over coaxial cable carrying both video data and reverse-channel power and I2C.
## How the Jetson driver stack works
On Jetson, the camera side sees a standard CSI-2 interface coming from the MAX9286 deserializer. The GMSL chain is transparent to the Tegra ISP, from the Jetson's perspective, it is just another CSI camera after the deserializer handles link negotiation.
The driver stack:
1. **MAX9286 driver** handles link negotiation, I2C passthrough to sensors behind the serializer, and routes video from each camera to a V4L2 subdevice
2. **Sensor driver** (e.g., IMX327, OV10640) registers via the deserializer's I2C gateway
3. **V4L2 / Argus** captures from the resulting `/dev/video` nodes
The DTS for this setup is more complex than a direct CSI camera. The MAX9286 deserializer node appears in the I2C bus, and each camera port under it describes both the serializer and the sensor, with the sensor's I2C address translated through the deserializer's alias mechanism.
## Bring-up sequence
The same four-layer debugging approach applies here, with two additional GMSL-specific steps:
**Step 1: Verify power and I2C**
```bash
# Confirm MAX9286 is visible on the Jetson I2C bus
i2cdetect -y 2 # adjust bus number
# Expected output: MAX9286 at its configured address (typically 0x48 or 0x2c)
```
**Step 2: Check GMSL link lock**
```bash
dmesg | grep -i max9286
```
A successful bring-up looks like:
```
max9286 2-0048: Found 4 cameras
max9286 2-0048: camera 0 address 0x40: IMX327
```
A link-lock failure looks like:
```
max9286 2-0048: Unable to lock GMSL link
```
Link-lock failures are most often caused by cable problems (wrong impedance, damaged coax, poor connector termination), power issues on the serializer side, or incorrect GMSL configuration registers. Check the physical cable first.
**Step 3: Verify sensor I2C passthrough**
Once the link has locked, the MAX9286 exposes a virtual I2C bus for each camera port. The sensor behind each MAX96705 should appear on this bus at its translated address:
```bash
# Read from sensor through the deserializer I2C passthrough
i2ctransfer -y r2@0x40
```
**Step 4: V4L2 and Argus capture**
Once the sensor I2C is working and the DTS is correctly configured:
```bash
# Verify V4L2 node exists
v4l2-ctl --list-devices
# Capture test frames
v4l2-ctl -d /dev/video0 --stream-mmap --stream-count=10
# Argus pipeline
gst-launch-1.0 nvarguscamerasrc sensor-id=0 ! \
video/x-raw(memory:NVMM),format=NV12 ! \
nvvidconv ! nv3dsink sync=false
```
## Common problems
**Coax cable quality.** GMSL1 is more sensitive to cable quality than you might expect. A cable that passes DC continuity can still fail GMSL bring-up if the impedance is wrong or there is too much capacitance. Use recommended cable specifications from the MAX9286 datasheet.
**Conflicting I2C addresses.** When multiple MAX96705 serializers share the same I2C bus through the deserializer, the deserializer remaps each serializer to a unique address. The initial broadcast address (0x40 for MAX96705) must not conflict with any other device on the bus during bring-up. The DTS must configure the alias addresses correctly.
**Power sequencing.** The MAX9286 requires the MAXIM_ENABLE pin and the serializer power supplies to sequence correctly. If the deserializer probes before the serializer has power, the link will not lock and the driver may fail silently.
For newer designs, [GMSL2 bring-up with MAX9295/MAX9296A on Jetson Orin](/blog/gmsl2-camera-bringup-jetson-orin-max9295-max9296) covers the GMSL2 equivalent of this process with the newer chip family and its different driver architecture.
## Frequently Asked Questions
### Is MAX96705 a GMSL or GMSL2 serializer?
MAX96705 is a GMSL1 (first-generation) serializer, not GMSL2. GMSL1 operates at 3.12 Gbps. GMSL2 uses different chips: MAX9295A (serializer) and MAX9296A (deserializer).
### What deserializer pairs with MAX96705?
MAX96705 pairs with MAX9286 (4-channel GMSL1 deserializer) or MAX96706 (single-channel). Do not confuse these with MAX9296A or MAX96792, which are GMSL2 deserializers.
### Is there a Linux kernel driver for MAX96705 and MAX9286?
Yes. A MAX9286 driver with MAX96705 support has been upstream in the Linux kernel since v5.1 under `drivers/media/i2c/max9286.c`.
### How do I check if the GMSL link has locked between MAX96705 and MAX9286?
Check `dmesg` for `max9286` messages after driver probe. A successful lock shows the number of cameras detected. A failed lock shows a link-lock error. Check the physical cable first, it is the most common cause.
### When should I upgrade from GMSL1 to GMSL2?
Upgrade when you need more bandwidth than 3.12 Gbps per lane or are starting a new hardware design. For existing GMSL1 hardware, the upgrade requires replacing camera modules, serializers, and the deserializer, generally only practical for a new product generation.
---
*ProventusNova has shipped GMSL1 and GMSL2 camera integrations on Jetson. [Talk to us if you are stuck on a serializer bring-up.](https://proventusnova.com/services)*
---
## Yocto build guide for MediaTek Genio: complete walkthrough
URL: https://proventusnova.com/blog/mediatek-genio-yocto-build-guide/
Published: 2026-06-04
Author: Aaron Angulo
Tags: mediatek, genio, yocto, embedded linux, bsp, kas, genio-flash
How to build the IoT Yocto BSP for MediaTek Genio from scratch. Host setup, kas, manifest, NDA flag, flashing, and common build errors.
Building the Yocto BSP for MediaTek Genio is straightforward once you have the right host setup, the correct manifest URL, and understand the NDA_BUILD flag that controls whether proprietary hardware acceleration is included. This guide covers every step from a fresh Ubuntu machine to a flashed board.
## Key Insights
- Ubuntu 22.04 LTS is the only officially supported build host, other distros cause hard-to-debug package failures
- `kas` is MediaTek's chosen build configuration tool, do not use `repo` or raw `bitbake` without it
- `NDA_BUILD=1` adds hardware video, NPU, and camera acceleration, requires a MediaTek NDA and the private BSP layer
- The download cache and sstate-cache are the biggest time savers, point multiple machines at a shared network location
- `genio-flash` handles the entire flash sequence, board must be in download mode before running it
## What are the host requirements?
MediaTek validates the IoT Yocto BSP against Ubuntu 22.04 LTS (Jammy). Minimum hardware:
| Resource | Minimum | Recommended |
|---|---|---|
| CPU | 4 cores | 8+ cores |
| RAM | 16 GB | 32 GB |
| Disk | 100 GB free | 250 GB SSD |
| OS | Ubuntu 22.04 LTS | Ubuntu 22.04 LTS |
Install required packages:
```bash
sudo apt-get update
sudo apt-get install -y \
gawk wget git diffstat unzip texinfo gcc build-essential \
chrpath socat cpio python3 python3-pip python3-pexpect \
xz-utils debianutils iputils-ping python3-git python3-jinja2 \
libegl1-mesa libsdl1.2-dev pylint xterm python3-subunit \
mesa-common-dev zstd liblz4-tool file locales libacl1
sudo locale-gen en_US.UTF-8
```
Install `kas`:
```bash
pip3 install kas
```
`kas` is a Python tool that manages Yocto layer fetching and configuration. MediaTek ships `.yml` configuration files that `kas` reads to clone all required layers at the right revisions.
## How do you fetch the BSP source?
The entry point is the `genio-yocto` manifest repository:
```bash
git clone https://gitlab.com/mediatek/aiot/rity/genio-yocto.git
cd genio-yocto
```
The repository contains a `kas/` directory with one configuration file per supported machine:
```
kas/
genio-350-evk.yml
genio-510-evk.yml
genio-520-evk.yml
genio-700-evk.yml
genio-720-evk.yml
genio-1200-evk.yml
```
Each `.yml` file pins the exact branch and commit for every layer. Run `kas checkout` to clone all layers without building:
```bash
kas checkout kas/genio-720-evk.yml
```
This fetches: `poky`, `meta-openembedded`, `meta-clang`, `meta-arm`, `meta-mediatek-bsp`, and `meta-rity`. If you have the NDA layer, you add it here.
## How do you configure the build?
The build is controlled by two things: the kas `.yml` file (which machine you target) and the `NDA_BUILD` environment variable.
**Public build (no NDA required):**
```bash
NDA_BUILD=0 kas build kas/genio-720-evk.yml
```
**NDA build (proprietary drivers + hardware acceleration):**
First, add the private layer to your kas configuration or place it in the `layers/` directory alongside the public layers. For a detailed breakdown of what the NDA build unlocks versus the public build, see [NDA vs public Yocto build on Genio](/blog/mediatek-genio-nda-vs-public-build). Then:
```bash
NDA_BUILD=1 kas build kas/genio-720-evk.yml
```
The NDA build includes:
- `mtkvdec` / `mtkh265enc`, hardware video codec GStreamer elements
- NeuroPilot SDK, NPU and MDLA inference runtime
- MT3D Mali GPU firmware
- Camera ISP drivers (`v4l2` ISP pipeline)
The public build falls back to software implementations for all of these.
## What does the layer structure look like?
| Layer | Type | Purpose |
|---|---|---|
| `poky` | Public | Yocto Project core (OE-Core + BitBake) |
| `meta-openembedded` | Public | Extended package collection |
| `meta-clang` | Public | LLVM/Clang toolchain |
| `meta-arm` | Public | ARM architecture support |
| `meta-mediatek-bsp` | Public | Public Genio BSP, drivers, u-boot, kernel |
| `meta-rity` | Public | RITY RTOS co-processor integration |
| `meta-mediatek-bsp-private` | NDA | Closed hardware blobs, NeuroPilot, VPU, ISP |
## What do you get after a successful build?
Output lands in `build/tmp/deploy/images//`. If you need to add GStreamer plugins to your image before flashing, see [adding GStreamer plugins to Genio IoT Yocto](/blog/mediatek-genio-yocto-gstreamer-plugins).
- `-.wic.zst`, the full flash image (partitioned)
- `u-boot.bin`, bootloader
- `Image`, kernel
- `.dtb`, device tree
The `.wic.zst` image contains all partitions and is what `genio-flash` uses.
## How do you flash the image?
Install `genio-flash`:
```bash
pip3 install genio-flash
```
Put the board in download mode: hold the **Download** button and power on (or press Reset while holding Download). A USB device should appear.
Flash:
```bash
genio-flash
```
Run from the build output directory or pass `--image-dir path/to/deploy/images/`. The tool selects the correct image and flashes all partitions. The process takes 2-5 minutes.
## What are the common build failures?
**`locale: Cannot set LC_ALL`**: Locale not generated. Run `sudo locale-gen en_US.UTF-8` and set `export LC_ALL=en_US.UTF-8`.
**`FileNotFoundError: kas`**: `kas` is not in PATH. Add `~/.local/bin` to PATH: `export PATH=$HOME/.local/bin:$PATH`.
**Out of disk space mid-build**: BitBake work directories consume 60-80 GB for a full build. Check with `df -h` before starting. Point `TMPDIR` to a larger partition in `conf/local.conf`.
**`meta-mediatek-bsp-private not found`**: You set `NDA_BUILD=1` but the private layer is not cloned. Either obtain the NDA layer from your MediaTek FAE or set `NDA_BUILD=0`.
**Recipe fetching fails (network errors)**: Some recipes fetch source at build time. If you are behind a proxy, set `http_proxy` and `https_proxy` before running `kas build`. Also set them in `conf/local.conf` as `BB_ENV_PASSTHROUGH_ADDITIONS`.
---
Building on MediaTek Genio and need help with BSP integration, Yocto customization, or getting to production faster? [ProventusNova](https://proventusnova.com) specializes in embedded Linux on Genio. See our [custom board bringup service](/services/custom-board-bringup) or [get in touch](https://proventusnova.com/contact).
---
## nvdrmvideosink + gdkpixbufoverlay: fix NVMM caps on Jetson
URL: https://proventusnova.com/blog/nvdrmvideosink-gdkpixbufoverlay-jetson-gstreamer/
Published: 2026-06-04
Author: Andres Campos
Tags: jetson, gstreamer, nvdrmvideosink, gdkpixbufoverlay, nvmm, overlay
gdkpixbufoverlay outputs video/x-raw but nvdrmvideosink needs NVMM. Get the exact double-nvvidconv caps chain and a copy-paste Jetson pipeline that runs.
If you are building a GStreamer pipeline on Jetson that needs to render video to a display without a running compositor, and you want to overlay PNG or JPEG graphics on top of the camera feed, the combination of `nvdrmvideosink` and `gdkpixbufoverlay` comes up quickly. The problem is that they have an incompatible memory format between them, `gdkpixbufoverlay` produces system RAM buffers, and `nvdrmvideosink` expects NVMM. The fix is a second `nvvidconv` stage, but getting the caps chain right takes some trial and error.
## Key Insights
- `nvdrmvideosink` renders directly via DRM/KMS, the right choice for headless or kiosk setups with no Wayland compositor
- `gdkpixbufoverlay` works with system RAM buffers; you must convert back to NVMM with `nvvidconv` before `nvdrmvideosink`
- The full pipeline requires two `nvvidconv` stages: one before the overlay (NVMM to system RAM) and one after (system RAM back to NVMM)
- For overlays that need to stay entirely in NVMM memory, `nvdsosd` (NVIDIA DeepStream OSD) is the alternative, but it requires the DeepStream SDK and uses a different metadata-based API
- The supported input format for `nvdrmvideosink` is `video/x-raw(memory:NVMM),format=NV12`, other formats may require an additional nvvidconv conversion step
## Understanding the memory incompatibility
`nvarguscamerasrc` outputs `video/x-raw(memory:NVMM),format=NV12`. That is GPU-mapped memory, fast, zero CPU copies, stays in hardware. `gdkpixbufoverlay` is a standard GStreamer element from the `gst-plugins-good` package. It reads your overlay image file, composites it onto each video buffer, and outputs `video/x-raw` (system RAM). `nvdrmvideosink` then expects `video/x-raw(memory:NVMM)` again.
So the memory path is:
```
NVMM (camera) → system RAM (gdkpixbufoverlay) → NVMM (nvdrmvideosink)
```
Both conversions happen via `nvvidconv`. The element handles both directions.
## Working pipeline
```bash
gst-launch-1.0 \
nvarguscamerasrc sensor-id=0 ! \
video/x-raw(memory:NVMM),width=1920,height=1080,format=NV12,framerate=30/1 ! \
nvvidconv ! \
video/x-raw,format=BGRx ! \
gdkpixbufoverlay location=/path/to/logo.png \
offset-x=20 offset-y=20 \
overlay-width=200 overlay-height=100 ! \
nvvidconv ! \
video/x-raw(memory:NVMM),format=NV12 ! \
nvdrmvideosink sync=false
```
The explicit caps after each `nvvidconv` are important. Without them, GStreamer may pick a format path that causes a second negotiation failure downstream.
For a live camera feed where you want to minimize latency, add a leaky queue before the display:
```bash
gst-launch-1.0 \
nvarguscamerasrc sensor-id=0 ! \
video/x-raw(memory:NVMM),width=1920,height=1080,format=NV12,framerate=30/1 ! \
nvvidconv ! \
video/x-raw,format=BGRx ! \
gdkpixbufoverlay location=/path/to/logo.png offset-x=20 offset-y=20 \
overlay-width=200 overlay-height=100 ! \
nvvidconv ! \
video/x-raw(memory:NVMM),format=NV12 ! \
queue max-size-buffers=1 leaky=2 ! \
nvdrmvideosink sync=false
```
## gdkpixbufoverlay properties
| Property | Type | Description |
|---|---|---|
| `location` | string | Path to PNG, JPEG, or any GdkPixbuf-supported image |
| `offset-x` | int | Horizontal position in pixels from left edge |
| `offset-y` | int | Vertical position in pixels from top edge |
| `overlay-width` | int | Scale overlay to this width (0 = original size) |
| `overlay-height` | int | Scale overlay to this height (0 = original size) |
| `alpha` | float | Overlay opacity, 0.0 to 1.0 |
| `relative-x` | float | Position as fraction of frame width (0.0 to 1.0) |
| `relative-y` | float | Position as fraction of frame height (0.0 to 1.0) |
To update the overlay image at runtime, set the `location` property on the element while the pipeline is running:
```python
overlay = pipeline.get_by_name("overlay")
overlay.set_property("location", "/path/to/new-logo.png")
```
## Which display sink to use
The three common display sinks on Jetson have different requirements:
| Sink | Compositor needed | Input format | Use case |
|---|---|---|---|
| `nvdrmvideosink` | No | `video/x-raw(memory:NVMM)` | Headless, kiosk, no desktop |
| `nv3dsink` | Yes (Weston/Wayland) | `video/x-raw(memory:NVMM)` | Wayland desktop |
| `waylandsink` | Yes (any Wayland) | `video/x-raw` | Standard Wayland |
If you are running under a full desktop environment (GNOME on JetPack 4.x, or Weston on JetPack 5/6), use `nv3dsink` instead. `nvdrmvideosink` requires exclusive access to the DRM device and will conflict with a running compositor.
## Common errors
**`nvdrmvideosink: DRM device not found`**: Check `ls /dev/dri/`. The display driver must be loaded. If the device exists but the error persists, another process (a compositor) may have exclusive access.
**`Negotiation failed` between `nvvidconv` and `nvdrmvideosink`**: Add explicit caps after the second `nvvidconv`: `video/x-raw(memory:NVMM),format=NV12`. Without explicit caps, GStreamer may select a format that `nvdrmvideosink` does not accept.
**`gdkpixbufoverlay: Failed to load`**: Verify the image path is correct and the image is a supported format. `gdkpixbufoverlay` requires `gst-plugins-good` with GdkPixbuf support compiled in; verify with `gst-inspect-1.0 gdkpixbufoverlay`.
For lower-latency overlay that stays entirely in NVMM, consider [NVIDIA's nvdsosd element from DeepStream](/blog/gstreamer-pipeline-examples-jetson), it draws text and rectangle overlays in GPU memory without the CPU round-trip.
## Frequently Asked Questions
### What is nvdrmvideosink and when should I use it on Jetson?
`nvdrmvideosink` renders video directly via DRM/KMS without a compositor. Use it in headless or kiosk setups where Wayland is not running. Use `nv3dsink` or `waylandsink` when a compositor is present.
### Why does nvdrmvideosink require video/x-raw(memory:NVMM)?
It reads directly from GPU-mapped DMA memory to compose the display output without a CPU copy. System RAM buffers are not accepted, use `nvvidconv` to convert before the sink.
### Can I use gdkpixbufoverlay directly before nvdrmvideosink?
No. `gdkpixbufoverlay` outputs system RAM buffers. You need an `nvvidconv` stage after it to convert back to NVMM before `nvdrmvideosink`.
### What is the difference between nvdrmvideosink, nv3dsink, and waylandsink on Jetson?
`nvdrmvideosink` is DRM/KMS direct, no compositor needed. `nv3dsink` is OpenGL-based, requires Wayland/Weston. `waylandsink` is standard Wayland protocol. For embedded headless use, `nvdrmvideosink` is the right choice.
### nvdrmvideosink says 'DRM device not found', how do I fix this?
Check `ls /dev/dri/`. The NVIDIA display driver must be loaded, and no compositor should have exclusive access to the DRM device.
---
*ProventusNova builds production GStreamer pipelines on Jetson for hardware startups. [Talk to us about your embedded video pipeline.](https://proventusnova.com/services)*
---
## How to Reduce End-to-End Latency in a GStreamer Pipeline on Jetson
URL: https://proventusnova.com/blog/reduce-gstreamer-pipeline-latency-jetson/
Published: 2026-06-04
Author: Aaron Angulo
Tags: jetson, gstreamer, latency, nvvidconv, nvmm, performance
Practical techniques for reducing GStreamer pipeline latency on NVIDIA Jetson: sync flags, queue tuning, NVMM memory, and hardware decode paths.
A GStreamer pipeline that works correctly at low load often develops latency problems in production, frame delay that grows over time, display output that lags behind the capture stream, or simply sluggish end-to-end response. On Jetson, most of these problems come from three sources: buffering, CPU copies, and display sync. Each is fixable once you know where to look.
## Key Insights
- The biggest single latency fix on a live camera pipeline is setting `sync=false` on the output sink, it can reduce display latency from hundreds of milliseconds to single digits
- Staying in NVMM memory (`video/x-raw(memory:NVMM)`) for as long as possible avoids DMA copies that add both latency and CPU load
- Queue elements with default settings buffer up to 200 frames, on a live feed, reduce `max-size-buffers` to 1 and set `leaky=2` to drop old frames
- Hardware decode with `nvv4l2decoder` keeps the output in NVMM and runs on the VPU, not the CPU; software decoders (`avdec_h264`) defeat this entirely
- Measuring latency with `GST_DEBUG=GST_LATENCY:5` before tuning tells you which element is actually the bottleneck
## The four latency sources and how to fix them
### 1. Display sync
The default `sync=true` on any GStreamer sink tells the element to hold each frame until its presentation timestamp arrives. For a live camera feed, this introduces as much latency as the buffer depth allows. Set `sync=false` on your output sink:
```bash
# Before: renders at presentation timestamp, adds buffering delay
nvvidconv ! nv3dsink
# After: renders frames immediately as they arrive
nvvidconv ! nv3dsink sync=false
```
This is the first thing to change on any live pipeline. The tradeoff is that without sync, the pipeline will not pace itself, if upstream produces faster than the display can consume, you need leaky queues (below) to manage the overflow.
### 2. Queue buffering
GStreamer's `queue` element buffers up to 200 frames by default. On a 30fps camera feed, that is almost 7 seconds of latency sitting in the queue. For a live pipeline where you always want the most recent frame:
```bash
# Buffers up to 200 frames, up to ~6.7s latency at 30fps
queue
# Buffers 1 frame, drops old frames when full
queue max-size-buffers=1 leaky=2
```
`leaky=2` means the queue drops the oldest buffer when full (downstream leaky). This keeps the output at the most recent frame rather than working through a backlog.
### 3. NVMM memory path
Every transition from `video/x-raw(memory:NVMM)` to `video/x-raw` (system RAM) forces a DMA copy through the CPU. This adds latency, increases CPU load, and defeats hardware acceleration. The rule is simple: stay in NVMM until you absolutely need system RAM.
```bash
# This pipeline forces a CPU copy between capture and display
nvarguscamerasrc ! video/x-raw(memory:NVMM) ! nvvidconv ! video/x-raw,format=BGRx ! nv3dsink sync=false
# This stays in NVMM all the way to the sink, no CPU copy
nvarguscamerasrc ! video/x-raw(memory:NVMM) ! nvvidconv ! video/x-raw(memory:NVMM),format=I420 ! nv3dsink sync=false
```
If you need system RAM for a specific consumer (OpenCV, Python appsink), extract it as late in the pipeline as possible and keep the display path in NVMM on a separate branch via `tee`.
### 4. Software decode
If your pipeline includes video decoding, the decoder choice matters significantly. `avdec_h264` is a libav software decoder that runs on the CPU and outputs system RAM. `nvv4l2decoder` is the Jetson hardware VPU decoder that outputs NVMM:
```bash
# Software decoder, CPU load, system RAM output, higher latency
... ! rtph264depay ! h264parse ! avdec_h264 ! videoconvert ! ...
# Hardware decoder, VPU, NVMM output, lower latency
... ! rtph264depay ! h264parse ! nvv4l2decoder ! nvvidconv ! ...
```
At 1080p30, the difference is typically 20 to 40ms of additional latency with `avdec_h264`, plus significant CPU overhead.
## A low-latency camera display pipeline
Combining all four fixes:
```bash
gst-launch-1.0 \
nvarguscamerasrc sensor-id=0 ! \
video/x-raw(memory:NVMM),width=1920,height=1080,format=NV12,framerate=30/1 ! \
queue max-size-buffers=1 leaky=2 ! \
nvvidconv ! \
video/x-raw(memory:NVMM),format=I420 ! \
nv3dsink sync=false
```
This keeps the full pipeline in NVMM, drops stale frames from the queue, and renders immediately without presentation timestamp sync.
## Measuring before you tune
Before changing anything, enable latency tracing to see where the time actually goes:
```bash
GST_DEBUG_NO_COLOR=1 GST_DEBUG=GST_LATENCY:5 gst-launch-1.0 \
nvarguscamerasrc sensor-id=0 ! \
video/x-raw(memory:NVMM),format=NV12 ! \
nvvidconv ! nv3dsink sync=false 2>&1 | grep latency
```
This logs the latency contribution of each element. Most pipelines show the queue or the display sync as the dominant source, not the conversion elements.
For more complete pipeline examples including RTSP streaming and multi-camera setups, the [GStreamer pipeline examples for Jetson](/blog/gstreamer-pipeline-examples-jetson) post covers the full range of production configurations.
## Frequently Asked Questions
### What causes high latency in a GStreamer pipeline on Jetson?
The three most common causes are large queue buffers, unnecessary CPU copies from leaving the NVMM memory path, and display sync enabled on the output sink. Each adds independent latency that compounds.
### Does setting sync=false on a GStreamer sink reduce latency?
Yes. With `sync=true` (the default), GStreamer holds frames until their presentation timestamp. With `sync=false`, frames render immediately on arrival. For live camera feeds, `sync=false` is almost always the right choice.
### What is NVMM memory and why does it affect GStreamer latency on Jetson?
NVMM is GPU-mapped DMA memory. Buffers in NVMM move between elements without CPU copies. Every transition to system RAM forces a DMA copy, adding latency and CPU load. Keep the pipeline in NVMM as long as possible.
### How do I measure GStreamer pipeline latency on Jetson?
Use `GST_DEBUG=GST_LATENCY:5` to enable GStreamer's built-in latency tracing. This logs each element's contribution and makes the bottleneck visible before you start tuning.
### Should I use nvv4l2decoder or avdec_h264 for decoding on Jetson?
Always use `nvv4l2decoder` on Jetson. It uses the hardware VPU and keeps output in NVMM. `avdec_h264` is a software decoder that produces system RAM buffers and runs significantly slower, particularly at 1080p and above.
---
*ProventusNova builds and optimizes GStreamer pipelines for production Jetson deployments. [Talk to us about your pipeline.](https://proventusnova.com/services)*
---
## Who Can Help Fix Camera Integration Issues on NVIDIA Jetson?
URL: https://proventusnova.com/blog/who-can-help-fix-jetson-camera-integration-issues/
Published: 2026-06-04
Author: Andres Campos
Tags: jetson, camera integration, imx sensor, gstreamer, v4l2, debugging
Stuck on IMX sensor bring-up, GStreamer caps failures, or Argus not capturing on Jetson? Here is what the problem usually is and who can actually fix it.
Camera integration on NVIDIA Jetson fails in predictable ways, but diagnosing which layer is broken takes experience across all of them at once. The sensor might appear on I2C but produce no frames. Argus might fail while V4L2 works fine. The GStreamer pipeline might negotiate caps successfully and still deliver corrupted output. Each of these points to a different root cause, and working through them without Jetson-specific experience means reading documentation and guessing.
## Key Insights
- Camera integration failures on Jetson usually happen at one of four layers: I2C/power, V4L2 driver, device tree, or GStreamer, diagnosing which one first saves days of debugging
- A working `/dev/video0` does not mean Argus will work, they have different failure modes and the `tegra-camera-platform` DTS node is the most common hidden gap
- GMSL2 camera chains add two more failure surfaces: serializer link-lock and the I2C passthrough to the sensor behind the deserializer
- Fixing this work yourself is reasonable if you have the time and Jetson experience, hiring a specialist makes sense when the project timeline has a deadline
## The four layers where camera integration breaks
**Layer 1: I2C and power.** The first step in any camera bring-up is confirming the sensor is electrically alive. Run `i2cdetect -y ` and confirm the sensor appears at its expected I2C address. If it does not, the problem is hardware: power sequencing, missing pull-ups, wrong bus number, or damaged hardware. No software will fix this.
**Layer 2: V4L2 driver.** If the sensor appears on I2C but `/dev/video0` does not exist, the driver is not probing. Check `dmesg | grep ` for the probe sequence. Common causes: wrong compatible string in the device tree, missing clock, wrong reset GPIO, or a driver that was compiled but not loaded. Use `modprobe` to verify the module is present.
**Layer 3: Device tree overlay.** This is the most common hidden failure point. Even with a working V4L2 node, `nvarguscamerasrc` will fail if the `tegra-camera-platform` node in the camera DTS overlay is incomplete or wrong. The Tegra ISP requires specific entries: correct CSI port assignment, sensor mode table with matching format and framerate, power rail nodes, and lane count. The error message (`Failed to create capture session`) does not tell you which field is wrong.
**Layer 4: GStreamer pipeline.** Once the driver and DTS are correct, pipeline failures are usually caps negotiation issues or format path problems. The output of `nvarguscamerasrc` is always `video/x-raw(memory:NVMM),format=NV12`, any downstream element that does not accept NVMM input will cause a silent negotiation failure. The fix is usually adding `nvvidconv` before the format-incompatible element and specifying explicit caps.
## GMSL2 adds two more surfaces
For camera setups using a GMSL2 serializer/deserializer chain, the failure surface expands. Beyond the four layers above, you also need to verify that the serializer-to-deserializer GMSL2 link has locked, and that the I2C passthrough to the sensor behind the deserializer is working. The link-lock failure mode is particularly painful because the DTS can look correct while the serializer and deserializer are simply not communicating. Reading the `max9296` or `max96792` driver status via `dmesg` is the starting point.
We have a detailed guide on [GMSL2 camera bring-up with MAX9295/MAX9296 on Jetson Orin](/blog/gmsl2-camera-bringup-jetson-orin-max9295-max9296) that covers this diagnostic flow in depth.
## When to hire outside help
Most camera integration problems on Jetson are solvable in-house if you have Linux kernel driver experience and time to read the Tegra documentation. The case for outside help is when the project has a deadline and the diagnosis has stalled.
The signal that you need specialist help: you have a working I2C connection, a `/dev/video0` node, and still cannot get a frame through `nvarguscamerasrc` after two or more days of debugging. At that point, you are likely in the `tegra-camera-platform` DTS weeds, and someone who has fixed three of these before will find it in hours.
What to look for in a specialist: they should be able to describe the `tegra-camera-platform` node structure from memory, name a specific sensor they have brought up on Jetson, and quote a fixed price for the work rather than an open-ended hourly engagement.
## What the fix actually looks like
A typical engagement starts with a 30-minute call to understand what is working and what is not. From the debug output, `dmesg`, `v4l2-ctl`, and the DTS file, it is usually possible to identify the layer within the first hour. The actual fix is often a DTS correction, a sensor mode table entry, or a driver property. The GStreamer pipeline integration comes after that.
For more context on the [Argus API and camera driver architecture on Jetson](/blog/argus-api-camera-driver-jetson), that post covers the ISP pipeline and common configuration requirements in detail.
## Frequently Asked Questions
### Why does nvarguscamerasrc say 'no cameras available' on Jetson?
This almost always means the `tegra-camera-platform` node in your device tree overlay is misconfigured or not loaded. Verify with `dmesg | grep tegra-camrtc` and check that the DTB overlay is being applied at boot. A valid V4L2 node at `/dev/video0` does not guarantee Argus will work.
### Who should I call when I am stuck on Jetson camera integration?
ProventusNova specializes in Jetson camera bring-up, including IMX sensor drivers, GMSL2 chains, and GStreamer pipeline integration. We offer fixed-bid engagements so you know the cost upfront rather than paying by the debugging hour.
### How do I know if my camera integration issue is a driver problem or a hardware problem?
Run `i2cdetect -y ` first. If the sensor address does not appear, the problem is electrical. If the sensor appears but `/dev/video0` does not exist, the driver is not probing. If `/dev/video0` exists but capture fails, the issue is driver configuration or DTS.
### Can GStreamer caps negotiation failures cause camera capture to fail on Jetson?
Yes, but caps failures happen downstream of the driver. The output of `nvarguscamerasrc` is always `video/x-raw(memory:NVMM),format=NV12`, downstream elements must accept NVMM input or you need an `nvvidconv` stage between them.
### How long does it typically take to fix a stuck Jetson camera integration?
Simple cases, a misconfigured DTS node or wrong I2C address, resolve in hours. Complex cases involving GMSL2 link-lock failures or Argus mode table mismatches can take days. The wide range is why you want someone who has seen these failures before.
---
*ProventusNova fixes stuck Jetson camera integrations on a fixed-bid basis. [Describe your issue and we'll tell you if we can help.](https://proventusnova.com/services)*
---
## APU, NPU, VPU, and MDLA on MediaTek Genio: what each one does
URL: https://proventusnova.com/blog/mediatek-genio-apu-npu-vpu-mdla-explained/
Published: 2026-06-03
Author: Andres Campos
Tags: mediatek, genio, npu, vpu, mdla, apu, ai inference, embedded ai, neuropilot
Clear explanation of APU, NPU, VPU, and MDLA on MediaTek Genio. What each accelerator handles, which Genio SoCs include them, and when to use each.
MediaTek uses four terms, APU, NPU, VPU, and MDLA, that appear throughout the Genio documentation, forum posts, and NeuroPilot SDK. They refer to four distinct hardware blocks with different functions, and confusing them leads to misrouted workloads and incorrect performance expectations. Here is what each one actually does.
## Key Insights
- VPU is for video codec only, it is not an AI accelerator and has no connection to the NPU or MDLA
- APU is the marketing name for the entire AI subsystem; NPU and MDLA are the actual hardware blocks inside it
- MDLA is fast for convolutions but falls back to NPU for unsupported ops, your model's layer mix determines real throughput
- Genio 350 has no NPU or MDLA; the minimum AI-capable platform is Genio 510/700
- Published TOPS figures combine NPU and MDLA under peak conditions, benchmark your own model
## What is the VPU?
The VPU (Video Processing Unit) is the hardware video codec engine. It handles:
- **Decode**: H.264, H.265, VP9, AV1 (platform-dependent)
- **Encode**: H.264, H.265
In GStreamer, the VPU is accessed through two proprietary elements included in the [NDA BSP](/blog/mediatek-genio-nda-vs-public-build):
- `mtkvdec`, hardware video decoder
- `mtkh265enc`, hardware H.265 encoder
Without the NDA build, these elements are not available and video encode/decode falls back to CPU-based elements (`avdec_h264`, `x264enc`). The VPU has no relationship to AI inference. It does not appear in NeuroPilot, ONNX Runtime, or TFLite contexts.
## What is the APU?
APU stands for AI Processing Unit. It is MediaTek's umbrella term for the entire AI hardware subsystem on the SoC. When MediaTek publishes TOPS figures in datasheets or marketing materials, those figures refer to the APU as a whole, which internally contains the NPU cores and the MDLA.
The APU is the correct term when referring to the hardware block in system-level discussions or power management. In software, you do not program the APU directly, you target the NPU or MDLA through NeuroPilot, ONNX Runtime, or TFLite.
## What is the NPU?
The NPU (Neural Processing Unit) refers to the programmable inference cores within the APU. It supports a broad range of operation types and is the execution target for:
- [NeuroPilot SDK](/blog/mediatek-genio-inference-offline-neuropilot) (`neuron_delegate`)
- ONNX Runtime with `NeuronExecutionProvider`
- TFLite with Neuron delegate
The NPU can handle operations that the MDLA cannot, activations, normalizations, recurrent layers, and custom ops. It is more flexible but slower than the MDLA for operations they share.
NPU generation differs across Genio platforms:
- Genio 510/700: NPU Gen 1 (APUSYS 2.0)
- Genio 520/720: NPU Gen 2 (APUSYS 2.5) with MDLA 5.x
- Genio 1200: dual MDLA with NPU Gen 2
## What is MDLA?
MDLA (MediaTek Deep Learning Accelerator) is a fixed-function matrix accelerator within the APU. It is optimized specifically for the operations that dominate CNN inference, 2D convolutions, depthwise convolutions, matrix multiply, and batch normalization.
For models where these operations account for most of the compute (ResNet, MobileNet, YOLO), the MDLA provides the highest throughput and lowest power. TFLite models compiled with `ncc-tflite` are partitioned so supported layers go to MDLA and the rest fall back to NPU or CPU.
The TOPS numbers MediaTek publishes represent MDLA peak throughput. A model that runs 100% on MDLA achieves that number. A model with 20% unsupported ops will see noticeably less.
## How do they map across Genio platforms?
| Platform | SoC | VPU | NPU Gen | MDLA | AI TOPS |
|---|---|---|---|---|---|
| Genio 350 | MT8365 | H.264/H.265 decode | None | None | - |
| Genio 510 | MT8370 | H.264/H.265/VP9 | Gen 1 | None | ~2 TOPS |
| Genio 700 | MT8395 | H.264/H.265/VP9/AV1 | Gen 1 | MDLA 4.x | ~4 TOPS |
| Genio 520 | MT8371 | H.264/H.265/VP9 | Gen 2 | MDLA 5.x | ~4 TOPS |
| Genio 720 | MT8395S | H.264/H.265/VP9/AV1 | Gen 2 | MDLA 5.x | ~6 TOPS |
| Genio 1200 | MT8395 | H.264/H.265/VP9/AV1 | Gen 2 | Dual MDLA 5.x | ~8 TOPS |
*TOPS figures are approximate and reflect typical published values. Actual throughput depends on model and op support.*
For guidance on choosing between these platforms, see [Genio 510 vs 700 vs 1200: which MediaTek module for your product](/blog/mediatek-genio-510-vs-700-vs-1200).
## When to use which
**VPU**: Any video encode or decode workload. Use `mtkvdec` in GStreamer. Keep video processing on the VPU to avoid burning GPU or CPU on codec work.
**NPU via NeuroPilot**: General inference workloads. Use when your model has operations the MDLA does not support, or when using ONNX Runtime with `NeuronExecutionProvider`.
**MDLA via ncc-tflite**: CNN-heavy models (object detection, image classification, segmentation). Compile your TFLite model with `ncc-tflite` to partition it for MDLA execution. Best throughput per watt for supported architectures.
**GPU (Mali)**: OpenCL workloads, compute shaders, image processing. Not the primary inference path in NeuroPilot but useful for preprocessing and custom operators.
---
Working on AI inference on Genio and need help with NeuroPilot, model conversion, or BSP integration? [ProventusNova](https://proventusnova.com) specializes in embedded AI on MediaTek Genio. See our [edge AI deployment service](/services/edgeai-deployment) or [get in touch](https://proventusnova.com/contact).
---
## GStreamer + waylandsink on MediaTek Genio: display output setup
URL: https://proventusnova.com/blog/mediatek-genio-gstreamer-waylandsink-display/
Published: 2026-06-02
Author: Aaron Angulo
Tags: mediatek, genio, gstreamer, waylandsink, embedded linux, display, wayland
How to use waylandsink on MediaTek Genio for Wayland display output. Pipeline setup, multi-display config, and fixes for common failures.
On MediaTek Genio running IoT Yocto, `waylandsink` is the correct GStreamer element for sending video to a display. It integrates with the Weston Wayland compositor that runs by default in the BSP. Getting it working requires the right environment variables, a correct pipeline, and knowing how to target a specific physical output when your board has both DSI and HDMI active.
## Key Insights
- `waylandsink` only works when Weston is running, it is a Wayland client, not a DRM/KMS sink
- `WAYLAND_DISPLAY` must be set in the environment where `gst-launch-1.0` runs, SSH sessions do not inherit this automatically
- Use the `display` property to target a specific output (`HDMI-A-1`, `DSI-1`), without it, Weston picks the output
- `kmssink` bypasses Weston and writes directly to the framebuffer, use it only when running without a compositor
- Running two pipelines to two outputs simultaneously is supported on Genio 720 and 1200
## What is waylandsink and why does Genio use it?
`waylandsink` is a GStreamer element that renders video frames as a Wayland surface. It communicates with the running Weston compositor over the Wayland socket, and Weston handles compositing the surface onto the physical display.
IoT Yocto starts Weston by default on boot. Because Weston owns the display hardware, any application that wants to show video must go through Weston, which means using waylandsink, not kmssink or autovideosink (which tries X11 first and fails on a Wayland-only system).
The MediaTek-specific `waylandsink` in IoT Yocto is not the same as the upstream GStreamer waylandsink from `gstreamer1.0-plugins-bad`. It is a proprietary plugin that integrates with the MTK multimedia stack for zero-copy buffer handling between the decoder and the display. For the full list of GStreamer packages available in the Yocto build, see [adding GStreamer plugins to Genio IoT Yocto](/blog/mediatek-genio-yocto-gstreamer-plugins).
## How do you set up a basic display pipeline?
The minimal working pipeline:
```bash
export WAYLAND_DISPLAY=wayland-0
gst-launch-1.0 videotestsrc ! videoconvert ! waylandsink
```
With a V4L2 camera source:
```bash
export WAYLAND_DISPLAY=wayland-0
gst-launch-1.0 v4l2src device=/dev/video0 ! videoconvert ! waylandsink
```
With hardware-decoded video:
```bash
export WAYLAND_DISPLAY=wayland-0
gst-launch-1.0 filesrc location=test.mp4 ! qtdemux ! h264parse ! mtkvdec ! waylandsink
```
The `WAYLAND_DISPLAY` variable points to the Weston socket. On IoT Yocto it is typically `wayland-0` and the socket lives at `/run/user/0/wayland-0`. If you run as a non-root user, check `/run/user//` for the socket path.
## How do you target a specific display output?
Boards with both DSI and HDMI outputs need explicit output targeting. Without it, Weston puts the surface on whichever output it considers primary, which may not be what you want.
First, list available outputs:
```bash
weston-info | grep "output"
```
Output names follow the DRM connector convention: `DSI-1` for the MIPI DSI panel, `HDMI-A-1` for HDMI. Then specify the target:
```bash
gst-launch-1.0 videotestsrc ! videoconvert ! waylandsink display=HDMI-A-1
```
For two simultaneous outputs, run two pipelines:
```bash
# Terminal 1, DSI panel
gst-launch-1.0 v4l2src device=/dev/video0 ! videoconvert ! waylandsink display=DSI-1 &
# Terminal 2, HDMI monitor
gst-launch-1.0 filesrc location=video.mp4 ! qtdemux ! h264parse ! mtkvdec ! waylandsink display=HDMI-A-1 &
```
Both pipelines are independent Wayland clients. Weston composites them to their respective outputs.
## waylandsink vs kmssink: which to use?
| | waylandsink | kmssink |
|---|---|---|
| **Requires Weston** | Yes, Weston must be running | No, talks to DRM directly |
| **Conflicts with Weston** | No | Yes, will fail if Weston is active |
| **Compositor overhead** | One vsync (~16ms at 60fps) | None |
| **Zero-copy support** | Yes (MTK implementation) | Yes |
| **Multi-window/overlay** | Yes, Weston composites | No, single plane |
| **Use case** | Standard IoT Yocto application | Kiosk / bare framebuffer / headless |
Use `waylandsink` for any application running on the standard IoT Yocto image with Weston. Use `kmssink` only if you have stopped Weston and are building a system that owns the display hardware directly.
To stop Weston before using kmssink:
```bash
systemctl stop weston
gst-launch-1.0 videotestsrc ! videoconvert ! kmssink
```
## What are the common waylandsink failures?
**"Could not connect to Wayland display"**: `WAYLAND_DISPLAY` is not set or points to a non-existent socket. Check `ls /run/user/0/` for the actual socket name and export it.
**"No element waylandsink"**: The MTK waylandsink plugin is not installed. It comes from the [NDA BSP layer](/blog/mediatek-genio-nda-vs-public-build) (`meta-mediatek-bsp-private`). The public build includes a fallback but it lacks hardware acceleration.
**Black window appears but no video**: Pipeline is running but `videoconvert` is producing a format waylandsink cannot handle. Add `! video/x-raw,format=NV12 !` before waylandsink to force a compatible format.
**Video appears on wrong output**: `display` property is not set and Weston chose the other output. Use `waylandsink display=HDMI-A-1` explicitly.
**Tearing on HDMI**: Weston's frame sync is not aligned with your source. Add `sync=true` to waylandsink to force timestamp-based synchronization.
---
Building on MediaTek Genio and need help with GStreamer pipelines, display bringup, or Yocto BSP work? [ProventusNova](https://proventusnova.com) specializes in embedded Linux on Genio. See our [GStreamer pipeline service](/services/gstreamer) or [get in touch](https://proventusnova.com/contact).
---
## GMSL2 vs FPD-Link III for Jetson: SerDes comparison
URL: https://proventusnova.com/blog/gmsl2-vs-fpd-link-iii-jetson-serdes-comparison/
Published: 2026-05-25
Author: Andres Campos
Tags: gmsl2, fpd-link, serdes, jetson, camera, comparison, max9296, ds90ub954
Compare GMSL2 and FPD-Link III for Jetson cameras. Cable distance, data rate, multi-camera topology, PoC, driver support, and which SerDes to choose.
Engineers choosing a SerDes technology for a Jetson camera system typically come down to GMSL2 (Analog Devices MAX9295/MAX9296) or FPD-Link III (TI DS90UB953/DS90UB954). Both solve the same problem, transporting MIPI CSI-2 video from a remote camera over coaxial cable, but they differ in driver support, data rate, chip ecosystem, and the amount of custom kernel work required to bring them up on Jetson.
## Key Insights
- GMSL2 has NVIDIA reference drivers in L4T; FPD-Link III does not, this single factor dominates the decision for new Jetson designs
- Both support up to 15m cable distance, power over coax, and hardware frame sync
- GMSL2 runs at 6 Gbps per link; FPD-Link III at 4.16 Gbps, GMSL2 supports higher-resolution or higher-frame-rate sensors
- The image sensor (IMX390, OX03C, etc.) is SerDes-agnostic, camera module vendors offer both variants
- Mixing both in one system is possible but requires two separate deserializers and two separate NVCSI connections
## Side-by-side comparison
| | GMSL2 | FPD-Link III |
|---|---|---|
| **Primary chipmaker** | Analog Devices (was Maxim) | Texas Instruments |
| **Common serializer** | MAX9295A | DS90UB953-Q1 |
| **Common deserializer** | MAX9296A (dual), MAX96724 (quad) | DS90UB954-Q1 (quad) |
| **Link data rate** | Up to 6 Gbps | Up to 4.16 Gbps |
| **Cable type** | Coax (RG-6 typical) | Coax or shielded twisted pair |
| **Max cable distance** | 15m | 15m |
| **Power over coax** | Yes | Yes |
| **Back channel (I2C/GPIO)** | Yes, GMSL2 control channel | Yes, FPD-Link III back channel |
| **Frame sync** | FSYNC via control channel | SYNC via back channel |
| **Virtual channels** | Up to 4 VC per deserializer output | Up to 4 VC per deserializer output |
| **NVIDIA L4T drivers** | Reference drivers included | Not included, custom driver required |
| **Automotive qualification** | AEC-Q100 (MAX9295A) | AEC-Q100 (DS90UB953-Q1) |
| **Common use in Jetson** | Very common, NVIDIA reference design | Less common, requires BSP work |
## Why GMSL2 is the default choice for Jetson
NVIDIA's L4T kernel source includes complete reference drivers for the MAX9295A serializer and MAX9296A/MAX96724 deserializer. These drivers handle:
- Link training and lock detection
- I2C tunnel and address reassignment
- MIPI output configuration
- FSYNC routing for multi-camera sync
- Integration with the tegra-camera-platform framework
This means GMSL2 bring-up on Jetson Orin starts from a working reference point. You write a sensor driver for your specific image sensor, the SerDes layer is already handled.
FPD-Link III has no equivalent in L4T. Bringing up a DS90UB954 on Jetson means writing the deserializer driver from scratch: I2C tunnel management, link lock handling, MIPI output configuration, and tegra-camera-platform integration. This is a real engineering project, typically 2–4 weeks of kernel driver work, before you even get to sensor bringup.
Unless your camera module vendor ships a Jetson-specific BSP with FPD-Link III support already integrated, the choice effectively is: use GMSL2 and start from NVIDIA's reference, or use FPD-Link III and write the base driver yourself.
## Data rate: when 6 Gbps vs 4.16 Gbps matters
At typical camera resolutions and frame rates, FPD-Link III's 4.16 Gbps is sufficient:
- 1920×1080 @ 30fps, RAW12 → ~750 Mbps → well within both limits
- 1920×1080 @ 60fps, RAW12 → ~1.5 Gbps → within both limits
- 3840×2160 (4K) @ 30fps, RAW12 → ~3 Gbps → within both, but tight for FPD-Link III with overhead
Where GMSL2's 6 Gbps headroom matters: high-speed sensors (120fps+), wide-format sensors (>3840 wide), or sensors with high bit depth (RAW16) where the raw data rate approaches the link capacity. For standard automotive camera resolutions (1080p at 30fps), data rate is not a differentiator.
## Multi-camera configurations
Both SerDes systems support aggregating multiple cameras onto a single MIPI output using virtual channels, but the topology differs.
**GMSL2 multi-camera topology:**
```
Camera 0 → MAX9295A → MAX9296A (dual-link) → MIPI VC0+VC1 → Jetson NVCSI
Camera 1 → MAX9295A ↗
Camera 0-3 → MAX9295A × 4 → MAX96724 (quad-link) → MIPI VC0-VC3 → Jetson NVCSI
```
**FPD-Link III multi-camera topology:**
```
Camera 0-3 → DS90UB953 × 4 → DS90UB960 (quad-link) → MIPI VC0-VC3 → Jetson NVCSI
```
The DS90UB960 supports 4 input ports like the MAX96724. Both can aggregate 4 cameras onto a single MIPI link. The wiring and bring-up sequence are similar; the difference is the driver layer.
## Power over coax: powering the camera from the host
Both GMSL2 and FPD-Link III support Power over Coax (PoC). The deserializer injects DC voltage onto the coaxial cable, and the serializer (on the camera board) has a PoC regulator that extracts it.
Practical limits:
- **MAX9296A PoC**: up to 800mA at 8.6V nominal (varies by operating conditions), sufficient for a camera module and serializer with a small image sensor
- **DS90UB954 PoC**: similar current capability, check the specific revision datasheet
Neither is suitable for powering high-power cameras (thermal IR sensors, high-frame-rate sensors with significant analog front-end power). For those, run a separate power conductor alongside the coax or use a dedicated power injection board.
## Choosing between GMSL2 and FPD-Link III
**Use GMSL2 when:**
- Your target platform is NVIDIA Jetson (Orin NX, Orin AGX)
- You want to start from NVIDIA's reference drivers
- Your camera module vendor offers GMSL2 variants
- You need the extra data rate headroom for high-resolution sensors
- You are not committed to a specific automotive platform that mandates FPD-Link III
**Use FPD-Link III when:**
- Your existing platform ecosystem (other SOCs, automotive ECU) is already FPD-Link III
- Your camera module vendor only offers FPD-Link III and you cannot switch
- You have a BSP vendor who provides FPD-Link III Jetson support
- You're integrating into an automotive ADAS platform where TI's ecosystem is standard
For GMSL2 bring-up on Jetson Orin from scratch, the full sequence is in [GMSL2 camera bring-up on Jetson Orin: MAX9295/MAX9296 setup](/blog/gmsl2-camera-bringup-jetson-orin-max9295-max9296). For the SerDes architecture overview, see [GMSL2 SerDes explained: MAX9295 and MAX9296 for Jetson bring-up](/blog/gmsl2-serdes-max9295-max9296-jetson).
If you need a custom GMSL2 or FPD-Link III bring-up on a custom carrier board or with a non-reference sensor, the [GMSL camera driver development service](/services/gmsl) covers what a scoped engagement typically involves.
The MAX9295A and MAX9296A datasheets with full register maps are on the [Analog Devices product pages](https://www.analog.com/en/products/max9296a.html). The DS90UB953 and DS90UB954 datasheets are on the [TI product pages](https://www.ti.com/product/DS90UB954-Q1).
---
## Jetson Orin AGX vs Orin NX vs Orin Nano: which to pick
URL: https://proventusnova.com/blog/jetson-orin-agx-vs-orin-nx-vs-orin-nano/
Published: 2026-05-25
Author: Aaron Angulo
Tags: jetson orin, orin nx, orin nano, jetson comparison, edge ai, module selection
Compare Jetson AGX Orin, Orin NX, and Orin Nano on TOPS, memory bandwidth, I/O, power, and price. Pick the right module for your edge AI project.
Choosing between Jetson AGX Orin, Orin NX, and Orin Nano comes down to three things: how much inference throughput your application actually needs, how many I/O interfaces your hardware design requires, and what power budget you're working within. The modules share the same Ampere GPU architecture and run the same JetPack 6 software stack, the differences are in how much of that hardware is exposed and at what power draw.
## Key Insights
- All three run JetPack 6 and the same software stack, switching between them is a hardware and DTS change, not a software port
- Orin NX and Orin Nano are pin-compatible on the same carrier board; AGX Orin uses a different, larger form factor
- The DLA is present on AGX Orin and Orin NX but absent on Orin Nano, this is the most important functional difference for inference workloads
- Memory bandwidth drops from 204 GB/s (AGX) to 68 GB/s (Nano), a bigger real-world bottleneck than TOPS
- PCIe lane count limits peripheral expansion: AGX Orin can drive NVMe + Ethernet + PCIe capture simultaneously; Orin NX and Nano cannot
## Full specification comparison
| | AGX Orin 64GB | AGX Orin 32GB | Orin NX 16GB | Orin NX 8GB | Orin Nano 8GB | Orin Nano 4GB |
|---|---|---|---|---|---|---|
| **CPU** | 12-core A78AE | 12-core A78AE | 8-core A78AE | 6-core A78AE | 6-core A78AE | 4-core A78AE |
| **GPU CUDA cores** | 2048 | 2048 | 1024 | 1024 | 1024 | 512 |
| **DLA cores** | 2 | 2 | 2 | 2 | None | None |
| **AI performance** | 275 TOPS | 275 TOPS | 100 TOPS | 70 TOPS | 40 TOPS | 20 TOPS |
| **Memory** | 64GB LPDDR5 | 32GB LPDDR5 | 16GB LPDDR5 | 8GB LPDDR5 | 8GB LPDDR5 | 4GB LPDDR5 |
| **Memory BW** | 204.8 GB/s | 204.8 GB/s | 102.4 GB/s | 68.3 GB/s | 68.3 GB/s | 34.1 GB/s |
| **Storage** | 64GB eMMC | 64GB eMMC | 16GB eMMC | 16GB eMMC | 16GB eMMC | 16GB eMMC |
| **PCIe** | 4.0 ×16 | 4.0 ×16 | 4.0 ×4 | 4.0 ×4 | 3.0 ×4 | 3.0 ×4 |
| **MIPI CSI cameras** | Up to 16 | Up to 16 | Up to 4 | Up to 4 | Up to 4 | Up to 4 |
| **USB 3.2 Gen 2** | 3× | 3× | 2× | 2× | 2× | 2× |
| **GbE** | 10GbE | 10GbE | 1GbE | 1GbE | 1GbE | 1GbE |
| **CAN FD** | 2× | 2× | 2× | 2× | 2× | 1× |
| **Power (max TDP)** | 60W | 60W | 25W | 25W | 15W | 15W |
| **Module price (approx)** | ~$899 | ~$499 | ~$299 | ~$199 | ~$149 | ~$99 |
| **Form factor** | AGX (87×100mm) | AGX (87×100mm) | Module (69.6×45mm) | Module (69.6×45mm) | Module (69.6×45mm) | Module (69.6×45mm) |
*Prices are NVIDIA suggested retail for production quantities. Devkit pricing is higher.*
## The DLA is the most important functional difference
The Deep Learning Accelerator (DLA) is a fixed-function neural network accelerator separate from the GPU. It is present on AGX Orin and Orin NX, and absent on Orin Nano.
Why it matters: TensorRT can partition models to run layers on DLA and the rest on GPU, freeing the GPU for other tasks. In a camera pipeline running continuous inference, the DLA handles the inference engine while the GPU handles preprocessing, postprocessing, and other concurrent workloads. Without the DLA, all inference runs on the GPU, which works, but consumes more power and competes with other GPU work.
In practice: if you are running a YOLOv8 model on a camera stream alongside GStreamer decode and display, the DLA on Orin NX lets the inference run independently of the GPU, keeping the overall pipeline throughput higher. On Orin Nano, everything shares the GPU, and you will hit GPU utilization limits sooner.
For purely CPU-bound workloads (ROS2 processing, control loops, sensor fusion without neural networks), the DLA difference is irrelevant and Orin Nano is a perfectly capable platform.
## Memory bandwidth is the real runtime bottleneck
TOPS figures are easy to compare but memory bandwidth is what you actually feel in production. The GPU and DLA share memory with the CPU on all Jetson modules. High-resolution video decode, GStreamer pipeline buffers, model activations, and postprocessing all compete for that bandwidth.
A concrete example: running two concurrent 1920×1080@30fps camera streams through a YOLOv8-M model:
- **AGX Orin**: saturates at about 20% of memory bandwidth, headroom for more workloads
- **Orin NX 16GB**: saturates at about 40%, workable for 2 cameras, tight for 4
- **Orin Nano 8GB**: saturates at about 65–70%, leaves little room for additional processing
If you are building a surround-view system with 4+ cameras doing concurrent inference, memory bandwidth on Orin Nano will bottleneck you before GPU compute does.
## Camera I/O: how many MIPI CSI cameras fit
AGX Orin has substantially more MIPI CSI-2 lane capacity than the NX and Nano modules:
- **AGX Orin**: 8 MIPI CSI-2 ports, up to 16 cameras total with a deserializer
- **Orin NX / Orin Nano**: 4 MIPI CSI-2 ports, up to 4 cameras directly or up to 8 via GMSL2 with a quad-deserializer
For GMSL2 camera systems, the deserializer aggregates multiple cameras onto fewer MIPI lanes. A MAX96724 quad-deserializer routes 4 GMSL2 cameras over 2 MIPI ports, so Orin NX can support 4–8 GMSL2 cameras in practice. For 6+ camera surround-view or full surround-view AVM systems, AGX Orin is typically required.
For direct CSI cameras (no SerDes): Orin NX supports 4 simultaneous cameras. AGX Orin supports up to 16 with the right carrier board.
## PCIe expansion: when AGX Orin is the only option
If your carrier board design requires multiple PCIe devices simultaneously, for example, an NVMe SSD plus a PCIe Ethernet controller plus a PCIe-connected FPGA or capture card, only AGX Orin has the lane budget.
Orin NX and Orin Nano expose ×4 PCIe lanes total. In practice this means one NVMe SSD OR one additional PCIe device, not both simultaneously. For designs that need full PCIe expansion, plan for AGX Orin from the start.
## Which module to choose
**Choose AGX Orin when:**
- You need 6 or more MIPI CSI cameras
- You need multiple PCIe devices simultaneously (NVMe + Ethernet + other)
- Your inference workload requires more than 100 TOPS
- You need 10GbE on the module
- You are in a development phase and want maximum headroom
**Choose Orin NX 16GB when:**
- Your application needs 1–4 cameras
- You need DLA for sustained inference at low power
- Your PCIe requirements fit within ×4
- You're building a product and 25W fits your thermal design
- You want Orin NX and Orin Nano to share the same carrier board for cost-tier SKUs
**Choose Orin Nano when:**
- Cost and power envelope are the primary constraints
- Your workload doesn't require DLA (simple models, CPU-based processing, or occasional inference)
- You can accept PCIe Gen 3 ×4
- You are prototyping and will move to NX for production if performance headroom is needed
## Carrier board compatibility
Orin NX and Orin Nano use the same 260-pin SO-DIMM style connector and are pin-compatible with each other and with Jetson Xavier NX. A carrier board designed for Xavier NX will generally work with Orin NX and Orin Nano, with a DTS and BSP update, not a hardware change.
AGX Orin uses a different 699-pin module connector and requires a carrier board designed specifically for the AGX form factor. NVIDIA's AGX Orin Developer Kit carrier board is the reference design. Third-party carrier boards for AGX Orin are available from Auvidea, Leopard Imaging, Sievert Larsen, and others.
For GMSL2 camera bring-up on any of these modules, the process is the same, the module choice affects how many cameras you can connect and which NVCSI ports you route them to. See [GMSL2 camera bring-up on Jetson Orin](/blog/gmsl2-camera-bringup-jetson-orin-max9295-max9296) for the full setup sequence.
For help selecting the right module and carrier board for your application, the [Jetson expert support service](/get-expert-nvidia-jetson-support) covers module selection, carrier board design review, and BSP bring-up.
NVIDIA's official module comparison is on the [Jetson modules page](https://www.nvidia.com/en-us/autonomous-machines/embedded-systems/jetson-orin/). The full hardware design guidelines for each module are in the [Jetson Linux Developer Guide](https://docs.nvidia.com/jetson/archives/r36.4.3/DeveloperGuide/index.html).
---
## BSP Development Cost: DIY vs Outsource on NVIDIA Jetson
URL: https://proventusnova.com/blog/bsp-development-cost-nvidia-jetson/
Published: 2026-05-19
Author: Aaron Angulo
Tags: jetson, bsp, embedded linux, outsource embedded, board support package
BSP development cost on NVIDIA Jetson: 3-6 months to hire, $150K-$200K fully-loaded annual cost vs a fixed-bid outsource engagement. The real numbers.
BSP development cost on NVIDIA Jetson is the question nobody asks until they're already six weeks into it and the carrier board still isn't booting. At that point, the question usually sounds like: "How long is this supposed to take?" The answer depends entirely on who's doing it and what they've seen before. For an engineer new to JetPack, it takes 3-6 months. For someone who's done ten of these, it takes 1-3 weeks.
The cost difference is not a skill gap. It's a pattern library gap.
**The short answer, in numbers:** building the capability in-house costs **$94,000–$213,000 and 5–9 months before first productive BSP output** (full model below: hiring, salary, and ramp). A scoped fixed-bid engagement delivers a booting, validated BSP in **weeks**, with the cost known before work starts. If you're mid-project and the board still isn't booting, [book a scoping call](/discovery-call): the first conversation is free and you'll leave with a concrete estimate either way.
## Key Insights
- DIY BSP development with an in-house hire costs $150,000-$200,000 annually plus 3-6 months of hiring time and 2-3 months of ramp before productive output on your specific hardware.
- The 30% Tax™ applies to BSP work harder than almost any other Jetson task. JetPack version-specific failure modes, DTBO handling changes between R35 and R36, and carrier board-specific PMIC timing aren't documented anywhere. They're learned by debugging.
- The Silicon Ceiling™ hits BSP-blocked teams especially hard because everything upstream -- camera, inference, GStreamer -- can't run until the board is booting clean.
- A fixed-bid BSP engagement delivers a validated, documented board support package for a specific carrier board in 7-21 days, with full IP transfer.
- The right exit state for a BSP engagement: your board boots clean, your custom peripherals are configured in device tree, the BSP is documented well enough that a new engineer can maintain it without calling us.
## What Is a Jetson BSP and Why Is It Hard?
A board support package for NVIDIA Jetson is the complete software foundation that makes your custom carrier board run on Linux. It includes:
- U-Boot bootloader configuration for your carrier board's storage device, PMIC, and power sequencing
- Linux kernel with your carrier board's device tree describing every peripheral -- I2C buses, SPI, UART, USB, PCIe, GMSL2 camera interfaces, Ethernet PHY
- JetPack-specific drivers: NVCSI for camera, NVSRCMGR for power, XHCI for USB, PCIe endpoint configuration
- Device tree overlays (DTBO) applied at boot via the UEFI Plugin Manager or U-Boot extlinux
- Flash scripts (`doflash.sh` or `initrd-flash`) configured for your storage layout
Without a working BSP, none of the application stack runs. The camera doesn't enumerate. The inference pipeline can't load. GStreamer has no capture source. Every milestone downstream is blocked.
What makes Jetson BSP work hard is not the volume of knowledge required -- it's that the failure modes are JetPack version-specific, carrier board-specific, and largely undocumented outside teams who've hit them in production.
A device tree that boots correctly on JetPack 5 (L4T R35) may fail silently on JetPack 6 (L4T R36) because PHY node bindings changed. The correct DTBO application mechanism changed between R35 and R36: `TEGRA_PLUGIN_MANAGER_OVERLAYS` must use `:append` (not assignment) or it silently removes required platform overlays. None of this is obvious from the official documentation.
The engineer who debugged it last week knows it immediately. The engineer debugging it for the first time spends three weeks finding it.
## The Real Cost of DIY BSP Development on Jetson
Let's run the full cost model for in-house BSP development on a custom Jetson Orin carrier board.
**Hiring cost**
| Item | Estimate |
|------|----------|
| Time-to-hire (job posting to accepted offer) | 3-6 months |
| Engineering time spent on hiring (interviews, evaluation) | 4-8 weeks of lead engineer time |
| Engineering burn during hiring period | $60,000-$150,000 at $20k/month |
The candidate pool for senior embedded Linux engineers with genuine JetPack depth -- U-Boot, device tree, NVCSI, JetPack version-specific BSP configuration -- is thin. You're competing with NVIDIA, automotive OEMs, and every robotics startup at Series A or later that also needs this exact skill set.
**Salary and total compensation**
| Item | Estimate |
|------|----------|
| Base salary | $150,000-$220,000 |
| Equity | 0.25-0.75% |
| Benefits + employer taxes | $20,000-$30,000/year |
| Fully-loaded annual cost | $170,000-$250,000 |
| Fully-loaded monthly cost | $14,000-$21,000 |
**Ramp cost**
Even a strong embedded Linux engineer with prior Jetson experience needs 2-3 months to ramp on your specific carrier board design, your JetPack version, your camera configuration, and your application requirements. That ramp isn't billable output -- it's platform orientation.
| Item | Estimate |
|------|----------|
| Ramp period | 2-3 months |
| Cost during ramp (30% Tax on $17k/month) | $10,000-$15,000 lost per month |
| Total ramp cost | $20,000-$45,000 |
**Total DIY cost to first productive BSP output**
| Phase | Duration | Cost |
|-------|----------|------|
| Hiring | 3-6 months | $60,000-$150,000 (opportunity cost) |
| Ramp | 2-3 months | $34,000-$63,000 |
| **Total before useful output** | **5-9 months** | **$94,000-$213,000** |
That's before they've resolved the BSP blocker you hired them to fix.
## The 30% Tax™ on Jetson BSP Work
The 30% Tax™ describes the 20-30% of engineering hours on Jetson BSP work that goes to platform ramp rather than actual deliverables. For BSP specifically, it's often higher.
The reason: BSP failure modes on Jetson don't generalize. A JetPack 5 bring-up expert can miss the JetPack 6 DTBO handling change (`TEGRA_PLUGIN_MANAGER_OVERLAYS` assignment vs `:append`) entirely. A carrier board expert on one design has to relearn PMIC soft-start timing for each new design. An engineer who has debugged USB enumeration failures on one board configuration hasn't necessarily seen the specific PHY property deprecation that breaks another.
For BSP work at $17,000/month fully-loaded, 25% ramp cost = $4,250/month going to platform orientation. Over a 6-month initial period: $25,500 that doesn't produce a working BSP.
This isn't fixed by hiring a better engineer. It's fixed by starting from a pre-validated foundation where those failure modes are already accounted for.
## What a Fixed-Bid BSP Engagement Delivers
A ProventusNova BSP engagement for a custom Jetson Orin carrier board covers:
1. **Triage (Days 1-3):** Reproduce the failure, identify root cause, document the specific carrier board configuration. Board not booting, USB not enumerating, camera not streaming -- we find the exact failure before writing any code.
2. **BSP Foundation (Days 3-10):** U-Boot configuration, device tree for the carrier board peripherals, JetPack-specific PMIC and power sequencing, DTBO overlays applied via the correct mechanism for the JetPack version.
3. **Peripheral integration (Days 10-21):** Camera driver bring-up, Ethernet PHY, USB, PCIe, custom I2C/SPI peripherals. Each peripheral validated with the correct diagnostic at each step.
4. **Handoff (Final 2 days):** Documented BSP: annotated device tree, U-Boot config notes, flash script configuration, bring-up guide. Your team maintains and extends independently. No ongoing dependency.
**Timeline and price comparison**
| | DIY (in-house hire) | ProventusNova fixed-bid |
|--|---------------------|------------------------|
| Time to working BSP | 5-9 months | 7-21 days |
| Ramp cost | $20,000-$45,000 | $0 (absorbed) |
| Annual cost after | $170,000-$250,000 | $0 (IP transfer, no ongoing) |
| IP ownership | Employer owns code | Client owns everything |
| Documentation | Variable | Annotated source + guide |
## When DIY BSP Development Makes Sense
Building in-house BSP capability makes sense when:
- Your product roadmap involves multiple custom carrier board designs over 2+ years
- You need a BSP engineer embedded in hardware design reviews from the beginning of each board spin
- You have the runway to absorb 5-9 months before meaningful BSP output
- The volume of ongoing BSP work justifies a senior headcount permanently
It doesn't make sense when:
- A field trial or investor demo is the near-term milestone
- One specific carrier board bring-up is blocking everything downstream
- You'd prefer a documented, transferable foundation to a vendor dependency
The pattern we see most: a startup outsources initial BSP development to us, gets a documented foundation with full IP transfer, then hires a BSP engineer who starts from that validated baseline. That engineer is productive in weeks, not months, because the foundation is already built and documented. For a full cost model comparing [embedded software development outsourcing versus in-house hire](/blog/outsource-embedded-software-development-vs-hire), including the five criteria to use when evaluating any outsourcing partner, see the complete breakdown.
## Frequently Asked Questions
### How much does BSP development cost for NVIDIA Jetson on a custom carrier board?
DIY BSP development costs $150,000-$200,000 annually in fully-loaded salary, plus 3-6 months of hiring time and 2-3 months of ramp before productive output. Total cost before first working BSP: $94,000-$213,000 over 5-9 months. A fixed-bid ProventusNova BSP engagement delivers a validated, documented BSP in 7-21 days with full IP transfer.
### How long does Jetson BSP development take for a custom carrier board?
With an experienced BSP engineer who has prior Jetson depth on your specific JetPack version, initial BSP bring-up for a well-designed carrier board with standard peripherals takes 1-3 weeks. Without Jetson-specific experience, the same scope takes 3-6 months as the engineer learns JetPack version-specific failure modes that aren't documented outside teams who've hit them in production.
### What does a BSP engineer with Jetson depth cost to hire?
A senior embedded Linux engineer with NVIDIA Jetson BSP depth commands $150,000-$220,000 in base salary at a hardware startup, plus equity and benefits, for a fully-loaded annual cost of $170,000-$250,000. Time-to-hire is 3-6 months in a competitive market where NVIDIA, automotive OEMs, and robotics companies compete for the same candidates.
### What is a board support package (BSP) for Jetson and what does it include?
A Jetson BSP is the complete software foundation that makes your custom carrier board run: U-Boot bootloader configuration, Linux kernel with device tree for your carrier board peripherals, JetPack-specific drivers, device tree overlays for custom hardware, and flash scripts to deploy it. Without a working BSP, none of the application stack -- camera, inference, GStreamer -- can run.
### Can I outsource Jetson BSP development and still own the code?
Yes. ProventusNova delivers full IP transfer on every engagement -- the client owns the complete BSP: U-Boot config, device tree, kernel patches, driver source, and flash scripts. There's no vendor lock-in and no ongoing dependency. The handoff includes annotated source code and a bring-up guide so your in-house team can maintain and extend independently.
---
*ProventusNova delivers validated Jetson BSP development in days, not months -- fixed-bid, full IP transfer, no vendor lock-in. [See our Custom Board Bring-up service](https://proventusnova.com/services/custom-board-bringup) or [book a Proof Sprint scoping call](https://proventusnova.com/contact).*
---
## Embedded Software Development Outsourcing vs In-House Hire
URL: https://proventusnova.com/blog/outsource-embedded-software-development-vs-hire/
Published: 2026-05-19
Author: Andres Campos
Tags: embedded engineer, outsource embedded software, embedded software development outsourcing, edgeai, hardware startup, cost comparison
Embedded software development outsourcing vs in-house hire: 3–6 month hiring window, 2–3 month ramp. Real cost breakdown for EdgeAI hardware startups.
When a founder says "we'll just hire someone," they're making a financial decision. The problem is they're usually making it without running the actual numbers. Outsource embedded software development vs hire is not a values question or a control question -- it's a math question. The math is why most hardware startups that come to us have already spent $80,000 to $150,000 and four months finding out the hard way.
## Key Insights
- Time-to-hire for a qualified embedded engineer with real Jetson depth is 3-6 months. Add 2-3 months of ramp. You're looking at 5-9 months before useful output on the problem blocking you right now.
- The Silicon Ceiling™ doesn't wait. Every month your board isn't shipping costs $15,000-$25,000 in engineering burn, plus the opportunity cost of delayed field trials and funding conversations.
- The 30% Tax™ applies to internal hires the same as contractors. Any engineer who hasn't debugged your exact JetPack version and carrier board combination pays it.
- A fixed-bid specialist engagement eliminates the ramp cost from your invoice entirely. You pay for delivery, not learning.
- The Proof Sprint™ entry point costs less than one month of an embedded engineer's salary and delivers a resolved milestone in 7-14 days.
## Why "We'll Just Hire Someone" Costs More Than You Think
The most common objection we hear is also the most expensive one: "We'll figure it out ourselves. We just need to hire the right person."
Three months later, the same founder calls us with $120,000 more burn and no working board.
Here's the math they didn't run.
Finding a senior embedded engineer with genuine Jetson depth -- not generic Linux driver experience, not RTOS firmware, but BSP configuration, V4L2 driver development, GMSL2 camera bring-up, TensorRT inference on Orin -- takes 3-6 months from job posting to accepted offer. That's in a competitive market where there are roughly 400 qualified candidates in North America. Your posting is competing with NVIDIA, Qualcomm, Apple, and every Series B robotics company that also needs this skill set right now.
During those 3-6 months, your engineering team isn't idle. They're trying. A generalist with embedded experience is pulling NVIDIA forum threads and reading L4T documentation. They're making progress, but it's slow, and every week of slow progress is another $15,000-$25,000 in loaded engineering cost on a problem that should have been solved before it became a blocker.
Then the offer gets accepted. Now the new hire needs 2-3 months to ramp on your specific hardware -- your carrier board design, your camera configuration, your JetPack version, your application requirements. This isn't optional. It's what every engineer who hasn't seen your exact combination before has to do.
Total time to first meaningful output: 5-9 months. Total cost before productive embedded work: $75,000-$225,000.
## The Silicon Ceiling™: What's Actually at Stake
The Silicon Ceiling™ is the point where a hardware startup has validated silicon but can't ship because the software stack isn't working. The board isn't booting reliably. The camera isn't streaming. The inference pipeline is running at 200ms latency when you need 50ms. The carrier board hardware passed electrical review but the BSP configuration is wrong for your peripheral combination.
This is almost always underestimated, and always for the same reason: hardware milestones are visible. A board that doesn't boot is obviously broken. But the software timeline is murky. "We're making progress" is the status for weeks at a time, and by the time it's clear that progress isn't fast enough, the field trial window has moved.
The Silicon Ceiling™ is not a catastrophic failure. It's a slow one. And the opportunity cost compounds.
| Delay duration | Engineering burn (at $20k/month loaded) | Field trial impact | Funding risk |
|----------------|----------------------------------------|--------------------|--------------|
| 1 month | $20,000 | Pilot customer patience thinning | Low |
| 3 months | $60,000 | Pilot pushed or cancelled | Medium |
| 6 months | $120,000 | Market window narrowing | High |
| 9 months (hire + ramp) | $180,000 | Competitive landscape shifted | Critical |
Those numbers are client-measured benchmarks from our engagements, not projections.
## The 30% Tax™: Why the Hire Doesn't Fix It Immediately
Here's the part that surprises most founders: the 30% Tax™ applies to your new full-time hire the same as it applies to any contractor.
The 30% Tax™ is the 20-30% of engineering hours on Jetson bring-up work that goes to platform ramp -- not to the deliverable you hired them to build. Any engineer who hasn't debugged your specific JetPack version on your specific carrier board configuration has to pay it. There's no shortcut. The failure modes are version-specific, hardware-specific, and largely undocumented outside teams who've hit them in production.
A senior embedded engineer who has never worked on JetPack 6 with a custom carrier board and GMSL2 cameras doesn't have the failure pattern library yet. They'll learn it, but they'll learn it on your clock, during the months when you needed them productive.
For an engineer at $20,000/month fully-loaded, 20-30% ramp cost means $4,000-$6,000 per month going to platform orientation before the first production commit. Over a 3-month ramp period, that's $12,000-$18,000 that doesn't move your board forward.
This is not a commentary on the engineer's ability. It's structural. It's unavoidable without a pre-validated foundation to start from.
## Running the Full Cost Comparison
Let's put concrete numbers on both options for a typical Jetson board bring-up + camera integration milestone.
**Option A: In-house embedded engineer hire**
| Cost item | Estimate | Notes |
|-----------|----------|-------|
| Time-to-hire | 3-6 months | Senior Jetson depth, competitive market |
| First-year base salary | $150,000-$220,000 | Plus equity (0.25-0.75%) |
| Fully-loaded monthly cost | $15,000-$25,000 | Salary + benefits + employer taxes |
| Ramp period cost (2-3 months) | $30,000-$75,000 | Before productive output on your hardware |
| 30% Tax (first 6 months) | $12,000-$18,000 | Platform orientation cost on top |
| Opportunity cost of delay | $75,000-$225,000 | 5-9 months at $20k/month burn |
| **Total to first productive output** | **$117,000-$318,000** | Before core milestone is resolved |
**Option B: ProventusNova fixed-bid specialist engagement**
| Cost item | Estimate | Notes |
|-----------|----------|-------|
| Proof Sprint (Board BringUp) | Fixed bid | 7-14 days, one milestone resolved |
| Ramp cost | $0 | Absorbed into Foundational Layers |
| 30% Tax | $0 | Pre-validated starting point eliminates it |
| Time to first output | 7-14 days | Not 5-9 months |
| Full 15-week engagement | Fixed bid | All 5 stages of Dead Silicon to Demo |
| IP transfer | Full, on delivery | Client owns everything immediately |
The comparison isn't that outsourcing is always cheaper. It's that for a bounded, critical-path milestone with a timeline that matters, the hire path takes 5-9 months to produce the same outcome a specialist delivers in 7-14 days. When a field trial is 30 days out and your board isn't booting, the hire path is not an option.
## When Hiring an In-House Embedded Engineer Does Make Sense
We're not arguing against in-house teams. There are situations where building internal embedded expertise is the right call.
Hire in-house when:
1. Your embedded roadmap spans 12+ months of new work requiring constant integration with hardware design decisions
2. The role requires someone embedded in daily product discussions, not just available for a sprint
3. You have runway to absorb 5-9 months before productive output without missing a critical market window
4. The ongoing volume of embedded work justifies the overhead of a senior headcount
Outsource a specialist when:
1. A specific, bounded milestone is blocking everything downstream (board bring-up, camera integration, inference deployment)
2. Your timeline doesn't accommodate 5-9 months of hiring plus ramp
3. You need a pre-validated foundation your eventual in-house hire can maintain and extend from day one
4. Full IP transfer matters -- you don't want to create a vendor dependency
The pattern we see most often: a startup works with us to resolve the Silicon Ceiling™ milestone, gets a documented, structured foundation, then brings on a full-time embedded engineer who starts productive on week one because the foundation is already built. That engineer ramps in weeks, not months.
## How the Proof Sprint™ Changes the Decision
Most engagements start with a Proof Sprint™ -- one bounded milestone, 7-14 days, fixed price.
Board not booting: Board BringUp Proof Sprint™. Delivered in 7 days.
Camera not streaming: Camera Driver Proof Sprint™. Delivered in 14-21 days.
Inference too slow: Model Deployment Proof Sprint™. Delivered in 14 days.
The Proof Sprint™ costs less than one month of a senior embedded engineer's fully-loaded salary. If you're not satisfied after two weeks, you keep everything built and pay nothing. That guarantee is only possible because the Foundational Layers™ -- pre-validated, modular embedded software architecture built across years of real-device engagements -- eliminates the ramp cost before the sprint begins.
The Proof Sprint™ also gives you something no hiring process can: evidence. After 7-14 days, you know exactly what the problem was, how it was solved, and what the documented foundation looks like. That's a much better position from which to decide whether to hire for ongoing work.
## What to Look for in an Embedded Software Outsourcing Partner
If you've already decided to outsource your embedded software development and you're evaluating firms, the comparison above tells you what the decision costs. What follows tells you how to pick the right firm, and what to watch for when the wrong one is pitching you.
### Does the firm have platform-specific depth, or just general embedded experience?
General embedded experience and platform-specific depth are not the same thing. A team that has never debugged a Genio 720 BSP or brought up a custom carrier board on JetPack 6 will spend your first 4-8 weeks learning the platform on your budget. That's the 30% Tax™ applied externally, and it's entirely avoidable.
Ask directly: Which version of JetPack have you debugged in the last 90 days? Which Genio BSP configurations have you shipped? If the answer is vague, the ramp cost is yours.
### Does the firm quote fixed-bid or hourly for bounded milestones?
A firm that insists on hourly billing for a bounded milestone, board bring-up, camera driver development, model deployment, is telling you they don't know how long it takes. A specialist who has solved that exact problem before can quote a fixed price because the unknowns are already known to them. Fixed-bid is not a risk to the client. It's a signal that the contractor's Foundational Layers are already built.
If a firm won't price a 7-14 day board bring-up at a fixed rate, move on.
### Is IP transferred in full at delivery, or tied to ongoing payments?
Some outsourcing arrangements tie IP transfer to contract completion, milestone invoices, or retainer continuity. For a hardware startup, that creates a dependency you cannot afford. The BSP configuration, driver stack, and firmware that brings up your carrier board needs to be fully owned by your team from the moment it's delivered, not held as leverage in a billing dispute.
Confirm IP transfer terms before signing. If it isn't "full transfer on delivery," renegotiate or walk.
### Does the firm have custom carrier board experience, or just devkit work?
There's a meaningful gap between a contractor who can configure a Jetson Orin Developer Kit or a Genio evaluation board and one who can bring up a custom carrier board with undocumented peripheral combinations. Most embedded outsourcing providers have only done module-level work. Custom carrier board bring-up, non-standard power rails, undocumented peripheral connections, no BSP configuration guide from the SOM vendor, is a different class of problem.
Ask for examples of custom carrier board bring-up specifically. Not devkit configuration. Not module integration. Custom boards.
### How fast can the firm deliver a first resolved milestone?
The clearest signal of a firm's actual readiness is their time to first delivery. If the answer is "we'll need 3-4 weeks to scope the project and set up our environment," that's the ramp cost returning in a different form. A team with pre-validated embedded architecture and genuine platform depth can deliver a first resolved milestone, one bounded problem, fully solved, in 7-14 days.
When a field trial is 30 days out and your board isn't booting, 7-14 days to a resolved milestone is the only timeline that matters.
ProventusNova's [Proof Sprint™](/services) covers one bounded milestone, board bring-up, camera driver, or inference deployment, in 7-14 days at a fixed price. If the milestone isn't met, you keep everything built and pay nothing.
## Frequently Asked Questions
### How long does it take to hire an embedded engineer with Jetson-specific depth?
Three to six months from job posting to accepted offer for a senior engineer with genuine Jetson-specific depth -- BSP configuration, V4L2 driver development, GMSL2 camera bring-up. That's in a competitive market where NVIDIA, Qualcomm, Apple, and dozens of robotics startups are competing for the same 400 candidates in North America. On top of hiring time, add 2-3 months of ramp before meaningful output on your specific hardware.
### What does a fully-loaded embedded engineer cost at a hardware startup?
A senior embedded engineer with Jetson depth costs $150,000-$220,000 in base salary, plus equity (typically 0.25-0.75%), plus benefits and employer taxes, putting fully-loaded cost at $180,000-$280,000 per year, or $15,000-$25,000 per month. The 4-month hiring window alone costs $60,000-$100,000 in opportunity cost before anyone writes a line of code.
### What is the Silicon Ceiling and how do I know if I'm hitting it?
The Silicon Ceiling™ is where the hardware is validated but the software stack won't come together. Signs you're hitting it: board bring-up stalled for 2+ months with no clear root cause, camera driver work yielding NVIDIA forum threads with no complete answers, inference pipeline running 3-5x over latency requirements. If your team has been on the same embedded blocker for more than 6 weeks without resolution, you're likely there.
### Can I use ProventusNova for the initial milestone and then hire in-house for ongoing work?
Yes, and it's a common pattern. We deliver the foundation -- board booting, camera streaming, inference pipeline running -- under a fixed-bid engagement with full IP transfer. Your in-house hire maintains and extends from that documented baseline. They start productive on week one instead of spending three months ramping on problems we've already solved.
### What is the 30% Tax and does it apply to full-time employees?
The 30% Tax™ is the 20-30% of engineering hours on Jetson bring-up work that goes to platform ramp rather than the deliverable. It applies to any engineer who hasn't debugged your specific JetPack version and carrier board combination before -- freelance contractor, new full-time hire, or internal engineer assigned outside their platform depth. The format of the engagement changes; the cost doesn't. A specialist with Foundational Layers™ absorbs that ramp before the engagement starts.
---
*ProventusNova takes EdgeAI hardware startups from stalled development to a running demo -- in fixed time, at fixed cost, with full IP transfer. [See all our services and Proof Sprint entry points.](https://proventusnova.com/services)*
---
## Python to C++: 4x Latency Reduction on Jetson
URL: https://proventusnova.com/blog/python-to-cpp-embedded-ai-device-time-to-market/
Published: 2026-05-19
Author: Andres Campos
Tags: jetson, gstreamer, computer vision, python c++, edge ai latency
Python to C++ on Jetson: 4x latency cut via GStreamer + TensorRT. Profiler output, NVMM buffer path, and the exact changes that took 280ms to 68ms.
The Farmhand AI team built their first computer vision pipeline in Python. That's the right call -- Python is fast to develop in, the TensorRT Python API is well-documented, and OpenCV is already there. The pipeline worked. It validated the model. Then they put it on Jetson Orin NX hardware for field evaluation and watched the latency numbers.
Two hundred and eighty milliseconds end-to-end. They needed 70.
This is not a Jetson problem or a TensorRT problem. It's a Python-to-embedded-AI-device problem. When you optimize for time to market on the development side, you eventually hit a latency wall on the deployment side. The question is whether you have a path through it. We ported the pipeline to C++ using GStreamer and native TensorRT, and the result was 68ms -- a 4x reduction.
Here's exactly what the profiler showed and what we changed.
## Key Insights
- Python overhead on Jetson CV pipelines is typically 30-45% of end-to-end latency. It's not Python being slow at math -- it's GIL contention, buffer copies through NumPy, and serialized operations that should be concurrent.
- The fastest diagnostic is `nsys profile` + `tegrastats`. If one CPU core is at 100% while GPU utilization is under 60%, Python is the bottleneck.
- The C++ porting path follows a clear structure: GStreamer appsink with C callback, NvBufSurface for zero-copy NVMM buffer access, TensorRT IExecutionContext directly. No NumPy, no Python GIL, no interpreter dispatch overhead.
- GStreamer handles the pipeline concurrency that Python threads can't. The capture loop, inference, and output stages run as separate GStreamer elements with proper buffer queue management.
- The port took 3 weeks: 1 week profiling and scoping, 1 week core C++ pipeline, 1 week integration and field validation. The Python prototype took 6 weeks to build. This ratio is normal.
## What the Profiler Actually Showed
The first step wasn't writing C++. It was proving, with data, where the 280ms was going.
On the Jetson Orin NX 16GB, we ran `nsys profile` on the Python pipeline while it was processing at target frame rate:
```bash
nsys profile \
--trace=cuda,nvtx,osrt \
--output=farmhand_python_baseline \
python pipeline.py
```
The Nsight Systems timeline showed something specific: the GPU was idle for 165ms out of every 280ms cycle. This isn't what you expect if inference is the bottleneck. GPU idle time in an inference pipeline means the CPU is the bottleneck -- something is occupying the CPU while the GPU waits.
`tegrastats` confirmed it:
```
CPU [98%@1420,45%@1420,42%@1420,40%@1420,38%@1420,41%@1420,38%@1420,39%@1420]
GR3D_FREQ 32%
```
CPU core 0 at 98%. GPU at 32%. The Python GIL was serializing everything through one interpreter thread.
Breaking down the 280ms by component:
| Pipeline stage | Python baseline | Root cause |
|----------------|----------------|------------|
| Camera capture (GStreamer appsink callback) | 85ms | GIL acquisition on every callback, NumPy copy |
| Pre-processing (resize + normalize) | 20ms | NumPy operations, not GPU |
| TensorRT inference | 140ms | Waiting for GIL between CUDA launches |
| Post-processing + NMS | 35ms | Python loops on detection results |
| **Total** | **280ms** | |
The 140ms "inference" number was misleading. Actual GPU inference for YOLOv8s on Orin NX is around 18ms. The other 122ms was Python interpreter overhead: waiting for GIL, marshaling data across the Python/C boundary, and CPU-side pre-processing that should have been GPU-side.
## What We Changed and Why
The porting approach follows three structural changes. Each one addresses a specific measurement from the profiler.
**Change 1: Replace Python appsink callback with C++ GStreamer appsink**
The Python appsink callback acquires the GIL on every frame. At 30fps, that's 30 GIL acquisitions per second, each one blocking any other Python thread from running while the callback processes.
In C++, the appsink callback is a plain C function:
```cpp
static GstFlowReturn on_new_sample(GstAppSink *appsink, gpointer user_data) {
GstSample *sample = gst_app_sink_pull_sample(appsink);
GstBuffer *buffer = gst_sample_get_buffer(sample);
// Map NVMM buffer directly -- no copy
NvBufSurface *surface;
ExtractNvBufSurfaceFromBuffer(buffer, &surface);
// Submit to inference queue
inference_queue.push(surface);
gst_sample_unref(sample);
return GST_FLOW_OK;
}
```
No GIL. No NumPy copy. The NVMM buffer goes directly from GStreamer into the inference queue without touching system RAM.
Capture stage latency after this change: 85ms to 12ms.
**Change 2: NVMM direct access instead of NumPy intermediary**
The Python pipeline copied every frame from GPU memory (NVMM) to system RAM (NumPy array) for pre-processing, then copied it back to GPU memory for TensorRT inference. Two unnecessary DMA copies per frame.
On Jetson, GStreamer's NVMM memory (managed by `nvvidconv` and `nvarguscamerasrc`) is the same physical memory that TensorRT uses for inference input. The correct path:
```cpp
// Get NVMM surface from GStreamer buffer
NvBufSurface *surface = get_surface_from_buffer(buffer);
// Map directly as TensorRT input
void *input_ptr = get_cuda_ptr_from_nv_surface(surface);
// Run inference -- input_ptr is already on GPU, no copy
context->enqueueV2(bindings, cuda_stream, nullptr);
```
The resize and color conversion happen via `nvvidconv` in the GStreamer pipeline itself, on the GPU, before the buffer reaches the inference callback:
```
nvarguscamerasrc ! video/x-raw(memory:NVMM),width=1920,height=1080 !
nvvidconv ! video/x-raw(memory:NVMM),width=640,height=640,format=RGBA !
appsink
```
TensorRT inference latency after this change: 140ms to 35ms. Actual GPU inference time was always 18ms -- the other 17ms remaining is legitimate CUDA kernel dispatch and result retrieval, not Python overhead.
**Change 3: GStreamer queue elements for pipeline concurrency**
In the Python version, capture, pre-processing, inference, and post-processing all ran serially in the same interpreter thread. The GIL prevented any real concurrency.
In the C++ pipeline, GStreamer's `queue` element decouples pipeline stages into separate threads. The capture thread fills frames into the queue while the inference thread drains it. No GIL, no serialization:
```
nvarguscamerasrc ! queue max-size-buffers=2 leaky=downstream !
nvvidconv ! queue max-size-buffers=2 !
appsink name=inference_sink
```
The `leaky=downstream` property on the capture queue drops the oldest frame when the queue is full rather than blocking the capture thread. For real-time applications, a stale frame is worse than a dropped one.
Post-processing latency after pipeline concurrency: 35ms to 21ms for the overall end-to-end number (the stages now run concurrently, so the total isn't a simple sum).
## Final Numbers and What They Mean
After the three-week port:
| Stage | Python baseline | C++ port | Reduction |
|-------|----------------|---------|-----------|
| Capture (GStreamer callback) | 85ms | 12ms | 7x |
| Pre-processing | 20ms | 0ms (GPU in pipeline) | Eliminated |
| TensorRT inference | 140ms | 35ms | 4x |
| Post-processing + NMS | 35ms | 21ms | 1.7x |
| **End-to-end** | **280ms** | **68ms** | **4.1x** |
The 68ms end-to-end latency cleared the 70ms field requirement. GPU utilization went from 32% to 78%. CPU core 0 went from 98% to 41%. The device has headroom to add a second model on DLA without impacting the primary detection pipeline.
The Farmhand AI team got to field evaluation on schedule. The Python pipeline got them through development and model validation. The C++ port got them to production latency.
## When to Port and When to Wait
Python-to-C++ is not always the right move, and it's never cheap. The port took three weeks of specialist time. The decision to port should be based on profiler data, not intuition.
Port when the profiler shows:
- GPU utilization under 60% while one CPU core is at saturation
- End-to-end latency 2x or more above your target
- NVMM-to-NumPy copies showing up in the Nsight Systems timeline
Wait when:
- You haven't frozen the model architecture yet -- C++ is expensive to iterate on
- Throughput (frames/second) is the metric, not latency -- Python can saturate GPU throughput if the pipeline is structured correctly
- The latency gap is under 30% -- optimization in the Python pipeline (batch inference, NumPy avoidance) might close it without a full port
The port to C++ is a one-way door for the pipeline code. Once it's done, changes that would have taken a few hours in Python take longer in C++. Make sure you're porting the right pipeline at the right time.
## Frequently Asked Questions
### Why is Python too slow for production computer vision inference on Jetson?
Python's GIL prevents true multi-threaded parallelism. On Jetson, every GStreamer callback, every NumPy operation, and every TensorRT inference call acquires the GIL, serializing what should be concurrent operations. Profiling shows that 30-45% of end-to-end latency in Python CV pipelines goes to Python overhead -- GIL contention, interpreter dispatch, and buffer copies through NumPy that wouldn't exist in a C++ pipeline using NVMM directly.
### What is the typical latency improvement from porting a Python CV pipeline to C++ on Jetson?
In the Farmhand AI engagement, we achieved a 4x end-to-end latency reduction: 280ms to 68ms on Jetson Orin NX 16GB. The improvements came from three sources: eliminating GIL contention in the capture loop, using NVMM buffers directly in TensorRT instead of copying through NumPy, and running GStreamer in a dedicated thread without Python callback overhead.
### How do I profile where Python overhead is in my Jetson CV pipeline?
Use NVIDIA Nsight Systems on the device: `nsys profile --trace=cuda,nvtx python your_pipeline.py`. The timeline view shows GPU idle time between inference calls -- this is where Python overhead lives. Also run `tegrastats` while the pipeline runs to see CPU utilization across cores. A Python pipeline hitting the latency wall typically shows one CPU core at 100% while GPU utilization is 30-50%.
### What does a GStreamer + TensorRT + C++ pipeline look like vs a Python pipeline?
A Python pipeline typically uses OpenCV VideoCapture or a Python GStreamer appsink callback, copies frames to NumPy arrays, runs TensorRT inference through the Python bindings, and processes results in Python. The C++ equivalent uses a GStreamer appsink with a direct C callback, pulls NVMM buffers with NvBufSurface, runs TensorRT inference with the C++ IExecutionContext directly, and processes results without any Python interpreter involvement. The C++ version eliminates 3-4 buffer copies and removes all GIL contention.
### When should I port a Python CV pipeline to C++ on Jetson?
Port when your profiler shows GPU utilization below 60% with CPU at saturation, when end-to-end latency is 2x or more above your target, or when your pipeline can't sustain the target frame rate without dropping frames. Don't port prematurely -- Python is valid for prototyping and for workloads where throughput, not latency, is the metric. The right time to port is when you have a frozen model, a defined target latency, and profiler data showing exactly where the overhead is.
---
*ProventusNova ports Python computer vision pipelines to production-grade C++ on Jetson -- GStreamer, TensorRT, full IP transfer. [See our GStreamer Pipeline and EdgeAI Deployment services.](https://proventusnova.com/services)*
---
## TensorRT vs DLA on Jetson Orin: power, latency, layers
URL: https://proventusnova.com/blog/tensorrt-vs-dla-jetson-orin/
Published: 2026-05-19
Author: Andres Campos
Tags: jetson orin, tensorrt, dla, edgeai, inference optimization
TensorRT vs DLA on Jetson Orin: decide based on layer compatibility, latency vs throughput, and power budget. A practical decision framework for ML engineers.
If you're deploying a computer vision model on Jetson Orin, you'll hit the TensorRT vs DLA question within the first few days of optimization work. The short answer: use TensorRT GPU inference when latency is your primary constraint and your model uses operators outside the DLA-supported set. Use DLA when you need to run inference continuously at low power, or when you're running multiple models concurrently and need to keep the GPU free for other workloads. Most production deployments on Orin end up splitting inference across both.
## Key Insights
- DLA (Deep Learning Accelerator) is not a slower GPU. It's a fixed-function hardware block optimized for a specific layer subset. It draws 2-5W per core vs 10-25W for GPU inference -- but only for models where DLA-compatible layers dominate.
- TensorRT GPU inference gives the lowest single-stream latency and supports every operator. DLA gives lower power at the cost of 2-4x higher latency and layer support restrictions.
- All Jetson Orin modules include DLA. The AGX Orin has 2 DLA cores; Orin NX (16GB and 8GB) has 2; Orin Nano (8GB and 4GB) has 1.
- The TensorRT build process handles DLA fallback transparently. Use `trtexec --useDLACore=0 --allowGPUFallback` and inspect the build log to see which layers ran on DLA vs GPU.
- Transformer-based models (ViT, attention layers) do not run on DLA as of JetPack 6.2. Classic CNN architectures (YOLO, MobileNet, ResNet) are largely DLA-compatible.
## What Is DLA and How Does It Fit Into the Orin Architecture?
The Jetson Orin SoC (T234) includes a dedicated Deep Learning Accelerator alongside the Ampere GPU. DLA is not a stripped-down GPU -- it's a purpose-built fixed-function inference engine designed to run common DNN operations at very low power. It doesn't share memory bandwidth with the GPU and runs completely independently, which is the key reason it's useful for concurrent workloads.
The DLA core count varies by module:
| Module | DLA Cores | GPU (CUDA Cores) | Max DLA TOPS | Max GPU TOPS |
|--------|-----------|------------------|--------------|--------------|
| AGX Orin 64GB | 2 | 2048 | 2x 5.5 = 11 | 275 |
| AGX Orin 32GB | 2 | 1792 | 2x 5.5 = 11 | 170 |
| Orin NX 16GB | 2 | 1024 | 2x 3.5 = 7 | 100 |
| Orin NX 8GB | 2 | 512 | 2x 2.3 = 4.6 | 70 |
| Orin Nano 8GB | 1 | 1024 | 5.5 | 40 |
| Orin Nano 4GB | 1 | 512 | 3.5 | 20 |
DLA on Orin supports FP16 and INT8 precision. INT8 on DLA is the right target for production deployments -- it requires a calibration dataset during the TensorRT build step, but the power and throughput numbers assume INT8.
## When to Use TensorRT GPU Inference
GPU inference via TensorRT is the right choice when:
1. **Single-stream latency is the hard requirement.** A robotics manipulator that needs a pick decision in under 30ms, a medical imaging device with a real-time feedback loop, or an inspection system where a missed detection has immediate downstream consequences. GPU at INT8 on AGX Orin can run YOLOv8m inference in under 5ms. DLA will run the same model in 15-25ms.
2. **Your model uses operators outside the DLA-supported set.** Transformer attention, dynamic shapes, custom CUDA plugins, LSTM/GRU layers, or any operation that needs arbitrary precision. These layers fall back to GPU when you specify DLA, which defeats much of the power benefit and adds PCIe transfer overhead.
3. **You're prototyping and need iteration speed.** The DLA build path requires INT8 calibration and a fixed-shape engine. GPU inference builds faster, accepts FP32/FP16/INT8, and handles dynamic shapes. Build with GPU during development, then evaluate DLA for production once the model is frozen.
4. **Your thermal budget is unconstrained.** A device with active cooling and a 30W or 60W power budget can run GPU inference continuously without thermal throttling. DLA's power advantage disappears if your system can handle the GPU load without a problem.
## When to Use DLA on Jetson Orin
DLA is the right choice when:
1. **Power budget is the constraint.** Battery-powered drones, autonomous agricultural equipment, and wearable devices where every watt matters. Running a MobileNetV3 classification model on DLA at 30fps draws roughly 2-3W vs 8-12W on GPU. Over an 8-hour deployment, that's the difference between a battery that lasts the day and one that doesn't.
2. **You're running multiple models concurrently.** On AGX Orin, you can run one model on DLA core 0, a second model on DLA core 1, and a third on the GPU simultaneously -- all without the GPU being the bottleneck. A multi-camera pipeline processing four streams with classification on each can run the detection model on GPU and the classification model on DLA, keeping both accelerators occupied.
3. **Your model is a classic CNN architecture at a fixed input size.** MobileNet, EfficientDet, YOLO (v5 through v8 with standard heads), ResNet variants -- these are well within DLA's supported operator set. If you're running a model the team has been deploying for more than a year and it hasn't changed architecture, it's a good DLA candidate.
4. **You need continuous inference with strict thermal limits.** Edge devices that run 24/7 without active cooling need to stay within a tight thermal envelope. DLA inference generates significantly less heat than GPU inference, which can be the difference between reliable operation and thermal throttling in a sealed enclosure.
## How to Profile DLA Compatibility for Your Model
The fastest way to evaluate DLA compatibility is with `trtexec` on the target hardware. Never build TensorRT engines on your development machine -- they're not portable across Jetson SKUs, and an engine built on an AGX Orin won't load on an Orin NX.
On the Jetson device:
```bash
# Evaluate DLA compatibility with GPU fallback for unsupported layers
trtexec \
--onnx=model.onnx \
--useDLACore=0 \
--allowGPUFallback \
--int8 \
--calib=calibration.cache \
--saveEngine=model_dla.engine \
--buildOnly \
--verbose 2>&1 | grep -E "DLA|GPU|Layer"
```
The build log shows each layer and its assigned device. A layer assigned to DLA looks like:
```
[08/15/2025-14:22:31] [I] [TRT] DLA Compatibility Check: Convolution_0 -> DLA
[08/15/2025-14:22:31] [I] [TRT] DLA Compatibility Check: Pooling_1 -> DLA
[08/15/2025-14:22:31] [I] [TRT] DLA Compatibility Check: Attention_2 -> GPU (unsupported)
```
The decision rule is practical: if more than 70-80% of the compute graph (by FLOPs) is assigned to DLA, the power and throughput benefits are real. If the GPU fallback layer count is high -- especially if the fallback layers sit in the middle of the graph, forcing frequent DLA-to-GPU transfers -- the efficiency benefit largely evaporates and you'd be better off running fully on GPU.
## Splitting Inference Across DLA and GPU
The most powerful Orin deployment pattern isn't DLA-only or GPU-only -- it's splitting a multi-model pipeline across both accelerators.
A practical example from a multi-camera agricultural inspection deployment:
```
Camera 0-3 (GMSL2) → GStreamer pipeline
└─► Detection model (YOLO) → TensorRT GPU (latency-critical, 5ms/frame)
└─► Classification model (MNet) → TensorRT DLA (throughput, 20ms/frame)
└─► Anomaly scoring (ResNet) → TensorRT DLA (power-sensitive, 25ms/frame)
```
This configuration keeps the GPU dedicated to the latency-critical detection step while DLA handles the classification and anomaly models concurrently, freeing GPU cycles for GStreamer pipeline management and any post-processing work.
To run on DLA core 1 (second core, on AGX Orin or Orin NX):
```python
import tensorrt as trt
config = builder.create_builder_config()
config.default_device_type = trt.DeviceType.DLA
config.DLA_core = 1 # 0 or 1 on AGX Orin / Orin NX
config.set_flag(trt.BuilderFlag.GPU_FALLBACK)
config.set_flag(trt.BuilderFlag.INT8)
```
The INT8 flag is mandatory for DLA on Orin. FP32 DLA is not supported; FP16 DLA is technically available but INT8 gives materially better throughput and power numbers.
## The Decision Framework: Which to Use
Apply this in order:
1. **Does your model have unsupported layers (attention, LSTM, custom CUDA, dynamic shapes)?** If yes, use GPU inference. Check with `trtexec --useDLACore=0 --allowGPUFallback --buildOnly` and inspect the fallback count.
2. **Is single-stream latency under 10ms a hard requirement?** If yes, use GPU. DLA latency on most vision models is 15-40ms depending on model size.
3. **Are you running multiple models concurrently?** If yes, assign the less latency-critical models to DLA and reserve the GPU for your most time-sensitive workload.
4. **Is power or thermal budget the binding constraint?** If yes, profile both GPU and DLA at production throughput, measure actual system draw, and choose based on measured numbers, not specs.
5. **Is the model a frozen, fixed-shape CNN (YOLO, MobileNet, ResNet family)?** If yes, DLA is almost certainly compatible. Run the compatibility check to confirm.
## Frequently Asked Questions
### What is the difference between TensorRT GPU inference and DLA inference on Jetson Orin?
TensorRT GPU inference runs on the Orin's Ampere GPU cores using CUDA. It supports the full range of operators and layer types and gives the lowest single-stream latency. DLA is a fixed-function hardware block that runs a subset of common DNN layers at very low power. DLA frees up the GPU for other workloads, but it only supports a specific layer set and runs at roughly 2-4x higher latency per model than GPU inference.
### Which Jetson Orin modules have DLA and how many cores?
All Jetson Orin modules include DLA. AGX Orin has 2 DLA cores. Orin NX 16GB and 8GB have 2 DLA cores. Orin Nano 8GB has 1 DLA core. Orin Nano 4GB has 1 DLA core. On AGX Orin with 2 DLA cores, you can run two models concurrently on DLA while the GPU handles a third.
### What layer types are not supported on Jetson Orin DLA?
DLA does not support custom CUDA plugins, dynamic shapes (fixed batch size and input dimensions required), recurrent layers (LSTM, GRU), transformer attention layers (as of JetPack 6.2), most element-wise operations beyond simple add or multiply, and operations requiring precision beyond INT8 or FP16. If your model uses any of these, those layers will fall back to GPU when running in DLA mode.
### How do I profile which layers in my model are compatible with DLA?
Use trtexec with the `--useDLACore=0` and `--allowGPUFallback` flags: `trtexec --onnx=model.onnx --useDLACore=0 --allowGPUFallback --buildOnly`. The build output lists each layer and its assigned device. If more than 20-30% of your compute falls back to GPU, the DLA efficiency benefit is largely lost.
### What is the power saving from DLA vs GPU inference on Jetson Orin?
DLA inference draws roughly 2-5W per DLA core for a typical vision model like YOLOv8n or MobileNetV3, compared to 10-25W for equivalent GPU inference. A well-quantized INT8 model on DLA running at 30fps might save 8-15W system-wide compared to GPU. This matters significantly for battery-powered devices or multi-camera deployments where thermal headroom is the constraint.
---
*ProventusNova deploys production-grade inference pipelines on Jetson Orin -- TensorRT optimization, DLA profiling, GStreamer integration, and full IP transfer. [See our EdgeAI Model Deployment service](https://proventusnova.com/services/edgeai-deployment) or [schedule a scoping call](https://proventusnova.com/contact).*
---
## How to create a hardware-accelerated GStreamer pipeline for live streaming on Jetson
URL: https://proventusnova.com/blog/gstreamer-live-streaming-jetson-orin/
Published: 2026-05-18
Author: Andres Campos
Tags: jetson, gstreamer, live streaming, rtsp, nvv4l2h264enc, nvarguscamerasrc, nvmm
Build a low-latency GStreamer live streaming pipeline on NVIDIA Jetson using nvv4l2h264enc and udpsink or gst-rtsp-server. RTSP, UDP, and SRT examples.
Building a hardware-accelerated live streaming pipeline on Jetson Orin means using `nvv4l2h264enc`, the Jetson NVENC engine, instead of software encoders. The difference is significant: software H.264 encoding (`avenc_h264`) can barely sustain 1080p30 on Jetson's Cortex-A78 cores, while `nvv4l2h264enc` handles it at under 5% CPU load. This post covers RTSP server setup, UDP streaming, latency tuning, and how to receive the stream on any device.
## How to create a hardware-accelerated GStreamer pipeline for live streaming on Jetson
A hardware-accelerated GStreamer live streaming pipeline on Jetson Orin works as follows: `nvarguscamerasrc` captures from the CSI camera through the Jetson ISP in NVMM memory, `nvvidconv` converts the format within NVMM, `nvv4l2h264enc` encodes in the NVENC hardware engine, `h264parse` prepares the bytestream, `rtph264pay` wraps in RTP, and `udpsink` or an RTSP server delivers the stream.
The key constraint is keeping everything in NVMM memory until the encoded output, inserting any CPU element (`videoconvert`, `appsink`) before the encoder forces a copy from GPU memory to system RAM, adding latency and CPU overhead.
## Key Insights
- **`nvv4l2h264enc` is the only correct choice** for live streaming on Jetson, it encodes entirely in NVENC hardware with near-zero CPU usage
- **Keep all elements in NVMM** between `nvarguscamerasrc` and `nvv4l2h264enc`, a single `videoconvert` in this path copies every frame through system RAM
- **`preset-level=1` (UltraFast) + `tune-level=1` (ZeroLatency)** on `nvv4l2h264enc` cuts encoder latency by 60-70% vs default settings
- **`sync=false` on all sinks** removes the presentation timestamp delay that adds 33ms+ of artificial latency
- **For RTSP**, `gst-rtsp-server` with a `nvv4l2h264enc` launch string handles multi-client streaming without running one encoder per client
## UDP streaming pipeline (fastest setup)
UDP is the simplest live streaming setup, no server process needed, one receiver, lowest overhead.
**On Jetson (sender):**
```bash
gst-launch-1.0 \
nvarguscamerasrc sensor-id=0 ! \
'video/x-raw(memory:NVMM),width=1920,height=1080,framerate=30/1,format=NV12' ! \
nvv4l2h264enc preset-level=1 tune-level=1 bitrate=4000000 iframeinterval=30 insert-vui=1 ! \
h264parse ! \
rtph264pay pt=96 config-interval=1 ! \
udpsink host= port=5000 sync=false
```
**On the receiving machine:**
```bash
gst-launch-1.0 \
udpsrc port=5000 ! \
'application/x-rtp,media=video,payload=96,clock-rate=90000,encoding-name=H264' ! \
rtph264depay ! \
avdec_h264 ! \
autovideosink sync=false
```
Replace `` with the laptop or server IP. Use `ifconfig` or `ip addr` on the Jetson to find its IP.
**`nvv4l2h264enc` key properties:**
| Property | Value | Effect |
|---|---|---|
| `preset-level` | 1 (UltraFast) | Fastest encode, some quality trade-off |
| `tune-level` | 1 (ZeroLatency) | Disables B-frames and look-ahead; adds no buffering delay |
| `bitrate` | 4000000 | 4 Mbps for 1080p30, adjust up for quality |
| `iframeinterval` | 30 | I-frame every 30 frames (1 second at 30fps) |
| `insert-vui` | 1 | Embeds VUI timing info; helps receivers sync |
| `insert-sps-pps` | 1 | Embeds SPS/PPS in every IDR; required for late joiners |
## RTSP server with gst-rtsp-server
RTSP allows multiple clients to connect and reconnect without restarting the pipeline. Install the server library:
```bash
sudo apt install python3-gi gir1.2-gst-rtsp-server-1.0
```
Python RTSP server, save as `rtsp_server.py`:
```python
import gi
gi.require_version('Gst', '1.0')
gi.require_version('GstRtspServer', '1.0')
from gi.repository import Gst, GstRtspServer, GLib
Gst.init(None)
server = GstRtspServer.RTSPServer.new()
server.set_service("8554")
mount_points = server.get_mount_points()
factory = GstRtspServer.RTSPMediaFactory.new()
factory.set_launch(
"( nvarguscamerasrc sensor-id=0 ! "
"video/x-raw(memory:NVMM),width=1920,height=1080,framerate=30/1,format=NV12 ! "
"nvv4l2h264enc preset-level=1 tune-level=1 bitrate=4000000 iframeinterval=30 ! "
"h264parse ! "
"rtph264pay name=pay0 pt=96 config-interval=1 )"
)
factory.set_shared(True) # one pipeline, multiple clients
mount_points.add_factory("/live", factory)
server.attach(None)
print("RTSP server running at rtsp://0.0.0.0:8554/live")
GLib.MainLoop().run()
```
Run it:
```bash
python3 rtsp_server.py
```
Connect from VLC, ffplay, or another Jetson:
```bash
# VLC
vlc rtsp://:8554/live
# ffplay (low latency flags)
ffplay -fflags nobuffer -flags low_delay -framedrop rtsp://:8554/live
# Another GStreamer pipeline
gst-launch-1.0 rtspsrc location=rtsp://:8554/live ! decodebin ! autovideosink sync=false
```
`factory.set_shared(True)` means all clients see the same encoded stream, the encoder runs once regardless of how many clients are connected. Without this, each client would start its own pipeline and camera session.
## Using v4l2src instead of nvarguscamerasrc
If your camera is a USB camera or a sensor not in the Argus registry, use `v4l2src` with explicit format caps:
```bash
gst-launch-1.0 \
v4l2src device=/dev/video0 ! \
'video/x-raw,format=YUY2,width=1280,height=720,framerate=30/1' ! \
nvvidconv ! \
'video/x-raw(memory:NVMM),format=NV12' ! \
nvv4l2h264enc preset-level=1 tune-level=1 bitrate=2000000 iframeinterval=30 ! \
h264parse ! \
rtph264pay pt=96 config-interval=1 ! \
udpsink host= port=5000 sync=false
```
The `nvvidconv` element converts `v4l2src` system memory output into NVMM for `nvv4l2h264enc`. Caps conversion through `nvvidconv` is required, `nvv4l2h264enc` does not accept system memory buffers directly.
## H.265 encoding for lower bandwidth
For bandwidth-constrained links, H.265 (HEVC) cuts bitrate roughly in half at the same quality level. Replace `nvv4l2h264enc + h264parse + rtph264pay` with:
```bash
nvv4l2h265enc preset-level=1 tune-level=1 bitrate=2000000 iframeinterval=30 ! \
h265parse ! \
rtph265pay pt=96 config-interval=1 ! \
udpsink host= port=5000 sync=false
```
Receive on the other side:
```bash
gst-launch-1.0 \
udpsrc port=5000 ! \
'application/x-rtp,media=video,payload=96,clock-rate=90000,encoding-name=H265' ! \
rtph265depay ! \
avdec_h265 ! \
autovideosink sync=false
```
H.265 decode is more CPU-intensive on the receiver. If the receiver is also a Jetson, use `nvv4l2decoder` instead of `avdec_h265`.
## Latency tuning
With default settings, a Jetson live stream often has 200-500ms of latency. These changes bring it under 100ms:
**Encoder side (Jetson):**
- `preset-level=1`, eliminates encoder look-ahead buffering
- `tune-level=1`, disables B-frames; each frame is independently decodable immediately
- `iframeinterval=30`, lower values add overhead; 30 is a good balance for fast recovery
**RTP/network side:**
- `config-interval=1` on `rtph264pay`, embeds SPS/PPS every second; receivers don't wait for the first IDR
- `udpsink sync=false`, no presentation timestamp waiting
**Receiver side:**
- `udpsrc` / `rtspsrc` typically add 50-200ms of jitter buffering by default
- For `rtspsrc`: set `latency=50` property (milliseconds), `rtspsrc latency=50 location=rtsp://...`
- For ffplay: add `-fflags nobuffer -flags low_delay -framedrop`
## Measuring actual end-to-end latency
Display a millisecond clock in the camera frame and film both the Jetson display and the receiver screen simultaneously to measure actual end-to-end delay. Alternatively, use GStreamer's `GST_DEBUG_DUMP_DOT_DIR` to see buffer timestamps, or add a `fakesink` with `dump=true` to inspect buffer PTS values at the output.
```bash
# Quick latency check pipeline, no network, renders to screen
gst-launch-1.0 \
nvarguscamerasrc sensor-id=0 ! \
'video/x-raw(memory:NVMM),width=1280,height=720,framerate=30/1' ! \
nvv4l2h264enc preset-level=1 tune-level=1 bitrate=4000000 ! \
h264parse ! \
nvv4l2decoder ! \
nvvidconv ! nv3dsink sync=false
```
This encode-then-decode loop on the same device gives a rough encoder+decoder latency figure. On Jetson AGX Orin at 1080p30 with UltraFast + ZeroLatency, this pipeline runs at under 30ms round-trip.
## Debugging common issues
**`nvv4l2h264enc: Error while encoding`**, almost always an NVMM caps mismatch. Verify `nvvidconv` is outputting `video/x-raw(memory:NVMM),format=NV12` before the encoder.
**Stream plays but freezes every few seconds**, IDR interval too large or receiver jitter buffer overflow. Lower `iframeinterval` to 15 and add `insert-sps-pps=1`.
**RTSP clients connect but see black video**, factory launch string syntax error. Test the launch string standalone with `gst-launch-1.0` first, then wrap in parentheses for the factory.
**High CPU on Jetson during streaming**, a CPU-based element crept into the pipeline. Run `htop` while streaming and check which processes are consuming CPU. Add `GST_DEBUG=nvvidconv:3` to trace NVMM buffer flows.
---
## MediaTek Genio for industrial edge AI: thermal, BSP, and longevity
URL: https://proventusnova.com/blog/mediatek-genio-industrial-edge-ai/
Published: 2026-05-14
Author: Andres Campos
Tags: mediatek genio, industrial edge ai, bsp, thermal design, long-term support
Is MediaTek Genio suitable for industrial edge AI products? Assessment of thermal design, BSP maturity, long-term supply, OTA updates, and what to verify.
Industrial deployments have different requirements than prototypes, supply commitments, extended temperature ratings, security patch support for 5-10 year product lifetimes, and reliable OTA update mechanisms. MediaTek Genio's positioning as an industrial IoT platform means these questions have answers, but some require direct verification with MediaTek and your module vendor.
## Key Insights
- Genio's 4–8W TDP is a genuine advantage for fanless industrial enclosures, lower thermal dissipation requirement than Jetson or x86 options
- BSP longevity is the most important question to answer before committing Genio to an industrial product, ask MediaTek directly about security patch cadence and CVE response process
- OTA updates are not built in, plan for swupdate or RAUC implementation during BSP bring-up, not as an afterthought
- Temperature range certification must be verified with the module vendor, not assumed from SoC datasheet
- For industrial products with 7+ year production runs, the Genio platform is newer, so the long-term track record is shorter than Jetson
## Why industrial edge AI has different requirements
A consumer product and an industrial product are subject to different constraints. Consumer devices ship quickly, operate in controlled environments, and have short production runs. Industrial devices operate at temperature extremes, run unattended for years, need guaranteed component supply, require security patch support for the product's operational lifetime, and cannot afford field firmware update failures.
Evaluating a compute platform for industrial use means asking questions that do not matter for a prototype or a consumer product. TOPS and GStreamer pipelines matter. Thermal specs matter more. Supply commitment matters more. BSP security patch cadence matters most.
Here is what those questions look like for MediaTek Genio.
## Thermal design at industrial temperatures
Genio's TDP range, approximately 4W for Genio 510, up to 8W for Genio 1200 under inference load, is compatible with fanless industrial enclosures. This is one of the platform's strongest industrial arguments.
The thermal design math:
```
Junction temperature = Ambient temperature + (TDP × Thermal resistance)
```
For a Genio 700 module at 6W TDP:
- At 40°C ambient: 6W × Rth = junction rise above 40°C
- At 70°C ambient (industrial): 6W × Rth = junction rise above 70°C
The heatsink or thermal spreader must keep the junction below the SoC's rated maximum. The challenge at industrial temperatures is the reduced thermal delta available, at 70°C ambient versus 25°C ambient, you have 45°C less thermal headroom.
In practice: a well-designed thermal solution for Genio at 40°C ambient industrial conditions is straightforward. At 70°C ambient in an enclosed enclosure with limited airflow, it requires careful thermal modeling before you commit to the mechanical design. Engage a thermal engineer early.
Compare this to Jetson Orin NX at 25W TDP, achieving fanless operation at elevated ambient temperatures is significantly harder and requires a larger thermal mass. Genio's lower TDP is a real practical advantage in this design constraint.
## Temperature range: verify with the module vendor
The Genio SoC (MT8390, MT8395) has junction temperature limits specified in the datasheet. The module vendor adds their own thermal and component specifications on top of the SoC. The result is a module-level temperature rating that depends on the specific module design.
Some Genio module vendors offer:
- Commercial temperature: 0°C to 70°C operating ambient
- Industrial temperature: -40°C to 85°C operating ambient (for modules using industrially-rated components)
These ratings are vendor-specific. Before specifying Genio for a product that requires industrial temperature operation, get the temperature rating in writing from your module vendor for their specific module. Check whether the rating is for the module in open air or requires derating in an enclosed enclosure. Check that the memory, PMIC, and connector components on the module are all rated to the same temperature.
This is a verification step, not an assumption from the SoC datasheet.
## BSP maturity and security patch support
For an industrial product that ships in 2025 and needs security patches through 2033, the BSP maintenance question is: will MediaTek issue kernel security patches for the IoT Yocto SDK throughout that window?
The honest answer is that the Genio IoT SDK does not yet have the track record to answer this with certainty. It is a newer platform. Jetson L4T has a demonstrated history of security updates and a public CVE response process going back over a decade.
For Genio, the questions to ask MediaTek directly before committing:
1. Which Yocto LTS release does the IoT SDK track? (Yocto LTS releases have known end-of-life dates)
2. What is the security patch cadence for BSP-level CVEs?
3. What is the process for reporting and getting a response to a security vulnerability?
4. Will security patches be available for your module's SoC variant for the duration of your product's support window?
These are not unreasonable questions. A responsible industrial product commitment requires answers.
## OTA update implementation on Genio
Jetson has a built-in A/B OTA mechanism as part of L4T. It is documented, tested, and has a defined failure recovery path. See [Jetson A/B OTA updates: what breaks on custom carrier boards](/blog/jetson-ab-ota-custom-carrier-board) for the practical details.
Genio does not have an equivalent built-in mechanism. OTA on Genio is a BSP-layer design choice. The standard Linux OTA tools are all viable:
- **swupdate**, single image or multi-artifact updates, supports A/B partitioning, hardware watchdog integration
- **RAUC**, similar to swupdate, good Yocto layer integration, signed bundle verification
- **Mender**, managed OTA with a cloud backend option, Yocto layer available
Any of these can implement a production-grade A/B OTA for Genio. The difference from Jetson is that you must explicitly design and implement it, OTA is not a feature you enable, it is a subsystem you build. This means:
- Partition layout must be designed for A/B at the start of BSP bring-up
- OTA test coverage must include rollback and failure scenarios
- The OTA mechanism must be validated on your target hardware before production
Plan for OTA as a dedicated task during BSP bring-up, not as something to add later.
## Supply commitment for long production runs
MediaTek positions Genio as an IoT platform with long-term availability, and the chipset lifecycle commitments for IoT silicon are typically longer than consumer silicon. The MT8390 and MT8395 are designed for 10-year supply availability, though the specific commitment terms depend on the purchasing agreement.
For industrial products with 7–10 year production runs, confirm:
1. Module vendor commitment: the module vendor (SEEED, Advantech, or other) may offer supply commitment beyond the chipset lifecycle
2. Last time buy rights: the process for securing inventory if the chipset reaches end of life
3. Migration path: whether a future Genio generation maintains software compatibility
None of these are unique to Genio, the same questions apply to any industrial compute platform. The difference is that Genio is newer, so the track record for honoring these commitments is shorter. Jetson has a demonstrated history of maintaining industrial compute modules through product lifecycles.
## The industrial Genio case in summary
Genio makes a compelling industrial case when:
- The application runs lightweight inference within the APU capability (4–6 TOPS)
- Fanless thermal design at 4–8W TDP is a hard requirement
- Volume is high enough that BOM cost advantage is meaningful
- Camera requirements are straightforward (standard MIPI CSI-2 sensors)
- The team can absorb BSP implementation work (OTA, security, Yocto customization)
The platform requires more BSP investment than Jetson for industrial-grade deployment. The payoff is a lower-power, lower-cost compute node, assuming the inference workload fits.
If your workload pushes the APU limits or requires GMSL2 cameras, Jetson Orin is the more capable and more thoroughly documented choice. For a comparison across use cases, see [MediaTek Genio vs NVIDIA Jetson Orin: which platform for edge AI](/blog/mediatek-genio-vs-nvidia-jetson).
MediaTek's Genio IoT product information is at [iot.mediatek.com](https://iot.mediatek.com/genio). Yocto LTS release schedule and end-of-life dates are at [yoctoproject.org](https://wiki.yoctoproject.org/wiki/Stable_Release_and_LTS).
---
## Running inference on MediaTek Genio: NeuroPilot, TFLite, and ONNX
URL: https://proventusnova.com/blog/mediatek-genio-inference-offline-neuropilot/
Published: 2026-05-13
Author: Aaron Angulo
Tags: mediatek genio, neuropilot, tflite, onnx, inference, edge ai
How to run offline inference on MediaTek Genio using NeuroPilot SDK, TFLite APU delegate, and ONNX. Model conversion workflow, supported ops, and latency.
Running inference on MediaTek Genio's APU requires INT8 quantized models and the NeuroPilot TFLite delegate, a different stack than TensorRT on Jetson or standard TFLite on CPU. The performance you get depends on how well your model architecture maps to the APU's supported operator set. This post covers the full deployment workflow from model conversion to running on-device.
## Key Insights
- NeuroPilot SDK provides a TFLite delegate that routes supported ops to the Genio APU, no separate compilation step required for basic deployment
- INT8 quantization is required for APU execution, float32 models run on CPU by default
- ONNX → TFLite is one path, but on Genio 520/720 ONNX Runtime also runs **directly** on the NPU via the NeuronExecutionProvider (see [ONNX Runtime on the Genio NPU](/blog/mediatek-genio-onnx-runtime-neuron)); the TFLite-delegate path below applies to every NPU-capable Genio part
- Unsupported ops fall back to CPU automatically, which can negate APU performance gains on models with many unsupported layers
- Latency scales with model complexity non-linearly, benchmark on hardware, not TOPS estimates
## How Genio's APU inference stack works
The MediaTek Genio APU is a dedicated neural network accelerator. It is not a GPU and has no general compute capability. It runs a fixed set of operations at INT8 precision, very efficiently, and routes anything it cannot handle to the CPU automatically.
The software stack is NeuroPilot SDK, which implements a TFLite delegate, a plug-in mechanism that lets TFLite route specific ops to hardware accelerators while keeping the rest on CPU. From the application's perspective, inference still happens through the TFLite runtime. The delegate handles dispatching operations to the APU transparently.
This design has two implications. First, deployment is simpler than platforms that require a full offline compilation step (like TensorRT on Jetson). You do not need to compile the model to a hardware-specific binary at deployment time, the delegate does this at load time. Second, operator compatibility becomes important. If your model has a high percentage of unsupported operations, those run on CPU, and the APU only handles the supported subset.
## Model requirements for APU execution
Before the APU runs your model, two requirements must be met:
**INT8 quantization.** The APU does not execute float32. A float32 TFLite model loaded with the NeuroPilot delegate runs on CPU, you get NeuroPilot overhead with no APU benefit. Quantize your model before deployment.
Two quantization paths:
1. Post-training quantization (PTQ), convert an existing float32 model. Requires a representative dataset for calibration. Fast, but accuracy may drop for some model types.
2. Quantization-aware training (QAT), train the model with simulated quantization. Better accuracy preservation, requires retraining.
For detection models (YOLO, EfficientDet), QAT typically preserves accuracy better than PTQ. For classification (MobileNet, EfficientNet), PTQ usually works well.
**Supported operator set.** Common CNN operators are supported. Transformer and LSTM-heavy architectures are partially or not supported at the APU level. Check the NeuroPilot SDK documentation for the current operator list, it changes between SDK versions.
## Deployment workflow
**From TensorFlow / Keras:**
```python
# Post-training INT8 quantization
import tensorflow as tf
def representative_dataset():
for image in calibration_images:
yield [image[np.newaxis, :].astype(np.float32)]
converter = tf.lite.TFLiteConverter.from_saved_model("saved_model_dir")
converter.optimizations = [tf.lite.Optimize.DEFAULT]
converter.representative_dataset = representative_dataset
converter.target_spec.supported_ops = [tf.lite.OpsSet.TFLITE_BUILTINS_INT8]
converter.inference_input_type = tf.int8
converter.inference_output_type = tf.int8
tflite_model = converter.convert()
with open("model_int8.tflite", "wb") as f:
f.write(tflite_model)
```
**From ONNX:**
```bash
# Convert ONNX → TFLite (using onnx2tf)
pip install onnx2tf
onnx2tf -i model.onnx -o ./tflite_output
# Then quantize the exported TFLite model using the PTQ path above
```
**Running inference with NeuroPilot delegate:**
```python
import tflite_runtime.interpreter as tflite
# Load the NeuroPilot delegate
delegate = tflite.load_delegate("libneuropilot.so")
interpreter = tflite.Interpreter(
model_path="model_int8.tflite",
experimental_delegates=[delegate]
)
interpreter.allocate_tensors()
input_details = interpreter.get_input_details()
output_details = interpreter.get_output_details()
interpreter.set_tensor(input_details[0]['index'], input_data)
interpreter.invoke()
result = interpreter.get_tensor(output_details[0]['index'])
```
The `libneuropilot.so` path depends on your Yocto build configuration, check the SDK sysroot for the exact location.
## Benchmarking and verifying APU utilization
The NeuroPilot SDK includes a benchmark tool. Use it to verify that your model is actually running on the APU (not falling back to CPU):
```bash
# Run the benchmark tool
neuropilot_benchmark \
--model model_int8.tflite \
--num_runs 50 \
--report_delegate_profiling true
```
The output shows per-layer execution location (APU vs CPU) and latency. If most layers are showing as CPU in the profiling output, check your quantization, the model may be running as float32.
Common causes of unexpected CPU fallback:
- Model not fully quantized (mixed float32/int8 layers)
- Operator not in the supported list (the benchmark output names which ops are unsupported)
- Tensor shape not supported by APU (very small or unusual shapes may fall back)
## Handling unsupported ops: what to do when layers fall back
Fallback is not just "that one layer runs slower." Every unsupported op splits the graph: the runtime builds separate APU and CPU subgraphs and hands tensors across the boundary each inference. One unsupported op in the middle of a network costs two transitions per frame, and a model with scattered unsupported ops can fragment into so many subgraphs that APU acceleration loses to plain CPU execution. The subgraph count in the profiling output matters as much as the op list.
The workaround ladder, cheapest first:
1. **Swap the op at the model level.** Most fallbacks come from a handful of choices that have APU-friendly equivalents: exotic activations (replace with ReLU6), unusual resize modes, or dynamic shapes that can be fixed at export time. Retrain or re-export with the substitution and the whole graph stays on the APU.
2. **Re-export through a different path.** The same network exported with a different opset or converter (onnx2tf vs tf2onnx round trips) often lands on supported ops. Converter choice changes the op mix more than people expect.
3. **Move the op out of the model.** If the offender sits at the head or tail (normalization, NMS, decoding), delete it from the graph and do it in application code. A contiguous APU subgraph plus explicit CPU pre/post-processing beats a fragmented graph, and detection post-processing on CPU is normal practice.
4. **Accept it, but only at the edges.** A CPU head or tail costs one transition. CPU islands in the middle cost two each; those are the ones worth engineering away.
On the ONNX Runtime path (Genio 520/720, or opt-in on 510/700/1200), the same physics applies with two extra knobs: `NEURON_FLAG_USE_FP16` is mandatory for float models to run on the NPU at all, and `NEURON_FLAG_MIN_GROUP_SIZE` sets how many nodes justify an NPU subgraph, which is your fragmentation control. Details in [ONNX Runtime on the Genio NPU](/blog/mediatek-genio-onnx-runtime-neuron). One platform note: on Genio 1200 the NeuronEP op coverage is narrower than on 520/720, so expect more fallback there and budget accordingly.
## Offline compilation: ncc-tflite and neuronrt
The delegate path above compiles the model to the APU at load time. For production, fixed models, faster startup, no runtime compile cost, compile ahead of time on a host PC into a hardware-specific `.dla` binary with the NeuronSDK compiler, then run it on the device.
Host-side compile (`ncc-tflite`):
```bash
export LD_LIBRARY_PATH=/path/to/neuropilot-sdk-basic-/neuron_sdk/host/lib
# INT8 quantized model
./ncc-tflite --arch=mdla3.0 model_int8.tflite -o model_int8.dla
# FP32 model, executed as FP16 on the NPU
./ncc-tflite --arch=mdla3.0 --relax-fp32 model.tflite -o model_fp32.dla
```
All NPU-capable Genio parts (510/700/520/720/1200) target `--arch=mdla3.0`. The `--relax-fp32` flag is the offline equivalent of the runtime `NEURON_FLAG_USE_FP16`.
On-device run and benchmark (`neuronrt`):
```bash
neuronrt -m hw -a model_int8.dla -i input.bin -c 10
# Total inference time = 52.648 ms (5.2648 ms/inf), Avg. FPS: 186.1 (YOLOv5s INT8)
```
`neuronrt` is for verification and benchmarking; production applications drive inference through the Neuron Runtime API (C/C++) for control over tensors and scheduling.
## Latency expectations by model class
These are representative figures on Genio 700 APU. Treat them as planning estimates, benchmark your actual model.
| Model | Quantization | Estimated APU latency |
|-------|-------------|----------------------|
| MobileNetV3-Small | INT8 | 5–8 ms |
| MobileNetV2 (224×224) | INT8 | 8–12 ms |
| EfficientNet-Lite0 | INT8 | 10–15 ms |
| EfficientDet-Lite0 | INT8 | 12–18 ms |
| YOLOv5n | INT8 | 20–30 ms |
| EfficientDet-Lite2 | INT8 | 30–50 ms |
For models with significant unsupported op content (transformers, complex attention mechanisms), the effective latency is the APU latency for supported ops plus CPU latency for unsupported ops. Models designed specifically for efficient deployment on mobile/edge APUs (MobileNet family, EfficientNet-Lite family) tend to have the best APU utilization.
For module comparison on how APU TOPS affects model selection, see [Genio 510 vs 700 vs 1200: which MediaTek module for your product](/blog/mediatek-genio-510-vs-700-vs-1200).
MediaTek's NeuroPilot developer portal is at [iot.mediatek.com](https://iot.mediatek.com/genio). The TFLite documentation for delegates is at [tensorflow.org](https://www.tensorflow.org/lite/performance/delegates).
---
## Real-time video on MediaTek Genio: GStreamer pipeline setup
URL: https://proventusnova.com/blog/mediatek-genio-gstreamer-real-time-video/
Published: 2026-05-12
Author: Aaron Angulo
Tags: mediatek genio, gstreamer, real-time video, v4l2, hardware acceleration
GStreamer pipeline setup for MediaTek Genio real-time video: hardware-accelerated H.264/H.265 encode and decode, V4L2 camera input, and 4K gotchas.
GStreamer on MediaTek Genio uses a different set of hardware-accelerated elements than Jetson, and the documentation is sparser. Getting real-time video working requires knowing which elements use the hardware codec, how to avoid the system memory bottleneck between pipeline stages, and what the known limitations are. This post covers the full pipeline setup.
## Key Insights
- MediaTek provides hardware-accelerated GStreamer elements for H.264/H.265 encode and decode, these work, but documentation is sparse
- Camera input uses standard V4L2 (`v4l2src`), not a proprietary element, which is both a strength and a limitation
- No NVMM-style zero-copy memory path: frames move through system RAM between pipeline stages
- Multi-process GStreamer pipelines compete for shared codec hardware, keep inference and video pipelines in the same process
- 4K60 encode is achievable on Genio 700 hardware; 4K120 on Genio 1200
## The GStreamer stack on Genio
MediaTek's IoT Yocto SDK includes a GStreamer plugin package (`gst-plugin-mtk` or similar depending on SDK version) that exposes the hardware video codec as GStreamer elements. The stack looks like this:
```
Camera → V4L2 kernel driver → v4l2src → [pipeline] → mtkh264enc → filesink / network
↓
waylandsink / kmssink (display)
```
This is different from Jetson's architecture, where camera input goes through the Argus API (Jetson-specific ISP) and frames live in NVMM memory from capture through encode. On Genio, V4L2 is the camera interface at the GStreamer level, standard Linux, which is actually easier to work with when you are debugging, but lacks the zero-copy optimization.
Beneath these elements, the hardware codec is driven by the `mtk-vcodec` V4L2 kernel driver and a user-space VPU daemon (`vpud.service`) that manages the codec hardware. The VPUD build maps SoC names internally (`mt8195 → mt8395`, `mt8370 → mt8188`), the same marketing-vs-internal naming mismatch that surfaces elsewhere in the Genio BSP, and worth knowing when a `vpud` recipe cannot find the codec firmware for your part.
## Hardware-accelerated elements
The MediaTek GStreamer plugin provides these elements (verify against your SDK version, element names can vary between IoT SDK releases):
| Element | Function |
|---------|----------|
| `mtkh264enc` | H.264 hardware encode |
| `mtkh264dec` | H.264 hardware decode |
| `mtkh265enc` | H.265/HEVC hardware encode |
| `mtkh265dec` | H.265/HEVC hardware decode |
| `mtkjpegenc` | JPEG hardware encode |
| `mtkjpegdec` | JPEG hardware decode |
Display sinks: `waylandsink` (Wayland compositor, the default on Genio Yocto builds), `kmssink` (KMS/DRM direct, for headless output to display without compositor). MediaTek patches `kmssink` to auto-detect the MTK KMS device; on an SDK build without that patch you have to pass `device=/dev/dri/card0` explicitly or the pipeline will not negotiate a display.
## Working pipeline examples
**Basic camera preview:**
```bash
gst-launch-1.0 \
v4l2src device=/dev/video0 ! \
video/x-raw,width=1920,height=1080,framerate=30/1 ! \
waylandsink
```
**Camera to H.264 file:**
```bash
gst-launch-1.0 \
v4l2src device=/dev/video0 ! \
video/x-raw,width=1920,height=1080,framerate=30/1 ! \
mtkh264enc ! \
h264parse ! \
mp4mux ! \
filesink location=output.mp4
```
**H.264 playback:**
```bash
gst-launch-1.0 \
filesrc location=input.mp4 ! \
qtdemux ! \
h264parse ! \
mtkh264dec ! \
waylandsink
```
**Camera + inference pipeline (single process):**
```bash
gst-launch-1.0 \
v4l2src device=/dev/video0 ! \
video/x-raw,width=640,height=480,framerate=30/1 ! \
tee name=t \
t. ! queue ! appsink name=inference_sink \
t. ! queue ! mtkh264enc ! h264parse ! mp4mux ! filesink location=record.mp4
```
## Known limitations to plan around
**No zero-copy memory path.** On Jetson, NVMM buffers let frames move from NVCSI through VI through nvvidconv through the encoder without touching CPU-accessible memory. Genio does not have an equivalent. Frames pass through system memory at each GStreamer element boundary. For 1080p30 this is fine. For 4K30 at high data rates, profile your memory bandwidth to make sure it is not a bottleneck.
**Multi-process codec contention.** The MediaTek hardware codec is a shared resource. If you run your inference pipeline in one process and your video record pipeline in another, both compete for the same encoder/decoder hardware. This is the same problem nvvidconv hits on Jetson with multiple processes, the solution is the same: keep related pipelines in the same process and use `tee` to branch the stream. Separate processes will work but will perform worse than a unified pipeline.
**4K decode needs the encoded-buffer-size patch.** The default encoded-buffer size in MediaTek's V4L2 GStreamer plugin is too small for 4K H.264/H.265 bitstreams, which shows up as decode failures or truncated frames rather than an obvious buffer error. MediaTek ships a `plugins-good` patch that raises the encoded buffer size for 4K, confirm it is applied in your SDK build before you start debugging the pipeline itself. A companion patch adds a force-non-blocking poll that stops `gst-launch` from hanging in some V4L2 capture scenarios.
**MJPEG decode uses the YM16 format.** Hardware MJPEG decode on Genio produces the YM16 planar YUV 4:2:2 16-bit format, added by a MediaTek `plugins-base` patch. If a downstream element rejects the MJPEG decoder output, a missing YM16 patch in the build is the usual cause.
**Sparse error messages.** When a `mtkh264enc` pipeline fails, the error messages are not always specific about why. Missing format capability, unsupported resolution, or hardware resource exhaustion can all produce similar generic errors. Start with a known-good pipeline at a standard resolution (1080p30) and change one variable at a time.
**ISP controls.** On Jetson, `nvarguscamerasrc` exposes ISP settings (exposure, white balance, gain) as GStreamer properties. On Genio, ISP control goes through V4L2 controls, `v4l2-ctl --set-ctrl`. This is more manual but also more standard, the same V4L2 control interface works on any Linux platform.
## Real-time video with inference
Running inference alongside video encode on Genio requires keeping everything in one GStreamer pipeline (or using shared memory between processes). A practical split: the encoder hardware runs independently of the APU, so you can record to file while running inference on the APU simultaneously without one consuming the other's budget.
What competes: CPU cycles (for the GStreamer pipeline thread, element processing) and memory bandwidth (camera frames flowing through system RAM). On Genio 700, a 1080p30 record + 640×480 inference workload is feasible. At 4K30 record + 1080p inference, profile memory bandwidth carefully.
For more on running inference on the APU alongside other workloads, see [running inference offline on MediaTek Genio: NeuroPilot, TFLite, and ONNX support](/blog/mediatek-genio-inference-offline-neuropilot).
GStreamer documentation for V4L2 source element: [gstreamer.freedesktop.org](https://gstreamer.freedesktop.org/documentation/video4linux2/v4l2src.html). MediaTek's IoT developer portal has the Genio SDK download with the GStreamer plugin package.
---
## Argus camera driver on Jetson: nvarguscamerasrc setup, ISP pipeline, and debugging
URL: https://proventusnova.com/blog/argus-api-camera-driver-jetson/
Published: 2026-05-11
Author: Aaron Angulo
Tags: jetson, argus, camera driver, libargus, nvarguscamerasrc, gstreamer, isp
Set up the Argus camera driver on NVIDIA Jetson: nvargus-daemon, nvarguscamerasrc pipelines, LibArgus C++ API, ISP features, and common Argus errors debugged.
The NVIDIA Argus API is how most production Jetson camera pipelines work. It sits above the V4L2 kernel driver and provides ISP processing, auto-exposure, auto-white-balance, HDR, without requiring you to build a custom ISP pipeline. If your camera produces blurry, poorly-exposed frames with raw V4L2 capture, Argus is usually the solution. This post covers how to get Argus working, what the API looks like, and what to do when it doesn't cooperate.
## Key Insights
- **Argus and V4L2 are not alternatives, they're layers.** The kernel driver (V4L2) must be working before Argus can do anything
- **nvargus-daemon is required**, it's a separate system service that manages the ISP hardware; if it's not running, all Argus calls fail immediately
- **The ISP adds real value**: AE, AWB, HDR, and denoise are handled automatically once Argus is running, with no additional application code
- **LibArgus C++ API** gives you full control; `nvarguscamerasrc` (GStreamer) gives you fast integration with existing pipelines
- **"No cameras available"** is almost always either a dead daemon or a driver that didn't register with the tegracam framework
## V4L2 vs Argus: which layer do you actually need?
Both operate on the same kernel driver. The kernel driver exposes a V4L2 subdev and video node. Argus, via nvargus-daemon, uses the V4L2 interface internally, processes frames through the ISP, and hands ISP-corrected output to your application.
| | V4L2 | Argus (LibArgus / nvarguscamerasrc) |
|---|---|---|
| Frame format | Raw Bayer, YUV | ISP-processed NV12, RGBA |
| ISP (AE, AWB, HDR) | No | Yes |
| GStreamer element | `v4l2src` | `nvarguscamerasrc` |
| Headless | Yes | Yes |
| Multi-camera sync | Manual | Built-in via sensor mode |
| NVIDIA-only | No | Yes |
The practical rule: if you need ISP output for a machine vision or AI inference pipeline, use Argus. If you need raw Bayer frames for custom processing or compatibility with non-NVIDIA tooling, use V4L2 directly.
## Setting up nvargus-daemon
The daemon is installed with the nvidia-l4t-libargus package (included in JetPack). On JetPack 6, it's managed by systemd:
```bash
# Check if it's running
systemctl status nvargus-daemon
# Start it
sudo systemctl start nvargus-daemon
# Enable it at boot
sudo systemctl enable nvargus-daemon
```
In headless setups (no display manager), the daemon often isn't started automatically because it has a display dependency in older JetPack releases. On JetPack 6, you can add it to a startup script or systemd target manually if it doesn't start on its own.
Verify the daemon is up before running any Argus code:
```bash
ps aux | grep nvargus
# Should show: /usr/sbin/nvargus-daemon
```
## GStreamer pipelines with nvarguscamerasrc
`nvarguscamerasrc` is the GStreamer source element that uses libargus internally. It's the fastest way to test your camera through the Argus path.
**Basic display test:**
```bash
gst-launch-1.0 nvarguscamerasrc sensor-id=0 ! \
'video/x-raw(memory:NVMM),width=1920,height=1080,framerate=30/1' ! \
nvvidconv ! 'video/x-raw,format=BGRx' ! \
videoconvert ! autovideosink
```
**Headless capture to file:**
```bash
gst-launch-1.0 nvarguscamerasrc sensor-id=0 num-buffers=300 ! \
'video/x-raw(memory:NVMM),width=1920,height=1080,framerate=30/1' ! \
nvv4l2h264enc ! h264parse ! qtmux ! \
filesink location=output.mp4
```
**Multiple cameras (sensor-id selects the camera):**
```bash
# Camera 0
gst-launch-1.0 nvarguscamerasrc sensor-id=0 ! \
'video/x-raw(memory:NVMM),width=1920,height=1080' ! nvvidconv ! autovideosink &
# Camera 1
gst-launch-1.0 nvarguscamerasrc sensor-id=1 ! \
'video/x-raw(memory:NVMM),width=1920,height=1080' ! nvvidconv ! autovideosink
```
The `(memory:NVMM)` caps keep frames in GPU memory between NVIDIA elements, avoiding a CPU copy. Always use NVMM caps between nvarguscamerasrc and nvvidconv.
**Check available sensor IDs:**
```bash
gst-launch-1.0 nvarguscamerasrc ! fakesink -v 2>&1 | grep "camera ID"
```
## ISP features Argus provides
Once the daemon is running, the ISP processes every frame automatically. Features available through the LibArgus API or nvarguscamerasrc properties:
**Auto-exposure (AE):** The ISP adjusts exposure time and gain to maintain target brightness. Enabled by default. Override with `exposuretimerange` and `gainrange` properties on nvarguscamerasrc.
**Auto-white-balance (AWB):** Color correction applied per-frame. Enabled by default. Override with `wbmode` property.
**ISP digital gain (IDG):** Additional gain applied after analog sensor gain. Useful for low-light without changing frame rate.
**HDR:** Supported on sensors that implement multi-exposure capture (sensor-specific, check your sensor driver's mode table).
**Noise reduction:** Temporal and spatial noise reduction applied by the ISP. Controlled via the LibArgus API `IDenoiseSettings` interface.
## LibArgus C++ API basics
For applications that need direct ISP control beyond what nvarguscamerasrc exposes:
```cpp
#include
#include
using namespace Argus;
// 1. Create the camera provider
UniqueObj cameraProvider(CameraProvider::create());
ICameraProvider* iCameraProvider = interface_cast(cameraProvider);
// 2. Get camera devices
std::vector cameraDevices;
iCameraProvider->getCameraDevices(&cameraDevices);
CameraDevice* cameraDevice = cameraDevices[0];
// 3. Create capture session
UniqueObj captureSession(
iCameraProvider->createCaptureSession(cameraDevice));
ICaptureSession* iCaptureSession = interface_cast(captureSession);
// 4. Create output stream (EGLStream for GPU consumption)
UniqueObj streamSettings(
iCaptureSession->createOutputStreamSettings(STREAM_TYPE_EGL));
UniqueObj outputStream(
iCaptureSession->createOutputStream(streamSettings.get()));
// 5. Create request and submit
UniqueObj request(iCaptureSession->createRequest(CAPTURE_INTENT_PREVIEW));
IRequest* iRequest = interface_cast(request);
iRequest->enableOutputStream(outputStream.get());
// Start repeating capture
iCaptureSession->repeat(request.get());
```
The LibArgus headers live in `/usr/include/Argus/`. Link against `-lnvargus`. Full API documentation is in the JetPack SDK at `/usr/src/jetson_multimedia_api/argus/`.
## Common Argus errors
**"No cameras available"**
The sensor isn't registered with Argus. Check in order: (1) daemon running? `systemctl status nvargus-daemon`; (2) kernel driver probed? `dmesg | grep -i imx` or your sensor name; (3) driver implements tegracam interface? Reference drivers do; custom/ported drivers may not.
**"Failed to create capture session"**
The camera device exists but the ISP pipeline couldn't be initialized. Usually a kernel driver probe issue, the driver probed but didn't complete ISP configuration. Check `dmesg` during daemon start for VI or NVCSI errors.
**"nvarguscamerasrc: Internal data flow error"**
Frame delivery failure mid-stream. Usually a NVMM buffer exhaustion, either not consuming frames fast enough, or a downstream element isn't releasing buffers. Add `! queue` between nvarguscamerasrc and the next element.
**"Cannot open camera 0" / wrong sensor-id**
Sensor IDs are assigned at boot based on DTS order. If you have two cameras but only one is connected, sensor-id=0 may not be camera 0 by DTS position. Use the sensor ID inspection command above to verify which IDs are active.
## Debugging checklist
```bash
# 1. Daemon running?
systemctl status nvargus-daemon
# 2. Kernel driver loaded and probed?
lsmod | grep -i imx # replace with your sensor module name
dmesg | grep -i "probe"
# 3. V4L2 node exists?
v4l2-ctl --list-devices
# 4. Media pipeline intact?
media-ctl -d /dev/media0 --print-topology
# 5. GStreamer plugins available?
gst-inspect-1.0 nvarguscamerasrc
# 6. Test with minimal pipeline
gst-launch-1.0 nvarguscamerasrc num-buffers=10 ! fakesink -v
```
If step 5 fails ("No such element"), the nvidia-l4t-gstreamer package isn't installed: `sudo apt install nvidia-l4t-gstreamer`.
If step 6 hangs at "Setting pipeline to PLAYING" without error, the daemon is running but ISP initialization stalled, reboot the daemon and check dmesg for VI probe errors.
For the underlying kernel driver setup that Argus depends on, see [CSI camera driver on Jetson: V4L2, Argus, and IMX sensor bring-up](/blog/csi-camera-driver-jetson-v4l2-argus-imx). If you need to write a custom V4L2 driver for a sensor that isn't supported out of the box, see [how to write a custom V4L2 camera driver for Jetson Orin](/blog/custom-v4l2-camera-driver-jetson-orin). If you need camera driver development or ISP bring-up beyond what your sensor vendor provides, [ProventusNova handles Jetson camera driver development](/services/csi).
## FAQ
### What is the NVIDIA Argus API and how is it different from V4L2?
Argus (libargus) is NVIDIA's proprietary camera stack that sits above the V4L2 kernel driver. V4L2 gives you raw frame access, Bayer or YUV, with no ISP processing. Argus adds auto-exposure, auto-white-balance, HDR, and noise reduction through the Jetson ISP hardware. Both require the same kernel driver underneath; the choice between them is made at the application layer.
### How do I start nvargus-daemon on Jetson?
Run `sudo systemctl start nvargus-daemon` to start it once, or `sudo systemctl enable nvargus-daemon` to start it automatically at boot. Verify it's running with `systemctl status nvargus-daemon`. If the daemon isn't running, nvarguscamerasrc will produce "No cameras available" and LibArgus calls will fail immediately.
### Why does nvarguscamerasrc say "No cameras available"?
Three causes cover almost all cases: (1) nvargus-daemon isn't running; (2) the sensor kernel driver failed to probe, check `dmesg | grep -i camera` for probe errors; (3) the sensor isn't registered in the Argus sensor registry, the kernel driver must implement the tegracam interface for Argus to recognize it.
### Can I use Argus without a display server running?
Yes. nvargus-daemon runs as a system service and doesn't require X or Wayland. GStreamer pipelines using nvarguscamerasrc work fully headless, pipe to a file, UDP stream, or inference pipeline without any display.
### When should I use Argus instead of V4L2 directly?
Use Argus (nvarguscamerasrc or LibArgus) when you need ISP processing: auto-exposure, auto-white-balance, HDR, or denoise. Use V4L2 directly when you need raw Bayer frames, precise control over every ISP parameter, or compatibility with non-NVIDIA tooling.
---
---
## How to use flash.sh on Jetson Orin: parameters, board configs, and common errors
URL: https://proventusnova.com/blog/flash-sh-jetson-orin-guide/
Published: 2026-05-11
Author: Andres Campos
Tags: jetson, flash.sh, jetpack, bsp, jetson orin, board bring-up, l4t
Using flash.sh on Jetson Orin: board configs, recovery mode, partial flash with -k, custom carrier board workflow, and the 5 most common flash errors fixed.
`flash.sh` is NVIDIA's flashing tool included in every L4T BSP release. It's how you get JetPack onto a Jetson board for the first time, reflash after a failed bring-up, update the kernel, or flash a custom carrier board. Understanding its parameters and failure modes saves hours on every bring-up engagement. This post covers everything you need to use flash.sh on Jetson Orin correctly.
## Key Insights
- **flash.sh is in `Linux_for_Tegra/`** after extracting the L4T BSP, not installed as a system command
- **Recovery mode must be verified with `lsusb`** before running flash.sh, a USB connection alone isn't enough
- **The board config file determines what gets flashed**, wrong config on a custom carrier board results in a bricked board
- **Partial flash with `-k`** lets you update just the kernel or DTB without touching the rootfs, much faster for iterative bring-up
- **For custom carrier boards**, apply the vendor BSP with `apply_binaries.sh` before flashing, skipping this step is the most common mistake we see
## Prerequisites
Flash.sh runs on an Ubuntu host (20.04 or 22.04, NVIDIA's tested platforms). You need:
- Ubuntu host machine (native preferred over VM for USB reliability)
- NVIDIA JetPack/L4T BSP extracted on the host
- USB-A to USB-C or USB-A to Micro-B cable (depends on board, check your board docs)
- The Jetson board powered off
Install required host tools:
```bash
sudo apt install python3-pip qemu-user-static
pip3 install pyserial
```
## Extracting the BSP
Download the L4T BSP from NVIDIA's developer site. For Jetson Orin, the BSP is two tarballs: the main L4T package and the rootfs.
```bash
# Extract L4T
tar xf Jetson_Linux_R36.x.x_aarch64.tbz2
# Extract rootfs into the correct location
cd Linux_for_Tegra/rootfs/
sudo tar xpf ../../Tegra_Linux_Sample-Root-Filesystem_R36.x.x_aarch64.tbz2
# Apply default binaries
cd ..
sudo ./apply_binaries.sh
```
After this, `flash.sh` is at `Linux_for_Tegra/flash.sh`.
## Putting Jetson Orin in recovery mode
Recovery mode makes the board present as a flashing target over USB. Without it, flash.sh cannot reach the board.
**Orin devkit recovery sequence:**
1. Ensure the board is powered off
2. Connect USB cable from host to the Orin's USB-C recovery port
3. Hold the **FORCE RECOVERY** button (labeled on the devkit)
4. Press and release the **POWER** button
5. Release FORCE RECOVERY
Verify on the host:
```bash
lsusb | grep NVIDIA
# Expected output:
# Bus 001 Device 005: ID 0955:7023 NVIDIA Corp. APX
```
If you see the APX device, the board is in recovery mode and ready to flash. If nothing appears, try a different USB cable, many USB-C cables are charge-only and don't carry data.
**Custom carrier board recovery:** The recovery pin location varies by board. Check your carrier board schematic or vendor documentation for the FORCE RECOVERY GPIO or button.
## Basic flash command
```bash
cd Linux_for_Tegra
sudo ./flash.sh
```
**Common board configs for Jetson Orin devkits:**
| Board | Config file |
|-------|-------------|
| Jetson Orin Nano (8GB, devkit) | `jetson-orin-nano-devkit` |
| Jetson Orin Nano (4GB, devkit) | `jetson-orin-nano-devkit-4g` |
| Jetson Orin NX 16GB (devkit) | `jetson-orin-nx-16g-devkit` |
| Jetson Orin NX 8GB (devkit) | `jetson-orin-nx-8g-devkit` |
| Jetson AGX Orin (devkit) | `jetson-agx-orin-devkit` |
**Storage device targets:**
| Storage type | Target value |
|---|---|
| eMMC | `mmcblk0p1` |
| NVMe SSD | `nvme0n1p1` |
| USB | `sda` |
| SD card (Orin Nano) | `mmcblk1p1` |
Full flash example for Orin Nano to eMMC:
```bash
sudo ./flash.sh jetson-orin-nano-devkit mmcblk0p1
```
Flash takes 5–15 minutes depending on rootfs size and USB speed. Watch for `Flash successfully` in the output.
## Partial flash with the -k flag
Reflashing the full rootfs every time you change the kernel or device tree is slow. Use `-k` to update a single partition:
```bash
# Flash only the kernel
sudo ./flash.sh -k kernel jetson-orin-nano-devkit mmcblk0p1
# Flash only the device tree
sudo ./flash.sh -k kernel-dtb jetson-orin-nano-devkit mmcblk0p1
# Flash bootloader only (QSPI)
sudo ./flash.sh -k bup-payload jetson-orin-nano-devkit mmcblk0p1
```
Partial flash is the standard workflow during BSP bring-up iteration, change DTS, flash `kernel-dtb`, boot, verify, repeat. No rootfs touch means your test environment stays intact.
**List available partitions:**
```bash
sudo ./flash.sh --no-flash jetson-orin-nano-devkit mmcblk0p1
# Generates the flash image and partition list without actually flashing
```
## Flashing a custom carrier board
Custom carrier boards require a vendor-provided board config file. The workflow:
**1. Apply the vendor BSP:**
```bash
cd Linux_for_Tegra
sudo ./apply_binaries.sh
```
If the vendor provides their own apply script, run that instead, some vendors add extra binary patches beyond the standard `apply_binaries.sh`.
**2. Use the vendor's config file:**
```bash
# Vendor config files are typically in bootloader/
ls bootloader/ | grep ".conf"
# Flash with vendor config
sudo ./flash.sh mmcblk0p1
```
The vendor BSP README specifies the exact config file name. Using the wrong config on a custom carrier board (e.g., using `jetson-orin-nano-devkit` when the board has a different power tree) can result in a boot failure or hardware damage in extreme cases.
**3. Verify flash with vendor's recommended boot procedure.** Some vendor boards require additional steps after flash (QSPI write, bootloader key injection).
## Common errors
**"Device not found" or flash.sh hangs at start**
The board isn't in recovery mode, or the USB connection isn't recognized. Run `lsusb | grep NVIDIA` first. If nothing appears, recovery mode failed. Try: different cable, different USB port (USB 2.0 port is often more reliable than USB 3.0 for recovery), and verify recovery button sequence.
**"tegraflash.py failed with error 1"**
The underlying flash tool (tegraflash.py) encountered an error. Check the full output for the specific failure message. Common causes: missing Python dependencies (`pip3 install pyserial`), wrong board config, or corrupted BSP extraction. Re-extract the BSP and retry.
**"Failed to push bootloader payload"**
USB connection dropped mid-flash. Usually a cable or hub issue. Use a direct USB connection to the host (no hub), and if possible a shorter cable. Some USB 3.0 ports have issues with Jetson recovery mode, try USB 2.0.
**"Partition table mismatch"**
The board config specifies a partition layout that doesn't match what's already on the device. This happens when switching board configs (e.g., changing eMMC to NVMe). Add `--no-systemimg` flag, or do a full QSPI erase first with:
```bash
sudo ./flash.sh --erase-all jetson-orin-nano-devkit mmcblk0p1
```
**"apply_binaries.sh: command not found"**
You're in the wrong directory, or the BSP wasn't extracted correctly. `apply_binaries.sh` lives in `Linux_for_Tegra/`. If it's missing, re-extract the L4T BSP tarball.
## Generating a flash image without flashing
The `--no-flash` flag generates the full flash image and partition XML without connecting to any board. Useful for CI/CD pipelines or pre-staging:
```bash
sudo ./flash.sh --no-flash jetson-orin-nano-devkit mmcblk0p1
```
This produces `flash.img` and the partition layout in `Linux_for_Tegra/bootloader/`. The image can then be flashed separately using tegraflash.py directly.
## Verifying the flash
After a successful flash, the board reboots into JetPack. Verify the L4T version:
```bash
cat /etc/nv_tegra_release
# R36 (release), REVISION: 3.0, GCID: ...
# Or via the jtop tool
sudo pip3 install jetson-stats
jtop
```
Confirm the CUDA, TensorRT, and JetPack versions match what you flashed.
If the board doesn't boot after a successful `Flash successfully` message, the most common cause is a device tree mismatch, the board config doesn't match the actual hardware. For custom carrier board boot failures, see [Jetson carrier board not booting: 6 root causes](/blog/jetson-carrier-board-not-booting-root-causes). For UEFI shell failures specifically, see [Jetson UEFI shell at boot: assertion errors and how to recover](/blog/jetson-uefi-shell-assertion-boot-recovery). If you're flashing a custom carrier board as part of a bring-up engagement, [ProventusNova handles the full BSP bring-up process](/services/custom-board-bringup).
## FAQ
### How do I put Jetson Orin in recovery mode for flashing?
On the Orin devkit: hold the FORCE RECOVERY button, press and release the POWER button, then release FORCE RECOVERY. Verify with `lsusb | grep NVIDIA`, you should see `0955:7023 NVIDIA Corp. APX`. If nothing appears, try a different USB cable or port. A USB 2.0 port is sometimes more reliable than USB 3.0 for recovery mode.
### What board config file should I use with flash.sh?
For NVIDIA devkits: `jetson-orin-nano-devkit` (Orin Nano), `jetson-agx-orin-devkit` (AGX Orin), `jetson-orin-nx-16g-devkit` (Orin NX 16GB). For custom carrier boards or third-party boards, use the `.conf` file provided in the vendor's BSP package.
### Can flash.sh flash just the kernel without reflashing the entire rootfs?
Yes. Use the `-k` flag: `sudo ./flash.sh -k kernel jetson-orin-nano-devkit mmcblk0p1`. Common targets: `kernel` (kernel image), `kernel-dtb` (device tree), `APP` (rootfs).
### How do I flash a custom carrier board with flash.sh?
Apply the vendor BSP first with `sudo ./apply_binaries.sh`. Then flash using the vendor's board config file: `sudo ./flash.sh mmcblk0p1`. The vendor's BSP README specifies the exact config file name.
### Why does flash.sh say "device not found" even with the USB connected?
The board isn't in recovery mode. Verify with `lsusb | grep NVIDIA`, you must see the APX device. If lsusb shows nothing: try a different USB cable (some cables are charge-only), use a direct USB-A port instead of a hub, and verify you held the recovery button before applying power.
---
---
## nvarguscamerasrc pipeline examples for Jetson
URL: https://proventusnova.com/blog/gstreamer-pipeline-examples-jetson/
Published: 2026-05-11
Author: Aaron Angulo
Tags: jetson, gstreamer, nvarguscamerasrc, nvvidconv, v4l2src, pipeline, camera
nvarguscamerasrc pipeline examples for Jetson, copy-paste commands for capture, encode, decode, plus when to use v4l2src instead.
GStreamer on Jetson uses NVIDIA-specific elements for hardware-accelerated camera capture, format conversion, and encode/decode. These elements, nvarguscamerasrc, nvvidconv, nvv4l2h264enc, nvv4l2decoder, have different properties and caps requirements than their generic Linux equivalents. This post is a practical reference for the GStreamer pipelines that actually work on Jetson Orin, with copy-paste commands for the most common use cases.
## Key Insights
- **NVMM caps** (`video/x-raw(memory:NVMM)`) keep frames in GPU memory between NVIDIA elements, always use them between nvarguscamerasrc, nvvidconv, and nvv4l2h264enc
- **nvarguscamerasrc** is for ISP-processed camera capture; **v4l2src** is for raw sensor frames
- **kmssink** works without X or Wayland, use it for headless display output on embedded setups
- **nvv4l2h264enc and nvv4l2decoder** use Jetson's hardware encode/decode engines; `avenc_h264` and `avdec_h264` are software fallbacks
- **gst-inspect-1.0** and **GST_DEBUG** are your primary debugging tools, inspect before troubleshooting
## Prerequisites
Install NVIDIA's GStreamer plugins:
```bash
sudo apt install nvidia-l4t-gstreamer gstreamer1.0-plugins-good gstreamer1.0-plugins-bad gstreamer1.0-tools
```
Verify NVIDIA elements are available:
```bash
gst-inspect-1.0 nvarguscamerasrc
gst-inspect-1.0 nvvidconv
gst-inspect-1.0 nvv4l2h264enc
gst-inspect-1.0 nvv4l2decoder
```
If any of these fail, the nvidia-l4t-gstreamer package wasn't installed or its plugins didn't load. Check `gst-inspect-1.0 --gst-plugin-path /usr/lib/aarch64-linux-gnu/gstreamer-1.0/`.
## Camera capture pipelines
### nvarguscamerasrc (ISP path, recommended for production)
Basic display test:
```bash
gst-launch-1.0 nvarguscamerasrc sensor-id=0 ! \
'video/x-raw(memory:NVMM),width=1920,height=1080,framerate=30/1' ! \
nvvidconv ! 'video/x-raw,format=BGRx' ! \
videoconvert ! autovideosink
```
Headless, capture to file:
```bash
gst-launch-1.0 nvarguscamerasrc sensor-id=0 num-buffers=300 ! \
'video/x-raw(memory:NVMM),width=1920,height=1080,framerate=30/1' ! \
nvv4l2h264enc ! h264parse ! qtmux ! \
filesink location=/tmp/capture.mp4
```
Get ISP-processed frames as NV12 for OpenCV or inference:
```bash
gst-launch-1.0 nvarguscamerasrc sensor-id=0 ! \
'video/x-raw(memory:NVMM),width=1280,height=720,framerate=30/1' ! \
nvvidconv ! 'video/x-raw,format=NV12' ! \
appsink name=sink max-buffers=1 drop=true
```
Check available sensor IDs:
```bash
gst-launch-1.0 nvarguscamerasrc ! fakesink -v 2>&1 | grep "Available Sensor"
```
### v4l2src (raw V4L2 path)
Basic display (format depends on sensor):
```bash
gst-launch-1.0 v4l2src device=/dev/video0 ! \
'video/x-raw,format=YUY2,width=1920,height=1080,framerate=30/1' ! \
videoconvert ! autovideosink
```
Display via KMS/DRM without X server:
```bash
gst-launch-1.0 v4l2src device=/dev/video0 ! \
'video/x-raw,format=YUY2,width=1920,height=1080,framerate=30/1' ! \
videoconvert ! kmssink
```
Check what formats your camera supports:
```bash
v4l2-ctl --list-formats-ext -d /dev/video0
```
Raw capture to file (useful for debugging sensor output):
```bash
gst-launch-1.0 v4l2src device=/dev/video0 num-buffers=30 ! \
'video/x-raw,format=RG10,width=1920,height=1080' ! \
filesink location=/tmp/raw_frames.bin
```
## Hardware encode
### H.264 encode
Camera → H.264 file:
```bash
gst-launch-1.0 nvarguscamerasrc sensor-id=0 ! \
'video/x-raw(memory:NVMM),width=1920,height=1080,framerate=30/1' ! \
nvv4l2h264enc bitrate=8000000 ! h264parse ! \
qtmux ! filesink location=output.mp4
```
Camera → H.264 UDP stream (for remote viewing):
```bash
# Sender (Jetson)
gst-launch-1.0 nvarguscamerasrc sensor-id=0 ! \
'video/x-raw(memory:NVMM),width=1920,height=1080,framerate=30/1' ! \
nvv4l2h264enc ! h264parse ! \
rtph264pay ! udpsink host=192.168.1.100 port=5000
# Receiver (laptop)
gst-launch-1.0 udpsrc port=5000 ! \
'application/x-rtp,encoding-name=H264,payload=96' ! \
rtph264depay ! avdec_h264 ! autovideosink
```
### H.265 encode
H.265 typically achieves the same quality at half the bitrate:
```bash
gst-launch-1.0 nvarguscamerasrc sensor-id=0 ! \
'video/x-raw(memory:NVMM),width=1920,height=1080,framerate=30/1' ! \
nvv4l2h265enc bitrate=4000000 ! h265parse ! \
qtmux ! filesink location=output.mp4
```
**nvv4l2h264enc key properties:**
- `bitrate`, target bitrate in bps (default: 4000000)
- `maxperf-enable`, set to true for maximum throughput at higher power
- `preset-level`, 1 (ultra-fast) to 4 (best quality), default 3
## Hardware decode
MP4 file → display:
```bash
gst-launch-1.0 filesrc location=video.mp4 ! \
qtdemux ! h264parse ! nvv4l2decoder ! \
nvvidconv ! 'video/x-raw,format=BGRx' ! \
videoconvert ! autovideosink
```
H.265 decode:
```bash
gst-launch-1.0 filesrc location=video.mp4 ! \
qtdemux ! h265parse ! nvv4l2decoder ! \
nvvidconv ! autovideosink
```
**Note:** nvv4l2decoder outputs NVMM-format frames. Connect directly to nvvidconv (not videoconvert) to stay in the hardware path.
## nvvidconv, format conversion and scaling
nvvidconv is Jetson's hardware video converter. Use it between NVIDIA elements for format conversion and scaling without CPU involvement.
Convert YUY2 → BGRx:
```bash
gst-launch-1.0 v4l2src device=/dev/video0 ! \
'video/x-raw,format=YUY2,width=1920,height=1080' ! \
nvvidconv ! 'video/x-raw,format=BGRx,width=1920,height=1080' ! \
videoconvert ! autovideosink
```
Scale and convert in one step:
```bash
gst-launch-1.0 nvarguscamerasrc sensor-id=0 ! \
'video/x-raw(memory:NVMM),width=1920,height=1080,framerate=30/1' ! \
nvvidconv ! 'video/x-raw(memory:NVMM),width=640,height=360' ! \
nvv4l2h264enc ! h264parse ! qtmux ! filesink location=scaled.mp4
```
**Important:** When connecting two NVIDIA elements, add `(memory:NVMM)` to the caps between them:
```bash
# Correct, stays in GPU memory
! nvvidconv ! 'video/x-raw(memory:NVMM),format=NV12' ! nvv4l2h264enc
# Wrong, forces CPU copy
! nvvidconv ! 'video/x-raw,format=NV12' ! nvv4l2h264enc
```
## Multi-camera pipelines
View two cameras side by side:
```bash
gst-launch-1.0 \
nvarguscamerasrc sensor-id=0 name=cam0 ! \
'video/x-raw(memory:NVMM),width=1280,height=720,framerate=30/1' ! \
nvvidconv ! 'video/x-raw,format=BGRx,width=640,height=360' ! videoconvert ! \
compositor name=mix sink_0::xpos=0 sink_0::ypos=0 sink_1::xpos=640 sink_1::ypos=0 ! \
autovideosink \
nvarguscamerasrc sensor-id=1 ! \
'video/x-raw(memory:NVMM),width=1280,height=720,framerate=30/1' ! \
nvvidconv ! 'video/x-raw,format=BGRx,width=640,height=360' ! videoconvert ! \
mix.
```
Record both cameras independently:
```bash
gst-launch-1.0 \
nvarguscamerasrc sensor-id=0 ! \
'video/x-raw(memory:NVMM),width=1920,height=1080,framerate=30/1' ! \
nvv4l2h264enc ! h264parse ! qtmux ! filesink location=cam0.mp4 \
nvarguscamerasrc sensor-id=1 ! \
'video/x-raw(memory:NVMM),width=1920,height=1080,framerate=30/1' ! \
nvv4l2h264enc ! h264parse ! qtmux ! filesink location=cam1.mp4
```
## RTSP and network streaming
### UDP streaming (lowest latency)
Send a camera stream over UDP from Jetson to a remote host:
```bash
# Jetson (sender)
gst-launch-1.0 \
nvarguscamerasrc sensor-id=0 ! \
'video/x-raw(memory:NVMM),width=1920,height=1080,framerate=30/1' ! \
nvv4l2h264enc bitrate=4000000 iframeinterval=30 ! \
h264parse ! rtph264pay ! \
udpsink host=192.168.1.100 port=5000 sync=false
# Remote host (receiver)
gst-launch-1.0 \
udpsrc port=5000 ! \
'application/x-rtp,encoding-name=H264,payload=96' ! \
rtph264depay ! avdec_h264 ! autovideosink
```
### Record locally while streaming
Use `tee` to split the pipeline, one branch to file, one branch to network:
```bash
gst-launch-1.0 \
nvarguscamerasrc sensor-id=0 ! \
'video/x-raw(memory:NVMM),width=1920,height=1080,framerate=30/1' ! \
nvv4l2h264enc bitrate=4000000 ! h264parse ! \
tee name=t \
t. ! queue ! rtph264pay ! udpsink host=192.168.1.100 port=5000 sync=false \
t. ! queue ! qtmux ! filesink location=/tmp/recording.mp4
```
### H.265 for lower bandwidth
H.265 (HEVC) achieves similar quality at roughly half the bitrate:
```bash
gst-launch-1.0 \
nvarguscamerasrc sensor-id=0 ! \
'video/x-raw(memory:NVMM),width=1920,height=1080,framerate=30/1' ! \
nvv4l2h265enc bitrate=2000000 ! h265parse ! rtph265pay ! \
udpsink host=192.168.1.100 port=5001 sync=false
```
**Key streaming properties:**
- `sync=false` on udpsink, removes presentation timestamp delay
- `iframeinterval=30`, keyframe every second; lower values improve recovery from packet loss
- `max-size-buffers=1 leaky=2` on queue before udpsink, drops old frames on network congestion instead of building a backlog
## Python appsink: getting frames into OpenCV
This pattern pulls GStreamer frames into Python as NumPy arrays for OpenCV processing on Jetson:
```python
import gi
gi.require_version('Gst', '1.0')
from gi.repository import Gst, GLib
import numpy as np
import cv2
Gst.init(None)
pipeline = Gst.parse_launch(
'nvarguscamerasrc sensor-id=0 ! '
'video/x-raw(memory:NVMM),width=1280,height=720,framerate=30/1 ! '
'nvvidconv ! '
'video/x-raw,format=BGRx,width=1280,height=720 ! '
'appsink name=sink max-buffers=1 drop=true emit-signals=true'
)
appsink = pipeline.get_by_name('sink')
def on_new_sample(sink):
sample = sink.emit('pull-sample')
if not sample:
return Gst.FlowReturn.ERROR
buf = sample.get_buffer()
caps = sample.get_caps()
w = caps.get_structure(0).get_int('width').value
h = caps.get_structure(0).get_int('height').value
success, map_info = buf.map(Gst.MapFlags.READ)
if not success:
return Gst.FlowReturn.ERROR
frame = np.frombuffer(map_info.data, dtype=np.uint8).reshape(h, w, 4)
frame_bgr = cv2.cvtColor(frame, cv2.COLOR_BGRA2BGR)
buf.unmap(map_info)
# Your processing here
cv2.imshow('Jetson Camera', frame_bgr)
cv2.waitKey(1)
return Gst.FlowReturn.OK
appsink.connect('new-sample', on_new_sample)
pipeline.set_state(Gst.State.PLAYING)
loop = GLib.MainLoop()
loop.run()
```
The `format=BGRx` cap on nvvidconv outputs 4-channel BGRA which reshapes cleanly into a NumPy array. The final `cvtColor` strips the alpha channel. Using `max-buffers=1 drop=true` on appsink ensures the pipeline never backs up waiting for your callback, old frames are dropped if processing is slow.
**Do not call `cv2.imshow` inside the appsink callback in production.** The callback runs on a GStreamer streaming thread. Move heavy processing to a separate thread using a `queue.Queue` and pass frames across.
## Auto-reconnect on source failure
For production pipelines where the camera or network source may disconnect, listen on the pipeline bus and restart on error or EOS:
```python
import gi
gi.require_version('Gst', '1.0')
from gi.repository import Gst, GLib
import time
Gst.init(None)
PIPELINE_DESC = (
'udpsrc port=5000 ! '
'application/x-rtp,encoding-name=H264,payload=96 ! '
'rtph264depay ! avdec_h264 ! autovideosink'
)
def start_pipeline():
pipeline = Gst.parse_launch(PIPELINE_DESC)
pipeline.set_state(Gst.State.PLAYING)
return pipeline
def on_message(bus, message, pipeline_ref):
if message.type in (Gst.MessageType.ERROR, Gst.MessageType.EOS):
pipeline_ref[0].set_state(Gst.State.NULL)
time.sleep(2) # backoff
pipeline_ref[0] = start_pipeline()
pipeline_ref[0].get_bus().add_signal_watch()
pipeline_ref[0].get_bus().connect('message', on_message, pipeline_ref)
return True
pipeline_ref = [start_pipeline()]
bus = pipeline_ref[0].get_bus()
bus.add_signal_watch()
bus.connect('message', on_message, pipeline_ref)
loop = GLib.MainLoop()
loop.run()
```
The pipeline reference is wrapped in a list so the callback can replace it. On any error or EOS, the pipeline is torn down and a fresh one is started after a 2-second backoff. For production, use exponential backoff with a cap rather than a fixed delay.
## Debugging pipelines
**Inspect element properties:**
```bash
gst-inspect-1.0 nvarguscamerasrc
gst-inspect-1.0 nvv4l2h264enc
```
**Verbose caps negotiation:**
```bash
gst-launch-1.0 -v nvarguscamerasrc ! fakesink 2>&1 | head -50
```
**Enable debug logging:**
```bash
# Log all elements at level 3
GST_DEBUG=3 gst-launch-1.0 nvarguscamerasrc sensor-id=0 ! fakesink
# Log specific elements
GST_DEBUG=nvarguscamerasrc:5,nvvidconv:4 gst-launch-1.0 ...
```
**Check pipeline state manually:**
```bash
# Add -v to see state changes
gst-launch-1.0 -v nvarguscamerasrc sensor-id=0 ! \
'video/x-raw(memory:NVMM)' ! nvvidconv ! autovideosink
```
**Common pipeline errors:**
| Error | Cause | Fix |
|---|---|---|
| "No such element: nvarguscamerasrc" | nvidia-l4t-gstreamer not installed | `sudo apt install nvidia-l4t-gstreamer` |
| "Internal data flow error" | Buffer backpressure | Add `! queue` after the source |
| "nvarguscamerasrc: No cameras available" | nvargus-daemon not running | `sudo systemctl start nvargus-daemon` |
| Pipeline hangs at PLAYING | NVMM path broken | Check caps have `(memory:NVMM)` between NVIDIA elements |
| "Cannot identify /dev/video0" | Camera not probed | Check `v4l2-ctl --list-devices` |
For camera driver bring-up that these pipelines depend on, see [CSI camera driver on Jetson: V4L2, Argus, and IMX sensor bring-up](/blog/csi-camera-driver-jetson-v4l2-argus-imx). For Argus-specific setup including nvargus-daemon, see [NVIDIA Argus API camera driver on Jetson](/blog/argus-api-camera-driver-jetson). For pipeline performance issues, nvvidconv throughput collapse under multiple processes, see [nvvidconv performance with multiple GStreamer processes on Jetson](/blog/nvvidconv-performance-multiple-gstreamer-processes).
## FAQ
### Why does nvarguscamerasrc say "No such element or plugin"?
The nvidia-l4t-gstreamer package isn't installed. Install it with: `sudo apt install nvidia-l4t-gstreamer`. Also verify `gst-inspect-1.0 nvarguscamerasrc` returns the element description. If it still fails after install, nvargus-daemon isn't running, start it with `sudo systemctl start nvargus-daemon`.
### What is the difference between v4l2src and nvarguscamerasrc on Jetson?
`v4l2src` reads raw frames directly from the V4L2 kernel driver, no ISP processing. `nvarguscamerasrc` routes through the nvargus-daemon and Jetson ISP, providing auto-exposure, auto-white-balance, and hardware noise reduction. Use nvarguscamerasrc for production pipelines that need ISP output; use v4l2src when you need raw Bayer frames or have a sensor that isn't Argus-compatible.
### What does "video/x-raw(memory:NVMM)" mean in a Jetson GStreamer pipeline?
NVMM keeps frame buffers in GPU memory, avoiding a CPU copy between NVIDIA hardware elements. When connecting nvarguscamerasrc to nvvidconv, or nvvidconv to nvv4l2h264enc, always use NVMM caps to maintain the hardware-accelerated path. Without NVMM, frames are copied through system RAM, adding latency and CPU load.
### Why does my GStreamer pipeline stall or produce "Internal data flow error"?
Usually buffer backpressure, a downstream element isn't consuming frames as fast as they arrive. Add `! queue` between the source and a slow downstream element. If the pipeline stops after a few seconds, check for missing NVMM caps, this often causes stalls in the format conversion stage.
### How do I display a Jetson camera feed without X or Wayland (headless)?
Use `kmssink` for DRM/KMS direct rendering without a display server: `gst-launch-1.0 v4l2src device=/dev/video0 ! videoconvert ! kmssink`. Or pipe to a file or network stream instead of a display sink.
---
---
## Third-party NVIDIA Jetson carrier board manufacturers compared for edge AI
URL: https://proventusnova.com/blog/jetson-carrier-board-manufacturers-compared/
Published: 2026-05-11
Author: Andres Campos
Tags: jetson, carrier board, manufacturers, gmsl2, hardware selection, edge ai
Third-party Jetson carrier board manufacturers compared: Connect Tech, Leopard Imaging, FRAMOS, Auvidea, Tier IV, Seeed Studio. BSP quality and GMSL2 support.
Choosing a third-party Jetson carrier board involves more than checking the connector pinout. The BSP quality, camera driver support, and the vendor's JetPack update cadence determine whether the board saves you time or costs you weeks of bring-up. This post compares the main Jetson carrier board manufacturers for edge AI applications, what they make, what their BSP actually covers, and which fits which project.
## Key Insights
- **BSP quality varies more than hardware quality**, a board with poor or unmaintained BSP support costs you bring-up time even if the hardware is solid
- **GMSL2 requires a specific vendor shortlist**, Leopard Imaging and Tier IV have the most mature GMSL2 support; most other vendors don't support GMSL2 at all
- **"BSP available" in the product listing means nothing without specifics**, ask which sensors are validated, which JetPack version, and when it was last updated
- **Seeed Studio reComputer is the price leader**, but BSP depth is lighter, fine for evaluation, not for a production camera pipeline
- **Custom carrier boards** are a different conversation, third-party boards get you hardware faster, but you'll still likely need bring-up help for camera drivers
## What "carrier board" actually means
A Jetson carrier board hosts the Jetson System-on-Module (SoM). The SoM contains the SoC, RAM, and eMMC. The carrier board provides power, USB, PCIe, camera interfaces, and all the connectors your product needs. NVIDIA sells devkits with their own carrier boards; third-party manufacturers sell alternative carriers with different form factors, connector configurations, and camera support.
The critical distinction for software teams: the carrier board manufacturer is responsible for the BSP that makes the hardware work with JetPack. NVIDIA's BSP covers the devkit. Everything else is the vendor's responsibility.
## How do you choose a Jetson carrier board?
Work through four questions in order, they eliminate most of the market quickly:
1. **How many cameras, and over what interface?** More than 2 cameras or cable runs beyond ~30cm means GMSL2 (or FPD-Link), that alone narrows you to Leopard Imaging, Tier IV, or DesignCore. Direct CSI at short range keeps everyone in play.
2. **What environment?** Industrial temperature range, vibration, or an enclosure requirement points to Connect Tech, Forecr, or Tier IV. Bench and indoor prototypes can use anything.
3. **Who owns the BSP?** If nobody on the team wants to maintain device trees and JetPack migrations, pay for vendor BSP quality (Connect Tech's update cadence is the benchmark). If you have embedded Linux capacity in-house, a cheaper board with a basic BSP (Auvidea) is a legitimate trade.
4. **Prototype or production?** Seeed reComputer is fine to start development this week, but validate your production camera path on the production board, not the prototype one.
If your form factor, connector, or interface requirements survive none of the off-the-shelf options, that is the [custom carrier board](#custom-carrier-boards-vs-third-party-boards) conversation.
## The main manufacturers
### Connect Tech, Best overall BSP track record
[Connect Tech](https://connecttech.com) (CTI) has been making Jetson carrier boards longer than most. Their Rogue and Boson series for Jetson Orin are well-maintained, and their BSP packages (CTI board support packages) are updated with each major JetPack release.
| | |
|---|---|
| **Modules supported** | Orin NX, Orin Nano, AGX Orin |
| **Notable boards** | Rogue (industrial compact), Boson (full-size industrial), Quill |
| **GMSL2 support** | Via FRAMOS adapter integration; not native on most boards |
| **BSP quality** | High, maintained against current L4T, documented |
| **Price tier** | Mid ($400–$900) |
| **Best for** | Industrial deployments, teams that need a maintained BSP and don't want to manage it themselves |
CTI's BSP support is their strongest differentiator. When JetPack 6 shipped, CTI had updated BSPs available within weeks. If you're building on Orin and want a third-party board without a BSP headache, CTI is the safest choice for non-GMSL2 applications.
### Leopard Imaging, Best for camera-forward designs
[Leopard Imaging](https://leopardimaging.com) focuses specifically on camera modules and carrier boards. Their boards are designed around camera connectivity, and their BSP packages include camera drivers for their sensor modules, which is unusual in this market.
| | |
|---|---|
| **Modules supported** | Orin NX, Orin Nano, AGX Orin |
| **Notable boards** | LI-ORIN-NANO-SD, LI-Orin-GMSL2-4CAM, LI-Orin-GMSL2-8CAM |
| **GMSL2 support** | Native, GMSL2-focused boards with MAX9296A/MAX96724 |
| **BSP quality** | High for their validated sensors; limited outside their sensor ecosystem |
| **Price tier** | Mid to high ($500–$1,500) |
| **Best for** | Projects requiring GMSL2 cameras or validated ISP pipelines for specific sensors |
If your design requires GMSL2 cameras, Leopard Imaging should be your first evaluation. Their GMSL2 carrier boards ship with driver support for IMX390 and other sensors in their lineup. The tradeoff: their BSP works well for their sensors but requires more work to add sensors outside their catalog.
### FRAMOS, Best sensor ecosystem depth
[FRAMOS](https://www.framos.com) focuses on camera modules and adapter boards rather than full carrier boards. Their FSA-FPA adapter board system adds camera connectivity to existing Jetson carriers. Their value is the FRAMOS Sensor Driver Package, which includes drivers for a wide range of Sony, onsemi, and Omnivision sensors.
| | |
|---|---|
| **Modules supported** | Orin NX, Orin Nano, AGX Orin (via adapter to other carriers) |
| **Notable products** | FPA-4.A-X1 adapter boards, FSA-FPA camera modules |
| **GMSL2 support** | Limited, CSI focus |
| **BSP quality** | High within their sensor ecosystem |
| **Price tier** | Mid ($300–$800 for adapter + module) |
| **Best for** | Teams with an existing carrier board who need validated drivers for FRAMOS sensor modules |
FRAMOS is a good choice if you've already selected a carrier board and need drivers for a specific sensor module that FRAMOS supports. Less useful if you're starting from scratch and need a full board selection.
### Tier IV, Best for automotive and GMSL2
[Tier IV](https://tier4.jp) builds Jetson carrier boards for automotive applications. Their IE-4000 is an automotive-grade carrier with native GMSL2 support, designed for multi-camera autonomous driving setups.
| | |
|---|---|
| **Modules supported** | AGX Orin primarily |
| **Notable boards** | IE-4000 (automotive, GMSL2) |
| **GMSL2 support** | Native, up to 8 GMSL2 cameras with MAX96724 |
| **BSP quality** | High, maintained for automotive reliability requirements |
| **Price tier** | High ($2,000–$3,000+) |
| **Best for** | Automotive, robotics, or industrial applications requiring high GMSL2 camera counts and long-term support |
If you're building an autonomous vehicle or robotic perception system with multiple GMSL2 cameras and need board-level support you can count on for years, Tier IV is worth the premium. For most edge AI applications without those requirements, it's overspecced.
### Auvidea, Low-cost industrial option
[Auvidea](https://auvidea.eu) makes a range of Jetson carrier boards at competitive price points, particularly for the B369 and B386 targeting Orin. BSP support is more basic than CTI or Leopard.
| | |
|---|---|
| **Modules supported** | Orin NX, Orin Nano, AGX Orin |
| **Notable boards** | B369, B386, B203 |
| **GMSL2 support** | Limited, primarily CSI |
| **BSP quality** | Basic, base L4T BSP; less camera-driver depth |
| **Price tier** | Low-mid ($200–$600) |
| **Best for** | Teams comfortable managing their own BSP who want a lower hardware cost |
Auvidea boards work well as hardware platforms, but expect more BSP self-management. Good choice if your team has embedded Linux experience and wants to own the BSP work.
### Seeed Studio reComputer, Best entry-level option
[Seeed Studio](https://www.seeedstudio.com)'s reComputer J series (J3010, J4011, J4012) are accessible Jetson Orin boards aimed at developers and prototype-stage teams. Lower price, lighter BSP depth.
| | |
|---|---|
| **Modules supported** | Orin NX, Orin Nano |
| **Notable boards** | reComputer J3010, J4011, J4012 |
| **GMSL2 support** | None |
| **BSP quality** | Basic, community support, less enterprise-grade maintenance |
| **Price tier** | Low ($150–$400) |
| **Best for** | Prototyping, evaluation, early development before production board selection |
The reComputer series is fine for getting Jetson development started. Don't plan a production camera pipeline around it without verifying that your specific camera is supported.
### DesignCore (D3 Embedded), Best for high camera counts
[D3 Embedded](https://www.d3embedded.com)'s DesignCore line targets rugged, multi-camera perception systems, including 8-camera GMSL2 configurations on Orin. D3 also offers integration support alongside the boards, which is worth factoring into the purchase path.
| | |
|---|---|
| **Modules supported** | Orin NX, AGX Orin |
| **Notable boards** | DesignCore rugged GMSL2 carriers (up to 8 cameras) |
| **GMSL2 support** | Native, high camera counts |
| **BSP quality** | High for their validated camera kits |
| **Price tier** | High (quote-based) |
| **Best for** | Robotics/perception products needing many synchronized GMSL2 cameras with integration support behind them |
### Forecr, Industrial catalog alternative
[Forecr](https://www.forecr.io) (Mist Elektronik) ships the DSBOARD line of industrial Jetson carriers with enclosures, and publishes flashing guides and BSP packages per JetPack release, better documentation discipline than most vendors in its price range.
| | |
|---|---|
| **Modules supported** | Orin NX, Orin Nano, AGX Orin |
| **Notable boards** | DSBOARD-ORNX, DSBOARD-AGX |
| **GMSL2 support** | Limited, primarily CSI/USB |
| **BSP quality** | Mid, documented, regular updates |
| **Price tier** | Low-mid |
| **Best for** | Industrial deployments on a budget that still want documented BSPs and enclosures |
## Comparison table
| Vendor | GMSL2 | BSP quality | JetPack updates | Price tier | Best use case |
|--------|-------|-------------|----------------|------------|---------------|
| Connect Tech | Via adapter | ★★★★★ | Fast | $$$ | Industrial non-GMSL2 |
| Leopard Imaging | Native | ★★★★☆ | Regular | $$$ | GMSL2, validated ISP |
| FRAMOS | No | ★★★★☆ | Regular | $$$ | Sensor module ecosystem |
| Tier IV | Native | ★★★★★ | Automotive cadence | $$$$$ | Automotive, multi-GMSL2 |
| Auvidea | Limited | ★★★☆☆ | Irregular | $$ | Teams owning BSP |
| Seeed reComputer | No | ★★☆☆☆ | Community | $ | Prototyping |
| DesignCore (D3) | Native, 8-cam | ★★★★☆ | With services | $$$$ | Multi-camera perception |
| Forecr | Limited | ★★★☆☆ | Regular | $$ | Industrial on a budget |
## Questions to ask any vendor before buying
**"Which sensors is your BSP validated with?"** The answer should name specific sensors (IMX390, IMX219, etc.) with JetPack version numbers. If the answer is vague, the BSP validation is likely equally vague.
**"What JetPack version is your BSP currently validated on?"** If the answer is JetPack 5 and you're targeting JetPack 6, you have a migration project.
**"How are BSP updates delivered when JetPack is updated?"** Good vendors have a release cadence. Others ship one BSP and stop.
**"Do you provide device tree source for your camera configurations?"** If you need to modify camera settings (different sensor, different mode), you need DTS source. Binary-only BSPs are a lock-in risk.
**"What is your support channel for bring-up issues?"** Forum, Slack, email, or phone, and what's the typical response time.
## Custom carrier boards vs. third-party boards
Third-party carrier boards get you hardware faster. But even with a third-party board, you often need bring-up help for:
- Camera sensors not in the vendor's supported list
- Custom peripheral integration (PCIe devices, specific UART configs)
- JetPack migration when the vendor's BSP hasn't been updated
A custom carrier board is the right call when your product has specific form factor, connector, or interface requirements that no off-the-shelf board matches. The hardware design cost is typically $50k–$150k depending on complexity; the BSP bring-up cost is additional.
From our own bring-up work, the BSP-quality gap between vendors is wider than the spec sheets suggest. The recurring red flags: a vendor BSP still pinned one or two JetPack majors behind current, device tree shipped as binary only (you cannot add a sensor without vendor involvement), and flash scripts that assume the devkit layout and silently fail on the vendor's own board. Any of these turns a "supported" board into a rescue project, ask the questions above *before* the purchase order, not after.
Once you've selected a board, third-party or custom, the bring-up work starts. If you're working on a GMSL2 camera pipeline or need camera driver development for sensors outside your vendor's supported list, [ProventusNova handles Jetson camera bring-up](/services/csi) from driver to verified frame capture. For GMSL2-specific bring-up, see [GMSL2 camera bring-up on Jetson Orin](/blog/gmsl2-camera-bringup-jetson-orin-max9295-max9296). And if you would rather hand off the vendor evaluation itself, sample sourcing, spec matching, and ODM negotiation, that is what our [hardware sourcing service](/services/hardware-sourcing) does.
## FAQ
### Which is the best Jetson carrier board manufacturer?
It depends on your camera requirements. Connect Tech and Leopard Imaging have the strongest BSP support. For GMSL2 cameras, Leopard Imaging and Tier IV are the most mature options. For a lower price point with acceptable BSP quality, Connect Tech's Rogue or Seeed Studio's reComputer series are worth evaluating.
### Do third-party Jetson carrier boards include a BSP?
Some do, most don't, at least not a properly maintained one. Connect Tech, Leopard Imaging, FRAMOS, and Tier IV all provide BSP packages maintained against current JetPack releases. Auvidea and generic board-only vendors typically provide a base L4T BSP without camera drivers or custom peripheral support. Always ask which JetPack version the BSP was last validated on.
### What is the difference between a Jetson carrier board and a custom carrier board?
A third-party carrier board is an off-the-shelf board you buy from a manufacturer. A custom carrier board is one your team designs specifically for your product. Custom boards have better fit for your exact connector and peripheral requirements but require BSP bring-up work. Third-party boards trade flexibility for faster time-to-hardware, but still often require BSP bring-up for camera drivers.
### Which Jetson carrier boards support GMSL2 cameras?
Leopard Imaging (LI-Orin-GMSL2 series), Tier IV (IE-4000), DesignCore/D3 Embedded (rugged carriers up to 8 GMSL2 cameras), and Connect Tech (some configurations with FRAMOS adapters) have documented GMSL2 support with BSPs. If GMSL2 is a requirement, start with Leopard Imaging, Tier IV, or DesignCore.
### How do I choose between Jetson carrier board vendors?
Four questions in order: camera count/interface (>2 cameras or long cable runs → GMSL2 vendors), environment (industrial → Connect Tech, Forecr, Tier IV), BSP ownership (no in-house embedded Linux capacity → pay for BSP quality), and prototype vs production (validate the production camera path on the production board).
### How much does a Jetson Orin carrier board cost?
Entry-level boards (Seeed Studio reComputer, some Auvidea) run $150–$400. Mid-tier boards with solid BSP support (Connect Tech Rogue, Leopard Imaging) are typically $400–$900. Industrial-grade and GMSL2-focused boards (Tier IV IE-4000, Connect Tech Boson) can be $1,000–$3,000+.
---
---
## MediaTek Genio for robotics edge AI: inference, camera, BSP reality
URL: https://proventusnova.com/blog/mediatek-genio-robotics-edge-ai/
Published: 2026-05-09
Author: Andres Campos
Tags: mediatek genio, robotics, edge ai, ros2, inference
Is MediaTek Genio viable for robotics edge AI? Honest assessment of inference latency, camera pipeline, ROS 2 support, and BSP limitations for robotics builds.
MediaTek Genio is viable for robotics edge AI applications with the right expectation setting, it handles lightweight perception workloads at low power, but lacks the CUDA acceleration, GMSL2 camera support, and ROS 2 ecosystem depth that Jetson Orin provides. Whether it is the right choice depends on what your robot needs to perceive and how much power budget you have.
## Key Insights
- Genio handles simple robotics perception, single or dual camera, lightweight INT8 models, at meaningful power savings over Jetson
- ROS 2 runs on Genio's Yocto Linux, but CUDA-dependent packages need porting or replacement
- No GMSL2 support on Genio: for automotive-style long-cable cameras, this is a disqualifying gap
- APU latency on Genio 700 is 20–30ms for small YOLO-class models, workable for many AMR applications, not for time-critical manipulation
- If your application needs CUDA, Isaac ROS, or complex multi-camera fusion, Jetson Orin is the right platform
## What "robotics edge AI" actually requires
Robotics perception is a broad category. The compute requirements depend almost entirely on what the robot needs to perceive and how fast.
A mobile robot doing warehouse navigation with obstacle detection and basic object classification needs something very different from a robotic arm doing bin picking with depth estimation and 6-DOF pose regression. Before deciding whether Genio is viable, you need to know which category you are in.
The question is not "can Genio run robotics AI", it can, in limited cases. The question is whether your specific perception workload fits within its capabilities, and whether the ecosystem gaps are something your team can absorb.
## Inference latency on Genio's APU
Genio's APU is an efficient fixed-function neural network accelerator, not a GPU. It runs INT8 quantized models fast and at low power. It does not have CUDA cores, Tensor Cores, or NVDLA-style deep learning accelerators.
What this means for robotics inference:
| Model | Genio 700 APU (est.) | Jetson Orin NX GPU |
|-------|---------------------|-------------------|
| MobileNetV3-Small (INT8) | 5–8 ms | < 2 ms |
| EfficientDet-Lite0 (INT8) | 12–18 ms | < 5 ms |
| YOLOv5n (INT8) | 20–30 ms | 5–10 ms |
| YOLOv5s (INT8) | 40–60 ms (estimate) | 10–20 ms |
These are approximate figures, actual latency depends on the NeuroPilot delegate version, model architecture specifics, and memory bandwidth utilization. Always benchmark on the actual target hardware before committing.
For an AMR running obstacle detection at 15–20 fps, Genio 700 can handle this with lightweight models. For a manipulation system needing 30+ fps depth estimation with a complex model, the latency budget does not work.
## ROS 2 on Genio: what works and what does not
ROS 2 runs on Genio. It is just a Linux process, and Genio's Yocto SDK gives you a standard Linux userspace. You can build ROS 2 from source (or use a compatible Yocto layer) and run your node graph.
What works:
- CPU-bound ROS 2 packages: navigation stack, tf2, parameter server, standard sensor drivers
- V4L2-based camera nodes (via standard Linux V4L2, no Argus equivalent)
- Point cloud processing on CPU
- Standard serial/CAN/GPIO interfaces for actuator control
What does not work without porting:
- Any package that calls CUDA directly
- Isaac ROS nodes (NVIDIA-specific, CUDA + cuDNN backend)
- Packages that use cuDNN or TensorRT for model inference
For the inference side, the path on Genio is through NeuroPilot's TFLite delegate, not TensorRT. Any ROS node using TensorRT needs to be rewritten to use TFLite + NeuroPilot. This is real engineering work, not a configuration change.
## Camera pipeline for robotics
Genio's camera interface is MIPI CSI-2 over standard V4L2. This is the same interface most robotics cameras support, so hardware compatibility is generally not the problem.
What you get with Genio 700/1200:
- Up to 16 MIPI CSI-2 lanes → supports 2–4 cameras in typical robotics configurations
- ISP for image processing (auto-exposure, white balance, de-noise)
- Hardware frame sync via GPIO trigger, needed for stereo or multi-camera setups (same approach as Jetson: see [multi-camera synchronization on Jetson CSI](/blog/multi-camera-sync-jetson-csi))
What is missing versus Jetson:
- No GMSL2 support. For any camera using GMSL2 (long-cable coax connection, common in autonomous vehicles and outdoor robots), Genio is not an option.
- Smaller camera sensor ecosystem, fewer validated drivers for specific sensors
- Less community documentation for camera bring-up issues
For a 2-camera mobile robot using standard MIPI CSI cameras, Genio is workable. For any design using GMSL2 cameras or needing a validated 4-camera rig out of the box, Jetson has a significant practical advantage.
## Where Genio makes sense for robotics
The honest Genio robotics use case:
- **Battery-powered mobile robots** where the difference between 4W and 25W is a 6x battery life improvement
- **High-volume platforms** where BOM cost per unit matters more than time-to-first-prototype
- **Simple perception workloads**, single camera object detection, basic navigation with lightweight models
- **Integration with MediaTek cellular**, for robots using LTE/5G connectivity where the companion chip integration simplifies the design
If you are building a one-off research robot or a small production run, the BSP ecosystem gaps add real schedule risk. If you are building at volume with a well-defined perception workload that fits Genio's capability, the power and cost advantages are real.
For comparison against Jetson Orin across all these dimensions, see [MediaTek Genio vs NVIDIA Jetson Orin: which platform for edge AI](/blog/mediatek-genio-vs-nvidia-jetson).
---
## Genio 510 vs 700 vs 1200: which MediaTek module for your product
URL: https://proventusnova.com/blog/mediatek-genio-510-vs-700-vs-1200/
Published: 2026-05-08
Author: Andres Campos
Tags: mediatek genio, genio 510, genio 700, genio 1200, edge ai, module selection
MediaTek Genio 510 vs 700 vs 1200 comparison for embedded AI products. AI TOPS, camera lanes, memory, power, and which module fits which application.
The three Genio modules are not just different speeds of the same chip, they have different ISP capabilities, different camera lane counts, and different power envelopes that affect which applications each is suited for. Choosing the wrong module creates hardware constraints that software cannot fix. This post covers the differences that matter for product decisions.
## Key Insights
- Genio 510 targets cost-sensitive IoT and simple vision; Genio 700 targets vision-AI applications with 2-4 cameras; Genio 1200 targets demanding multi-camera and complex inference
- APU performance difference between 510 and 1200 is roughly 2×, meaningful for inference-heavy applications
- All three modules share the same Linux BSP base (IoT Yocto SDK), a driver written for Genio 700 runs on Genio 1200 with minimal changes
- The camera lane count and ISP capability differ between modules, verify your camera count requirement against the specific module's spec before committing to a design
- Memory bandwidth is often the practical bottleneck before raw TOPS becomes the limit
## The three Genio modules and where they fit
MediaTek's Genio family covers a range from entry-level IoT compute to mid-range edge AI. The three main modules, Genio 510, 700, and 1200, are not just different speeds of the same chip. They have different ISP capabilities, different camera lane counts, and different power envelopes.
| Property | Genio 510 | Genio 700 | Genio 1200 |
|----------|----------|----------|-----------|
| Chip | MT8390 | MT8395 | MT8395 / MT8395P |
| Process | 6nm | 6nm | 6nm |
| CPU | 4× A78 + 4× A55 | 4× A78 + 4× A55 | 4× A78 + 4× A55 |
| APU (INT8 TOPS) | ~2 TOPS | ~4 TOPS | ~4.8 TOPS |
| GPU | Mali-G57 MC4 | Mali-G57 MC5 | Mali-G57 MC5 |
| Max RAM | 8 GB LPDDR5 | 16 GB LPDDR5 | 16 GB LPDDR5 |
| MIPI CSI-2 lanes | 4 lanes | Up to 16 lanes | Up to 16 lanes |
| Video encode | Up to 4K30 | Up to 4K60 | Up to 4K120 |
| TDP | ~4W | ~6W | ~8W |
| Connectivity | PCIe, USB3, I2C, SPI | PCIe, USB3, I2C, SPI | PCIe, USB3, I2C, SPI |
Note: specifications vary by specific module variant and board implementation. Verify against MediaTek's official product briefs for your exact configuration.
## Genio 510: entry-level IoT and simple vision
Genio 510 is the right module when your application involves:
- Single camera or simple dual-camera setups
- Lightweight inference models (MobileNet, EfficientDet-Lite, small YOLO variants)
- IoT edge compute with moderate AI requirements
- Strict cost sensitivity at volume
The 2 TOPS APU is sufficient for running one or two lightweight detection models at real-time frame rates on a single camera stream. For a smart camera, a retail analytics device, or a building automation controller with visual sensing, Genio 510 hits the cost and power targets without overpowering the application.
Where Genio 510 is not the right choice: 4-camera systems, complex models that require more than ~2 TOPS, or applications that need 4K video encoding alongside inference.
## Genio 700: the sweet spot for vision-AI products
Genio 700 is where most vision-AI embedded products will land. The step up from 510 is meaningful:
- 4 TOPS APU handles medium-complexity detection models (YOLOv5s, EfficientDet-D1) at real-time rates
- More MIPI camera lanes support 2–4 simultaneous cameras
- Higher memory bandwidth reduces the likelihood of memory becoming the bottleneck before compute
- 4K60 video encode enables recording alongside inference
For a product doing object detection on 2 camera streams with a medium model, or running separate detection and classification models in a pipeline, Genio 700 is the right fit. It also leaves enough headroom for NeuroPilot SDK's INT8 optimizations to push model performance further.
Typical applications that match Genio 700: industrial visual inspection with 2-4 cameras, smart retail with camera-based analytics, robotics with moderate perception requirements.
## Genio 1200: top-end Genio for demanding applications
Genio 1200 provides incremental improvements over Genio 700: ~20% more APU performance, better multimedia capabilities (4K120 encode), and higher-end positioning. The BOM cost premium over Genio 700 is real, and for many applications the delta in APU performance is not the bottleneck.
Genio 1200 makes sense when:
- Your inference pipeline is saturating Genio 700's APU headroom
- You need 4K120 video encode alongside AI inference
- You need the maximum memory bandwidth available in the Genio family
For most edge AI vision products, Genio 700 is sufficient and Genio 1200 adds cost without proportional performance gain. The exception is applications genuinely bottlenecked by APU throughput, run your model benchmarks on Genio 700 first before committing to Genio 1200.
## The camera lane question
Camera lane count is a practical design constraint that often forces the module selection more than compute does.
Genio 510 has limited MIPI CSI-2 lane capacity. If your design requires 4 cameras at full resolution, Genio 510 may not physically support it, you need Genio 700 or 1200 regardless of compute requirements.
For designs with 4+ CSI cameras, verify the MIPI lane count for the specific Genio module variant against your camera configuration before finalizing hardware. The 16-lane maximum on Genio 700/1200 supports 4× 4-lane sensors or 8× 2-lane sensors, but your carrier board must route all those lanes correctly.
## BSP compatibility across modules
One practical advantage of the Genio family: all three modules share the same Linux BSP foundation (MediaTek IoT Yocto SDK). A camera driver written for Genio 700 compiles for Genio 1200 with little or no modification. This means you can prototype on a Genio 700 development board and then move to Genio 1200 for production without a full software port, assuming the hardware routing is equivalent.
This also means the BSP maturity discussion from [MediaTek Genio vs NVIDIA Jetson Orin](/blog/mediatek-genio-vs-nvidia-jetson) applies equally across all three modules, they share the same strengths and the same limitations in BSP documentation depth.
MediaTek's official product pages for the Genio family are at [MediaTek Genio IoT products](https://iot.mediatek.com/genio). SEEED Studio's Genio development boards are at [seeedstudio.com](https://www.seeedstudio.com/).
---
## MediaTek Genio vs NVIDIA Jetson Orin: which platform for edge AI
URL: https://proventusnova.com/blog/mediatek-genio-vs-nvidia-jetson/
Published: 2026-05-07
Author: Aaron Angulo
Tags: mediatek genio, nvidia jetson, edge ai, platform comparison, embedded ai
MediaTek Genio vs NVIDIA Jetson Orin for edge AI products. Compute, camera support, BSP maturity, ecosystem, and which platform wins for robotics.
MediaTek Genio and NVIDIA Jetson Orin both run Linux and support neural network inference, but they target fundamentally different points on the cost, performance, and power tradeoff curve. The decision between them usually comes down to three factors: compute requirements, camera complexity, and volume. This post covers the comparison at the level that actually matters for product decisions.
## Key Insights
- Jetson Orin leads on AI compute throughput, GPU availability, camera ecosystem depth, and BSP maturity
- MediaTek Genio leads on power efficiency, lower BOM cost at volume, and connectivity integration
- The AI TOPS gap is significant: AGX Orin at 275 TOPS vs. Genio 1200 APU at ~4.8 TOPS, different leagues for complex models
- BSP maturity is the less visible but often most consequential difference in product development timelines
- For most robotics and multi-camera vision applications, Jetson is the clearer choice; Genio is competitive for simpler inference at lower power
- Genio has two underrated advantages for industrial products: a hard real-time domain (Linux plus Zephyr isolated on Jailhouse, on the Genio 720) and long production longevity (committed into the 2030s)
- The Genio NPU runtime matrix is chip-specific: ONNX Runtime on the NPU works only on the Genio 520 and 720, while Jetson's TensorRT path is uniform across every Orin module
## The two platforms at a glance
MediaTek Genio and NVIDIA Jetson Orin are both positioned as edge AI compute platforms for embedded products. Both run Linux. Both support camera input and neural network inference. Beyond that, they are quite different in their architecture, ecosystem, and what kinds of products they are actually suited for.
| Property | Jetson Orin (NX 16GB) | MediaTek Genio 1200 |
|----------|----------------------|---------------------|
| AI compute | Up to 100 TOPS (GPU + DLA) | ~4.8 TOPS (APU) |
| GPU | NVIDIA Ampere (1024 CUDA cores) | Mali-G57 (no CUDA) |
| CPU | 8× Arm Cortex-A78AE | 4× Cortex-A78 + 4× Cortex-A55 |
| Memory | Up to 16 GB LPDDR5 | Up to 8 GB LPDDR5 |
| MIPI CSI ports | 4 (8 lanes) | Up to 4 CSI-2 |
| GMSL2 support | Via carrier board ecosystem | Not standard |
| TDP | ~25W | ~5–8W |
| BSP | L4T (R36), mature, well-documented | IoT Yocto SDK, newer |
| Community | Large, active | Smaller |
| AI frameworks | CUDA, TensorRT, DLA, cuDNN (uniform across SKUs) | NeuroPilot / MDLA, TFLite on NPU; ONNX Runtime on NPU only on Genio 520/720 |
| Price (dev kit) | ~$499–$899 (module) | ~$149–$249 (dev kit) |
| Production longevity | Long NVIDIA Jetson production lifecycle | Committed to 2035 (MediaTek longevity program) |
| Hard real-time | PREEMPT_RT kernel (tuned Linux) | PREEMPT_RT; isolated Zephyr cell via Jailhouse on Genio 720 |
## AI compute: the gap that matters
The most significant difference between the platforms is AI compute. This matters because the compute available determines which models you can run at real-time frame rates.
Jetson Orin NX combines an NVIDIA Ampere GPU (CUDA cores + Tensor Cores) with dedicated DLA (Deep Learning Accelerator) hardware. TensorRT optimizes models for this combination. A YOLOv8-medium model runs at 30+ fps on Jetson Orin NX. More complex detection and segmentation models that would require cloud inference on lower-end hardware run on-device.
MediaTek Genio 1200's APU is an efficient neural network accelerator, not a GPU. It handles lightweight models well: MobileNetV3, EfficientDet-Lite, lightweight segmentation models. For those applications it is power-efficient. For YOLOv8, ResNet-50 depth estimation, or any multi-model pipeline, the ~4.8 TOPS is the bottleneck.
If your application runs on a model that fits within 4.8 TOPS (or if you are deploying to Genio 700 with even less headroom), Genio is viable. If you are running production AI workloads that require 20+ TOPS to meet your latency target, Jetson Orin is the right call.
## AI frameworks: which Genio chips actually run ONNX on the NPU
There is a constraint in MediaTek's AI stack that does not show up on a spec sheet but decides whether your model pipeline ports cleanly: not every Genio chip runs the same inference runtimes on its NPU.
The accelerator itself is the APUSys MDLA (Multi-Dimension Learning Accelerator). Models are compiled offline with the NeuronSDK toolchain (`ncc-tflite --arch=mdla3.0`) into an MDLA binary, then loaded at runtime. Two runtime paths sit on top of it, and they do not have the same coverage:
- **TFLite with the Neuron Delegate** runs on the NPU across the AI-capable Genio lineup.
- **ONNX Runtime with the NPU Execution Provider** runs on only two platforms: the **Genio 520 and Genio 720**. On every other Genio (350, 510, 700, 1200), ONNX Runtime falls back to the CPU or the Mali GPU rather than the MDLA.
So if your stack is built on ONNX Runtime and you need it accelerated on the NPU, the platform decision is partly made for you: it is the 520 or the 720. We have watched teams pick a higher-tier Genio for the headline compute, then find their ONNX pipeline will not touch the NPU on that part.
Jetson does not have this split. TensorRT compiles for the GPU and DLA on every Orin module, and ONNX feeds TensorRT through a standard parser, so the runtime path is identical from Orin Nano to AGX Orin. That uniformity is part of what BSP maturity buys you. For the full deployment walkthrough, see [running ONNX Runtime on the Genio NPU](/blog/mediatek-genio-onnx-runtime-neuron).
## Camera ecosystem: where Jetson leads clearly
Jetson has a camera ecosystem built up over a decade: hundreds of supported sensors, multiple GMSL2 carrier board vendors, established V4L2 driver frameworks, and community-contributed camera drivers for niche sensors.
MediaTek Genio supports MIPI CSI-2, and there are reference camera designs. But the depth of the ecosystem is not comparable. Fewer sensor vendors have Genio-validated drivers. GMSL2 (the interface used for automotive and long-cable cameras) is not a standard part of the Genio platform. For designs with complex camera requirements, multiple cameras, GMSL2, high-resolution sensors, Jetson has a significant practical advantage.
This matters for product development timelines. Camera bring-up on Jetson, while not trivial, has documented failure modes and a community that has seen the same problems. Camera bring-up on Genio is less charted territory.
## BSP maturity: the hidden project risk
NVIDIA has maintained L4T since 2012. The documentation is comprehensive, the community is large, and the failure patterns are well-understood. When something goes wrong with a Jetson BSP, there is usually a forum thread, a developer blog, or an NVIDIA support engineer who has seen it before.
MediaTek's IoT Yocto SDK for Genio is newer. The documentation is improving but thinner. The community is smaller. BSP-level debugging, device tree issues, driver failures, power domain problems, requires more direct engagement with MediaTek support rather than self-service resolution.
For a startup with a fixed product development timeline, BSP maturity translates directly into schedule risk. The week you spend finding the right MediaTek contact for a Genio BSP issue is a week that would have been a forum search on Jetson.
There are also platform-specific traps that only surface once you are deep in a build. MediaTek's hardware IP blocks carry internal names that differ from the marketing names, and the BSP recipes use the internal ones. The Genio 510 (MT8370) builds its GPU, VPU, and ISP firmware against `mt8188`; the Genio 720 (MT8391) maps to `mt8189`; the Genio 1200 (MT8395) to `mt8195`. A recipe written against the marketing name installs the wrong firmware and fails in ways that are hard to trace back. None of this lives in one place in the documentation, you learn it by reading the layers. That is the kind of cost BSP maturity quietly absorbs on the Jetson side.
## Real-time determinism: Genio's underrated advantage
Most edge-AI comparisons skip hard real-time, because teams evaluating these boards are usually thinking about inference rather than control. It is worth covering, because this is one axis where Genio has a genuine architectural edge.
The Genio 720 can run a Linux root cell and a Zephyr RTOS inmate cell side by side on the Jailhouse hypervisor. The two are isolated in memory, interrupts, and CPU cores. The Zephyr cell gets deterministic timing that the Linux scheduler cannot perturb, while Linux keeps the application stack, networking, and OTA. A fault in one cell does not bring down the other. For a product that pairs an application-processor workload with tight motor control, sensor acquisition, or deterministic I/O, that partitioning is hard to replicate any other way.
Jetson approaches real-time differently. You can build a PREEMPT_RT kernel for Orin and pull scheduling latency down, but that is tuned general-purpose Linux, not a hardware-isolated RTOS cell. If you need a real-time domain that survives a Linux panic, the Genio-plus-Jailhouse architecture is the cleaner answer. For the bring-up specifics on each side, see [Jailhouse on the MediaTek Genio](/blog/jailhouse-hypervisor-mediatek-genio) and [PREEMPT_RT on Jetson Orin](/blog/jetson-orin-preempt-rt-real-time-kernel).
## When Genio makes sense
Genio is the right choice when:
- Your AI workload fits within ~4 TOPS and your priority is power efficiency over maximum compute
- You are building at volume where BOM cost advantage (Genio at ~$20–40 per chip vs. Jetson at higher price points) matters significantly
- Your product needs tight integration with MediaTek's cellular or wireless connectivity stack
- Camera requirements are straightforward (2-4 CSI cameras, standard sensors)
- Your product needs a hard real-time domain alongside Linux (the Genio 720 with Linux plus Zephyr on Jailhouse), which Jetson does not provide as a hardware-isolated cell
- You need a long, guaranteed production lifecycle; MediaTek commits Genio supply into the 2030s (see our [Genio longevity and supply plan](/blog/mediatek-genio-soc-longevity-supply-plan))
For single-camera or dual-camera products with lightweight inference models deploying at volume, Genio is worth evaluating seriously.
For ProventusNova's experience with both platforms, see [our Jetson support services](/get-expert-nvidia-jetson-support) and [our Genio support services](/get-expert-mediatek-genio-support).
NVIDIA's Jetson Orin product page with full specs is at [nvidia.com/embedded](https://www.nvidia.com/en-us/autonomous-machines/embedded-systems/). MediaTek Genio platform overview is at [MediaTek's IoT developer page](https://iot.mediatek.com/genio).
---
## Choosing a GMSL2 carrier board for Jetson Orin: what to check
URL: https://proventusnova.com/blog/gmsl2-carrier-board-jetson-orin/
Published: 2026-05-06
Author: Aaron Angulo
Tags: gmsl2, carrier board, jetson orin, hardware selection, bsp
How to evaluate a GMSL2 carrier board for Jetson Orin before you buy. Port count, deserializer chipset, BSP support, and the questions most vendors don't.
Choosing a GMSL2 carrier board for Jetson Orin is not just about whether it has the right number of GMSL2 ports. The PCB routing quality, impedance control, and power delivery to the MAX9296 matter as much as the port count, and these differences only become visible during bring-up. This post covers what to check before you buy.
## Key Insights
- Deserializer chipset and port count determine maximum camera count, verify before committing to a carrier board
- BSP quality varies dramatically between vendors, a carrier board without a validated GMSL2 BSP is just hardware
- GMSL1 (MAX9286) and GMSL2 (MAX9296A/MAX96724) are different technologies with different drivers, verify which generation the board uses
- Ask vendors specifically: supported sensors, tested JetPack version, and BSP update cadence
- An integrated GMSL2 carrier board is simpler than an adapter board approach, but limits future camera flexibility
## The four things that determine carrier board fit
Choosing a GMSL2 carrier board for Jetson Orin is not just a hardware purchase. The board's BSP, the deserializer chipset, and the vendor's support posture determine whether you are buying weeks of bring-up time or months of it.
**Port count.** How many cameras do you need? MAX9296A boards support 2 GMSL2 cameras. MAX96724 boards support 4. MAX96722 supports 8 but requires a custom or vendor-provided driver. Count your cameras, add one for development flexibility, then check the board specs.
**Deserializer chipset.** NVIDIA's L4T R36 has reference drivers for MAX9296A and MAX96724 for specific configurations. If the board uses MAX96722, GMSL1 chipsets (MAX9286), or a newer Analog Devices part without L4T support, expect driver work.
**BSP quality.** A carrier board without a working GMSL2 BSP is hardware without a software stack. Ask for specifics: which sensors are supported, which JetPack version is validated, and what happens when JetPack is updated.
**Physical connector type.** GMSL2 cameras use FAKRA, Mini-FAKRA, or HSD connectors depending on the camera module. The carrier board must match your camera connector type, or you need adapters that add reliability risk.
## Established GMSL2 carrier board vendors
These vendors have documented GMSL2 support with BSPs for Jetson Orin:
| Vendor | Notable GMSL2 boards | BSP approach |
|--------|---------------------|-------------|
| Leopard Imaging | LI-Orin-GMSL2-4CAM | Bundled sensor drivers for their camera modules |
| FRAMOS | FSA-FPA series | FRAMOS camera ecosystem BSP |
| Connect Tech | Rogue, Boson carrier boards | CTI board support packages, JetPack-aligned |
| Tier IV | IE-4000 | Automotive-grade, TIER IV sensor ecosystem |
These vendors produce GMSL2 carrier boards as a core product, which means their BSPs get maintained when JetPack updates. A generic carrier board vendor who lists GMSL2 as a feature but has no camera sensor in their supported list is a different situation.
## Questions to ask before buying
**"Which specific sensors is your GMSL2 BSP validated with?"** A good answer names specific sensors (IMX390, IMX728, etc.) with JetPack version numbers. A bad answer is "any GMSL2-compatible sensor."
**"What JetPack version is your BSP currently validated on?"** If the answer is JetPack 5 and you are shipping on JetPack 6, you have a migration project built into your timeline.
**"How are BSP updates delivered when NVIDIA releases a new JetPack?"** Good vendors have a release cadence. Others ship one BSP and never update it.
**"Do you provide the device tree source for your GMSL2 configuration?"** If you need to modify the DTS (different sensor, different camera count), you need the source. Binary-only BSPs are a lock-in risk.
**"Can your driver framework support custom sensors not in your list?"** Some vendors have a plugin architecture for adding sensors. Others require full driver re-implementation.
## What to watch out for in specs
**"Supports GMSL2" without chipset detail.** Always ask which Analog Devices part is on the board. MAX9286 is GMSL1, not GMSL2. The software stack is completely different.
**Port count vs. camera count.** Some boards advertise camera count based on daisy-chaining that requires non-standard wiring. Verify whether the advertised count is direct-connect ports.
**"BSP available on request."** This usually means it exists but has not been recently validated. Ask for the JetPack version it was last tested on.
## MAX96722: the 8-port deserializer
The MAX96722 from Analog Devices supports up to 8 GMSL2 inputs on a single chip, useful for high-camera-count deployments like autonomous vehicles or multi-view inspection systems.
**What sets it apart:** Unlike MAX9296A (2-port) and MAX96724 (4-port), the MAX96722 has no reference driver in NVIDIA's L4T. NVIDIA's kernel source includes drivers for MAX9296A and MAX96724 for specific configurations; MAX96722 requires either a custom driver or a vendor-provided BSP.
**Implications for carrier board selection:** If you're evaluating a carrier board that uses MAX96722, ask the vendor:
- Do you ship a kernel driver for MAX96722?
- Which JetPack version is it validated on?
- Is the driver source available, or is it binary-only?
Boards from Tier IV and some Leopard Imaging configurations have MAX96722 BSP support. Most generic carrier board vendors don't, they may list MAX96722 as a supported chip but provide no driver.
**DTS note:** The MAX96722 connects to Jetson via multiple MIPI output ports. A full 8-camera configuration requires careful NVCSI port mapping in the device tree, 8 cameras split across multiple NVCSI ports depending on the SoC's lane count. This DTS work is more complex than a 2-port or 4-port configuration and usually requires bring-up support.
If you're selecting a carrier board with MAX96722 and need driver development or DTS configuration, [ProventusNova handles GMSL2 bring-up](/services/gmsl) including MAX96722 configurations.
For the GMSL2 bring-up process once you have your board, see [GMSL2 camera bring-up on Jetson Orin: MAX9295/MAX9296 setup](/blog/gmsl2-camera-bringup-jetson-orin-max9295-max9296). For what to expect when bringing up GMSL2 on a custom carrier board versus a devkit, see [GMSL2 cameras on a custom carrier board: what's different](/blog/gmsl2-custom-carrier-board-jetson).
Analog Devices' GMSL2 product selector for their deserializer family is at the [Analog Devices GMSL product page](https://www.analog.com/en/products/gmsl.html). NVIDIA's supported carrier board list for Jetson Orin is in the [Jetson Partner Hardware Catalog](https://developer.nvidia.com/embedded/jetson-partner-supported-cameras).
---
---
## GMSL2 multi-camera sync on Jetson Orin: FSYNC setup guide
URL: https://proventusnova.com/blog/gmsl2-multi-camera-sync-jetson/
Published: 2026-05-05
Author: Aaron Angulo
Tags: gmsl2, multi-camera, frame sync, jetson orin, trigger, synchronization
GMSL2 multi-camera frame sync for Jetson Orin: FSYNC path, virtual channel assignment, MAX96724 topology, GStreamer pipeline, and verification.
Synchronizing multiple GMSL2 cameras on Jetson requires hardware-level frame sync, software timestamp comparison introduces too much jitter for stereo or multi-view applications. The FSYNC signal travels through the GMSL2 control channel from Jetson to each camera, triggering simultaneous exposure across all sensors. This post covers the full synchronization setup, from DTS configuration to verifying sync is actually working.
## Key Insights
- Hardware frame sync via FSYNC is the only reliable way to synchronize GMSL2 cameras, software approaches drift within seconds
- The FSYNC signal travels from Jetson GPIO → MAX9296A → GMSL2 control channel → MAX9295A → camera sensor trigger input
- Virtual channel assignment is mandatory for multi-camera setups, two cameras on the same VC corrupt both streams
- The MAX96724 quad-deserializer simplifies 4-camera designs by aggregating all streams into a single MIPI output
- Frame sync failures look like intermittent frame drops or tearing, not a complete pipeline failure, harder to diagnose
## Why frame sync matters for multi-camera
If you are building a stereo, surround-view, or array camera system, unsynchronized frames are not a cosmetic problem, they cause real failures. Stereo depth estimation requires both cameras to capture the same moment in time. Surround-view stitching requires frames to align spatially. Even 10 ms of offset between cameras introduces motion artifacts that make the output unusable for most applications.
Free-running cameras, even cameras with identical settings, drift relative to each other over time because their internal oscillators have tolerance. Two cameras nominally running at 30 fps may be 16.7 ms apart (half a frame period) within a minute of start-up.
Hardware frame sync solves this by driving all cameras from a common trigger. Every camera captures on the same edge. Frame-to-frame timing error is in the microsecond range, which is acceptable for virtually any multi-camera application.
## The FSYNC signal path in GMSL2
GMSL2 provides a control channel that runs bidirectionally alongside the video data. This control channel carries I2C/UART traffic and GPIO signals between the deserializer and serializer sides.
The FSYNC path for a dual-camera GMSL2 setup on Jetson Orin:
```
Jetson GPIO (configured as PWM or GPIO output)
→ MAX9296A FSYNC pin
→ GMSL2 control channel (both links simultaneously)
→ MAX9295A FSYNC pin (link 0)
→ MAX9295A FSYNC pin (link 1)
→ Camera sensor TRIGGER/SYNC input
```
This means a single Jetson GPIO triggers all cameras simultaneously. No separate wire per camera. No cable routing changes for additional cameras.
The FSYNC GPIO is configured in the DTS and the deserializer driver forwards it automatically once the link is locked.
```dts
/* Configure FSYNC GPIO in DTS */
max9296@48 {
/* ... */
fsync-gpios = <&tegra_aon_gpio TEGRA234_AON_GPIO(BB, 1) GPIO_ACTIVE_HIGH>;
fsync-mode = "GMSL2";
fsync-period = <3300000>; /* 33ms = ~30fps FSYNC period in nanoseconds */
};
```
## Virtual channel assignment for multi-camera
The MAX9296A deserializer aggregates multiple camera streams onto a single MIPI output using MIPI CSI-2 virtual channels. Each camera gets a unique VC number.
```
Camera 0 → MAX9295A link 0 → MAX9296A → MIPI VC0 → NVCSI → V4L2 device 0
Camera 1 → MAX9295A link 1 → MAX9296A → MIPI VC1 → NVCSI → V4L2 device 1
```
The VC assignment is configured in the MAX9296A deserializer registers and must also be reflected in the DTS via `vc_id`:
```dts
/* Camera 0, Virtual Channel 0 */
imx390@1a {
sensor_modes {
mode0 {
vc_id = "0";
/* ... */
};
};
};
/* Camera 1, Virtual Channel 1 */
imx390@1b {
sensor_modes {
mode0 {
vc_id = "1";
/* ... */
};
};
};
```
If both cameras are on VC0, the NVCSI interleaves their data and both streams are corrupt. The failure looks like two unusable but active video streams, not a complete pipeline failure.
## 4-camera topology with MAX96724
For 4-camera designs on Jetson Orin, the MAX96724 quad-deserializer is the common solution. It supports 4 GMSL2 input ports and outputs 4 virtual channels over a single MIPI CSI-2 link.
```
Camera 0 → MAX9295A → MAX96724 port 0 → \
Camera 1 → MAX9295A → MAX96724 port 1 → MIPI (VC0-VC3) → Jetson NVCSI
Camera 2 → MAX9295A → MAX96724 port 2 → /
Camera 3 → MAX9295A → MAX96724 port 3 → /
```
The MAX96724 requires a different kernel driver and DTS structure than the MAX9296A. NVIDIA's reference drivers in L4T R36 include MAX96724 support for specific carrier board configurations.
## GStreamer pipeline for synchronized multi-camera capture
Once hardware sync is working, reading all streams in GStreamer uses `nvarguscamerasrc` per sensor fed into `nvstreammux`. The NVCSI hardware timestamps each frame at the moment of capture using a shared system clock, frames triggered on the same FSYNC edge arrive at the muxer with matching timestamps, so no software alignment is needed.
```bash
gst-launch-1.0 \
nvstreammux name=mux batch-size=2 width=1920 height=1080 \
batched-push-timeout=4000000 live-source=1 ! \
nvinfer config-file-path=config_infer.txt ! \
nvmultistreamtiler rows=1 columns=2 width=3840 height=1080 ! \
nvvidconv ! nv3dsink \
nvarguscamerasrc sensor-id=0 ! \
'video/x-raw(memory:NVMM),width=1920,height=1080,framerate=30/1' ! \
nvvidconv ! mux.sink_0 \
nvarguscamerasrc sensor-id=1 ! \
'video/x-raw(memory:NVMM),width=1920,height=1080,framerate=30/1' ! \
nvvidconv ! mux.sink_1
```
`live-source=1` is important, without it, `nvstreammux` may block waiting for a full batch from a slow source, which introduces artificial latency. With live sources, it pushes partial batches after `batched-push-timeout` microseconds.
For stereo depth applications, you typically want to read frames in C++ via `appsink` and process them as a pair. The key is setting `max-buffers=1` and `drop=false` on both sinks and using a mutex to collect the matching pair before dispatching to the stereo algorithm.
## How to verify frame sync is working
The most direct verification is timestamp comparison across streams:
```bash
# Run both in parallel, capture 60 frames each
v4l2-ctl --stream-mmap -d /dev/video0 --stream-count=60 \
--stream-to=/dev/null -v 2>&1 | grep "ts" > /tmp/ts0.txt &
v4l2-ctl --stream-mmap -d /dev/video1 --stream-count=60 \
--stream-to=/dev/null -v 2>&1 | grep "ts" > /tmp/ts1.txt
# Compare corresponding timestamps
paste /tmp/ts0.txt /tmp/ts1.txt
```
With hardware sync, every row should show timestamps within 1ms of each other. With free-running cameras, the delta grows over time as oscillator drift accumulates.
A second verification: probe the FSYNC pin on the serializer board with an oscilloscope while the pipeline is running. You should see a clean square wave at the configured frame rate (e.g., 30Hz = 33ms period). If the pin is static, the DTS GPIO configuration is wrong or the deserializer driver isn't forwarding the signal.
```bash
# Confirm FSYNC GPIO direction and state from software
gpioinfo | grep -A2 "BB 1"
gpioget # should toggle at frame rate if correctly configured
```
## Diagnosing sync failures
**Cameras appear to capture but timestamps diverge over time**
Hardware FSYNC is not reaching the sensors. Check that the GMSL2 link is locked (`dmesg | grep "link locked"`), then verify the FSYNC GPIO is configured as output in the DTS. Use `gpioset` to manually pulse the GPIO and confirm it toggles.
**One camera captures correctly, the other shows corrupted frames**
Virtual channel conflict. Both cameras are sharing a VC number. Check the `vc_id` values in the DTS, they must be unique per camera. Also verify the deserializer register configuration matches the DTS.
**All cameras drop frames after a few seconds of sync operation**
FSYNC period mismatch between the configured period and what the sensor expects. If the sensor expects 30fps but FSYNC is toggling at 25Hz, it will eventually lose lock. Verify `fsync-period` in nanoseconds matches the target frame rate exactly.
**`nvarguscamerasrc` fails to open sensor after adding FSYNC config**
A DTS error in the FSYNC node is preventing driver probe. Check `dmesg | grep max9296` for probe errors and compare the GPIO specifier against your carrier board schematic.
For complex GMSL2 bring-up problems, multi-camera with unusual serializer configurations, custom carrier boards, or mixed sensor arrays, the [GMSL camera driver development service](/services/gmsl) covers what a fixed-bid engagement typically involves. For the broader GMSL2 pipeline setup, see [GMSL2 camera driver on Linux: V4L2, MAX9296 kernel driver, device tree](/blog/gmsl2-camera-driver-linux-v4l2-max9296).
The MIPI CSI-2 virtual channel specification is in the [MIPI Alliance CSI-2 standard](https://www.mipi.org/specifications/csi-2). The MAX9296A FSYNC configuration registers are documented in the [Analog Devices MAX9296A datasheet](https://www.analog.com/en/products/max9296a.html).
---
## GMSL2 cameras on a custom carrier board: what's different
URL: https://proventusnova.com/blog/gmsl2-custom-carrier-board-jetson/
Published: 2026-05-02
Author: Aaron Angulo
Tags: gmsl2, custom carrier board, jetson orin, device tree, camera bring-up
GMSL2 camera bring-up on a custom Jetson carrier board differs from devkit in specific, predictable ways. I2C bus, NVCSI routing, GPIO assignments, and.
A custom carrier board adds new failure modes to GMSL2 camera bring-up that do not exist on development kits. Power sequencing, PCB impedance, and I2C address conflicts between multiple serializer instances all show up differently on custom hardware. This post covers what changes when you move from a devkit to your own board.
## Key Insights
- The devkit GMSL2 DTS is a reference, not a starting point, every GPIO, I2C bus, and NVCSI port number needs verification against your schematic
- The three most common differences between devkit and custom board: I2C bus number, NVCSI port routing, and PWDNB/ERRB GPIO assignments
- Orin NX and AGX Orin have different NVCSI port counts and different SoM pin-to-CSI lane mappings, a DTS that works on one will not work on the other without modification
- Power sequencing differences are the least visible but cause intermittent failures that look like driver bugs
- Work through the hardware mapping before touching the DTS, wrong hardware assumptions produce fixes that work once and fail randomly
## What actually changes on a custom carrier board
When NVIDIA's reference GMSL2 setup works on the devkit and fails on a custom carrier board, the failure is almost always in one of four areas. None of them are driver bugs, they are hardware mapping differences between the devkit and your board.
**I2C bus number.** The MAX9296A deserializer connects to one of the Jetson's I2C controllers. The devkit may use I2C3; your board may use I2C1 or I2C6. The DTS parent node for the MAX9296A must match the correct controller.
**NVCSI port routing.** The MIPI D-PHY lanes from the MAX9296A connect to specific SoM pins. Those pins belong to a specific NVCSI port. The DTS must declare the correct port number. Wrong port: zero frames, no error message.
**GPIO pin assignments.** PWDNB (power-down bar), ERRB (error bar), and camera power enable GPIOs all land on different GPIO pins on custom boards. The DTS GPIO references must match your schematic.
**Power sequencing.** The devkit powers camera regulators through its PMIC with a specific sequence. Custom boards may power the same rails through a different path or without the same sequencing guarantees.
## Building your hardware mapping before touching the DTS
Before writing a single line of DTS, build this hardware map from your schematic:
```
MAX9296A VDD → from which regulator/rail on carrier board?
MAX9296A VDDIO → same question
MAX9296A PWDNB → which Jetson SoM GPIO pin?
MAX9296A ERRB → which Jetson SoM GPIO pin?
MAX9296A I2C SDA → which SoM connector pin? → which I2C controller?
MAX9296A I2C SCL → same
MAX9296A MIPI_A D0+/D0- → which SoM connector pins? → which NVCSI port/lane?
MAX9296A MIPI_A D1+/D1- → same
MAX9296A MIPI_A CLK+/CLK- → same
```
Once you have this mapping, the DTS changes are mechanical, substitute the correct bus number, pin number, and port number into the devkit DTS template.
## Adapting the devkit DTS
The key substitutions:
```dts
/* DEVKIT, uses I2C3 on i2c@3180000 */
&i2c3 {
max9296@48 {
reset-gpios = <&tegra_main_gpio TEGRA234_MAIN_GPIO(H, 3) GPIO_ACTIVE_LOW>;
/* ... */
};
};
/* YOUR CUSTOM BOARD, uses I2C1 on i2c@3160000, different GPIO */
&i2c1 {
max9296@48 {
reset-gpios = <&tegra_main_gpio TEGRA234_MAIN_GPIO(Q, 5) GPIO_ACTIVE_LOW>;
/* ... */
};
};
```
For the NVCSI port:
```dts
/* DEVKIT, NVCSI port 0 */
nvcsi_in0: endpoint@0 {
remote-endpoint = <&max9296_csi_out0>;
data-lanes = <0 1 2 3>;
};
/* YOUR CUSTOM BOARD, NVCSI port 2 (if MIPI lanes route there) */
nvcsi_in2: endpoint@2 {
remote-endpoint = <&max9296_csi_out0>;
data-lanes = <0 1 2 3>;
};
```
The NVCSI port number determines where `csi-port` is set in the tegra-camera-platform module entry. Both the NVCSI binding and the module entry must use the same port number.
## Orin NX vs AGX Orin differences
If you are porting a GMSL2 setup from AGX Orin to Orin NX, these specific differences matter:
| Property | AGX Orin | Orin NX |
|----------|---------|---------|
| NVCSI ports | 6 | 4 |
| Maximum MIPI lanes | 12 | 8 |
| Camera I2C controllers | I2C3, I2C6, I2C8 | I2C1, I2C3 (fewer) |
| SoM connector CSI pin mapping | Different | Different |
An AGX Orin DTS that uses NVCSI port 4 or 5 will not work on Orin NX (which only has ports 0–3). The camera I2C bus that was I2C8 on AGX Orin may be on I2C3 on Orin NX. Both need to be re-mapped.
For debugging GMSL2 failures after DTS adaptation, see [GMSL2 camera not working on Jetson: 5 failure modes](/blog/gmsl2-camera-not-working-jetson). For the complete devkit bring-up sequence to verify your DTS before customizing, see [GMSL2 camera bring-up on Jetson Orin: MAX9295/MAX9296 setup](/blog/gmsl2-camera-bringup-jetson-orin-max9295-max9296).
The Jetson Orin NX module datasheet with connector pin assignments is available on the [NVIDIA Jetson download center](https://developer.nvidia.com/embedded/downloads). The Orin TRM with NVCSI port-to-pin mapping is in the same location under Tegra234 Technical Reference Manual.
---
---
## GMSL2 sensor driver code for Jetson: tegra-camera-platform
URL: https://proventusnova.com/blog/gmsl2-custom-camera-driver-jetson/
Published: 2026-05-01
Author: Andres Campos
Tags: gmsl2, camera driver, v4l2, kernel driver, jetson orin, max9296, subdev
Write the sensor-side driver for a GMSL2 camera on Jetson: tegra_cam_platform_sensor_ops in C, DTS mode table math, exposure/gain controls, debugging.
This is the implementation post: the actual C code for the sensor-side driver of a GMSL2 camera on Jetson. It covers the `tegra_cam_platform_sensor_ops` table, the DTS sensor mode table and its timing math, and the V4L2 exposure/gain controls Argus needs for auto-exposure. If you are still bringing up the SerDes link itself, start with [GMSL2 camera bring-up on Jetson Orin](/blog/gmsl2-camera-bringup-jetson-orin-max9295-max9296); for the kernel driver stack and device tree chain, see [GMSL2 camera driver on Linux](/blog/gmsl2-camera-driver-linux-v4l2-max9296). This post assumes the link locks and the I2C tunnel works, from here on it's sensor driver code.
## Key Insights
- Custom GMSL2 sensor drivers for Jetson use the tegra-camera-platform framework, not raw V4L2 subdev ops
- You almost never write SerDes drivers from scratch, the MAX9295A/MAX9296A drivers already exist in L4T
- The sensor mode table in the DTS is as important as the driver code, wrong mode table means wrong MIPI timing
- The minimum viable driver is: power on/off, one hard-coded mode, streaming start/stop
- Test the SerDes chain first with an existing reference sensor before swapping in your custom sensor
## What "custom GMSL2 driver" actually means
When teams say they need to write a custom GMSL2 driver, they usually mean one of three things:
1. **A new sensor driver** for a camera sensor that NVIDIA does not have in L4T (non-reference IMX variant, custom ISP, OmniVision sensor not in NVIDIA's supported list)
2. **A modified SerDes driver** because their hardware uses a different register initialization sequence than NVIDIA's reference design
3. **A combined driver** for a vertically integrated camera module where sensor and serializer are a single unit
In most cases it is option 1. The MAX9295A and MAX9296A drivers that NVIDIA ships in L4T handle the SerDes side correctly for standard configurations. The custom work is the sensor driver, the code that programs the specific image sensor registers, manages the sensor power sequence, and describes the sensor's operating modes.
## The tegra-camera-platform sensor driver framework
Jetson sensor drivers do not implement raw V4L2 subdev ops. They implement `tegra_cam_platform_sensor_ops` which wraps V4L2 and adds Jetson-specific extensions.
The minimum required ops:
```c
static struct tegra_cam_platform_sensor_ops sensor_ops = {
.numfmts = ARRAY_SIZE(sensor_fmts),
.fmts = sensor_fmts,
.numframerates = ARRAY_SIZE(sensor_framerates),
.framerates = sensor_framerates,
.s_power = sensor_s_power,
.s_stream = sensor_s_stream,
.g_frame_interval = sensor_g_frame_interval,
.s_frame_interval = sensor_s_frame_interval,
.set_mode = sensor_set_mode,
.g_sensor_mode_id = sensor_g_mode_id,
};
```
The framework calls `set_mode` before `s_stream`. Your `set_mode` implementation writes the sensor register table for the selected mode. Your `s_stream` implementation sends the streaming enable/disable command to the sensor.
## The sensor mode table
The mode table is where MIPI timing is defined. It lives in the device tree, not in the driver code. The framework reads it during probe and makes it available through V4L2 controls.
```dts
sensor_modes {
mode0 { /* 1920x1080 @ 30fps, 4-lane MIPI */
mclk_khz = "37125";
num_lanes = "4";
tegra_sinterface = "serial_a";
vc_id = "0";
discontinuous_clk = "no";
dpcm_enable = "false";
cil_settletime = "0";
active_w = "1920";
active_h = "1080";
mode_type = "bayer";
pixel_phase = "rggb";
csi_pixel_bit_depth = "12";
readout_orientation = "0";
line_length = "2200";
inherent_gain = "1";
mclk_multiplier = "20.25";
pix_clk_hz = "750750000";
min_gain_val = "1";
max_gain_val = "16";
min_hdr_ratio = "1";
max_hdr_ratio = "64";
min_framerate = "1.462151";
max_framerate = "30";
min_exp_time = "13";
max_exp_time = "683709";
embedded_metadata_height = "1";
};
};
```
Getting the `pix_clk_hz`, `line_length`, and `mclk_multiplier` values wrong produces subtle failures, the sensor streams but at the wrong frame rate, or the MIPI timing is slightly off causing intermittent `uncorr_err`. Cross-reference these values against your sensor's datasheet register tables for the specific operating mode.
## The sensor driver structure
A minimal custom sensor driver for a GMSL2 camera:
```c
static int sensor_s_power(struct v4l2_subdev *sd, int on)
{
struct camera_common_data *s_data = to_camera_common_data(sd->dev);
/* Toggle VDD, VDDIO, VANA rails via regulator API */
/* Toggle XCLR (reset) GPIO */
/* Wait for PLL lock time (check datasheet, typically 1-5ms) */
return 0;
}
static int sensor_set_mode(struct v4l2_subdev *sd, u32 val)
{
/* Write register table for mode 'val' */
/* Tables are typically in a separate sensor_regs.h file */
/* Each entry: {address, value} pairs in 16-bit or 8-bit format */
return sensor_write_table(sd, sensor_mode_table[val]);
}
static int sensor_s_stream(struct v4l2_subdev *sd, int enable)
{
if (enable)
return sensor_write_reg(sd, SENSOR_STREAM_ENABLE_REG, 0x01);
else
return sensor_write_reg(sd, SENSOR_STREAM_ENABLE_REG, 0x00);
}
```
The register tables are typically long arrays of address/value pairs derived directly from the sensor vendor's initialization script. For IMX sensors, Sony publishes these through their partner portal. For OmniVision sensors, they are in the OV design guide.
## Testing before full implementation
Start with the minimum viable driver: power on, hard-code a single mode, send the streaming enable register. Do not worry about V4L2 controls (gain, exposure) until you have frames.
Test progression:
1. Sensor probes (`dmesg | grep sensor_name` shows probe success)
2. `i2cdetect` on the camera bus shows the sensor address
3. `v4l2-ctl --list-devices` shows the camera entry
4. `nvarguscamerasrc sensor-id=0 ! fakesink` exits without error
5. `nvarguscamerasrc sensor-id=0 ! nvvidconv ! xvimagesink` produces visible frames
If step 4 passes but step 5 shows a green or purple frame, the pixel format or Bayer pattern in the mode table is wrong, not a driver bug.
## Adding V4L2 controls for exposure and gain
Argus uses V4L2 controls to read and write exposure and gain during auto-exposure operation. Without these controls, Argus falls back to fixed values and AE does not converge.
```c
static int sensor_s_ctrl(struct v4l2_ctrl *ctrl)
{
struct sensor_priv *priv = container_of(ctrl->handler,
struct sensor_priv, ctrl_handler);
switch (ctrl->id) {
case V4L2_CID_EXPOSURE:
/* Convert microseconds to sensor line count */
/* line_time_us = line_length / pix_clk_hz * 1e6 */
return sensor_set_exposure_lines(priv->client,
ctrl->val / priv->line_time_us);
case V4L2_CID_ANALOGUE_GAIN:
/* Convert V4L2 gain value to sensor's dB or linear register format */
return sensor_set_gain_reg(priv->client, ctrl->val);
}
return -EINVAL;
}
static int sensor_ctrls_init(struct sensor_priv *priv)
{
struct v4l2_ctrl_handler *hdl = &priv->ctrl_handler;
v4l2_ctrl_handler_init(hdl, 4);
priv->exposure = v4l2_ctrl_new_std(hdl, &sensor_ctrl_ops,
V4L2_CID_EXPOSURE, SENSOR_MIN_EXP_US, SENSOR_MAX_EXP_US,
1, SENSOR_DEFAULT_EXP_US);
priv->gain = v4l2_ctrl_new_std(hdl, &sensor_ctrl_ops,
V4L2_CID_ANALOGUE_GAIN, SENSOR_MIN_GAIN, SENSOR_MAX_GAIN,
1, SENSOR_DEFAULT_GAIN);
return hdl->error;
}
```
Get `SENSOR_MIN_EXP_US` and `SENSOR_MAX_EXP_US` from the datasheet's exposure register description. The min is typically determined by sensor readout constraints (cannot be less than one line time); the max is one frame period minus a few lines of blanking.
## Driver-level troubleshooting
The failures below are the ones your driver code causes. If the sensor never appears on `i2cdetect` at all, that is a link-lock or address-reassignment problem, a SerDes-chain issue, not a driver bug: work through the [bring-up diagnostic sequence](/blog/gmsl2-camera-bringup-jetson-orin-max9295-max9296) first.
**Driver probes but `v4l2-ctl --list-devices` shows no camera**
The tegra-camera-platform module entry is missing or the `proc-device-tree` path in the DTS is wrong. Verify by checking `/proc/device-tree/i2c@*/max9296*/` to confirm the sensor node exists at the exact path your DTS module definition declares.
**Streaming starts but frames are all black**
The sensor's streaming enable register wrote correctly, but the analog section didn't initialize. Check that your register table includes the full sensor startup sequence, not just the streaming enable. Some sensors require a specific sequence: standby → load mode registers → enable analog path → enable digital path → enable output. Missing the analog enable step produces black frames.
**Green or purple frames**
Wrong Bayer pattern. The `pixel_phase` in the mode table (`rggb`, `bggr`, `grbg`, `gbrg`) doesn't match the sensor's actual Bayer output for this mode. Check the sensor datasheet for the pixel array layout. Also check `readout_orientation`, a 180° rotation also inverts the Bayer phase.
**Mode table validation: the pix_clk_hz and link_freq_hz math**
If frames arrive but `nvcsi` logs `uncorr_err`, your mode table timing does not match what the sensor's PLL actually outputs. Recalculate from the register table you loaded in `set_mode`: `pix_clk_hz = line_length × (active_h + vblank) × fps`. If `link_freq_hz` is set separately, it must equal half the physical MIPI bit rate per lane: `link_freq_hz = (pix_clk_hz × bit_depth) / (2 × num_lanes)`. Every mode in the table needs this validated against the datasheet, this is a driver/mode-table bug, not a hardware one.
For custom GMSL2 driver development on unusual sensors or non-standard serializer configurations, the [GMSL camera driver development service](/services/gmsl) covers scoped engagements. For the supporting infrastructure these drivers rely on, see [GMSL2 camera driver on Linux: V4L2, MAX9296 kernel driver, device tree](/blog/gmsl2-camera-driver-linux-v4l2-max9296). For debugging the GMSL2 chain before writing your sensor driver, see [GMSL2 camera bring-up on Jetson Orin](/blog/gmsl2-camera-bringup-jetson-orin-max9295-max9296).
NVIDIA's sensor driver framework documentation is in the [Jetson Linux Sensor Driver Programming Guide](https://docs.nvidia.com/jetson/archives/r36.4.3/DeveloperGuide/SD/CameraApplicationDevelopment/SensorDriverProgrammingGuide.html). Reference sensor drivers (IMX390, IMX219) are in the L4T kernel source at `kernel/nvidia/drivers/media/i2c/`.
---
---
## GMSL2 camera driver on Linux: V4L2, MAX9296 kernel driver, device tree
URL: https://proventusnova.com/blog/gmsl2-camera-driver-linux-v4l2-max9296/
Published: 2026-04-30
Author: Aaron Angulo
Tags: gmsl2, linux driver, v4l2, v4l2 tutorial, max9296, kernel driver, device tree, jetson
V4L2 camera driver tutorial: GMSL2 setup on Linux for Jetson. MAX9296A kernel driver, subdev chain, device tree structure, and common probe failures.
The GMSL2 camera driver stack on Linux involves multiple kernel drivers working in coordination, the MAX9296 deserializer driver, the serializer driver, and the sensor driver, with the V4L2 subdev framework tying them together. Understanding where each piece lives and how they communicate is the prerequisite for debugging when any part of it fails. This post covers the full driver architecture.
## Key Insights
- A GMSL2 camera driver on Linux is a chain of V4L2 subdevs: sensor → serializer → deserializer → NVCSI → VI
- NVIDIA provides reference drivers for specific module/sensor combinations, everything else needs custom work
- Probe success on the deserializer does not mean the V4L2 video node exists, that depends on the VI driver linking correctly
- `media-ctl -p` is the fastest way to see the full pipeline state and identify broken links
- The DTS must describe every node in the chain with correct compatible strings, I2C addresses, and port linkages
## What a V4L2 camera driver tutorial needs to cover
Every V4L2 camera driver on Jetson, whatever the physical link, GMSL2, direct MIPI CSI, FPD-Link, comes down to the same five things going right in order: the physical link has to come up, every subdev in the chain has to probe, the media graph has to link end to end, a `/dev/videoN` node has to appear, and a real frame has to come out of it. Almost every driver bring-up problem is a failure at one of those five steps, not a mystery bug.
This post walks that exact sequence for a real system, a GMSL2 camera on Jetson using the MAX9295A serializer and MAX9296A deserializer, because a specific system is what shows real commands and real device tree, not generic advice that does not transfer to your dmesg output. If your hardware uses a different physical link, direct CSI with no SerDes, or a different SerDes pair, the five-step sequence and every debugging command past step 1 is the same. Only the physical-link-verification step changes.
## The V4L2 subdev chain for GMSL2
A GMSL2 camera on Jetson is not a single driver, it is a chain of V4L2 subdevices that must all probe successfully and link together before any capture is possible.
The chain, from camera to memory:
```
IMX390 (sensor subdev)
→ MAX9295A (serializer subdev)
→ MAX9296A (deserializer subdev)
→ NVCSI (CSI receiver subdev)
→ VI (Video Input capture node → /dev/videoN)
```
Each component is a separate Linux kernel driver. Each must probe successfully. Each must be linked to the next in the V4L2 media graph. If any link is broken, wrong DTS, wrong compatible string, missing regulator, the entire chain fails and no video node appears.
```bash
# View the media controller pipeline
sudo media-ctl -p
# Output shows all entities and their link state:
# - pad links between sensor, serializer, deserializer, NVCSI, VI
# - enabled (=>) vs disabled (->) links
# All links from sensor to VI must be enabled for capture to work
```
## The kernel drivers involved
Each component in the chain has a corresponding kernel driver:
| Component | Driver location | Compatible string |
|-----------|----------------|-------------------|
| IMX390 sensor | `drivers/media/i2c/imx390.c` | `"sony,imx390"` |
| MAX9295A serializer | `drivers/media/i2c/max9295.c` | `"maxim,max9295"` |
| MAX9296A deserializer | `drivers/media/i2c/max9296.c` | `"maxim,max9296"` |
| NVCSI | `drivers/media/platform/tegra/camera/vi/channel.c` | Tegra-internal |
| VI | `drivers/media/platform/tegra/camera/vi/` | Tegra-internal |
NVIDIA ships these drivers in the L4T kernel source for reference sensor combinations. For a custom sensor (not IMX390), you need to either port an existing driver or write a new one using the tegra-camera-platform sensor driver framework.
The NVCSI and VI drivers are Tegra-internal and are not modified for custom cameras, they are configured through the device tree and through V4L2 controls.
## Device tree structure
The DTS for a GMSL2 setup declares every node in the chain. The NVCSI port binding connects the deserializer output to the Jetson capture hardware.
```dts
/* Binding the deserializer output to NVCSI port 0 */
nvcsi@15a00000 {
num-lanes = <4>;
ports {
port@0 {
reg = <0>;
nvcsi_in0: endpoint@0 {
remote-endpoint = <&max9296_csi_out0>;
data-lanes = <0 1 2 3>;
};
};
};
};
```
The `remote-endpoint` reference ties the deserializer output port to the NVCSI input port. Both sides must declare the same endpoint with reciprocal `remote-endpoint` references, if one side references a node that does not exist or has a typo in the label, the media controller cannot build the graph and the VI node does not appear.
## Diagnosing probe failures
Work through this sequence when the driver fails to probe:
```bash
# 1. Check which drivers probed
sudo dmesg | grep -E "max929[56]|imx390|nvcsi|tegra-vi"
# 2. Check for deferred probe (dependency not ready)
sudo dmesg | grep "probe deferred"
# Common causes: GPIO not ready, regulator not ready, clock not ready
# 3. Check I2C bus accessibility
sudo i2cdetect -y 3 # Replace 3 with your camera I2C bus
# Should show 0x48 (MAX9296A), 0x40 (MAX9295A), sensor address
# 4. Check media graph
sudo media-ctl -p 2>/dev/null | head -60
# Verify all entities are present and links are correct
# 5. Check V4L2 devices
v4l2-ctl --list-devices
# Should show sensor entries if VI linked correctly
```
A common failure pattern: `max9296 probe success` in dmesg, but `/dev/video0` does not exist. This means the MAX9296A driver probed but the VI driver could not link to the NVCSI. The fix is almost always a DTS error in the NVCSI port binding or the tegra-camera-platform `drivernode` entry.
## How to verify GMSL2 link lock on Jetson
Before the kernel driver can probe the sensor, the GMSL2 physical link between serializer and deserializer must be established. No link = no I2C tunnel = sensor probe deferred or failed. This step is often skipped in debugging, leading to time wasted on DTS changes that cannot fix a physical link problem.
Verify link lock by reading the MAX9296A status register directly over I2C:
```bash
# Replace 3 with your camera I2C bus number
sudo i2cget -y 3 0x48 0x13
```
| Value | Meaning |
|---|---|
| `0x00` | No lock, link not established |
| `0x01` | LOCK bit set, physical layer locked, video not yet detected |
| `0x09` | LOCK + VIDEO_LOCK, full link established, video flowing |
| `0x0D` | LOCK + VIDEO_LOCK + additional flags, normal operating state |
If `i2cget` returns `0x00` or hangs (no ACK from address 0x48):
1. **Check cable continuity**: the GMSL2 coax must be intact and properly terminated. Use a multimeter on the center conductor.
2. **Check serializer power**: the camera module VDD must be active before the GMSL2 link can establish. Verify your carrier board enables camera power before the kernel driver loads.
3. **Check cable length**: MAX9296A at 6 Gbps is specified for up to 15m. Longer cables require switching to 3 Gbps mode (set in the serializer GMSL2 rate register).
4. **Try a shorter cable**: cable impedance mismatch is a common issue on prototype boards; a known-good short cable isolates whether the problem is cable or hardware.
Only proceed to DTS and driver debugging once `i2cget 0x48 0x13` returns a non-zero value showing link lock.
## Common DTS errors that break probe
These are the DTS mistakes we see most often:
**Wrong `compatible` string.** The compatible string must exactly match the driver's `of_device_id` table. `"maxim,max9296"` (not `"max9296"`, not `"maxim,max9296a"`).
**Wrong I2C bus.** The DTS node parent must be the correct I2C controller node. On Orin, camera I2C is typically on `i2c@3180000` or `i2c@31c0000`, check the Orin TRM for which controller maps to your carrier board's camera I2C pins.
**Wrong `drivernode` `devname`.** The tegra-camera-platform `devname` field must exactly match the I2C device name format: `"imx390 3-001a"` where `3` is the I2C bus number and `001a` is the address in 4-digit hex.
**Missing `nvidia,gmsl-dser-device` phandle.** The serializer DTS node must reference the deserializer via this property so the driver knows which deserializer manages the I2C tunnel for this link.
For the full GMSL2 bring-up sequence, see [GMSL2 camera bring-up on Jetson Orin: MAX9295/MAX9296 setup](/blog/gmsl2-camera-bringup-jetson-orin-max9295-max9296). For writing a custom driver on top of this infrastructure, see [Writing a custom GMSL2 camera driver for Jetson](/blog/gmsl2-custom-camera-driver-jetson). If you also need a custom V4L2 driver for the sensor itself, [how to write a custom V4L2 camera driver for Jetson Orin](/blog/custom-v4l2-camera-driver-jetson-orin) covers the full kernel driver implementation.
NVIDIA's Sensor Driver Programming Guide covering the V4L2 subdev framework for Jetson is in the [Jetson Linux Developer Guide](https://docs.nvidia.com/jetson/archives/r36.4.3/DeveloperGuide/SD/CameraApplicationDevelopment/SensorDriverProgrammingGuide.html). The Linux media controller API documentation is at [kernel.org](https://www.kernel.org/doc/html/latest/userspace-api/media/mediactl/media-controller.html).
## GMSL1 vs GMSL2: which should you use for a new design?
| | GMSL1 | GMSL2 |
|---|---|---|
| Max link speed | 3.12 Gbps | 6 Gbps |
| Max camera resolution | ~3 MP at 30fps | ~8 MP at 30fps |
| Typical cable length | Up to 15m | Up to 15m at 6 Gbps |
| Reverse channel (control) | Yes (slower) | Yes (higher bandwidth) |
| I2C tunnel | Yes | Yes, plus SPI |
| GPIO forwarding | Limited | Full GPIO forwarding |
| Reference design | MAX96705 + MAX9296 | MAX9295A + MAX9296A |
| NVIDIA reference driver | L4T GMSL1 drivers | L4T GMSL2 drivers (IMX390) |
For any new design, use GMSL2. The serializer/deserializer ecosystem is fully on GMSL2, NVIDIA's reference drivers target GMSL2, and the resolution headroom handles current and next-generation sensors.
GMSL1 is appropriate only if you are maintaining an existing system with GMSL1 cameras already in production.
## MAX9295A vs MAX96705: serializer selection guide
These two serializers appear in many Jetson camera designs and are frequently confused:
| | MAX9295A | MAX96705 |
|---|---|---|
| Protocol | GMSL2 | GMSL1 |
| Link speed | Up to 6 Gbps | 3.12 Gbps |
| Paired deserializer | MAX9296A | MAX9296 or MAX96712 |
| I2C tunnel | Yes | Yes |
| SPI tunnel | Yes | No |
| GPIO channels | 6 bidirectional | 2 |
| Package | 40-pin WLCSP | 32-pin TQFN |
| NVIDIA L4T reference | Yes (with IMX390) | Older L4T versions only |
If you are starting a new design or driver project, choose MAX9295A + MAX9296A. NVIDIA's L4T source includes reference drivers for this pair, and it is the combination covered by NVIDIA's GMSL2 driver framework.
If you are working with an existing system using MAX96705, the bring-up process is similar but the L4T reference drivers target the GMSL2 pair. You will be adapting the GMSL1 driver structure, which is documented in older L4T kernel trees.
## From zero to first frame: GMSL2 bring-up sequence
The fastest path to a first captured frame on a new GMSL2 setup:
1. **Power on and verify GMSL2 link lock**: `i2cget -y 0x48 0x13` must return non-zero
2. **Check I2C tunnel**: `i2cdetect -y ` should show the serializer address (0x40) and sensor address tunneled through the deserializer
3. **Boot with NVIDIA reference DTS**: use the L4T reference DTS for MAX9295A/MAX9296A as a starting point
4. **Verify all subdevs probe**: `dmesg | grep -E "max929[56]|imx390|nvcsi"` should show probe success for each
5. **Check media graph**: `media-ctl -p` should show all entities linked from sensor to VI
6. **Verify V4L2 node**: `v4l2-ctl --list-devices` should show the sensor
7. **Capture a test frame**: `v4l2-ctl --stream-mmap -d /dev/video0 --count=1`
8. **Decode and view**: pipe the raw frame through ffmpeg or use v4l2-ctl `--save-frames` to verify image content
If step 4 fails (subdev probe error), the problem is DTS or power. If step 5 fails (media graph incomplete), the problem is the NVCSI port binding in DTS. If step 6 fails (no V4L2 node), the VI driver could not link, check for VI-side errors in dmesg.
---
---
## GMSL2 camera not working on Jetson: 5 failure modes
URL: https://proventusnova.com/blog/gmsl2-camera-not-working-jetson/
Published: 2026-04-29
Author: Andres Campos
Tags: gmsl2, jetson, camera debugging, max9296, max9295, troubleshooting
GMSL2 camera not working on Jetson Orin? These 5 failure modes cover link lock failure, I2C tunnel issues, MIPI misconfiguration, address conflicts, and.
A GMSL2 camera that is not producing frames on Jetson fails in a small number of specific ways, and each failure mode has a distinct signature in the kernel logs and at the hardware level. The problem is that several different failure modes produce similar symptoms on the surface. This post covers the five most common root causes and how to tell them apart.
## Key Insights
- GMSL2 failures on Jetson fall into 5 distinct modes, each has a different root cause and a different fix
- Link lock failure is always the first thing to rule out; nothing else works until the link is established
- I2C address conflicts on multi-camera designs are silent, no error message, just wrong register writes
- `uncorr_err` from the NVCSI with a locked GMSL2 link means MIPI parameter mismatch, not a hardware fault
- Custom carrier boards break devkit GMSL2 setups in specific, predictable ways: wrong I2C bus, wrong GPIO, wrong NVCSI port
## Failure mode 1: link never locks
Link lock is the foundation. If the MAX9296A and MAX9295A cannot complete physical link training, nothing else, I2C tunnel, sensor initialization, MIPI output, will work.
Read register 0x0013 on the MAX9296A after at least 200 ms of power-on. Bit 3 should be 1. If it is 0, the link is not locked.
Root causes:
- **MAX9295A serializer not powered.** Check the VDD rail on the camera board. The serializer needs stable power before link training starts.
- **Wrong termination resistor.** The coaxial cable needs a 100-ohm termination at each end. Wrong value (or missing resistor) prevents the differential signal from settling correctly.
- **PWDNB not asserted on MAX9296A.** If the deserializer is in power-down, it does not attempt link training. Verify the PWDNB pin is driven high (or pulled high).
- **Damaged cable or connector.** A cold solder joint on the SMA or FAKRA connector, or a kinked coax, is enough to prevent lock at 3 Gbps.
```bash
# Check link lock register
sudo i2cget -y 0x48 0x13
# Expected: 0x09 (LOCK bit set) or similar, bit 3 = 1
```
## Failure mode 2: I2C address conflicts on multi-camera designs
All MAX9295A serializers power up at the same default I2C address (0x40). When multiple cameras are connected to one deserializer, the host cannot talk to each one individually until addresses are reassigned.
If the reassignment sequence fails, or if the kernel driver has wrong default addresses in the DTS, all I2C writes go to the wrong chip. The result: sensors appear to initialize but are never actually configured. Frames either do not start or come out with incorrect format or color.
The correct sequence for a two-camera setup:
1. Disable link 1 (talk to link 0 only through the deserializer's link-specific I2C address)
2. Reassign link 0 serializer from 0x40 to 0x42
3. Enable link 1, disable link 0
4. Reassign link 1 serializer from 0x40 to 0x44
5. Now both serializers are at unique addresses and can be configured independently
This sequence is handled by the GMSL2 deserializer kernel driver if the DTS specifies the target addresses correctly. Verify your DTS has the right address assignments in the serializer child nodes.
## Failure mode 3: MIPI lane count or data rate mismatch
With the link locked and sensors initialized, the MAX9296A's MIPI output must be configured to exactly match what the Jetson NVCSI expects. The critical parameters are:
- **Number of data lanes**, if the DTS says 4 lanes but the deserializer is configured for 2, every frame is corrupt
- **Link frequency**, must match the sensor's actual output rate, which the deserializer is forwarding
- **Virtual channel assignment**, each camera in a multi-sensor setup must be on a unique virtual channel
A mismatch produces `uncorr_err` from `tegra-camrtc-capture-vi` in dmesg. The link is locked, the sensor is streaming, but the NVCSI sees garbage.
```bash
# Check for uncorr_err
sudo dmesg | grep -E "uncorr_err|tegra-camrtc"
# Verify MIPI link frequency in device tree matches sensor mode
cat /proc/device-tree/i2c@31c0000/max9296@48/max9295@40/imx390@1a/sensor_modes/mode0/link_freq_hz
```
For more on `uncorr_err` from the NVCSI in general, see [V4L2 uncorr_err on Jetson: what it means and how to fix it](/blog/v4l2-uncorr-err-jetson-csi-camera-fix).
## Failure mode 4: wrong NVCSI port in device tree
On custom carrier boards, the GMSL2 deserializer's MIPI output lanes are often routed to a different NVCSI port than on the devkit. The device tree must reflect the actual PCB routing, if the DTS says NVCSI port 0 but the lanes are physically connected to port 2, the capture engine arms the wrong port and produces zero frames.
Trace the MIPI lanes from the MAX9296A MIPI output pads to the Jetson SoM connector pins. Cross-reference the SoM pin assignments with the Orin TRM to determine which NVCSI port those pins belong to. Then update the DTS.
This failure is silent, no error message in dmesg, just zero frames and a timeout in the capture path.
## Failure mode 5: ERRB pin not handled
The MAX9296A and MAX9295A have an ERRB pin that asserts (active-low) when the chip detects a link error, parity error, or internal fault. If this pin is connected to a Jetson GPIO that is configured as an interrupt, the kernel driver uses it for error detection. If the GPIO is tristated or configured incorrectly in the DTS, ERRB errors are silently ignored.
On custom carrier boards, the ERRB routing is sometimes left unconnected or pulled to the wrong level. Check your schematic for the ERRB signal path, and verify the GPIO configuration in the DTS matches the physical connection.
For the complete GMSL2 bring-up sequence, see [GMSL2 camera bring-up on Jetson Orin: MAX9295/MAX9296 setup](/blog/gmsl2-camera-bringup-jetson-orin-max9295-max9296). If your symptoms point specifically to a custom carrier board, see [GMSL2 cameras on a custom carrier board: what's different from the devkit](/blog/gmsl2-custom-carrier-board-jetson).
The MAX9296A error register map is in the [Analog Devices MAX9296A datasheet](https://www.analog.com/en/products/max9296a.html). NVIDIA's camera bring-up troubleshooting guidance is in the [Jetson Linux Sensor Driver Programming Guide](https://docs.nvidia.com/jetson/archives/r36.4.3/DeveloperGuide/SD/CameraApplicationDevelopment/SensorDriverProgrammingGuide.html).
---
---
## GMSL2 camera bring-up on Jetson Orin: MAX9295/MAX9296 setup
URL: https://proventusnova.com/blog/gmsl2-camera-bringup-jetson-orin-max9295-max9296/
Published: 2026-04-28
Author: Aaron Angulo
Tags: gmsl2, jetson orin, max9295, max9296, camera bring-up, device tree
Step-by-step GMSL2 camera bring-up on Jetson Orin with MAX9295A and MAX9296A. Link lock, I2C tunnel, device tree, and first frame verification.
Bringing up a GMSL2 camera on Jetson Orin for the first time is a multi-step process that requires getting both hardware initialization and the software stack right before a single frame appears. The MAX9295 serializer and MAX9296 deserializer need to establish a link, the virtual channels need to be configured, and the V4L2 driver stack needs to see the sensor correctly. This post covers the full first-time setup sequence.
## Key Insights
- GMSL2 bring-up has a fixed sequence: power → link lock → I2C tunnel → address reassignment → MIPI config → first frame
- Skip any step and the next one will fail with a misleading error
- The Jetson NVCSI is downstream of the deserializer, treat it exactly like a direct-attach CSI camera once the SerDes is configured
- NVIDIA provides reference bring-up scripts for devkit combinations; custom carrier boards need DTS modifications before any of those scripts work
- `dmesg | grep -i max929` and `dmesg | grep -i nvcsi` in sequence tells you exactly which layer is failing
## The bring-up sequence, in order
GMSL2 camera bring-up on Jetson Orin is a fixed six-step sequence. Every step depends on the previous one completing successfully. The most common mistake is jumping ahead, testing MIPI output before confirming I2C tunnel, for example, and then spending hours debugging the wrong layer.
**Step 1: Power.** The MAX9296A deserializer needs stable VDD (1.8V) and VDDIO (1.8V or 3.3V) before anything else. The PWDNB pin must be driven high (or pulled high) to bring the chip out of power-down mode. On the camera side, the MAX9295A serializer needs its own VDD from the carrier board or from the camera module.
**Step 2: Link lock.** Once both chips are powered, the link training starts automatically. The MAX9296A drives the lock signal on the coax; the MAX9295A responds. This takes 5–50 ms. Read register 0x0013 on the MAX9296A, bit 3 should be 1. If it is not, link lock has failed and nothing downstream will work.
**Step 3: I2C tunnel.** With the link locked, the I2C tunnel is active. The deserializer forwards I2C transactions from the host to the serializer side. Verify by running `i2cdetect` on the camera I2C bus, you should see the MAX9295A at 0x40 and the sensor at its default address.
**Step 4: Address reassignment.** For multi-camera designs, each MAX9295A must be assigned a unique I2C address before individual sensor access is possible. This is done sequentially: enable link 0 only, reassign its serializer address, disable link 0, enable link 1, reassign, and so on. The kernel driver handles this if the DTS is correct.
**Step 5: Sensor initialization.** With unique addresses assigned, write the sensor initialization register sequence. For IMX390 or similar, this means writing the full register table for the desired resolution and frame rate mode.
**Step 6: MIPI output.** Configure the MAX9296A's MIPI output (lane count, data rate, virtual channel mapping) to match what the Jetson NVCSI expects. This is done by the kernel driver based on the DTS configuration. Once set, the deserializer starts forwarding frames to the NVCSI.
## Device tree requirements for Jetson Orin
The DTS for a GMSL2 camera on Jetson Orin has a specific structure. The NVCSI node references the deserializer output port, and the deserializer node contains the serializer and sensor as child nodes.
```dts
/* tegra234-camera-gmsl2-imx390.dts */
#include
#include
/ {
tegra-camera-platform {
compatible = "nvidia, tegra-camera-platform";
modules {
module0 {
badge = "imx390_gmsl2";
position = "front";
orientation = "1";
drivernode0 {
pcl_id = "v4l2_sensor";
devname = "imx390 2-001a";
proc-device-tree = "/proc/device-tree/i2c@31c0000/max9296@48/max9295@40/imx390@1a";
};
drivernode1 {
pcl_id = "v4l2_lens";
};
};
};
};
};
&i2c3 {
max9296@48 {
compatible = "maxim,max9296";
reg = <0x48>;
csi-mode = "2x4";
max-src = <2>;
reset-gpios = <&tegra_aon_gpio TEGRA234_AON_GPIO(AA, 0) GPIO_ACTIVE_LOW>;
ports {
port@0 {
reg = <0>;
max9296_gmsl0_in0: endpoint@0 {
remote-endpoint = <&max9295_gmsl0_out0>;
link-frequency = /bits/ 64 <1500000000>;
};
};
port@1 {
reg = <1>;
max9296_csi_out0: endpoint {
remote-endpoint = <&nvcsi_in0>;
data-lanes = <1 2 3 4>;
};
};
};
max9295@40 {
compatible = "maxim,max9295";
reg = <0x40>;
nvidia,gmsl-dser-device = <&max9296>;
port@0 {
reg = <0>;
max9295_gmsl0_out0: endpoint {
remote-endpoint = <&max9296_gmsl0_in0>;
};
};
imx390@1a {
compatible = "sony,imx390";
reg = <0x1a>;
sensor_model = "imx390";
physical_w = "5.37";
physical_h = "3.02";
sensor_modes {
mode0 {
num_lanes = "4";
mclk_khz = "37125";
pix_clk_hz = "594000000";
link_freq_hz = "1500000000";
csi_pixel_bit_depth = "12";
active_w = "1920";
active_h = "1080";
framerate = "30000";
};
};
};
};
};
};
```
## Diagnostic sequence
When GMSL2 bring-up fails, work through these checks in order rather than jumping to MIPI debugging:
```bash
# 1. Check link lock
sudo i2cget -y 3 0x48 0x13 # MAX9296A register 0x0013
# Bit 3 = 1 → locked, 0 → not locked
# 2. Check I2C tunnel, scan for devices on camera I2C bus
sudo i2cdetect -y 3
# Should show 0x40 (MAX9295A) and 0x1a (IMX390 or your sensor)
# 3. Check kernel driver probe
sudo dmesg | grep -i "max929\|gmsl"
# Should show probe success messages
# 4. Check NVCSI
sudo dmesg | grep -i nvcsi
# Should show no errors
# 5. Test capture
gst-launch-1.0 nvarguscamerasrc sensor-id=0 ! \
'video/x-raw(memory:NVMM),width=1920,height=1080' ! \
nvvidconv ! xvimagesink -e
```
If step 1 fails, the problem is power or cable. If step 2 fails with the link locked, the I2C tunnel is misconfigured. If step 3 shows probe failure, the device tree is wrong. If step 4 shows `uncorr_err`, the MIPI lane count or data rate is mismatched.
## Common GMSL2 bring-up errors
**`max9296 probe failed` in dmesg**
The deserializer driver can't reach the chip. Check that VDD is stable, PWDNB is high, and the I2C bus number in the DTS matches the actual bus the chip is wired to. Confirm with `i2cdetect -y ` before touching the DTS.
**`max9295 probe failed` / no devices on camera I2C bus**
Link lock hasn't been established. The I2C tunnel only operates over a locked GMSL2 link. Go back to step 1, read register 0x0013 on the MAX9296A and confirm bit 3 is set.
**`uncorr_err` in nvcsi or camrtc-capture-vi logs**
MIPI data rate or lane count mismatch. The MAX9296A's MIPI output is configured for a different data rate or number of lanes than the Jetson NVCSI expects. Check `link_freq_hz` in the sensor DTS node against the MAX9296A register configuration. Also verify `data-lanes` count in the deserializer output port matches the physical lane count from the serializer.
**`nvarguscamerasrc no cameras available` after driver probe succeeds**
The sensor driver loaded but the libargus camera stack can't enumerate the sensor. This is usually a `tegra-camera-platform` DTS node issue, a missing or incorrectly named `proc-device-tree` path in the module definition. Check that the path points to the actual sensor node location in `/proc/device-tree/`.
**Frames arrive for 5–10 seconds then drop to zero**
GMSL2 link instability, usually from a marginal cable or connector. The link re-trains after a momentary error, causing a brief capture gap that looks like a pipeline stall. Check the cable for damage, reduce cable length if possible, and verify the MAX9296A's equalization settings match the cable characteristics. ECC error counts in the MAX9296A registers will increase steadily before the link drops.
## Custom carrier board vs devkit bring-up
Bring-up on a custom carrier board is materially different from bring-up on an NVIDIA devkit. On the devkit, NVIDIA provides tested overlays for supported camera modules, bring-up is applying the right overlay and running a validation script.
On a custom carrier board, you need to write the full DTS from scratch. The key differences:
| | Devkit | Custom carrier board |
|--|--------|----------------------|
| DTS | Apply NVIDIA overlay | Write from scratch |
| I2C bus | Fixed (documented) | Depends on your schematic |
| PWDNB / reset GPIO | Pre-wired | Must match your schematic |
| NVCSI port routing | Fixed in NVIDIA DTS | Depends on PCB layout |
| MIPI lane assignment | Documented by NVIDIA | Depends on trace routing |
The most common mistakes on custom boards: using the devkit GPIO numbers for PWDNB and reset (they're different), using the wrong I2C bus number, and mismatching NVCSI port to physical MIPI lanes. All of these fail silently at different stages of the bring-up sequence.
If you're bringing up GMSL2 on a custom carrier board and hitting the link lock stage reliably but failing at NVCSI or V4L2, the [GMSL camera driver development service](/services/gmsl) covers what a scoped engagement for this kind of problem looks like.
For the GMSL2 SerDes architecture overview, see [GMSL2 SerDes explained: MAX9295 and MAX9296 for Jetson bring-up](/blog/gmsl2-serdes-max9295-max9296-jetson). If you are bringing up GMSL2 on a custom carrier board instead of a devkit, see [GMSL2 cameras on a custom carrier board: what's different from the devkit](/blog/gmsl2-custom-carrier-board-jetson). If the sensor requires a custom kernel driver, see [how to write a custom V4L2 camera driver for Jetson Orin](/blog/custom-v4l2-camera-driver-jetson-orin).
The MAX9296A datasheet with full register maps is available on the [Analog Devices product page](https://www.analog.com/en/products/max9296a.html). NVIDIA's Jetson Linux Developer Guide covers the tegra-camera-platform DTS structure in the [Sensor Driver Programming Guide](https://docs.nvidia.com/jetson/archives/r36.4.3/DeveloperGuide/SD/CameraApplicationDevelopment/SensorDriverProgrammingGuide.html).
---
---
## GMSL2 SerDes explained: MAX9295 and MAX9296 for Jetson bring-up
URL: https://proventusnova.com/blog/gmsl2-serdes-max9295-max9296-jetson/
Published: 2026-04-25
Author: Aaron Angulo
Tags: gmsl2, serdes, max9295, max9296, jetson, camera driver
GMSL2 SerDes on Jetson: MAX9295A/MAX9296A quick reference (I2C addresses, link speeds), lock sequence, tunneling, and device tree setup.
The MAX9295A serializer and MAX9296A deserializer are the transport layer between a GMSL2 camera sensor and Jetson, and understanding what they do and how they fail is the foundation for any GMSL2 bring-up work. Most GMSL2 debugging sessions turn out to be SerDes configuration issues rather than sensor or Jetson problems. This post covers how the SerDes pair works.
## Key Insights
- GMSL2 SerDes is a two-chip pipeline: MAX9295A serializer on the camera, MAX9296A deserializer on the host/carrier board
- The link must lock before any I2C communication with the camera sensor is possible, link lock is step zero
- I2C tunneling over the GMSL2 link means one coaxial cable carries both video and camera control traffic
- The deserializer's output to the Jetson SoC is MIPI CSI-2, the rest of the capture pipeline is standard
- Most bring-up failures happen at link lock or I2C address reassignment, not at the MIPI layer
- NVIDIA provides reference drivers for specific module/carrier combinations only, custom hardware needs custom driver work
## MAX9295A / MAX9296A quick reference
| | MAX9295A (serializer) | MAX9296A (deserializer) |
|---|---|---|
| Role | Camera side | Host/carrier board side |
| Default I2C address | `0x40` | `0x48` |
| Link speed | 3 Gbps or 6 Gbps per channel | 3 Gbps or 6 Gbps per channel |
| Max cable run | 15 m at 3 Gbps | 15 m at 3 Gbps |
| Output interface | GMSL2 (coax or STP) | MIPI CSI-2 to host SoC |
| Link lock indicator | N/A (responds to deserializer) | `LOCK` bit, register `0x0013` bit 3 |
| Control channel | I2C/UART tunneled over GMSL2 | I2C tunnel endpoint, transparent to host |
Both default I2C addresses are set by strap pins at power-on and must be reassigned per-serializer when more than one camera shares a deserializer, see the address reassignment step below.
## What GMSL2 actually is
GMSL2 (Gigabit Multimedia Serial Link 2) is a serialization standard from Maxim Integrated (now Analog Devices) that transmits high-speed video, control data, and power over a single coaxial cable or shielded twisted pair. It operates at 3 Gbps or 6 Gbps per channel and supports cable runs of 15 meters at 3 Gbps, which is why it is the standard interface for automotive cameras and anything where the camera needs to be physically separated from the compute unit.
On Jetson, GMSL2 is almost always implemented with two chips: the MAX9295A serializer on the camera board and the MAX9296A deserializer on the carrier board. Some designs use the MAX96717 (serializer) or MAX96724 (quad deserializer) for different port counts, but the bring-up process is the same.
The signal path looks like this:
```
Camera sensor → MIPI CSI-2 → MAX9295A → GMSL2 link (coax) → MAX9296A → MIPI CSI-2 → Jetson NVCSI → VI → V4L2
```
From the Jetson's perspective, the deserializer looks like any other MIPI CSI-2 source. The GMSL2 complexity is entirely on the serializer/deserializer side. If the SerDes is configured correctly, the rest of the Jetson camera pipeline behaves identically to a direct-attach CSI camera.
## The link lock sequence
The link lock sequence is the first thing that has to work, and it is the most common point of failure. Nothing else matters until the GMSL2 link is established.
1. **Power up the serializer side.** The MAX9295A needs VDD (1.8V or 3.3V depending on variant) and its MIPI clock from the camera sensor or an external oscillator.
2. **The deserializer initiates link training.** The MAX9296A drives a lock signal on the coaxial cable. The MAX9295A responds. This exchange happens automatically at power-on, no software involvement.
3. **Link lock is established.** The MAX9296A LOCK bit (register 0x0013, bit 3) goes high. This takes 5–50 ms depending on cable length and electrical conditions.
4. **I2C tunnel becomes active.** Once locked, the deserializer's I2C bus extends transparently to the serializer side. The host can now reach the MAX9295A and the camera sensor registers over I2C.
5. **Address reassignment.** If multiple cameras share one deserializer, each serializer must be reassigned to a unique I2C address before any sensor register access begins. This is done by communicating with each serializer one at a time through the deserializer's per-link I2C gateway.
If the link never locks, you cannot proceed. Every subsequent step depends on it.
```bash
# Check link lock status on a running Jetson with working driver
sudo i2cget -y 0x48 0x0013 # Read MAX9296A register 0x0013
# Bit 3 = 1 means link locked
```
## Why the I2C tunnel matters
The I2C tunnel is what makes GMSL2 practical for embedded systems. Without it, you would need a separate control wire from the host to each camera, defeating much of the purpose of a serialized link.
Through the tunnel, the Jetson can:
- Write initialization sequences to the camera sensor (IMX, OV, Sony)
- Read sensor status and configuration registers
- Control the MAX9295A serializer registers (crossbar, output format, sync signals)
The tunnel operates at standard I2C speeds (100 kHz, 400 kHz). It is transparent to Linux I2C drivers, the sensor appears as a normal I2C device on the I2C bus once the link is locked and the deserializer is configured to forward addresses.
One practical consequence: if the GMSL2 link is not locked, `i2cdetect` on the bus will show nothing. Engineers sometimes interpret this as a dead sensor, when the actual problem is link lock. The sensor is fine, it is just unreachable until the link is established.
## Device tree structure on Jetson
The device tree for a GMSL2 camera on Jetson has three layers: the deserializer node, the serializer node (as a child), and the camera sensor node (as a child of the serializer).
```dts
&i2c_cam {
/* MAX9296A deserializer */
max9296@48 {
compatible = "maxim,max9296";
reg = <0x48>;
reset-gpios = <&gpio TEGRA234_MAIN_GPIO(H, 3) GPIO_ACTIVE_LOW>;
ports {
port@0 {
max9296_out0: endpoint {
remote-endpoint = <&nvcsi_in0>;
data-lanes = <1 2 3 4>;
};
};
};
/* MAX9295A serializer, reached via I2C tunnel */
max9295@40 {
compatible = "maxim,max9295";
reg = <0x40>;
/* Camera sensor, reached via serializer I2C tunnel */
imx390@1a {
compatible = "sony,imx390";
reg = <0x1a>;
/* sensor configuration */
};
};
};
};
```
The NVCSI node references the deserializer output as its source. The capture pipeline is then identical to any other CSI camera from the Jetson's perspective.
## Most common bring-up failures
We have brought up GMSL2 cameras on Jetson Orin, AGX Xavier, and Orin NX across multiple custom carrier boards. The failures cluster into three areas:
**Link never locks.** Usually power or termination. The MAX9295A's VDD must be within spec and stable before the link training can complete. The coaxial cable's termination resistor (typically 100 ohm) must match the PCB design. A cold or intermittent solder joint on the coax connector is enough to prevent lock.
**I2C address conflict.** When multiple cameras are connected, all serializers start at the same default I2C address (0x40). Before the deserializer can address each one individually, you have to enable each link's pipe independently, reassign the serializer address, then enable the next. Getting the reassignment sequence wrong means I2C writes collide and both serializers end up in an undefined state.
**MIPI output misconfiguration.** The deserializer's MIPI output lane count, data rate, and format must match exactly what the NVCSI expects in the device tree. A mismatch here produces `uncorr_err` from the NVCSI, the link is locked, I2C works, but frames are corrupt or absent. Check that `data-lanes` in the DTS matches the physical lane count routed from the deserializer to the SoM.
For carrier board-specific GMSL2 bring-up issues, see [GMSL2 cameras on a custom carrier board: what's different from the devkit](/blog/gmsl2-custom-carrier-board-jetson). For the full camera diagnostic stack on Jetson, see [5 signs your GMSL2 camera integration will miss your milestone](/blog/gmsl2-camera-integration-jetson-warning-signs).
GMSL2 and the MAX9295A/MAX9296A register maps are documented in the [Analog Devices MAX9296A datasheet](https://www.analog.com/en/products/max9296a.html). The GMSL2 protocol specification is available through the [Analog Devices partner portal](https://www.analog.com/en/products/gmsl.html).
---
---
## 5 Signs Your GMSL2 Camera Integration on Jetson Will Miss Your Milestone
URL: https://proventusnova.com/blog/gmsl2-camera-integration-jetson-warning-signs/
Published: 2026-04-24
Author: Aaron Angulo
Tags: gmsl2, camera integration, jetson, v4l2, edgeai
GMSL2 camera integration on Jetson stalling? Five warning signs -- link lock, frame drops, V4L2 errors, latency, multi-camera failures -- with root causes.
GMSL2 camera integration on Jetson breaks in specific ways. The link locks. The V4L2 device appears. And then the integration stalls -- frames aren't arriving, or they're arriving intermittently, or they work for one camera but not two, or the latency is higher than expected without an obvious explanation in the pipeline metrics.
Each of these symptoms has a specific root cause. The challenge is that GMSL2 failures at the link and data layer aren't loudly reported by the kernel. The failures are quiet. You're looking for configuration mismatches across multiple ICs -- the sensor, the serializer, the deserializer, the V4L2 driver -- that only become visible when you know where to check.
These are the five warning signs that a GMSL2 camera integration is off track, what each one means, and where to look.
**Key Insights**
1. **GMSL2 link lock and frame delivery are independent.** A locked link means the physical layer is up. It says nothing about whether the data layer is configured correctly. Frames can fail to arrive even with a locked link, and this is one of the most common GMSL2 integration failures.
2. **Most GMSL2 integration failures are register configuration mismatches, not hardware problems.** Pixel format mismatch, lane count mismatch, I2C address conflict, channel ID collision -- these are all configuration issues that don't produce hardware errors. They produce silence or bad frames.
3. **Multi-camera failures are almost always I2C address or channel assignment problems.** A single-camera integration that works perfectly will fail when a second camera is added if the serializer I2C addresses or GMSL2 channel IDs aren't unique. This is a device tree problem, not a hardware problem.
4. **GMSL2 latency issues that aren't visible in GStreamer metrics are upstream.** If V4L2 timestamps show frames arriving later than expected, the latency is in the GMSL2 or V4L2 layer, not in GStreamer. GStreamer only sees frames after they've crossed the V4L2 boundary.
5. **Checking in the wrong layer wastes weeks.** GMSL2 integration debugging is most efficient when you work layer-by-layer: link lock, then data configuration, then V4L2 format, then GStreamer. Jumping to GStreamer when the problem is in the serializer register config is two weeks of debugging the wrong thing.
## Sign 1: The GMSL2 link locks but no frames arrive at V4L2
This is the most common GMSL2 integration failure, and the most deceptive. The deserializer shows link status as locked. The V4L2 device node appears. `v4l2-ctl --list-devices` shows your camera. But `v4l2-ctl --stream-mmap` produces nothing, or produces an immediate error.
**What it means:** The physical link between serializer and deserializer is established, but the video data pipeline is misconfigured. The most common mismatches:
- **Pixel clock mismatch.** The PIXEL_CLK setting on the serializer doesn't match what the deserializer expects. The data is being clocked at the wrong rate and the deserializer can't reconstruct frames.
- **CSI lane count mismatch.** The serializer is configured to output on 2 CSI lanes and the V4L2 driver expects 4, or vice versa. Data arrives but the lane alignment is wrong.
- **Embedded data header conflict.** Some sensors output embedded statistics lines at the start of each frame. If the V4L2 driver isn't configured to handle embedded data and the serializer is sending it, the driver loses frame sync on the first line.
**Where to check:** Read the MAX9296 deserializer registers over I2C and compare the pixel clock, lane count, and embedded data settings against the serializer (MAX96717 or MAX96705) configuration. These need to match. Also compare both against the V4L2 driver configuration in the device tree -- the `data-lanes` property and the media bus format need to reflect the actual pipeline.
## Sign 2: Frame drops appear under load, especially with multiple cameras
Single-camera operation works. Add a second camera, increase the frame rate, or add inference to the pipeline and frames start dropping. `dmesg` shows errors during drop events but they're not consistent.
**What it means:** Two likely causes depending on where the drops occur.
If `dmesg` shows `NVCSI: ERR_STATUS0: ERR_PIXEL_SHORT_LINE` or similar CSI errors, the Jetson CSI receiver is seeing malformed frames. This usually indicates a GMSL2 packet timing issue on the serializer side -- the serializer is not holding inter-line timing correctly, especially under thermal or electrical load.
If `dmesg` shows CSI overflow errors or V4L2 buffer underruns, the CSI bandwidth is saturating. The aggregate frame rate across all cameras exceeds what the CSI lanes allocated to your camera group can carry.
**Where to check:** For serializer timing issues, read the frame sync error register on the MAX9296 (register 0x0B) during a drop event. A non-zero value confirms the deserializer is losing frame sync from the serializer -- a serializer-side timing problem. For bandwidth saturation, calculate the aggregate CSI bandwidth for your camera configuration (frame rate × resolution × bit depth × cameras) and compare against the CSI lane bandwidth for your Jetson module and lane assignment.
## Sign 3: VIDIOC_S_FMT returns EINVAL
`v4l2-ctl` or your application calls VIDIOC_S_FMT with the expected format and gets EINVAL back. The format negotiation is failing before a single frame is captured.
**What it means:** The V4L2 driver rejected the requested format because it doesn't match what the driver actually supports. This is almost always a mismatch between what the application is requesting and what the sensor driver exposes. It happens most frequently after a kernel or driver update that changes the supported format list without updating the application.
**Where to check:** Run `v4l2-ctl --list-formats-ext` on the camera device node to see exactly what formats and frame sizes the driver exposes. Compare this to what your application or pipeline is requesting. The requested format needs to match exactly -- format code, width, height, and in some cases stride.
For GMSL2 cameras, also check the `bus-type` and `mbus-fmt` properties in the device tree sensor node. The V4L2 driver derives its format list from these properties. A device tree that specifies `MEDIA_BUS_FMT_SBGGR12_1X12` but an application requesting `MEDIA_BUS_FMT_SBGGR10_1X10` will produce EINVAL.
## Sign 4: Latency is higher than expected and GStreamer metrics don't explain it
Your GStreamer pipeline is configured for low latency. The element metrics look right. But end-to-end latency is higher than the pipeline graph would predict, and you can't find the delay in GStreamer.
**What it means:** The latency is upstream of GStreamer -- in the GMSL2 link layer or in the V4L2 buffer handoff. GStreamer only timestamps frames when they cross the V4L2 buffer boundary. If the GMSL2 serializer is introducing latency (for example, due to long inter-frame gaps in the GMSL2 packet stream) or if V4L2 buffer allocation is causing frames to queue, the delay is invisible to GStreamer's element-level metrics.
**Where to check:** Use `v4l2-ctl --stream-mmap --stream-count=100` with timestamp output to measure when frames arrive at the V4L2 layer. Compare the V4L2 timestamps against the expected frame interval based on your configured frame rate. If frames are arriving late at V4L2 -- before GStreamer has seen them -- the delay is in the GMSL2 or V4L2 layer.
For serializer-side latency, check the GMSL2 packet configuration on the MAX9296. The `GMSL2_VIDEO_PACKET_SIZE` setting affects how the deserializer batches data before presenting it to the CSI interface. Larger packet sizes reduce CSI overhead but add serialization latency before the first byte of a frame is available.
## Sign 5: Camera 0 works but camera 1 or camera 2 fails
You integrate the first camera and it works. You add the second camera using the same device tree structure -- duplicating the node with different address assignments -- and the second camera fails to initialize, produces corrupted frames, or causes the first camera to stop working.
**What it means:** Almost always an I2C address conflict or GMSL2 channel ID collision. Multiple GMSL2 cameras on the same bus require:
- **Unique serializer I2C addresses.** The GMSL2 protocol uses I2C address translation to allow the deserializer to address each serializer individually. If two serializers start with the same default I2C address and the device tree doesn't include an address translation sequence for each, they conflict when addressed simultaneously.
- **Unique GMSL2 channel IDs.** Each serializer needs an assigned GMSL2 channel ID that the deserializer uses to route video streams. If two serializers have the same channel ID, the deserializer can't distinguish their streams.
**Where to check:** Open the device tree and look at the `i2c-alias` or address translation properties for each serializer node. Every serializer needs a unique translated address. Then check the GMSL2 channel assignment -- this is sometimes in the device tree, sometimes in board-specific initialization code. Run `i2cdetect` during boot to verify that each serializer appears at the expected translated address, not at the default address.
If both cameras appear at the same I2C address, the translation table is wrong or missing. Correct the device tree address translation for each serializer and verify each one appears at a unique address after the deserializer initialization sequence runs.
## What to do when you're past the five signs
The five signs above cover the failure modes we see most often in GMSL2 camera integration on Jetson. They're all configuration issues that don't require hardware changes to fix.
The failure modes that fall outside these five -- frame corruption from signal integrity problems on the coaxial cable, sensor-specific initialization sequences not matching the driver, GMSL2 firmware version mismatches between serializer and deserializer -- are less common and require hardware-level debugging: cable measurement, oscilloscope work on the coaxial link, and serializer firmware version verification.
If you're past the five configuration signs and the integration still isn't delivering frames, the problem is in one of those hardware-level categories and the diagnostic path is different.
---
---
## Jetson multi-camera sync: CSI hardware trigger setup
URL: https://proventusnova.com/blog/multi-camera-sync-jetson-csi/
Published: 2026-04-23
Author: Andres Campos
Tags: jetson, multi-camera, csi, frame sync, trigger, synchronization, v4l2
Synchronize multiple CSI cameras on Jetson with hardware trigger sync. FRSYNC GPIO, DTS config, sensor trigger mode, GStreamer pipeline, and verification.
Running multiple CSI cameras on Jetson simultaneously is straightforward, the hardware supports it natively. Synchronizing them so frames align within a millisecond requires hardware trigger synchronization. Software timestamp comparison introduces too much jitter for stereo vision or surround-view applications. This post covers the full synchronization setup.
## Key Insights
- Hardware trigger sync is the only reliable method for multi-camera synchronization on Jetson, software sync has too much jitter for stereo or surround-view
- The sync signal comes from a Jetson GPIO (or external source) to each sensor's trigger input, not from Jetson to the NVCSI
- Both sensors must be in external trigger mode, not free-running, or trigger sync does not override the internal frame timer
- NVCSI captures multiple streams in parallel by hardware, the synchronization problem is at the sensor output, not at capture
- A consistent frame offset (not jitter) points to trigger edge polarity mismatch, not a timing problem
## Why free-running sync fails
The most common multi-camera "synchronization" approach is running both cameras at the same frame rate setting and timestamping frames as they arrive. This fails for any application requiring real synchronization.
Here is why: camera sensors use internal oscillators to time their frame rate. These oscillators have frequency tolerance, typically ±100-300 ppm for a standard crystal. Two cameras at 30 fps nominal might run at 30.002 fps and 29.998 fps. That 4 ms/second drift means the cameras are a full frame apart within 4 seconds of running. For stereo depth estimation, this is completely unacceptable.
Software timestamp comparison is also unreliable. The timestamp is applied when the frame arrives at the V4L2 buffer, which depends on interrupt latency and task scheduling. Jitter of 5–30 ms is typical.
Hardware trigger sync solves both problems by forcing every camera to expose on a common hardware edge. The sensors do not free-run, they wait for the trigger pulse.
## Hardware trigger sync vs software sync vs GMSL2 FSYNC: which to use?
The right synchronization method depends on your camera interface and how many cameras you need to synchronize.
| Method | Sync accuracy | Max cameras | Cable requirement | When to use |
|---|---|---|---|---|
| **Hardware GPIO trigger** (CSI cameras) | <1 ms | 4–6 (GPIO fanout limit) | Dedicated trigger wire to each sensor | 2–4 CSI cameras on a single carrier board |
| **Software timestamping** | 5–30 ms jitter | Unlimited | None | Never, only acceptable for non-synchronized logging |
| **GMSL2 FSYNC** | <1 ms | 8+ per deserializer | Existing GMSL2 coax | 4+ cameras, especially over distance |
| **NVCSI FRSYNC** | <1 ms | 2 per port pair | Board routing only | Specific Orin port pairs that share FRSYNC |
For most stereo vision and surround-view applications on Jetson with CSI cameras, hardware GPIO trigger is the right choice. It requires a trigger wire from one Jetson GPIO to each sensor's trigger input pin, which is typically 4–6 connections on a well-designed carrier board.
For GMSL2 cameras, FSYNC over the coax is the standard approach. The MAX9296A deserializer generates the FSYNC pulse; no additional wiring is needed beyond the GMSL2 cable already present.
Software timestamping is not a synchronization method, it is a measurement of when frames arrived, which is different from when they were captured. For any application where inter-camera alignment matters (stereo depth, surround view, multi-sensor fusion), software timestamps are inadequate.
## Hardware trigger sync setup
The physical connection: a Jetson GPIO drives a sync pulse to the trigger input of each sensor. For CSI cameras, this is usually a direct GPIO connection via the carrier board.
```
Jetson GPIO (e.g., TEGRA234_AON_GPIO(BB, 2))
├── Sensor 0 trigger input (e.g., XVS or TRIGGER pin)
└── Sensor 1 trigger input
```
The GPIO is configured as a PWM output at the target frame rate (33.33 ms period for 30 fps), or driven manually for triggered-on-demand capture.
In the sensor driver, switch the sensor from free-running to external trigger mode:
```c
/* Put sensor in external trigger mode */
static int sensor_set_trigger_mode(struct camera_common_data *s_data)
{
/* Register address and value depend on your sensor */
/* For IMX477: write to trigger mode register */
return sensor_write_reg(s_data->client,
SENSOR_TRIGGER_MODE_REG,
SENSOR_TRIGGER_EXTERNAL);
}
```
In the DTS, declare the sync GPIO:
```dts
imx477@10 {
/* ... */
trigger-gpios = <&tegra_aon_gpio TEGRA234_AON_GPIO(BB, 2) GPIO_ACTIVE_HIGH>;
nvidia,trigger-mode = "external";
};
imx477@11 {
/* ... same GPIO reference ... */
trigger-gpios = <&tegra_aon_gpio TEGRA234_AON_GPIO(BB, 2) GPIO_ACTIVE_HIGH>;
nvidia,trigger-mode = "external";
};
```
Both sensors reference the same GPIO. When the GPIO fires, both sensors expose simultaneously.
## Multi-camera pipeline on Jetson
With synchronized sensors, the Jetson pipeline handles multiple streams in hardware in parallel:
```
Sensor 0 → NVCSI port 0 → VI → /dev/video0
Sensor 1 → NVCSI port 1 → VI → /dev/video1
```
The VI captures both streams independently. In a GStreamer pipeline, both streams can run concurrently within a single process (avoid separate processes, see [nvvidconv performance collapse with multiple GStreamer processes on Jetson](/blog/nvvidconv-performance-multiple-gstreamer-processes)):
```bash
gst-launch-1.0 \
nvarguscamerasrc sensor-id=0 ! \
'video/x-raw(memory:NVMM),width=1920,height=1080' ! \
queue ! comp.sink_0 \
nvarguscamerasrc sensor-id=1 ! \
'video/x-raw(memory:NVMM),width=1920,height=1080' ! \
queue ! comp.sink_1 \
nvmultistreamtiler name=comp rows=1 columns=2 \
width=3840 height=1080 ! \
nvvidconv ! nvoverlaysink
```
The `queue` elements decouple the two sensor pipelines so a slow frame from one sensor does not stall the other.
## Verifying synchronization
After enabling hardware trigger sync, verify that frames from both sensors arrive within the expected window:
```bash
# Capture frames with timestamps from both sensors simultaneously
v4l2-ctl --stream-mmap -d /dev/video0 --count=10 -v 2>&1 | grep "ts:" > /tmp/cam0_ts.txt &
v4l2-ctl --stream-mmap -d /dev/video1 --count=10 -v 2>&1 | grep "ts:" > /tmp/cam1_ts.txt &
wait
# Compare timestamps
paste /tmp/cam0_ts.txt /tmp/cam1_ts.txt
# Hardware sync: timestamps should differ by < 1ms per frame
# Software sync / no sync: timestamps drift several ms per frame
```
## What synchronization accuracy does hardware trigger achieve?
With hardware trigger sync correctly configured, frame capture timestamps from two CSI cameras on the same Jetson should differ by less than 1 millisecond. In practice, on Orin with correctly configured sensors, we measure deltas of 100–400 microseconds between corresponding frames.
Example `v4l2-ctl` timestamp output from a synchronized stereo pair (Jetson AGX Orin, 30fps, IMX477 sensors):
```
cam0: ts: 1.234567890 cam1: ts: 1.234568102 delta: 212 µs
cam0: ts: 1.267901234 cam1: ts: 1.267901456 delta: 222 µs
cam0: ts: 1.301234567 cam1: ts: 1.301234789 delta: 222 µs
cam0: ts: 1.334567890 cam1: ts: 1.334568101 delta: 211 µs
```
The delta is stable across frames, this is what correctly working hardware trigger sync looks like. The residual 200-µs offset is from fixed PCB routing delay differences between the two trigger paths, not from timing jitter.
For comparison, the same cameras running free (software timestamps only):
```
cam0: ts: 1.234567890 cam1: ts: 1.239123456 delta: 4.555 ms
cam0: ts: 1.267901234 cam1: ts: 1.274123456 delta: 6.222 ms
cam0: ts: 1.301234567 cam1: ts: 1.309876543 delta: 8.641 ms ← drifting
cam0: ts: 1.334567890 cam1: ts: 1.345012345 delta: 10.444 ms
```
The free-running cameras drift apart at roughly 4 ms/second due to crystal oscillator tolerance mismatch. At 10 seconds, the cameras are a full frame apart. Hardware trigger prevents this entirely.
For stereo depth estimation, a >1 ms delta between corresponding frames creates depth errors proportional to the object's velocity. At 60 km/h (16.7 m/s), 1 ms of desync introduces ~17 mm of depth error per meter of distance, acceptable for many applications. At 10 ms desync (typical software sync), that error grows to 167 mm/m, which breaks most stereo depth algorithms.
## Generating the trigger pulse from Jetson
The trigger GPIO needs to toggle at exactly your target frame rate. The simplest approach on Jetson is a userspace PWM loop using `/sys/class/gpio`:
```bash
# Export GPIO (find your GPIO chip and line number for TEGRA234_AON_GPIO(BB, 2))
echo 502 > /sys/class/gpio/export
echo out > /sys/class/gpio/gpio502/direction
# Toggle at 30Hz in a shell loop (for testing only, use a real-time thread for production)
while true; do
echo 1 > /sys/class/gpio/gpio502/value
sleep 0.016
echo 0 > /sys/class/gpio/gpio502/value
sleep 0.017
done
```
For production, use the Tegra PWM controller or a kernel thread with `SCHED_FIFO` priority. A userspace loop with standard `sleep` has ±2 ms jitter under load, which is acceptable for most applications but insufficient for precision strobe timing.
Alternatively, use `gpioset` from the `libgpiod` package for cleaner GPIO control:
```bash
# Pulse the GPIO once (for on-demand triggered capture)
gpioset --mode=time --usec=500 $(gpiodetect | grep tegra | head -1 | awk '{print $1}') 502=1
```
## Diagnosing synchronization failures
**Timestamps diverge after a few seconds**
External trigger mode is not active on one or both sensors. The sensor is free-running and ignoring the GPIO. Check that the trigger mode register write succeeded during driver probe, look for errors in `dmesg | grep -i "trigger\|imx"`. Also verify the GPIO is actually toggling: `gpioget ` while the pipeline is running.
**Consistent 1–2 frame offset between cameras**
Trigger edge polarity mismatch. One sensor triggers on rising edge, the other on falling. Check the trigger mode register in each sensor's driver, both must use the same edge. On IMX sensors, the trigger edge is set in the XTRIG_TRIG_SEL register.
**Both cameras capture but one shows a black frame every N frames**
The trigger period is slightly mismatched to one sensor's internal line time. The sensor is completing its readout from the previous frame when the next trigger arrives and drops it. Fix: increase the trigger period slightly (reduce frame rate by 0.5 fps) to give the sensor's readout time more margin.
**`nvarguscamerasrc` opens both sensors but only one produces frames**
Both sensors are on the same NVCSI port or the DTS maps them to conflicting resources. Check the DTS sensor node port assignments, each sensor must map to a unique NVCSI port. Review `dmesg | grep nvcsi` for port conflict errors.
For custom carrier board multi-camera designs or complex synchronization requirements, the [Jetson camera bring-up service](/services/gmsl) covers fixed-bid engagements. For GMSL2 multi-camera synchronization which uses the FSYNC signal over the GMSL2 control channel instead of a direct GPIO, see [GMSL2 multi-camera sync on Jetson Orin](/blog/gmsl2-multi-camera-sync-jetson).
The Linux V4L2 timestamp documentation is at [kernel.org](https://www.kernel.org/doc/html/latest/userspace-api/media/v4l/vidioc-qbuf.html). NVIDIA's multi-camera pipeline guidance is in the [Jetson Linux Accelerated GStreamer User Guide](https://docs.nvidia.com/jetson/archives/r36.4.3/DeveloperGuide/SD/Multimedia/AcceleratedGstreamer.html).
---
## How to write a V4L2 MIPI camera driver for Jetson
URL: https://proventusnova.com/blog/custom-v4l2-camera-driver-jetson-orin/
Published: 2026-04-22
Author: Andres Campos
Tags: v4l2, camera driver, jetson orin, kernel driver, csi camera, tegra-camera-platform
Step-by-step guide to writing a custom V4L2 MIPI camera driver for NVIDIA Jetson using the tegra-camera-platform framework. Sensor ops, mode tables, DTS.
Writing a V4L2 camera driver for Jetson Orin is a real project: kernel module, V4L2 subdev, sensor init sequence, and DTS integration, each a potential blocker on its own. Most engineers hit the same four or five failure points on the first attempt. This post covers the complete driver structure and what to do when it stops working.
## How to write a V4L2 MIPI camera driver for Jetson Orin
Writing a V4L2 MIPI camera driver for Jetson Orin requires four components: the C sensor driver implementing `tegra_cam_platform_sensor_ops`, a device tree source (DTS) fragment with the sensor mode table and MIPI timing parameters, registration in the `nvidia-kernel-oot` out-of-tree module tree, and validation using `v4l2-ctl` before testing with Argus.
The MIPI-specific parts are in the DTS: `data-lanes`, `link-frequencies`, and the per-mode `line_length`, `pix_clk_hz`, and `readout_orientation` fields. The driver code itself sets up I2C, reads the chip ID register, configures the sensor via the init register sequence, and implements the `set_mode`, `start_streaming`, and `stop_streaming` ops. The tegra-camera-platform framework handles all NVCSI and VI configuration from the DTS mode table, your driver does not touch those registers directly.
## Key Insights
- Jetson uses the tegra-camera-platform framework, not raw V4L2 subdev ops, the DTS structure and driver ops are Jetson-specific
- The sensor mode table in the DTS is as important as the C driver code, wrong timing values cause subtle streaming failures
- First goal: get any frame through the pipeline, then iterate on format, controls, and mode accuracy
- You need the sensor's full register map including init sequences and streaming enable registers, public datasheets are rarely sufficient
- Test with `v4l2-ctl` before Argus to separate driver issues from Argus integration issues
## Understanding the Jetson camera driver stack
Before writing a single line of code, it helps to understand what you are plugging into.
A Jetson camera driver sits at the bottom of a chain: your driver talks to the sensor via I2C, the sensor sends MIPI CSI-2 data to the NVCSI, the NVCSI feeds the VI (Video Input) capture engine, and V4L2 / Argus sits above the VI.
The tegra-camera-platform framework coordinates all of this. Your driver implements a set of ops that the framework calls during probe, stream start/stop, and mode changes. You do not directly configure NVCSI or VI, the framework does that based on your DTS mode table.
```
Your sensor driver (imx_custom.c)
↓ implements tegra_cam_platform_sensor_ops
tegra-camera-platform framework
↓ configures
NVCSI → VI → V4L2 / Argus
```
## The driver skeleton
Start with the minimal driver structure:
```c
#include
#include
#include
static int imx_custom_s_power(struct v4l2_subdev *sd, int on)
{
/* 1. Toggle VDD, VDDIO, VANA rails */
/* 2. Toggle XCLR (reset) GPIO, deassert for power-on */
/* 3. Wait for sensor power-on time per datasheet */
return 0;
}
static int imx_custom_set_mode(struct v4l2_subdev *sd, u32 val)
{
struct camera_common_data *s_data = to_camera_common_data(sd->dev);
/* Write register table for mode 'val' */
return imx_custom_write_table(s_data->client,
imx_custom_mode_table[val]);
}
static int imx_custom_s_stream(struct v4l2_subdev *sd, int enable)
{
struct camera_common_data *s_data = to_camera_common_data(sd->dev);
u8 val = enable ? 0x01 : 0x00;
return imx_custom_write_reg(s_data->client,
IMX_CUSTOM_STREAM_ENABLE_REG, val);
}
static struct camera_common_sensor_ops imx_custom_sensor_ops = {
.numfmts = ARRAY_SIZE(imx_custom_fmts),
.fmts = imx_custom_fmts,
.power_on = imx_custom_power_on,
.power_off = imx_custom_power_off,
.s_stream = imx_custom_s_stream,
.set_mode = imx_custom_set_mode,
.g_frame_interval = imx_custom_g_frame_interval,
.s_frame_interval = imx_custom_s_frame_interval,
};
```
The register write function is typically a straightforward I2C transfer. Use the camera_common infrastructure (`camera_common_i2c_write`) rather than raw i2c_transfer, it handles retry logic that sensor initialization sequences often need.
## The mode table
The mode table is the most time-consuming part to get right. Each mode defines the sensor's MIPI output timing for a given resolution and frame rate. Wrong values cause `uncorr_err` from the NVCSI or off-by-one frame rate.
The critical values, get these from the sensor datasheet, not by guessing:
```dts
mode0 { /* 1920x1080 @ 30fps */
mclk_khz = "24000"; /* Input clock frequency */
num_lanes = "4"; /* MIPI data lanes */
tegra_sinterface = "serial_a"; /* NVCSI interface */
vc_id = "0"; /* Virtual channel */
discontinuous_clk = "no";
dpcm_enable = "false";
cil_settletime = "0";
active_w = "1920"; /* Active pixel width */
active_h = "1080"; /* Active pixel height */
mode_type = "bayer";
pixel_phase = "rggb"; /* Bayer pattern, check datasheet */
csi_pixel_bit_depth = "10"; /* RAW10, RAW12, etc. */
line_length = "2200"; /* Total line length in pixels */
inherent_gain = "1";
mclk_multiplier = "20.0"; /* PLL multiplier from MCLK */
pix_clk_hz = "480000000"; /* Pixel clock = line_length × rows × fps */
min_gain_val = "1";
max_gain_val = "16";
min_framerate = "1.0";
max_framerate = "30.0";
min_exp_time = "28"; /* In microseconds */
max_exp_time = "33000";
embedded_metadata_height = "0";
};
```
The `pix_clk_hz` must be consistent with `line_length`, frame height, and frame rate: `pix_clk_hz = line_length × (active_h + vblank) × framerate`. Get this from the sensor PLL register table in the datasheet.
## Sensor register tables
Sensor init sequences are typically long arrays of (address, value) pairs. Structure them as:
```c
static struct reg_8 imx_custom_mode_1920x1080_30fps[] = {
/* Streaming disable */
{0x0100, 0x00},
/* PLL settings for 24MHz MCLK, 4-lane, 960Mbps */
{0x0301, 0x05},
{0x0303, 0x02},
/* ... many more registers ... */
/* Streaming enable */
{0x0100, 0x01},
{IMX_TABLE_END, 0x00},
};
```
The table ends with a sentinel value (`IMX_TABLE_END`) that the write function uses to stop. Write a simple loop that processes the table entry by entry:
```c
static int imx_custom_write_table(struct i2c_client *client,
const struct reg_8 *table)
{
int err;
while (table->addr != IMX_TABLE_END) {
err = camera_common_i2c_write(client, table->addr, table->val);
if (err)
return err;
table++;
}
return 0;
}
```
## Testing progression
Do not try to get a perfect frame immediately. Work through this progression:
1. **Driver probes.** `dmesg | grep imx_custom` shows probe success. If probe fails, fix the DTS compatible string, I2C address, or GPIO/regulator references.
2. **V4L2 device appears.** `v4l2-ctl --list-devices` shows your sensor. If absent, the VI-to-NVCSI link in the DTS is wrong.
3. **Format sets without error.** `v4l2-ctl --set-fmt-video=width=1920,height=1080,pixelformat=RG10` exits cleanly.
4. **Streaming starts.** `v4l2-ctl --stream-mmap --count=10` captures frames without timeout. Any frame, even a corrupted one, means the pipeline is working.
5. **Frame is valid.** Capture to file and view with a RAW image viewer. Wrong Bayer pattern? Fix `pixel_phase` in the mode table. Wrong resolution? Fix `active_w`/`active_h`.
## Implementing V4L2 controls
V4L2 controls expose sensor parameters (gain, exposure, AWB) to userspace and Argus. Register them in your probe function:
```c
static int imx_custom_ctrls_init(struct imx_custom *priv)
{
struct v4l2_ctrl_handler *ctrl_hdl = &priv->ctrl_handler;
int err;
err = v4l2_ctrl_handler_init(ctrl_hdl, 4);
if (err)
return err;
/* Exposure in microseconds */
priv->exposure = v4l2_ctrl_new_std(ctrl_hdl, &imx_custom_ctrl_ops,
V4L2_CID_EXPOSURE, IMX_MIN_EXPOSURE_US,
IMX_MAX_EXPOSURE_US, 1, IMX_DEFAULT_EXPOSURE_US);
/* Analog gain (sensor-specific units, converted in s_ctrl) */
priv->gain = v4l2_ctrl_new_std(ctrl_hdl, &imx_custom_ctrl_ops,
V4L2_CID_ANALOGUE_GAIN, IMX_MIN_GAIN,
IMX_MAX_GAIN, 1, IMX_DEFAULT_GAIN);
return ctrl_hdl->error;
}
```
In `s_ctrl`, translate V4L2 values to sensor register format:
```c
static int imx_custom_s_ctrl(struct v4l2_ctrl *ctrl)
{
struct imx_custom *priv = container_of(ctrl->handler,
struct imx_custom, ctrl_handler);
switch (ctrl->id) {
case V4L2_CID_EXPOSURE:
return imx_custom_set_exposure(priv->client, ctrl->val);
case V4L2_CID_ANALOGUE_GAIN:
return imx_custom_set_gain(priv->client, ctrl->val);
}
return -EINVAL;
}
```
Argus calls `s_ctrl` during auto-exposure computation. If the exposure or gain registers write fails, Argus silently falls back to fixed values, check dmesg for write errors if AE doesn't converge.
## Building and loading the driver module
For JetPack 6 (L4T R36), use the nvidia-kernel-oot build system:
```bash
# Clone the out-of-tree kernel module repository
git clone https://github.com/NVIDIA/nvidia-kernel-oot.git
cd nvidia-kernel-oot
# Add your driver files
cp /path/to/imx_custom.c drivers/media/i2c/
# Add to drivers/media/i2c/Kconfig:
# config VIDEO_IMX_CUSTOM
# tristate "Custom IMX sensor"
# depends on I2C && VIDEO_V4L2
# Add to drivers/media/i2c/Makefile:
# obj-$(CONFIG_VIDEO_IMX_CUSTOM) += imx_custom.o
# Build
make -C . \
KDIR=/usr/src/linux-headers-$(uname -r) \
CONFIG_VIDEO_IMX_CUSTOM=m
# Load
sudo insmod drivers/media/i2c/imx_custom.ko
dmesg | tail -20 # Check for probe success or error
```
To load automatically at boot, copy the `.ko` to `/lib/modules/$(uname -r)/extra/` and run `sudo depmod -a`, then add the module name to `/etc/modules`.
## Driver probe troubleshooting
**`probe failed` with `-ENODEV`**
The driver is trying to read the sensor chip ID register and getting the wrong value (or no response). Either the I2C address is wrong, the sensor isn't powered, or the I2C bus number in the DTS is wrong. Verify with `i2cdetect -y ` that the sensor responds at the expected address before debugging the driver.
**`probe failed` with `-EINVAL` or `-EPROBE_DEFER`**
A regulator or GPIO reference in the DTS is unresolved. `-EPROBE_DEFER` means a dependency (PMIC, GPIO expander) hasn't probed yet, this usually self-resolves at boot. `-EINVAL` means the DTS reference is wrong. Check `dmesg | grep -i "imx_custom\|regulator\|gpio"` for the specific resource that failed.
**Driver probes but `v4l2-ctl --list-devices` doesn't show the sensor**
The V4L2/media device registration failed. This is almost always a `tegra-camera-platform` DTS node issue, the `proc-device-tree` path in the module definition doesn't match the actual sensor node path. Verify by running `ls /proc/device-tree/i2c@*/` and confirming the path matches what your DTS declares.
**`uncorr_err` in nvcsi logs during streaming**
MIPI data rate or lane count mismatch between `pix_clk_hz`/`link_freq_hz` in the DTS and what the sensor is actually outputting. Recalculate `pix_clk_hz = line_length × (active_h + vblank) × fps` using the sensor's actual PLL configuration register values. See [V4L2 uncorr_err on Jetson: what it means and how to fix it](/blog/v4l2-uncorr-err-jetson-csi-camera-fix).
If the driver development is taking longer than expected or you are working with an undocumented sensor, the [Jetson camera driver development service](/services/gmsl) covers custom driver engagements for unusual sensors and custom carrier boards.
NVIDIA's complete sensor driver programming guide for Jetson is in the [Jetson Linux Developer Guide](https://docs.nvidia.com/jetson/archives/r36.4.3/DeveloperGuide/SD/CameraApplicationDevelopment/SensorDriverProgrammingGuide.html). Reference driver source code (IMX390, IMX219) is in the L4T kernel source at `kernel/nvidia/drivers/media/i2c/`.
---
---
## V4L2 uncorr_err on Jetson: what it means and how to fix it
URL: https://proventusnova.com/blog/v4l2-uncorr-err-jetson-csi-camera-fix/
Published: 2026-04-21
Author: Andres Campos
Tags: jetson, csi camera, v4l2, mipi, camera driver, debugging
The uncorr_err from tegra-camrtc-capture-vi on Jetson means the CSI receiver is getting corrupted MIPI data. Here are the 5 most common root causes and.
The uncorr_err message from tegra-camrtc-capture-vi on Jetson means NVCSI is receiving corrupted data from the CSI interface. It looks like a driver problem but is almost always a hardware signal integrity issue, usually inverted MIPI P/N pairs in the PCB layout or incorrect lane configuration in the DTS. This post covers how to find and fix it.
## Key Insights
- `uncorr_err` from `tegra-camrtc-capture-vi` means the NVCSI hardware is getting MIPI data it can't decode, CRC/ECC errors at the physical layer
- The sensor can be alive on I2C and `/dev/video0` can exist while this error fires, probe success and capture success are completely independent
- Five causes cover the vast majority of cases: wrong MCLK, MIPI link frequency mismatch, wrong lane count, lane polarity inversion on the PCB, power rail instability
- Start with software (MCLK, link freq, lane count in DTS) before suspecting hardware, most cases are configuration, not board damage
- Intermittent `uncorr_err` usually points to power; every-frame errors point to MCLK or lane misconfiguration
## Is uncorr_err a software or hardware problem?
In most cases, 80% or more of the `uncorr_err` issues we debug, the root cause is a software configuration error, not a hardware failure. Wrong MCLK frequency, wrong MIPI link frequency in the DTS, incorrect lane count, or uninverted lane polarity in the DTS all produce identical error messages to a physically broken board.
**Start with software. End with hardware.**
The quick way to distinguish:
- **Every frame produces `uncorr_err`**: Almost always a configuration problem (MCLK, link frequency, lane count, lane polarity). These are deterministic, wrong settings produce errors on every single frame.
- **Intermittent `uncorr_err`, some frames capture correctly**: Power issue (voltage droop, insufficient current budget) or signal integrity at the edge of spec (PCB trace impedance, connector contact resistance).
- **`uncorr_err` on all NVCSI ports, all sensors**: Likely a DTS-level mistake (wrong PHY mode sitewide, wrong clock configuration) or a power supply problem.
- **`uncorr_err` on one port only, works on others**: Could be lane polarity inversion on that port's PCB routing, or ESD damage to that specific NVCSI receiver.
Don't probe the board until you have confirmed the DTS is correct. We have seen teams spend days on signal integrity analysis when the actual cause was a `link_frequencies` value copied from a different sensor with a different MIPI output rate.
## What uncorr_err actually means
When you see this in dmesg:
```
[ 12.453] NVCSI stream 0, uncorr_err 0x00000001, err_status 0x00000020
[ 12.454] tegra-camrtc-capture-vi 13e00000.vi: capture failed, err 0xffffffea
[ 12.455] tegra-camrtc-capture-vi 13e00000.vi: vi_capture_control_message failed
```
...the sensor is producing MIPI output that the Jetson can't decode. The NVCSI (NVIDIA CSI receiver) is getting data, but it's garbage, CRC errors, lane alignment failures, or pure noise.
This is different from a probe failure. `/dev/video0` exists because the sensor registered on I2C and V4L2 successfully. The driver ran through its initialization sequence. But the MIPI physical link between sensor and SoC is either misconfigured or broken.
Here's the failure sequence: sensor starts streaming → MIPI data flows → NVCSI tries to receive and decode → data doesn't match expected framing → `uncorr_err` → VI captures nothing → `v4l2-ctl --stream-mmap` returns zero bytes.
## Root cause 1: wrong MCLK frequency
The sensor master clock (MCLK) drives the sensor's internal PLL. If MCLK is wrong, the sensor's output bit rate is wrong, and the NVCSI can't lock onto it.
Most sensors have a very specific MCLK requirement. The IMX477, for example, uses a 24 MHz MCLK. Running it at 25 MHz (or at the default Tegra MCLK output if the DTS isn't configured) will cause the sensor to output a different MIPI frequency than expected, producing `uncorr_err`.
Check your DTS sensor node:
```dts
mclk_khz = "24000"; /* Must match sensor datasheet */
mclk_multiplier = "2.0"; /* Check sensor PLL tables */
```
And verify the actual clock output on the MCLK pin with an oscilloscope if you have one. The Tegra clock divider arithmetic can produce frequencies that are slightly off if the parent clock isn't what you assumed.
## Root cause 2: MIPI link frequency mismatch
This is the most common cause on custom boards. The `link_frequency` in your sensor DTS must exactly match the MIPI bit rate the sensor is configured to output.
Example DTS entry:
```dts
link_frequencies = /bits/ 64 <456000000>; /* 456 MHz per lane */
```
If the sensor is outputting 480 MHz per lane because a register write in the init sequence put it in a different mode, `uncorr_err` is inevitable. The NVCSI configures its receiver to expect the declared frequency and will desync if the actual frequency is different.
How to check: review your sensor initialization sequence against the datasheet. Sensors often have multiple output modes; verify the register values in your driver's mode table correspond to the frequency declared in the DTS. A 5–10% mismatch will still cause errors.
## Root cause 3: wrong lane count or polarity
The `num_lanes` in your DTS must match the actual number of MIPI CSI data lanes connected on the board. If you declare 4 lanes but only 2 are routed, or declare 2 lanes when the sensor is outputting 4, the NVCSI will either receive incomplete data or try to read lanes that have nothing on them.
```dts
num_lanes = "4"; /* Must match PCB routing */
```
Lane polarity is a separate issue. MIPI differential pairs have a defined P/N orientation. If your PCB routing inverted one or more pairs (swapped + and -), the NVCSI receives bit-inverted data on that lane. Every byte is corrupted. This produces `uncorr_err` on every frame.
On Orin, lane polarity inversions can be corrected in the device tree without board rework:
```dts
lane_polarity = "6"; /* Bitmask: bit N inverts lane N */
```
The bitmask encoding is in the Orin technical reference manual. You can determine which lanes are inverted by process of elimination if you don't have board layout access.
## T-PHY vs D-PHY: PHY mode configuration
Jetson Orin's NVCSI supports two MIPI physical layer protocols: standard D-PHY (used by virtually all commercial CSI-2 sensors) and T-PHY (NVIDIA's enhanced protocol for higher lane speeds). Configuring the wrong PHY mode produces `uncorr_err` on every frame because the receiver's signal conditioning and clock recovery circuits are tuned for the wrong protocol.
The PHY mode is set in the DTS under the sensor mode node:
```dts
mode0 {
/* ... */
phy_mode = "DPHY"; /* For standard CSI-2 sensors */
/* phy_mode = "CPHY"; */ /* For sensors using C-PHY, rare */
};
```
If `phy_mode` is missing from your sensor mode DTS, the default is D-PHY on Orin. But if you borrowed a DTS from a T-PHY configuration or from a sensor that uses C-PHY, the mode will be wrong.
Check the NVCSI configuration as well:
```bash
sudo dmesg | grep -i "phy_mode\|cphy\|dphy\|tphy"
```
For virtually all commercial cameras (IMX series, OV series, AR series), the correct value is `"DPHY"`. T-PHY is primarily used with NVIDIA-developed cameras designed for the Orin's enhanced bandwidth. If your camera datasheet mentions only MIPI CSI-2, it uses D-PHY.
## What the err_status value tells you
The `uncorr_err` log line includes an `err_status` field:
```
NVCSI stream 0, uncorr_err 0x00000001, err_status 0x00000020
```
The `err_status` is a bitmask from the NVCSI error register. Common values and what they mean:
| err_status | Error type | Most likely cause |
|---|---|---|
| `0x00000001` | CRC error | Data lane corruption, wrong MCLK, link freq, or lane polarity |
| `0x00000002` | ECC double-bit error | Packet header corruption, signal integrity or wrong lane count |
| `0x00000020` | FIFO overflow | VI can't consume data fast enough, DTS format mismatch |
| `0x00000040` | Pixel count error | Frame dimensions don't match declared DTS format |
| `0x00000080` | Line count error | Number of lines doesn't match declared height |
**CRC and ECC errors** (0x01, 0x02) are the most common and point to physical layer problems: wrong frequencies, wrong lane count, or polarity inversions. These are the root causes covered in this post.
**FIFO overflow** (0x20) is less common and usually means the VI is configured for a different image format than the sensor is outputting, for example, the DTS says `YUV422` but the sensor is outputting `RAW10`. Check that `pixel_t` in your DTS matches your sensor's actual output format.
**Pixel count errors** (0x40, 0x80) mean the sensor is outputting a different resolution than what the DTS declares. Confirm `active_w` and `active_h` in your sensor mode DTS match the sensor's actual output resolution in the current mode.
## Root cause 4: sensor power instability
The sensor needs clean, stable power rails during MIPI streaming. If VDD, VDDIO, or VANA is noisy or drops below spec during the sensor's active imaging period, the MIPI transmitter output becomes intermittently corrupted.
`uncorr_err` caused by power issues often shows up as intermittent failures, some frames capture fine, others produce errors. Pure configuration issues (wrong MCLK, wrong link freq) produce errors on every frame.
Diagnostic steps:
- Probe the sensor power rails with an oscilloscope during capture, look for voltage droop under load
- Check if the errors go away when running at a lower frame rate (lower frame rate = lower average current draw)
- Verify your camera VDD regulator has adequate current budget for the sensor + MIPI I/O
## Root cause 5: incomplete sensor initialization
The sensor I2C init sequence must fully complete before the sensor starts streaming MIPI data. If a register write fails silently, or if the sequence is in the wrong order, the sensor may start transmitting before its internal PLL has locked.
Signs of this: `uncorr_err` on the first few frames only, or errors that go away when you add delays in the init sequence.
Check your driver's `sensor_reg_write` calls for return values. A failed I2C write returns an error but many drivers log it as a warning and continue. If the sensor isn't fully initialized, its MIPI output is undefined.
```bash
# Check for I2C errors during camera bring-up
sudo dmesg | grep -E "(i2c|I2C|sensor)" | head -30
```
Also check: does your driver implement `s_stream` in the right order? The sensor should not start MIPI output until after all mode registers are written and the PLL lock time has elapsed.
## Diagnosis sequence
Work through these in order, start cheap, end with hardware:
1. **Verify MCLK**: Check DTS `mclk_khz` against sensor datasheet. Measure on a scope if possible.
2. **Verify link frequency**: Cross-reference DTS `link_frequencies` with the sensor init register table.
3. **Check lane count**: Count the physical MIPI lanes on your schematic vs. DTS `num_lanes`.
4. **Check lane polarity**: Review PCB layout for P/N swaps, or test with different `lane_polarity` values.
5. **Check sensor power**: Probe rails during capture, lower frame rate to test.
6. **Add I2C error logging**: Verify every init register write succeeds.
If all six check out and you're still seeing `uncorr_err`, you may have a NVCSI configuration issue (PHY mode, T-PHY vs D-PHY selection) or an ESD-damaged MIPI receiver. At that point you're into kernel trace-level debugging.
For the full CSI camera bring-up sequence, including how to structure your DTS and sensor driver for Orin, see our [CSI camera driver on Jetson post](/blog/csi-camera-driver-jetson-v4l2-argus-imx). If your sensor also fails to produce frames after clearing the `uncorr_err`, see [IMX sensor on Jetson: I2C detects but no frames](/blog/imx-sensor-jetson-i2c-detects-no-frames) for the next layer of diagnosis. If you're hitting `uncorr_err` on a custom sensor and the standard fixes aren't resolving it, [book a scoping call](https://proventusnova.com/get-expert-nvidia-jetson-support), CSI bring-up is one of our most common engagements.
The MIPI CSI-2 specification covering CRC/ECC error handling is maintained by the [MIPI Alliance](https://www.mipi.org/specifications/csi-2). The Linux V4L2 subdev API documentation is at [kernel.org](https://www.kernel.org/doc/html/latest/userspace-api/media/v4l/dev-subdev.html).
---
## IMX sensor on Jetson: I2C detects but no frames, 5 root causes
URL: https://proventusnova.com/blog/imx-sensor-jetson-i2c-detects-no-frames/
Published: 2026-04-17
Author: Aaron Angulo
Tags: jetson, csi camera, imx sensor, v4l2, camera driver, i2c
i2cdetect finds your IMX477, IMX283 or IMX412 on Jetson, /dev/video0 exists, but streaming returns zero frames. Here are the 5 reasons this happens and.
An IMX sensor that I2C-detects correctly but produces no frames is one of the most common and frustrating camera bring-up failures on Jetson. The sensor appears in i2cdetect, the driver probes successfully, but nothing comes out of V4L2 capture. The cause is almost always in the sensor init sequence, the MIPI timing configuration, or the ISP pipeline setup. This post covers exactly how to diagnose which one.
## Key Insights
- `i2cdetect` finding your IMX sensor only means it's powered and on the I2C bus, it says nothing about the MIPI pipeline
- Five root causes cover the vast majority of no-frames failures: CSI port mismatch in DTS, sensor mode not loaded, MCLK not active before streaming, pixel format not set, driver is Argus-only
- CSI port mismatch is the most common on custom carrier boards, trace the physical MIPI lanes on your schematic before touching the driver
- Always set the V4L2 format on both the video device and the subdevice before streaming, setting only one silently falls back to a default that may not work
- If `nvarguscamerasrc` produces frames but `v4l2-ctl --stream-mmap` doesn't, you have an Argus-only driver, not a broken board
## Why I2C detection doesn't guarantee frames
When `i2cdetect -y 0` shows `0x10` (IMX477) or `0x1a` (IMX283), it means the sensor responded to an I2C address query. That's it. The sensor is powered, the I2C bus is functional, and the chip is there.
The MIPI capture pipeline is a completely separate path. For frames to arrive at the Jetson's V4L2 or Argus interface, all of the following must be true simultaneously:
- The sensor driver's `s_stream(1)` call must have completed and started MIPI output
- The MCLK must be active and at the correct frequency
- The NVCSI must be configured to receive on the correct CSI port and lane count
- The VI (Video Input) pipeline must be armed to capture
- The pixel format and resolution must match what the sensor is sending
I2C detection confirms only that the sensor is powered. Everything else can still be broken while `i2cdetect` shows a clean response.
## Root cause 1: CSI port mismatch in the device tree
This is the most common cause we see on custom carrier boards. The sensor DTS node specifies `csi-port = <0>`, but the physical MIPI lanes from the sensor are actually routed to CSI port 2 on the SoC. The VI tries to capture from port 0, which has nothing connected, and returns zero frames.
How to check: pull up your carrier board schematic and trace the MIPI data lanes from the sensor connector to the Jetson SoM pins. Cross-reference the SoM pin assignments with the Orin technical reference manual to determine which CSI port those pins belong to. Then verify the DTS matches.
```dts
/* Check this matches your PCB routing */
tegra-camera-platform {
modules {
module0 {
csi_port = "0"; /* This must match physical routing */
...
};
};
};
```
On Orin NX and Orin Nano, CSI ports 0 and 1 are on different physical connectors than on AGX Orin. If you're porting a reference design from one module to another, the CSI port numbers may not transfer.
## Root cause 2: sensor mode not loaded
IMX sensors support multiple operating modes, different resolutions, frame rates, and bit depths. The driver needs to load the correct register table for the selected mode before streaming starts.
If the driver defaults to an invalid mode index, or if the mode configuration doesn't match what `v4l2-ctl` requested, the sensor's register state after initialization may leave it in a non-streaming condition. The MIPI transmitter in the sensor won't start without the correct streaming enable register being set.
Check by looking at what `v4l2-ctl` reports for the sensor:
```bash
# List supported formats and frame sizes
v4l2-ctl --list-formats-ext -d /dev/video0
# Try setting a specific format before streaming
v4l2-ctl -d /dev/video0 \
--set-fmt-video=width=1920,height=1080,pixelformat=RG10
# Then start streaming
v4l2-ctl --stream-mmap -d /dev/video0 --count=10 -v
```
If `--list-formats-ext` returns nothing, the driver didn't register any valid formats, a driver implementation problem. If it lists formats but streaming still fails, check dmesg during the `--stream-mmap` call for `uncorr_err` or mode-switch errors.
## Root cause 3: MCLK not active before streaming
The IMX sensor's internal PLL requires a stable MCLK input before it can lock and produce valid MIPI output. If the driver enables MCLK and then immediately starts MIPI streaming without waiting for PLL lock time, the sensor's MIPI transmitter isn't ready and no frames come out.
This is a driver timing issue. The correct sequence is:
1. Enable MCLK (at correct frequency)
2. Wait for PLL lock time (usually 1–5 ms, per sensor datasheet)
3. Write the register initialization sequence
4. Wait for sensor streaming enable
5. Signal V4L2 that streaming has started
Drivers that skip the PLL lock delay or start MIPI capture before step 4 completes produce this failure. In dmesg you won't see errors, the pipeline starts, waits for frames, times out.
Check your driver's `s_stream` implementation. Does it call `clk_enable(mclk)` and then immediately proceed? Add the lock delay if it's missing.
## Root cause 4: wrong pixel format for capture
V4L2 on Jetson requires the capture format to be set before streaming begins. If you call `v4l2-ctl --stream-mmap` without first setting the format, the driver uses its default, which may not match what the sensor is outputting.
For a RAW10 sensor like the IMX477 sending 4-lane MIPI at 1920x1080, the format must be set to a compatible RAW10 format:
```bash
# Set format first
v4l2-ctl -d /dev/video0 \
--set-fmt-video=width=1920,height=1080,pixelformat=RG10
# Then set subdevice format (important on Orin)
v4l2-ctl -d /dev/v4l-subdev0 \
--set-subdev-fmt pad=0,width=1920,height=1080,code=0x300f
# Stream
v4l2-ctl --stream-mmap -d /dev/video0 --count=10
```
On Jetson Orin, you often need to set the format on both the video device and the subdevice. Setting only one and not the other results in format negotiation failure, which may silently fall back to a default that produces no valid frames.
## Root cause 5: Argus driver with limited V4L2 support
Some IMX sensor drivers provided by NVIDIA or carrier board vendors are primarily designed for the libargus API, not V4L2 direct capture. They implement the V4L2 subdev interfaces but may have incomplete implementations of the video node streaming path.
In practice, this means `v4l2-ctl` tools work for device query and format inspection, but actual frame capture requires going through the Argus pipeline:
```bash
# Test with nvarguscamerasrc instead of v4l2-ctl
gst-launch-1.0 nvarguscamerasrc sensor-id=0 ! \
'video/x-raw(memory:NVMM),width=1920,height=1080' ! \
nvvidconv ! xvimagesink -e
```
If this produces frames but `v4l2-ctl --stream-mmap` doesn't, you're in Argus-only mode. The driver works, but your V4L2 capture path needs to go through `nvarguscamerasrc` or the libargus API directly.
This is particularly common with IMX283 and IMX412 drivers from third-party BSP vendors.
## Quick diagnosis matrix
| Symptom | Most likely cause |
|---------|------------------|
| No `uncorr_err` in dmesg, zero frames, no timeout errors | CSI port mismatch |
| `uncorr_err` on every frame | MCLK/link frequency wrong (see our [uncorr_err post](/blog/v4l2-uncorr-err-jetson-csi-camera-fix)) |
| Frames work with nvarguscamerasrc but not v4l2-ctl | Argus-only driver |
| Format query returns no formats | Driver not registering V4L2 formats |
| Works first time, fails on subsequent runs | MCLK PLL lock timing |
| Works on JP5, broken on JP6 | tegracam API change (needs driver port) |
If the underlying problem is a missing or incomplete driver rather than a configuration issue, see [how to write a custom V4L2 camera driver for Jetson Orin](/blog/custom-v4l2-camera-driver-jetson-orin) for the full implementation guide. For more on the CSI bring-up stack including DTS structure and sensor driver templates, see our [CSI camera driver post](/blog/csi-camera-driver-jetson-v4l2-argus-imx). If your sensor produces frames but they come out corrupted, the next step is diagnosing [V4L2 uncorr_err on Jetson](/blog/v4l2-uncorr-err-jetson-csi-camera-fix). If you're stuck with a specific IMX variant and the standard fixes haven't moved the needle, [book a scoping call](https://proventusnova.com/get-expert-nvidia-jetson-support).
Sony's IMX sensor documentation (application notes and register maps) is available through the [Sony Semiconductor Solutions partner portal](https://www.sony-semicon.com/en/products/is/industry/index.html). For the V4L2 media controller API used to configure multi-subdev pipelines, see the [Linux kernel media documentation](https://www.kernel.org/doc/html/latest/userspace-api/media/mediactl/media-controller.html).
---
---
## CSI camera driver on Jetson: V4L2, Argus, and IMX sensor bring-up
URL: https://proventusnova.com/blog/csi-camera-driver-jetson-v4l2-argus-imx/
Published: 2026-04-15
Author: Andres Campos
Tags: jetson, csi camera, v4l2, argus, camera driver, imx sensor
How to bring up a CSI camera driver on NVIDIA Jetson. Covers V4L2 vs Argus, IMX sensor devicetree config, media-ctl debugging, and the 5 most common failures.
Getting a CSI camera working on Jetson involves two separate software paths, Argus for ISP-processed capture and V4L2 for raw access, and the right choice depends on what your application actually needs. The driver layer sits between your camera sensor and either of these APIs, and that's where most bring-up time gets spent. This post covers how the full stack fits together and where engineers get stuck.
## Key Insights
- **V4L2 and Argus are not competing, they're layered.** The kernel driver exposes a V4L2 node; Argus sits on top of it. You need the kernel driver working before either API will function
- **IMX sensor bring-up almost always fails first on the devicetree**, not the driver code itself, wrong i2c bus, wrong lane count, or wrong MCLK frequency
- **`media-ctl` is your first debugging tool.** If the sensor entity doesn't show up there, nothing else will work
- **The Argus daemon (`nvargus-daemon`) must be running** for `nvarguscamerasrc` and LibArgus to function, it's a separate process that gets missed in headless setups
- **Camera module vendors (Leopard Imaging, e-con, ArduCam) ship ready-to-use BSP packages** for most IMX sensors; building a driver from scratch is only necessary for custom silicon
## V4L2 vs Argus: which one do you actually need?
Both are valid, and most production Jetson deployments use both at different layers. The confusion comes from treating them as alternatives.
| | V4L2 | Argus (LibArgus / nvarguscamerasrc) |
|---|---|---|
| Layer | Kernel driver interface | Userspace camera server |
| Frame format | Raw (Bayer, YUV) | ISP-processed (NV12, RGBA) |
| ISP (auto-exposure, AWB) | No | Yes |
| GStreamer source element | `v4l2src` | `nvarguscamerasrc` |
| Works without X / display | Yes | Yes (daemon runs headless) |
| Multi-camera sync | Manual | Built-in via sensor mode |
| Requires NVIDIA platform | No | Yes |
The practical rule: if you need ISP output with auto-exposure for a machine vision or AI pipeline, use Argus via `nvarguscamerasrc`. If you need raw Bayer frames, precise frame timing, or a camera that isn't supported by the Argus daemon, use `v4l2src` directly.
Both require the same underlying kernel driver. The kernel driver is what we're bringing up when we talk about CSI camera driver development.
## Devicetree configuration for IMX sensors
This is where most CSI camera projects stall. The devicetree node tells the kernel driver how to talk to the sensor, i2c address, clock frequency, MIPI lane count, and power GPIO assignments.
A minimal IMX219 node looks like this:
```dts
imx219_a: imx219@10 {
compatible = "sony,imx219";
reg = <0x10>; /* i2c address */
clocks = <&bpmp TEGRA234_CLK_EXTPERIPH1>;
clock-names = "extperiph1";
clock-frequency = <24000000>; /* 24 MHz MCLK */
reset-gpios = <&gpio CAM0_RST_L GPIO_ACTIVE_LOW>;
pwdn-gpios = <&gpio CAM0_PWDN GPIO_ACTIVE_HIGH>;
port {
imx219_out: endpoint {
remote-endpoint = <&csi_in>;
data-lanes = <1 2>; /* num-lanes = 2 */
link-frequencies = /bits/ 64 <456000000>;
};
};
};
```
The fields that cause most failures:
1. **`reg`**, the i2c address in hex. Verify it with `i2cdetect -y -r `. A dot in the output means nothing responded at that address.
2. **`clock-frequency`**, must match your sensor's MCLK input exactly. Wrong frequency means the sensor PLL can't lock and won't respond.
3. **`data-lanes`**, must match the physical MIPI lane wiring. Two-lane sensors with a four-lane DT entry (or vice versa) will produce framing errors.
## Debugging with media-ctl
Once the devicetree is compiled in and the kernel module is loaded, use `media-ctl` to verify the sensor is visible:
```bash
# List all media devices
media-ctl -d /dev/media0 --print-topology
```
A working setup shows something like:
```
Entity 1: imx219 9-0010 (1 pad, 1 link)
type V4L2 subdev subtype Sensor flags 0
pad0: Source
[fmt:SRGGB10_1X10/3280x2464]
-> "vi-output, imx219 9-0010":0 [ENABLED,IMMUTABLE]
```
If your sensor entity doesn't appear, the driver didn't attach. Check `dmesg | grep imx` for probe errors, they'll usually tell you exactly why (i2c NACK, clock not found, GPIO request failed).
Once the entity is there, set the format and start capturing:
```bash
# Set format on the sensor pad
media-ctl -d /dev/media0 \
--set-v4l2 '"imx219 9-0010":0 [fmt:SRGGB10_1X10/1920x1080]'
# Capture a single frame to verify data is flowing
v4l2-ctl --device /dev/video0 \
--set-fmt-video=width=1920,height=1080,pixelformat=RG10 \
--stream-mmap --stream-count=1 \
--stream-to=test_frame.raw
```
If `v4l2-ctl` hangs on `--stream-mmap`, frames are not arriving from the sensor. That's almost always a link frequency mismatch, the MIPI D-PHY can't lock to the data rate.
## The 5 failures we see most often
**1. i2c address mismatch**
The sensor isn't responding on the bus. Verify with `i2cdetect -y -r `. Some sensors have address pins that can be pulled high or low, changing the address, check your board schematic.
**2. Wrong MCLK frequency**
The sensor datasheet specifies required input clock (commonly 24 MHz or 27 MHz). If the devicetree `clock-frequency` doesn't match, the sensor PLL won't lock. Symptom: i2c reads succeed but the sensor never enters streaming mode.
**3. MIPI lane count mismatch**
`data-lanes = <1 2>` means two lanes. `data-lanes = <1 2 3 4>` means four. If the DT says four lanes but the sensor is wired for two, you'll get framing errors and corrupt frames, sometimes the stream starts but every frame is garbage.
**4. Power sequencing**
Some sensors (particularly Sony IMX series) require VANA to come up before VDIG, and VDDIO last. The kernel driver's `power_on()` function controls this sequence. If you're using a custom carrier board, verify the regulator enable order matches the datasheet.
**5. nvargus-daemon not running**
After the kernel driver is confirmed working, `nvarguscamerasrc` in GStreamer still won't work if the Argus daemon isn't up. Check with:
```bash
systemctl status nvargus-daemon
# If inactive:
sudo systemctl start nvargus-daemon
```
In headless setups this service often isn't started automatically because it depends on display services. Fix it by adding it to your boot sequence or starting it in your application's launch script.
## Testing a full pipeline with GStreamer
Once `media-ctl` confirms the sensor is live, test end-to-end with GStreamer:
```bash
# Argus path, ISP-processed, production-ready
gst-launch-1.0 nvarguscamerasrc sensor-id=0 ! \
'video/x-raw(memory:NVMM),width=1920,height=1080,framerate=30/1' ! \
nvvidconv ! 'video/x-raw,format=BGRx' ! \
videoconvert ! autovideosink
# Raw V4L2 path, no ISP
gst-launch-1.0 v4l2src device=/dev/video0 ! \
'video/x-raw,format=RG10,width=1920,height=1080' ! \
videoconvert ! autovideosink
```
If `nvarguscamerasrc` produces a black frame, the ISP isn't getting valid data, go back and verify the MIPI link with `media-ctl`. If the V4L2 path works but Argus doesn't, the issue is in the Argus sensor mode configuration, not the kernel driver.
If your sensor doesn't have an existing driver and you need to build one from scratch, see [how to write a custom V4L2 camera driver for Jetson Orin](/blog/custom-v4l2-camera-driver-jetson-orin) for the full driver implementation walkthrough. For more on what to do once the camera is working, connecting it to an inference pipeline, see our [EdgeAI deployment service](/services/edgeai-deployment). If you're also dealing with a carrier board that won't boot, our [Jetson carrier board bring-up guide](/blog/custom-carrier-board-not-booting-jetson-orin) covers the most common BSP-level failures.
---
---
## Ethernet PHY bring-up on Jetson Orin: DP83867 and EQOS RGMII
URL: https://proventusnova.com/blog/ethernet-phy-bringup-jetson-orin-dp83867-eqos-rgmii/
Published: 2026-04-14
Author: Aaron Angulo
Tags: jetson, ethernet, dp83867, rgmii, eqos, carrier board, device tree
TI DP83867 PHY not working on Jetson Orin custom carrier board? Here are the EQOS RGMII timing, MDIO pinmux, and device tree configuration issues that.
The TI DP83867 is a capable Ethernet PHY that works reliably on Jetson Orin, once the RGMII timing, device tree configuration, and PHY strapping are all aligned. Getting there usually requires fixing two or three things simultaneously, which makes it hard to isolate the root cause. This post covers the full bring-up path and the most common failures.
## Key Insights
- Ethernet bring-up with DP83867 on Jetson Orin fails at one of four points: MDIO/MDC not in pinmux, wrong PHY address, RGMII delay double-counted, or EQOS clock not enabled
- RGMII delay misconfiguration is the most insidious, if you enable delays in both the DTS (`rgmii-id`) and the DP83867's strap pins, they stack and violate RGMII timing
- The PHY address in the DTS `reg` field must exactly match the `PHYAD[2:0]` strap resistors on your PCB, check your schematic, don't guess
- A link that comes up but drops packets almost always points to RGMII timing, wrong delay mode or missing termination
- `dmesg | grep -i eqos` and `dmesg | grep -i mdio` in sequence tells you exactly which layer is failing
## The EQOS + RGMII architecture on Jetson Orin
Jetson Orin (Tegra234) has two Ethernet controllers:
- **EQOS** (Ethernet Quality of Service): standard 1G/100M/10M controller, RGMII interface to PHY. This is what you use with the DP83867.
- **MGBE** (Multi-Gigabit Backplane Ethernet): 10G/25G, USXGMII/XFI interface. Not relevant to DP83867 designs.
The DP83867 is TI's widely-used Gigabit Ethernet PHY. It connects to the Orin via RGMII (Reduced Gigabit MII), 4-bit data paths with source synchronous clocking, and is configured over MDIO (Management Data Input/Output).
The failure modes are well-understood, but the diagnostic messages in dmesg are not always obvious about which layer is failing.
## Step 1: verify MDIO/MDC pinmux
The MDIO and MDC signals use Jetson SoM pins that must be explicitly enabled in the carrier board device tree. If these pins are in their default state (often HDMI or SFIO mode on Orin), the MDIO bus won't work and the PHY won't be detected.
Check your carrier board DTS for these pin configurations:
```dts
/* In your pinmux section */
eqos_mdio_pf5 {
nvidia,pins = "eqos_mdio_pf5";
nvidia,function = "eqos";
nvidia,pull = ;
nvidia,tristate = ;
nvidia,enable-input = ;
};
eqos_mdc_pf4 {
nvidia,pins = "eqos_mdc_pf4";
nvidia,function = "eqos";
nvidia,pull = ;
nvidia,tristate = ;
nvidia,enable-input = ;
};
```
Also verify the RGMII data pins (TX and RX data lanes, clocks) are all set to `nvidia,function = "eqos"` in the pinmux section. Missing even one pin in the pinmux block causes subtle failures, link may appear but drop packets.
## Step 2: confirm the PHY address
The DP83867 PHY address is set by its PHYAD[2:0] strap pins at power-on. Check your schematic for the resistor dividers or pull resistors on these pins. The most common values are 0x00 and 0x01.
Your EQOS device tree node must declare this address correctly:
```dts
&eqos {
phy-mode = "rgmii-id";
phy-reset-gpios = <&tegra_aon_gpio TEGRA234_AON_GPIO(EE, 2) GPIO_ACTIVE_LOW>;
mdio {
#address-cells = <1>;
#size-cells = <0>;
ethernet_phy0: ethernet-phy@0 {
reg = <0x0>; /* DP83867 PHYAD address, must match strap */
compatible = "ethernet-phy-id2000.a231"; /* DP83867 PHY ID */
};
};
};
```
A wrong address means the EQOS driver's PHY scan finds nothing and Ethernet is dead. You can verify the actual PHY address by enabling MDIO debug or using `ethtool -d eth0` to attempt register reads.
If the PHY address is wrong in the DTS, dmesg shows:
```
eqos 6800000.ethernet: no PHY found
eqos 6800000.ethernet: Could not attach to PHY
```
## Step 3: RGMII delay configuration
This is where most teams get stuck. RGMII requires setup and hold timing on the TX and RX data paths. These delays can be implemented in hardware (PCB trace length), in the PHY (internal delay settings), or in the MAC (through device tree phy-mode).
The DP83867 has configurable internal delays. Its `phy-mode` in the DTS must match how the delays are actually implemented:
| phy-mode | What it means |
|----------|--------------|
| `rgmii` | No delays in MAC or PHY, use PCB delays |
| `rgmii-id` | MAC applies both TX and RX internal delays |
| `rgmii-txid` | MAC applies TX delay only; PHY or PCB handles RX |
| `rgmii-rxid` | MAC applies RX delay only; PHY or PCB handles TX |
The most common mistake: using `rgmii-id` in the DTS (MAC applies both delays) while also enabling internal delays in the DP83867 via strapping or register writes. This doubles the delay, violates RGMII timing, and causes link problems, often "link up but no data" or extreme packet loss.
For a typical design where the DP83867 handles its own internal delays (common reference design choice):
```dts
phy-mode = "rgmii"; /* No MAC delays, PHY handles it internally */
```
Then configure the DP83867 delays via its registers at boot, or use the DP83867's strap pins to set the delay mode before the driver takes control.
For the NVIDIA DevKit reference design, look at the reference DTS for your carrier board, it shows how NVIDIA configured the delay mode for the KSZ9031 or DP83867 on the reference carrier.
## Step 4: reset GPIO timing
The DP83867 requires a hardware reset on power-up. The reset is active-low, and the Orin GPIO must be configured correctly in both the DTS and the pinmux.
```dts
phy-reset-gpios = <&gpio TEGRA234_MAIN_GPIO(G, 5) GPIO_ACTIVE_LOW>;
phy-reset-duration-us = <10000>; /* 10ms reset pulse */
phy-reset-post-delay-us = <50000>; /* 50ms after deassertion */
```
If the reset GPIO is wrong (wrong bank, wrong pin, or wrong polarity), the PHY comes up in an undefined state and MDIO register reads return garbage or fail entirely.
Check the reset GPIO against your schematic. Also verify the GPIO pin is configured as output in pinmux (not tristated). A tristated reset GPIO means the PHY may or may not be in reset depending on board-level pull resistors.
## Step 5: EQOS clock enable
The EQOS controller needs specific clocks enabled. These are usually handled by the NVIDIA BSP, but on custom carrier boards with modified power domain configurations, they can be missed.
Run this to check clock state:
```bash
# On Jetson: check EQOS-related clocks
sudo cat /sys/kernel/debug/clk/clk_summary | grep -i eqos
```
All relevant EQOS clocks should show non-zero reference counts when Ethernet is in use. If `clk_ref_count` is 0 for the main EQOS clocks when the interface should be up, that's your problem.
## Diagnostic command sequence
Work through this in order:
```bash
# 1. Check if EQOS is probing
sudo dmesg | grep -i eqos
# 2. Check MDIO/PHY detection
sudo dmesg | grep -i "phy\|mdio"
# 3. Check Ethernet interface state
ip link show eth0
ethtool eth0
# 4. Force link attempt
sudo ip link set eth0 up
sudo dmesg | tail -20 # Look for link partner negotiation
# 5. Check PHY registers if accessible
sudo ethtool -d eth0 2>/dev/null || echo "PHY not accessible"
```
If step 1 fails (`eqos 6800000.ethernet: probe failed`), the issue is device tree or clock configuration. If step 2 fails (`no PHY found`), check PHY address and MDIO pins. If step 3 shows the interface but no link, you're into RGMII delay or physical layer territory.
## Related posts
For broader bring-up context on custom Jetson carrier boards, see [Jetson carrier board not booting: 6 root causes nobody documents](/blog/jetson-carrier-board-not-booting-root-causes) and [Custom carrier board not booting on Jetson Orin](/blog/custom-carrier-board-not-booting-jetson-orin). If you're stuck on Ethernet PHY bring-up and the steps above haven't cleared it, [book a scoping call](https://proventusnova.com/get-expert-nvidia-jetson-support).
The TI DP83867 datasheet and application notes, including the RGMII delay configuration tables, are on the [TI product page for the DP83867IS](https://www.ti.com/product/DP83867IS). The RGMII specification and timing requirements are defined in the [IEEE 802.3 standard](https://standards.ieee.org/ieee/802.3/10422/).
---
---
## MediaTek Genio boot flow: from power-on to Linux
URL: https://proventusnova.com/blog/mediatek-genio-boot-flow/
Published: 2026-04-13
Author: Andres Campos
Tags: mediatek, genio, boot flow, u-boot, tf-a, bsp, embedded linux
MediaTek Genio boot sequence: TF-A, OP-TEE, U-Boot through Linux. Covers partition layout, boot_conf overlay loading, and strapping for custom carrier boards.
MediaTek Genio follows the standard ARM Trusted Firmware boot architecture, but the exact layout, which partitions hold what, how device tree overlays are loaded, and how boot mode is selected, is specific to the Genio platform. Understanding it fully matters when you're bringing up a custom carrier board or debugging a failed flash.
## Key Insights
- The boot chain is four stages: BL2 (TF-A, DRAM init) → BL31 (EL3 secure monitor, stays resident) → BL32 (OP-TEE) → BL33 (U-Boot, loads Linux).
- BL31+BL32+BL33 are packaged as `fip.bin` in the `bootloaders` partition. BL2 lives in `mmc0boot0`, loaded by the bootrom before the partition table is accessible.
- Set `boot_conf` to load device tree overlays, it accepts hash-delimited DTB/DTBO paths and can be set at Yocto build time, from the U-Boot shell, or from Linux via `fw_setenv`.
- U-Boot reads the fused chip ID at runtime and selects the correct DTB automatically via `UBOOT_CHIP_DTB_MAP`, one `fip.bin` can cover Genio 720 and 520 on a shared carrier board.
- External 12 kΩ strapping resistors are required on MT8391. Floating strapping pins cause random boot mode selection on every power cycle.
## The four-stage Genio boot chain
Genio follows the standard ARM Trusted Firmware boot architecture. Each stage runs at a specific exception level:
```
Power-on
↓
BL2 (TF-A), mmc0boot0
DRAM initialization, OP-TEE setup
↓
BL31 (Trusted Firmware), EL3, stays resident
Secure monitor for system lifetime
Handles all PSCI calls from Linux
↓
BL32 (OP-TEE), TrustZone EL1S
Secure OS, Trusted Applications
↓
BL33 (U-Boot), EL1
Loads fitImage, selects DTB via chip ID
↓
Linux kernel, EL1
```
BL31 is important to understand: it stays resident at EL3 and handles every PSCI call from Linux, CPU hotplug, suspend/resume, power domain control. If your Linux system has power management issues on Genio, BL31 is worth checking.
The entire BL31+BL32+BL33 chain is packaged as `fip.bin` (4MB) in the `bootloaders` partition. BL2 lives in `mmc0boot0`, a separate boot area the bootrom loads before the main partition table is accessible.
## Partition layout
| Partition | Size | Purpose |
|-----------|------|---------|
| `mmc0boot0` |, | BL2 (TF-A) |
| `mmc0boot1` |, | U-Boot environment + backup BL2 |
| `bootloaders` | 4MB | `fip.bin` (BL31 + BL32 + BL33) |
| `bootloaders_b` | 4MB | A/B backup of bootloaders |
| `kernel` | 32MB | `fitImage` (kernel + DTB + DTBOs) |
| `rootfs` | varies | Linux rootfs |
| `bootassets` | 32MB | DTBs, overlays, board assets |
| `EFI` | 100MB | EFI system partition (optional) |
| `misc` | 1MB | A/B update state tracking |
| `dramk` | 512KB | DRAM calibration data |
| `firmware` | 32MB | SCP, SOF, PMIC firmware |
| `firmware_b` | 32MB | A/B backup of firmware |
A/B update covers the `bootloaders` and `firmware` partitions. The `misc` partition tracks which slot is active. A failed bootloader update can be recovered from the `_b` slot, a real advantage over single-copy bootloader designs.
## How U-Boot selects the right DTB
U-Boot does runtime chip ID detection and selects the correct DTB from the fitImage automatically via `UBOOT_CHIP_DTB_MAP`:
```bitbake
UBOOT_CHIP_DTB_MAP = "mt8366:mediatek/mt8366-genio-360-evk.dtb \
mt8367:mediatek/mt8367-genio-360p-evk.dtb"
```
At boot, U-Boot reads the fused chip ID from hardware and picks the matching DTB. A single `fip.bin` and `fitImage` can cover multiple SoC variants on the same carrier board, useful for products supporting both MT8391 and MT8371 (Genio 720 and 520) on a common PCB.
## Loading device tree overlays, boot_conf
DTBOs are loaded via the `boot_conf` U-Boot environment variable:
```
boot_conf=#conf-mediatek_mt8391-genio-720-evk.dtb#conf-display-dsi.dtbo#conf-camera-imx214-csi0.dtbo
```
Three ways to set this:
**1. At Yocto build time:**
```bitbake
KERNEL_DEVICETREE_OVERLAYS_AUTOLOAD += "display-dsi.dtbo"
```
**2. From the U-Boot shell (persistent):**
```
setenv boot_conf "#conf-mediatek_mt8391-genio-720-evk.dtb#conf-display-dsi.dtbo"
saveenv
```
**3. From Linux (persistent, no U-Boot shell needed):**
```bash
fw_setenv boot_conf "#conf-mediatek_mt8391-genio-720-evk.dtb#conf-display-dsi.dtbo"
```
`fw_setenv` modifies the U-Boot environment stored in `mmc0boot1`, changes take effect on the next boot.
Available overlays on the Genio 720 EVK include:
- `display-dsi.dtbo`, MIPI DSI display
- `display-hdmi.dtbo`, HDMI output
- `display-dpoc.dtbo`, DisplayPort over Type-C (required on Genio 520/720, no HDMI on these SoCs)
- `audio-sof.dtbo`, SOF audio DSP
- `camera-imx214-csi0.dtbo`, IMX214 on CSI0
- `camera-lt6911uxe-csi0-std.dtbo`, LT6911 HDMI-to-CSI serializer
## Boot mode strapping on custom carrier boards
This is where carrier board bring-up often stalls. Genio latches the boot mode on the RESETB rising edge, whatever the strapping pins read at that instant is the boot mode for this power cycle.
External **12 kΩ pull-up or pull-down resistors** are required. Floating strapping pins cause the SoC to read random logic levels and boot into unpredictable modes. The failure pattern: USB download mode on some power cycles, eMMC boot on others, with no obvious cause.
MT8391 (Genio 720) supports: eMMC, UFS, SD, SPI NOR, and USB download mode. The strapping combination determines which. Get the resistors in place before first power-on, debugging a floating strapping pin after assembly is a significant setback.
We cover additional carrier board hardware design gotchas in the [Genio hardware design post](/blog/mediatek-genio-hardware-design-gotchas). For any Genio BSP work from a custom carrier board, we handle this from schematic review through first boot at [ProventusNova](/get-expert-mediatek-genio-support).
## Frequently Asked Questions
### What is the boot sequence on MediaTek Genio?
BL2 (TF-A) from mmc0boot0 initializes DRAM, BL31 sets up the EL3 secure monitor, BL32 (OP-TEE) runs the TrustZone secure OS, and BL33 (U-Boot) loads the fitImage and starts Linux.
### How do I load a device tree overlay on MediaTek Genio?
Set the `boot_conf` U-Boot environment variable with hash-delimited DTB and DTBO paths. Set it at Yocto build time, from the U-Boot shell with `setenv`/`saveenv`, or from Linux with `fw_setenv`.
### What does the Genio fitImage contain?
The fitImage (32MB kernel partition) contains the kernel binary, main board DTB, and any DTBOs. U-Boot selects the correct DTB at runtime from the chip ID via `UBOOT_CHIP_DTB_MAP`.
### What is the boot mode strapping on MediaTek Genio?
Boot mode is latched from strapping pins on the RESETB rising edge. External 12 kΩ pull-up or pull-down resistors are required. Floating strapping pins produce random boot mode selection.
### How does A/B update work on MediaTek Genio?
A/B update covers the `bootloaders` and `firmware` partitions. The 1MB `misc` partition tracks the active slot. Kernel and rootfs A/B operate independently.
---
## nvvidconv performance collapse with multiple GStreamer processes on Jetson
URL: https://proventusnova.com/blog/nvvidconv-performance-multiple-gstreamer-processes/
Published: 2026-04-10
Author: Aaron Angulo
Tags: jetson, gstreamer, nvvidconv, performance, vic, pipeline
Running multiple GStreamer pipelines as separate processes on Jetson? nvvidconv throughput can drop 5-10x. Here's why VIC contention causes it and the.
nvvidconv performance collapses when multiple GStreamer processes compete for NVIDIA's video conversion hardware simultaneously. The root cause is that nvvidconv uses a shared hardware resource, and concurrent access from separate processes causes serialization and latency spikes that look like pipeline bugs. The fix is to consolidate streams into a single pipeline.
## Key Insights
- Multiple GStreamer processes each using `nvvidconv` on Jetson serialize on the VIC (Video Image Composer) hardware, throughput can drop 5–10x
- VIC has a fixed number of concurrent contexts; when all are in use, other processes queue and wait
- The fix is architectural: run all pipelines in one GStreamer process, not multiple separate processes
- Keep every buffer in NVMM memory throughout the pipeline, system memory buffers add two DMA copies per frame
- On headless Jetson, DRM loading can also cause `nvvidconv` to use a slower path, disable DRM or run `jetson_clocks` on boot
## What's actually happening inside nvvidconv
`nvvidconv` is not a pure software color converter. It uses VIC, the Video Image Composer hardware unit on Jetson, for color space conversion and image scaling. VIC is a fixed-function hardware block separate from both the GPU and the CPU.
VIC has a fixed number of concurrent execution contexts. On Orin-class hardware, this is small, typically 2 to 4 contexts depending on the variant. Each GStreamer process that calls `nvvidconv` acquires a VIC context when it processes a buffer.
When you run two processes each with a `nvvidconv` element handling 30 fps video, here's what happens:
- Process A acquires VIC context, submits frame 0
- Process B tries to acquire VIC context, waits (all contexts in use)
- Process A completes, releases context
- Process B acquires context, submits its frame 0
- Process A tries to acquire for frame 1, waits again
Both pipelines end up running at roughly half the speed they'd achieve alone. With three processes it's worse. The `nvvidconv` elements in each process appear to work, no errors, no log messages, but frames queue up and the pipeline stalls.
The forum thread that surfaced this problem had a 9-reply discussion because the symptoms look like a hardware limitation ("Jetson can't handle this many streams") when it's actually a process architecture problem.
## How to confirm VIC contention
`tegrastats` is the tool. Run it while your pipelines are active:
```bash
sudo tegrastats --interval 500
```
Look for the VIC% field in the output:
```
RAM 2048/7764MB ... VIC 98% ...
```
If VIC% is near 100% and you have multiple processes, you're hitting contention. Each process's `nvvidconv` is queuing up behind the others. GPU% and CPU% may look fine, this is exclusively a VIC bottleneck.
For comparison, run a single pipeline alone and check VIC%. If it's 40% for one pipeline and 98% with two pipelines, the math confirms serialization.
You can also use `tegrastats --verbose` on some JetPack versions for per-engine breakdowns.
## The architectural fix: single process, multiple pipelines
The right architecture for multi-camera or multi-stream processing on Jetson is one GStreamer process running multiple pipelines, not multiple separate processes.
**Before (broken architecture):**
```bash
# Process 1
gst-launch-1.0 nvarguscamerasrc sensor-id=0 ! nvvidconv ! appsink &
# Process 2
gst-launch-1.0 nvarguscamerasrc sensor-id=1 ! nvvidconv ! appsink &
```
Each process holds its own VIC context. They serialize.
**After (correct architecture):**
```bash
# Single process, compositor handles both streams
gst-launch-1.0 \
nvarguscamerasrc sensor-id=0 ! \
nvvidconv ! video/x-raw(memory:NVMM),format=NV12 ! \
nvmultistreamtiler.sink_0 \
nvarguscamerasrc sensor-id=1 ! \
nvvidconv ! video/x-raw(memory:NVMM),format=NV12 ! \
nvmultistreamtiler.sink_1 \
nvmultistreamtiler rows=1 columns=2 width=3840 height=1080 ! \
nvvidconv ! nvoverlaysink
```
Or in your application code, use the GStreamer API to create multiple `GstPipeline` objects within a single process, each running in the shared mainloop:
```c
GstPipeline *pipeline1 = GST_PIPELINE(gst_pipeline_new("cam0"));
GstPipeline *pipeline2 = GST_PIPELINE(gst_pipeline_new("cam1"));
// Both share VIC contexts within the same process
GMainLoop *loop = g_main_loop_new(NULL, FALSE);
g_main_loop_run(loop);
```
Within a single process, VIC contexts are shared efficiently across pipelines. The serialization problem goes away.
## Keep buffers in NVMM memory throughout the pipeline
A secondary cause of nvvidconv slowdowns, separate from multi-process contention, is buffer memory type mixing.
When `nvvidconv` receives a GStreamer buffer allocated in system memory (CPU-accessible, non-NVMM), it has to:
1. Copy the buffer from system memory to hardware memory (DMA transfer)
2. Process it in VIC
3. Copy the result back
That's two extra DMA transfers per frame. At 4K30, this adds up fast.
Keeping buffers in NVMM memory throughout the pipeline eliminates both copies:
```bash
# Bad: system memory in the middle
... ! nvvidconv ! video/x-raw,format=NV12 ! nvvidconv ! ...
# ^^^^^^^^ no memory:NVMM = system memory
# Good: NVMM throughout
... ! nvvidconv ! video/x-raw(memory:NVMM),format=NV12 ! nvvidconv ! ...
```
Check every caps negotiation point in your pipeline with `GST_DEBUG=2` and look for buffer allocations that don't include `memory:NVMM`. Each one is a DMA copy insertion point.
## The DRM loading problem on headless Jetson
On headless Jetson deployments (no display connected), some configurations load the DRM (Direct Rendering Manager) subsystem at boot despite having no display. This can cause `nvvidconv` to initialize its buffer mapping in a compatibility mode that's significantly slower, sometimes an order of magnitude slower.
The symptom: `nvvidconv` performs fine when tested with a monitor connected, but is slow in headless production.
Fix options:
- Add `nvpmodel -m 0 && jetson_clocks` to your boot sequence to ensure clocks are at full speed before the pipeline starts
- Disable display output if truly headless: add `video=efifb:off` to kernel command line
- Load the NVMM drivers explicitly before the pipeline starts (the `nvcamerasrc` or `nvjpeg` initialization handles this in many cases)
For more on GStreamer pipeline performance generally, see our [GStreamer pipeline performance on Jetson post](/blog/gstreamer-pipeline-performance-jetson). If you're running CSI cameras into these pipelines and hitting frame drops before the VIC stage, see [V4L2 uncorr_err on Jetson](/blog/v4l2-uncorr-err-jetson-csi-camera-fix) for the upstream diagnosis.
The GStreamer `nvvidconv` element is documented in [NVIDIA's Accelerated GStreamer User Guide](https://docs.nvidia.com/jetson/archives/r36.4.3/DeveloperGuide/SD/Multimedia/AcceleratedGstreamer.html). For multi-stream pipeline design patterns, the [GStreamer documentation on pipeline construction](https://gstreamer.freedesktop.org/documentation/application-development/basics/pads.html) covers the fundamentals that apply across all platforms.
## Multi-process nvvidconv checklist
| Problem | Fix |
|---------|-----|
| Multiple `gst-launch` processes competing | Refactor to single process with multiple pipelines |
| VIC% at 100% with two or more pipelines | Confirm single-process architecture |
| NVMM buffers becoming system memory mid-pipeline | Add `memory:NVMM` to caps at every handoff point |
| Slow on headless, fast with display | Disable DRM or run `jetson_clocks` on boot |
| nvvidconv inside a loop or per-frame callback | Move to pipeline, don't call nvvidconv manually per frame |
---
## GStreamer pipeline performance on Jetson: fix slow pipelines
URL: https://proventusnova.com/blog/gstreamer-pipeline-performance-jetson/
Published: 2026-04-08
Author: Andres Campos
Tags: jetson, gstreamer, performance, nvvidconv, nvmm, pipeline optimization
Fix slow GStreamer pipelines on NVIDIA Jetson. Replace videoconvert with nvvidconv, use nvv4l2decoder, and keep data in NVMM to cut CPU load by 60–80%.
GStreamer pipeline performance on Jetson depends heavily on how well the pipeline uses NVIDIA hardware-accelerated elements. A pipeline with the wrong element choices can run at the same throughput on Jetson as on a generic ARM board, losing all the GPU acceleration. This post covers how to build pipelines that actually use the hardware.
## How to reduce end-to-end latency in a Jetson GStreamer pipeline
The dominant source of latency in a Jetson GStreamer pipeline is almost always a memory copy between system RAM and NVMM, not compute. Every time a CPU-based element like `videoconvert` or `appsink` receives an NVMM buffer, GStreamer copies the frame to system memory before passing it. On a 1080p30 stream that copy costs ~5-15ms per frame and saturates memory bandwidth.
The five most effective latency reductions, in order of impact:
1. **Replace `videoconvert` with `nvvidconv`** everywhere, VIC hardware handles format conversion in NVMM without CPU involvement
2. **Add `sync=false` on all sinks** (e.g., `nv3dsink sync=false`, `appsink sync=false`), disabling clock synchronization eliminates the presentation timestamp delay
3. **Use `queue leaky=2 max-size-buffers=1`** before slow elements, drop old frames instead of buffering them, keeping end-to-end delay at one frame
4. **Replace `avdec_h264` with `nvv4l2decoder`** for decode, hardware decode adds ~2ms vs ~20ms for software decode at 1080p
5. **Process frames in a GLib idle callback or separate thread from `appsink`**, a slow Python callback in `on_new_sample` blocks the entire pipeline
A camera-to-display pipeline with all five applied typically achieves under 50ms end-to-end latency on Jetson Orin at 1080p30.
## How to build a hardware-accelerated GStreamer live streaming pipeline on Jetson
A hardware-accelerated live streaming pipeline on Jetson keeps all processing in NVMM, from camera capture through encode, and transmits over UDP or RTSP with no CPU involvement in the video path.
**Camera to UDP (single stream, lowest latency):**
```bash
# Sender, Jetson
gst-launch-1.0 \
nvarguscamerasrc sensor-id=0 ! \
'video/x-raw(memory:NVMM),width=1920,height=1080,framerate=30/1' ! \
nvv4l2h264enc bitrate=4000000 iframeinterval=30 ! \
h264parse ! rtph264pay ! \
udpsink host=192.168.1.100 port=5000 sync=false
# Receiver, laptop or remote host
gst-launch-1.0 \
udpsrc port=5000 ! \
'application/x-rtp,encoding-name=H264,payload=96' ! \
rtph264depay ! avdec_h264 ! autovideosink
```
**Camera to file while streaming simultaneously (tee):**
```bash
gst-launch-1.0 \
nvarguscamerasrc sensor-id=0 ! \
'video/x-raw(memory:NVMM),width=1920,height=1080,framerate=30/1' ! \
nvv4l2h264enc bitrate=4000000 ! h264parse ! \
tee name=t \
t. ! queue ! rtph264pay ! udpsink host=192.168.1.100 port=5000 sync=false \
t. ! queue ! qtmux ! filesink location=/tmp/recording.mp4
```
**Key settings for low-latency streaming:**
- `iframeinterval=30`, keyframe every 30 frames (1 second at 30fps); lower = faster seek/recovery, higher bitrate
- `sync=false` on udpsink, disables presentation clock; without this, the sink adds presentation delay
- `nvv4l2h264enc` vs `x264enc`, hardware encoder uses <1% CPU; x264enc uses 40-60% CPU at 1080p30
- Add `queue max-size-buffers=1 leaky=2` before udpsink to drop old frames if the network is slow rather than building a backlog
For multi-client streaming, the gst-rtsp-server library wraps the pipeline in an RTSP server. A Python example using GstRtspServer is the cleanest approach for production deployments.
## Key Insights
- **The main bottleneck on Jetson GStreamer pipelines is almost always memory copies between system RAM and NVMM**, not compute, keep data in NVMM from camera to output
- **Replace `videoconvert` with `nvvidconv`** everywhere in a Jetson pipeline; the VIC hardware handles format conversion without touching the CPU
- **Use `nvv4l2decoder` instead of `avdec_h264`** for decode, hardware decode on Jetson handles 4K at a fraction of the CPU cost of software decode
- **`appsink` with a slow Python callback is the most common hidden bottleneck**, the pipeline backs up waiting for your callback to return
- **`GST_DEBUG_DUMP_DOT_DIR`** lets you visualize the full pipeline graph and spot where formats are negotiated incorrectly
## Hardware-accelerated vs CPU element reference
Use this table when building or auditing a Jetson GStreamer pipeline. Every CPU element in the left column is a potential performance sink, the right column is its hardware replacement.
| CPU element | Hardware replacement | Hardware engine | Notes |
|-------------|---------------------|-----------------|-------|
| `videoconvert` | `nvvidconv` | VIC | Drop-in replacement for format/colorspace conversion |
| `avdec_h264` | `nvv4l2decoder` | NVDEC | Add `h264parse` upstream |
| `avdec_h265` | `nvv4l2decoder` | NVDEC | Set `disable-dpb=1` for low-latency |
| `x264enc` | `nvv4l2h264enc` | NVENC | Set `bitrate` and `iframeinterval` |
| `x265enc` | `nvv4l2h265enc` | NVENC | |
| `jpegdec` | `nvjpegdec` | VIC | Required for camera MJPEG streams |
| `jpegenc` | `nvjpegenc` | VIC | |
| `videoscale` | `nvvidconv` | VIC | nvvidconv handles both scaling and format conversion |
| `videocrop` | `nvvidconv` with `left/right/top/bottom` | VIC | |
| `autovideosink` | `nvdrmvideosink` or `nv3dsink` | Display engine | autovideosink often picks a CPU path |
If you see any left-column element in your pipeline, replace it. One `videoconvert` in the middle of an otherwise NVMM pipeline forces every frame through system RAM.
## GStreamer element performance comparison on Jetson Orin
These numbers are from single-stream 1080p30 pipelines on Jetson AGX Orin. Multi-stream pipelines see proportional savings.
| Pipeline element | CPU usage | GPU/VIC engine | Notes |
|---|---|---|---|
| `videoconvert` (color convert) | 25–35% | none | Software; scales with resolution |
| `nvvidconv` (color convert) | <1% | VIC | Hardware; resolution-independent CPU cost |
| `avdec_h264` (decode) | 35–50% | none | Software; one core saturated at 1080p30 |
| `nvv4l2decoder` (decode) | 1–2% | NVDEC | Hardware; handles 4K30 at same CPU cost |
| `x264enc` (encode) | 50–70% | none | Software; 1080p30 uses 1+ cores |
| `nvv4l2h264enc` (encode) | <2% | NVENC | Hardware; handles 4K30 at same CPU cost |
| `autovideosink` | 5–15% | varies | Often picks a CPU path; replace with nvdrmvideosink |
| `nvdrmvideosink` | <1% | display engine | Direct DRM framebuffer; no compositor overhead |
**Pipeline audit formula:** If your pipeline's total CPU usage is above 5% at 1080p30 on Orin, you have at least one CPU element in the path. Run `htop` and look at per-core utilization, a saturated single core points to software decode or encode. CPU spread across cores at moderate load points to `videoconvert` or `appsink` with a slow callback.
## The unified memory architecture, and why it matters for pipelines
Jetson uses unified memory, the CPU and GPU share the same physical DRAM. This is different from a discrete GPU setup where CPU memory and GPU VRAM are separate. On Jetson, zero-copy between CPU and GPU is theoretically possible, but only when both sides use the right memory type.
NVIDIA's GStreamer plugins use **NVMM buffers**: a memory-mapped buffer that the GPU hardware engines (VIC, NVDEC, NVENC, DLA) can access without a DMA copy. The problem comes when you insert a CPU-based element into a pipeline that was otherwise entirely NVMM.
```
nvarguscamerasrc → nvvidconv → nvinfer → nvvidconv → nveglglessink
NVMM NVMM NVMM NVMM NVMM
```
This is a zero-copy pipeline. Everything stays in NVMM.
```
nvarguscamerasrc → videoconvert → appsink
NVMM ← COPY → system RAM
```
This copies every frame from NVMM to system RAM at `videoconvert`. On a 4K 30fps stream, that's roughly 720MB/s of unnecessary memory bandwidth.
## Identify the element causing the bottleneck
The fastest diagnostic is the GST pipeline graph. Set this before running your pipeline:
```bash
export GST_DEBUG_DUMP_DOT_DIR=/tmp
```
Then run your pipeline. After it starts (or crashes), `.dot` files appear in `/tmp`. Convert to PNG:
```bash
sudo apt install graphviz
dot -Tpng /tmp/pipeline*.dot -o /tmp/pipeline.png
```
Open the PNG. Look for:
- Elements showing `video/x-raw` (no `memory:NVMM`), these are CPU-path elements causing copies
- Caps negotiation failures, elements trying to send NVMM to a CPU-only sink
For runtime profiling, use `GST_DEBUG` with specific elements:
```bash
GST_DEBUG=nvvidconv:4,nvinfer:4,appsink:4 gst-launch-1.0 \
nvarguscamerasrc ! nvvidconv ! nvinfer config-file-path=det.cfg ! \
nvvidconv ! nvdrmvideosink
```
The logs will show per-element timing and buffer flow.
## The 4 patterns that kill throughput
**Pattern 1: `videoconvert` in a hardware pipeline**
The symptom is high CPU usage (70%+) on a pipeline that should be GPU-accelerated. The cause is one `videoconvert` element in the middle, forcing everything before and after it through system RAM.
Replace every `videoconvert` with `nvvidconv`:
```bash
# Slow (CPU path)
... ! videoconvert ! video/x-raw,format=BGR ! appsink
# Fast (hardware path)
... ! nvvidconv ! video/x-raw(memory:NVMM),format=NV12 ! nvvidconv ! \
video/x-raw,format=BGRx ! appsink
```
The second `nvvidconv` handles the final conversion out of NVMM before the CPU-side sink.
**Pattern 2: Software decode**
`avdec_h264` is a CPU-based H.264 decoder. On Jetson, use `nvv4l2decoder` instead:
```bash
# Slow
... ! h264parse ! avdec_h264 ! videoconvert ! autovideosink
# Fast
... ! h264parse ! nvv4l2decoder ! nvvidconv ! nvdrmvideosink
```
`nvv4l2decoder` uses the NVDEC hardware engine. On Jetson Orin, this handles 4K H.264 at roughly 1% CPU vs 40%+ for the software decoder.
**Pattern 3: Slow `appsink` callback**
`appsink` is how you pull frames into Python or C++ code. If your callback takes longer to process a frame than the pipeline produces them, the queue fills up and GStreamer stalls.
The default queue behavior is to block. Your pipeline backs up, your camera drops frames, and latency climbs. Fix it by setting a maximum buffer count and drop policy:
```python
appsink = pipeline.get_by_name("appsink0")
appsink.set_property("max-buffers", 1)
appsink.set_property("drop", True)
appsink.set_property("emit-signals", True)
```
`drop=True` means the sink drops old frames rather than blocking the pipeline. You lose frames but maintain real-time processing. If you can't afford to drop frames, you need to speed up the callback, move heavy work off the GStreamer thread with a separate processing queue.
**Pattern 4: Missing `queue` elements**
GStreamer runs elements in the same thread by default unless you insert `queue` elements to split into separate threads. A pipeline with a slow sink element (like a network sink) will block the camera source thread without a `queue` between them:
```bash
nvarguscamerasrc ! nvvidconv ! queue max-size-buffers=4 ! \
nvv4l2h264enc ! rtph264pay ! udpsink host=192.168.1.100 port=5000
```
The `queue` element decouples the camera thread from the encoder/network thread. Without it, network jitter stalls the camera.
## How to run multiple camera streams with nvstreammux
`nvstreammux` is the right way to handle multi-camera pipelines on Jetson, it batches multiple NVMM streams into a single batch buffer that `nvinfer` processes in one GPU inference call. Running a separate `nvinfer` per camera is ~4x less efficient for inference.
Basic 4-camera setup:
```bash
gst-launch-1.0 \
nvstreammux name=mux batch-size=4 width=1920 height=1080 \
batched-push-timeout=4000000 ! \
nvinfer config-file-path=config_infer.txt ! \
nvmultistreamtiler rows=2 columns=2 width=1920 height=1080 ! \
nvvidconv ! nv3dsink \
nvarguscamerasrc sensor-id=0 ! \
'video/x-raw(memory:NVMM),width=1920,height=1080,framerate=30/1' ! \
nvvidconv ! mux.sink_0 \
nvarguscamerasrc sensor-id=1 ! \
'video/x-raw(memory:NVMM),width=1920,height=1080,framerate=30/1' ! \
nvvidconv ! mux.sink_1 \
nvarguscamerasrc sensor-id=2 ! \
'video/x-raw(memory:NVMM),width=1920,height=1080,framerate=30/1' ! \
nvvidconv ! mux.sink_2 \
nvarguscamerasrc sensor-id=3 ! \
'video/x-raw(memory:NVMM),width=1920,height=1080,framerate=30/1' ! \
nvvidconv ! mux.sink_3
```
Key properties to set on `nvstreammux`:
- `batch-size`, must match the number of input streams
- `batched-push-timeout`, microseconds to wait for a full batch before pushing a partial one; 4000000 (4ms) is a good starting point for 30fps
- `live-source=1`, set this when reading from live cameras, not files; it prevents the muxer from blocking on slow streams
For GMSL2 multi-camera pipelines, the input comes from `nvarguscamerasrc` with virtual channel demuxing upstream. The muxer sink pad assignment must match the virtual channel order from the deserializer. If you're seeing frames from the wrong camera on the wrong output, check the VC-to-sink mapping in your deserializer device tree.
## A profiling pipeline for benchmarking
This pipeline measures pure throughput from camera to nowhere, useful for finding your theoretical maximum before you add processing:
```bash
gst-launch-1.0 -v \
nvarguscamerasrc num-buffers=300 ! \
'video/x-raw(memory:NVMM),width=1920,height=1080,framerate=30/1' ! \
nvvidconv ! \
'video/x-raw(memory:NVMM),format=NV12' ! \
fakesink sync=false
```
`fakesink` drops all frames immediately with no rendering overhead. If this pipeline runs at full framerate, your hardware can handle the resolution. If it drops frames here, the bottleneck is upstream of processing, check camera driver configuration and MIPI bandwidth.
For network streaming pipelines, see the [GStreamer development service](/services/gstreamer) page.
## Common GStreamer errors on Jetson and what they mean
**`no element "nvvidconv"`**
The NVIDIA GStreamer plugins aren't installed or aren't on the plugin path. Fix:
```bash
sudo apt install --reinstall gstreamer1.0-plugins-nvargus gstreamer1.0-nvvideo4linux2
gst-inspect-1.0 nvvidconv # should print the element description
```
Inside Docker, the container must use `--runtime=nvidia` and have the NVIDIA GStreamer libraries available. The simplest fix is to base your container on `nvcr.io/nvidia/l4t-base` which includes them.
**`video/x-raw(memory:NVMM) not compatible with video/x-raw`**
A CPU-side element is receiving an NVMM buffer it can't handle. This usually happens when `appsink` or `videoconvert` is immediately downstream of an NVMM-producing element. Insert an `nvvidconv` before the CPU element to convert out of NVMM:
```bash
... ! nvvidconv ! video/x-raw,format=BGRx ! appsink
```
**`internal data flow error` / pipeline stops after a few seconds**
Usually a queue overflow. Your appsink callback or downstream element is slower than the source. Set `max-buffers=1 drop=true` on appsink, or add `queue leaky=2 max-size-buffers=2` before the slow element.
**`nvarguscamerasrc no cameras available`**
The camera isn't initialized or the NVCSI driver can't find it. Check `dmesg | grep nvcsi` for errors. This is almost always a driver or device tree issue, not a GStreamer issue, the pipeline is fine, the camera isn't presenting itself to the driver. For bring-up problems at this layer, see [what's involved in CSI camera driver development](/services/csi).
**`failed to allocate required memory`**
Jetson's unified memory is exhausted. Reduce the number of streams, lower resolution, or reduce `nvstreammux` batch size. On Jetson Orin NX (16GB), this typically only happens above 8 simultaneous 1080p streams without careful memory management.
If you're hitting performance ceilings that go beyond pipeline configuration, custom hardware, unusual sensor combinations, or production latency requirements, the [GStreamer development service](/services/gstreamer) page outlines how a fixed-bid engagement works.
---
## OpenCV with CUDA on Jetson: CUDA_ARCH_BIN, cmake flags, JetPack 5 and 6
URL: https://proventusnova.com/blog/opencv-cuda-jetson-installation-guide/
Published: 2026-04-07
Author: Aaron Angulo
Tags: jetson, opencv, cuda, jetpack, edgeai, computer vision
Install OpenCV with CUDA on Jetson from source. cmake flags, CUDA_ARCH_BIN per module, swap setup, JetPack 5 and 6 differences, and troubleshooting.
Installing OpenCV with CUDA support on Jetson is not as simple as a package manager install, the prebuilt packages either lack CUDA support or link against the wrong CUDA version. Building from source with the right CMake flags gets you CUDA-accelerated OpenCV, but the build process has several known pitfalls that cost hours if you hit them blind.
## Key Insights
- **`apt install python3-opencv` gives you a CPU-only build**, it was compiled without CUDA flags and will not use the GPU for any operation, even on Jetson
- **CUDA architecture (`CUDA_ARCH_BIN`) must match your Jetson module**, Orin is 8.7, Xavier is 7.2, Nano is 5.3; wrong value = silent fallback to CPU
- **Build time ranges from 20 minutes (Orin AGX) to 2 hours (Nano)**, add swap space before building on lower-end modules or the compiler will OOM and abort
- **JetPack 5 and 6 have the same cmake flags**, the difference is in the pre-installed CUDA version (11.4 vs 12.x) and the available CUDA architectures
- **Uninstall the apt package before building**, conflicts will cause import errors even if the build succeeds
## Why the apt package doesn't use CUDA
This is the most common Jetson computer vision confusion we encounter. Run this on a fresh Jetson with the apt-installed OpenCV:
```python
import cv2
print(cv2.cuda.getCudaEnabledDeviceCount()) # Returns 0
print(cv2.getBuildInformation()) # CUDA: NO
```
The NVIDIA apt repository ships OpenCV built without CUDA because the correct `CUDA_ARCH_BIN` value is hardware-specific. Jetson Orin uses compute capability 8.7; Xavier uses 7.2; Nano uses 5.3. A single generic apt package can't encode all of these, so NVIDIA ships the CPU fallback and expects you to build from source.
The result is that every Jetson project doing computer vision needs a from-source OpenCV build at some point. Here's the exact sequence that works.
## What CUDA_ARCH_BIN should I use for my Jetson?
`CUDA_ARCH_BIN` tells the CUDA compiler which GPU compute capability to target. Using the wrong value means OpenCV's CUDA code compiles for the wrong architecture and falls back silently to CPU on your hardware.
| Jetson module | Compute capability | `CUDA_ARCH_BIN` |
|---|---|---|
| AGX Orin, Orin NX, Orin Nano | 8.7 | `8.7` |
| AGX Xavier, Xavier NX | 7.2 | `7.2` |
| TX2, TX2 NX | 6.2 | `6.2` |
| Nano (original 2019, 4GB/2GB) | 5.3 | `5.3` |
Check your module if unsure:
```bash
cat /etc/nv_tegra_release | head -1
```
The output includes the L4T version. Cross-reference against the table: R36.x = Orin (8.7), R35.x = Orin or Xavier (check the module), R32.x = Nano (5.3).
Setting the wrong value does not cause a build failure, it causes a silent fallback. You will get `getCudaEnabledDeviceCount()` returning 1 (CUDA is present) but operations that should run on the GPU will run on the CPU instead. Always verify with a timed benchmark after the build.
## Step 1: Remove the apt package and add swap
```bash
sudo apt remove python3-opencv libopencv-dev libopencv-contrib-dev -y
sudo apt autoremove -y
```
Add swap space before building. Without it, the compiler will OOM on modules with less than 16GB RAM:
```bash
sudo fallocate -l 8G /swapfile
sudo chmod 600 /swapfile
sudo mkswap /swapfile
sudo swapon /swapfile
```
Verify swap is active:
```bash
free -h
```
## Step 2: Install build dependencies
```bash
sudo apt update
sudo apt install -y \
build-essential cmake git pkg-config \
libjpeg-dev libpng-dev libtiff-dev \
libavcodec-dev libavformat-dev libswscale-dev \
libgtk2.0-dev libcanberra-gtk* \
python3-dev python3-numpy \
libgstreamer1.0-dev libgstreamer-plugins-base1.0-dev \
libv4l-dev v4l-utils
```
## Step 3: Clone OpenCV and opencv_contrib
```bash
cd ~
git clone --depth 1 --branch 4.9.0 https://github.com/opencv/opencv.git
git clone --depth 1 --branch 4.9.0 https://github.com/opencv/opencv_contrib.git
```
Use matching version tags for both repos. Mismatched versions will fail at compile time.
## Step 4: Build with CUDA flags
Find your CUDA architecture. Check your module first:
```bash
cat /etc/nv_tegra_release | head -1
```
Then use the right value:
| Jetson module | `CUDA_ARCH_BIN` |
|---|---|
| AGX Orin, Orin NX, Orin Nano | `8.7` |
| AGX Xavier, Xavier NX | `7.2` |
| TX2, TX2 NX | `6.2` |
| Nano (original 2019) | `5.3` |
```bash
cd ~/opencv
mkdir build && cd build
cmake -D CMAKE_BUILD_TYPE=RELEASE \
-D CMAKE_INSTALL_PREFIX=/usr/local \
-D OPENCV_EXTRA_MODULES_PATH=~/opencv_contrib/modules \
-D WITH_CUDA=ON \
-D CUDA_ARCH_BIN=8.7 \
-D WITH_CUDNN=ON \
-D OPENCV_DNN_CUDA=ON \
-D WITH_GSTREAMER=ON \
-D WITH_LIBV4L=ON \
-D BUILD_opencv_python3=ON \
-D BUILD_TESTS=OFF \
-D BUILD_PERF_TESTS=OFF \
-D BUILD_EXAMPLES=OFF \
-D INSTALL_PYTHON_EXAMPLES=OFF \
..
```
Replace `8.7` with your module's value from the table above.
Review the cmake output before building. Look for:
```
-- NVIDIA CUDA: YES (ver 12.2, CUFFT CUBLAS FAST_MATH)
-- NVIDIA GPU arch: 87
-- cuDNN: YES
-- GStreamer: YES
```
If CUDA shows NO, the CUDA toolkit path isn't set correctly. On Jetson, CUDA is at `/usr/local/cuda`, verify with `ls /usr/local/cuda/bin/nvcc`.
## Step 5: Compile and install
```bash
make -j$(nproc)
sudo make install
sudo ldconfig
```
On Jetson Nano this will take 90–120 minutes. On Orin AGX, closer to 25 minutes.
## Step 6: Verify
```python
import cv2
# Check CUDA is available
print("CUDA devices:", cv2.cuda.getCudaEnabledDeviceCount())
# Check build info for CUDA section
info = cv2.getBuildInformation()
cuda_start = info.find("NVIDIA CUDA")
print(info[cuda_start:cuda_start+200])
# Quick functional test
img = cv2.imread("test.jpg")
gpu_img = cv2.cuda_GpuMat()
gpu_img.upload(img)
gpu_gray = cv2.cuda.cvtColor(gpu_img, cv2.COLOR_BGR2GRAY)
result = gpu_gray.download()
print("GPU round-trip OK, shape:", result.shape)
```
`getCudaEnabledDeviceCount()` returning 1 confirms CUDA is active. If it returns 0 after a successful build, you have a Python path conflict, the old apt package is still being imported. Verify with `python3 -c "import cv2; print(cv2.__file__)"` to confirm the right `.so` is loading.
## JetPack 5 vs JetPack 6 differences
The cmake flags are identical between JetPack 5 and 6. What changes:
| | JetPack 5.x | JetPack 6.x |
|---|---|---|
| CUDA version | 11.4 | 12.x |
| cuDNN version | 8.x | 9.x |
| Python default | 3.8 | 3.10 |
| Supported modules | Orin, Xavier | Orin only |
For JetPack 5 on Xavier, the `CUDA_ARCH_BIN` is `7.2`. For JetPack 6 on Orin, it's `8.7`. Everything else in the build sequence is the same.
## How fast is CUDA OpenCV vs CPU OpenCV on Jetson?
The speedup depends on the operation and image size. CPU-bound operations like color space conversion and resizing see the largest gains because the VIC and GPU parallelize work the CPU handles serially.
Typical results on Jetson AGX Orin at 1080p (measured with `cv2.TickMeter`):
| Operation | CPU time | CUDA time | Speedup |
|---|---|---|---|
| `cvtColor` (BGR→Gray) | ~4 ms | ~0.4 ms | ~10x |
| `resize` (1080p→720p) | ~3 ms | ~0.3 ms | ~10x |
| `GaussianBlur` (15×15) | ~12 ms | ~1.2 ms | ~10x |
| `threshold` | ~1.5 ms | ~0.2 ms | ~7x |
| `Canny` edge detection | ~8 ms | ~1.5 ms | ~5x |
| DNN forward pass (MobileNet) | ~45 ms | ~6 ms | ~7x |
These are wall-clock times for a single-threaded CPU baseline vs a CUDA call with upload/download included. If you keep data on the GPU across multiple operations (upload once, chain CUDA ops, download once), the effective speedup is higher because you amortize the memory transfer.
The DNN module gains (WITH_CUDNN=ON + OPENCV_DNN_CUDA=ON) are the most impactful for inference workloads, 6-10x on Orin vs CPU is typical for classification networks under 10M parameters.
To benchmark your specific pipeline:
```python
import cv2
import numpy as np
img = cv2.imread("test.jpg")
gpu_img = cv2.cuda_GpuMat()
gpu_img.upload(img)
timer = cv2.TickMeter()
# CPU
timer.start()
for _ in range(100):
cv2.cvtColor(img, cv2.COLOR_BGR2GRAY)
timer.stop()
print(f"CPU cvtColor: {timer.getTimeMilli()/100:.2f} ms avg")
timer.reset()
# CUDA
timer.start()
for _ in range(100):
cv2.cuda.cvtColor(gpu_img, cv2.COLOR_BGR2GRAY)
timer.stop()
print(f"CUDA cvtColor: {timer.getTimeMilli()/100:.2f} ms avg")
```
Run this on your target module to get accurate numbers for your use case before committing to a CUDA-based pipeline.
## Troubleshooting common build failures
**`cc1plus: fatal error: Killed` during compilation**
The compiler process was OOM-killed. This always means insufficient memory. Fix: add 8GB swap before starting the build (`fallocate -l 8G /swapfile && chmod 600 /swapfile && mkswap /swapfile && swapon /swapfile`). If the OOM continues with swap, reduce parallelism to `make -j4` or `make -j2`. On Jetson Nano, 8GB swap + `make -j2` is the only reliable combination.
**`getCudaEnabledDeviceCount()` returns 0 after a successful build**
Python is loading the apt-installed OpenCV, not the one you built. The symptom: `python3 -c "import cv2; print(cv2.__file__)"` shows a path under `/usr/lib/python3/dist-packages/`. Fix: `sudo apt remove python3-opencv libopencv-dev` and reopen your terminal. The newly built `.so` at `/usr/local/lib/python3.x/dist-packages/` then takes precedence.
**cmake reports `NVIDIA CUDA: NO`**
The CUDA toolkit isn't on the path. On Jetson, CUDA lives at `/usr/local/cuda`. Verify:
```bash
ls /usr/local/cuda/bin/nvcc
export PATH=/usr/local/cuda/bin:$PATH
export LD_LIBRARY_PATH=/usr/local/cuda/lib64:$LD_LIBRARY_PATH
```
Add those exports to `~/.bashrc` so they persist across sessions before re-running cmake.
**`WITH_CUDNN=ON` but cmake shows `cuDNN: NO`**
The cuDNN development headers are missing. Fix:
```bash
sudo apt install libcudnn8-dev # JetPack 5
# or
sudo apt install libcudnn9-dev # JetPack 6
```
Then verify `/usr/include/cudnn.h` exists and re-run cmake.
**`ImportError: libopencv_core.so.4.9: cannot open shared object file`**
The shared library path isn't updated. Fix:
```bash
sudo ldconfig
```
If that doesn't resolve it, add `/usr/local/lib` to `/etc/ld.so.conf.d/opencv.conf` and run `sudo ldconfig` again.
## Building OpenCV with CUDA in Docker on Jetson
For reproducible deployments, building inside a container avoids polluting the host and makes the build portable across Jetson units.
Use an NVIDIA L4T base image that already includes CUDA:
```dockerfile
FROM nvcr.io/nvidia/l4t-ml:r36.2.0-py3
RUN apt-get update && apt-get install -y \
build-essential cmake git \
libjpeg-dev libpng-dev \
python3-dev python3-numpy \
libgstreamer1.0-dev \
&& rm -rf /var/lib/apt/lists/*
RUN git clone --depth 1 --branch 4.9.0 https://github.com/opencv/opencv.git /opencv && \
git clone --depth 1 --branch 4.9.0 https://github.com/opencv/opencv_contrib.git /opencv_contrib
RUN mkdir /opencv/build && cd /opencv/build && cmake \
-D CMAKE_BUILD_TYPE=RELEASE \
-D CMAKE_INSTALL_PREFIX=/usr/local \
-D OPENCV_EXTRA_MODULES_PATH=/opencv_contrib/modules \
-D WITH_CUDA=ON \
-D CUDA_ARCH_BIN=8.7 \
-D WITH_CUDNN=ON \
-D OPENCV_DNN_CUDA=ON \
-D WITH_GSTREAMER=ON \
-D BUILD_opencv_python3=ON \
-D BUILD_TESTS=OFF \
-D BUILD_EXAMPLES=OFF \
.. && make -j$(nproc) && make install && ldconfig
```
Run the container with GPU access:
```bash
docker build -t opencv-cuda-jetson .
docker run --runtime=nvidia --rm opencv-cuda-jetson \
python3 -c "import cv2; print(cv2.cuda.getCudaEnabledDeviceCount())"
```
The `--runtime=nvidia` flag is required to expose the GPU inside the container. Without it, the CUDA device count will be 0.
If you're also working out which JetPack version to target for your project, the [JetPack versions and L4T compatibility table](/blog/jetpack-versions-l4t-compatibility-table) has a full breakdown. For production-grade inference pipelines on Jetson, the [Jetson AI deployment service](/services/edgeai-deployment) covers TensorRT optimization, model conversion, and throughput testing.
---
## MediaTek Genio hardware design: what the EVK doesn't warn you about
URL: https://proventusnova.com/blog/mediatek-genio-hardware-design-gotchas/
Published: 2026-04-06
Author: Andres Campos
Tags: mediatek, genio, hardware design, carrier board, bsp, custom board
Hardware design gotchas moving from the MediaTek Genio EVK to a custom board: HDMI absence, SoC name mapping, pin conflicts, PMIC timing, and strapping.
Moving from the Genio EVK to a custom carrier board exposes issues that the reference documentation doesn't flag clearly. Most of them are fast to explain and painful to discover on hardware. The ones below account for the majority of first-boot failures we see on custom Genio designs.
## Key Insights
- Genio 520 and 720 have no HDMI, the only external display path is DisplayPort over Type-C (DPoC). Load `display-dpoc.dtbo` to enable it.
- SoC internal hardware names don't match marketing names: Genio 510 (MT8370) uses MT8188 GPU/VPU/ISP internally. Yocto recipes must reference the internal name.
- GPIO75 is shared between SPI1 MOSI and WiFi 3.3V power enable on the EVK 40-pin header, enabling SPI1 cuts power to WiFi unless you remap the regulator to GPIO42 first.
- MT6390 is pin-compatible with MT6357 PMIC but has different power-on timing, sequences that work on MT6357 hang on MT6390, with a failure that looks like the SoC never leaving BL2.
- Genio 420, 520, and 720 share the same Yocto machine config and pin footprint, a Genio 720 design can bin down to Genio 520 for cost reduction without a PCB respin.
## The HDMI assumption that kills carrier board schedules
Genio 520 and Genio 720 do not have HDMI output. This catches teams when they move from the devkit design to their own carrier board, or when they assume the Genio 720 EVK's display setup matches what their product needs.
The only external display path on MT8391 (Genio 720), MT8371 (Genio 520), and MT8371LV (Genio 420) is DPoC, DisplayPort over Type-C. To enable it:
```
boot_conf=...#conf-display-dpoc.dtbo
```
This is not a BSP limitation or a missing driver, there's no HDMI transmitter IP inside these SoCs. All three are pin-to-pin compatible (same VFBGA footprint) but none have HDMI.
MT8395 (Genio 1200) is a different package entirely (15x15mm vs the MT8391 footprint) and does have HDMI. It is not pin-compatible with MT8391, a Genio 720 design cannot swap to Genio 1200 without a board respin.
## eDP: the panel path, and the pins it shares with USB-C
Once HDMI is off the table, products with a built-in screen usually land on eDP, and it deserves its own design review line items. On Genio 510 and 700 the SoC's DP controller provides eDP 1.4 (`display-edp.dtbo`). On the 520/720 class, eDP is a first-class panel interface too: the EVKs pair it with a 4K INNOLUX panel, and the BSP ships separate `display-edp-4k.dtbo` and `display-edp-fhd.dtbo` overlays depending on the panel.
The board-level catches:
- **DP/eDP shares pins with USB-C.** The DP lanes are routed through the same pins as USB-C alt mode, so a design that wants eDP for the panel and USB-C for data needs the alt-mode mux decision made explicitly at schematic time. Discovering this after layout is a respin.
- **HPD needs a level shifter.** Hot plug detect on the SoC is 1.8V I/O; panels and connectors commonly expect 5V HPD. Budget the shifter on every DP-family interface.
- **Impedance is standard but unforgiving.** DP/eDP pairs route at 100Ω differential, same discipline as the MIPI lanes.
Practical guidance for product designs: DSI covers small and mid panels with the least design effort, eDP is the path that scales to high-resolution built-in screens, and DP over USB-C is the only external-monitor story on 420/520/720. Pick per product, and lock the USB-C mux topology before layout starts.
## The SoC internal name mapping trap
MediaTek's hardware IP blocks use internal names that don't match the marketing SoC names. This matters whenever you're writing Yocto recipes that target specific silicon:
| Marketing name | SoC ID | TFA Platform | GPU internal name | VPU/ISP internal name |
|----------------|--------|--------------|-------------------|-----------------------|
| Genio 350 | mt8365 | mt8365 | mt8365 | mt8365 |
| Genio 360 | mt8366 | mt8366 | **mt8189** | mt8366 |
| Genio 420/520/720 | mt8371lv/mt8371/mt8391 | mt8391 | **mt8189** | **mt8189** |
| Genio 510 | mt8370 | **mt8188** | **mt8188** | **mt8188** |
| Genio 700 | mt8390 | **mt8188** | **mt8188** | **mt8188** |
| Genio 1200 | mt8395 | **mt8195** | mt8195 | mt8395 |
The practical consequence: Genio 510 (MT8370) uses MT8188 GPU, VPU, and ISP hardware. Any recipe that installs Mali GPU firmware or builds a camera daemon for Genio 510 must reference `mt8188` internally, not `mt8370`. The BSP handles this automatically, but custom recipes that fail with a missing firmware error on Genio 510 are hitting this mapping issue.
Genio 360 (MT8366) uses `mt8189` GPU and requires Mali GPU firmware (`REQUIRE_FIRMWARE:mt8189 = "1"`). If you're porting Genio 350 bring-up experience to Genio 360 and GPU display isn't coming up, this is often the cause, Genio 350 (mt8365) has no such requirement.
## The SPI1 and WiFi power enable pin conflict on the EVK
The Genio 720 EVK exposes SPI1 on its 40-pin header. But GPIO75 is multiplexed between `SPIM1_MO` (SPI MOSI) and `WCN_3V3_EN` (WiFi module 3.3V power enable).
If your application needs SPI1 on the 40-pin header, you must remap the WiFi power enable from GPIO75 to GPIO42 first. Without this, enabling SPI1 cuts power to the WiFi module:
1. Change the `pins_wcn_3v3_en` fixed-regulator gpio from `<&pio 75>` to `<&pio 42>`
2. Update the pinctrl group to use `PINMUX_GPIO42__FUNC_GPIO42`
3. Add a gpio-hog node for GPIO42
This is EVK-specific. Custom carrier boards don't inherit this conflict, they define their own pinmux from scratch.
## PMIC timing: MT6390 vs MT6357
The Genio 720-class boards use MT6365 as the main PMIC (11 buck converters, 33 LDOs, 26MHz XO reference clock, 32kHz RTC). For GPU or custom power rails, an optional MT6691 auxiliary DC-DC provides additional I2C-programmable power.
MT6390 is pin-compatible with MT6357 and looks like a drop-in substitute. It's not, they have different power-on timing. MT6390 regulators become ready earlier in the power-on sequence, and sequences written for MT6357 hang on MT6390. The failure mode looks like the SoC never getting past BL2.
If you're substituting MT6390 on a design that was validated with MT6357, verify every timing assumption against the MT6390 datasheet before committing.
## Genio 360 audio gotcha
Genio 510/700/520/720 use SOF (Sound Open Firmware) for the ARM DSP audio path. Genio 360 is different, in the current BSP, the SCP and SOF firmware are commented out in the SOC include:
```bitbake
# Temporarily removed:
# linux-firmware-mt8188-scp
# linux-firmware-mt8188-sof
```
Audio SOF is not functional on Genio 360 in the current public BSP. If your product requires audio on Genio 360, verify SOF status against the current BSP release before committing to that platform.
## Three machines, one config, and what that means for custom boards
Genio 420 (MT8371LV), 520 (MT8371), and 720 (MT8391) all use the same Yocto machine configurations (`genio-720-evk`, etc.) and are pin-to-pin compatible. A design validated on Genio 720 hardware can be binned down to Genio 520 for cost reduction without a PCB respin, the Yocto machine config doesn't change; the bootloader detects the chip ID at runtime.
The LPDDR tradeoff: Genio 520 supports LPDDR4X (up to 8GB at 4266 Mbps) in addition to LPDDR5, while Genio 720 requires LPDDR5X. If BOM cost matters and 16GB RAM isn't required, Genio 520 with LPDDR4X can save meaningful cost without sacrificing NPU capability, the MDLA hardware is identical across all three.
We've brought up Genio 520, 700, 720, and 1200 on custom carrier boards at [ProventusNova](/get-expert-mediatek-genio-support). The hardware design issues above account for the majority of first-boot failures we see.
## Frequently Asked Questions
### Does MediaTek Genio 720 have HDMI output?
No. Genio 520 and Genio 720 have no HDMI interface, only DisplayPort over Type-C (DPoC). Load `display-dpoc.dtbo`. This applies to MT8391, MT8371, and MT8371LV.
### Why do recipes fail when building for Genio 510 in Yocto?
Genio 510 (MT8370) uses MT8188 GPU, VPU, and ISP hardware internally. Recipes must map mt8370 to mt8188 for firmware and daemon recipes. Same for Genio 700 (MT8390 uses mt8188).
### Are Genio 520 and Genio 720 pin-compatible?
Yes. MT8391, MT8371, and MT8371LV share the same VFBGA footprint and Yocto machine configs. MT8395 (Genio 1200) uses a different package and is not pin-compatible.
### Can I substitute MT6390 for MT6357 PMIC?
MT6390 is pin-compatible but has different power-on timing. Sequences that work with MT6357 hang with MT6390. Verify all power sequencing assumptions against the MT6390 datasheet.
### What strapping resistors are required for Genio boot?
External 12 kΩ pull-up or pull-down resistors on all boot mode strapping pins. Boot mode is latched on RESETB rising edge. Floating pins produce random boot mode selection.
---
## Jetson remote desktop: NoMachine, VNC, xrdp & headless
URL: https://proventusnova.com/blog/jetson-remote-desktop-nomachine-vnc-headless-setup/
Published: 2026-04-03
Author: Andres Campos
Tags: jetson, remote desktop, nomachine, headless, linux, jetson nano
Set up NoMachine, VNC, or xrdp on any NVIDIA Jetson. Includes the JetPack 6 Wayland fix, headless display setup, persistent service config, and firewall ports.
Running Jetson Orin headless for development or remote access requires choosing the right remote desktop stack, and the choice matters for GPU-accelerated applications. NoMachine, VNC, and X forwarding each have different performance characteristics and configuration requirements on Jetson. This post covers the setup and what to expect from each.
## How to install NoMachine on Jetson Orin
To install the latest NoMachine on Jetson Orin: go to [nomachine.com/download](https://www.nomachine.com/download), select **Linux → ARM (64-bit) → DEB**, download the package to your Jetson, and run `sudo dpkg -i nomachine_*.deb`. The NX server starts automatically after install with no additional configuration. On JetPack 6 (Wayland), set `WaylandEnable=false` in `/etc/gdm3/custom.conf` and restart GDM3 before connecting. Connect from any NoMachine client using the Jetson's IP address and your Linux username and password.
## Key Insights
- **NoMachine is the best Jetson remote desktop option**, install the ARM64 DEB from nomachine.com and the NX server starts automatically; no configuration needed
- **Headless without a monitor:** an HDMI dummy plug (~$5) is the fastest fix; for software-only, use `xserver-xorg-video-dummy` with a virtual screen config
- **JetPack 6 ships with Wayland by default**, you must set `WaylandEnable=false` in `/etc/gdm3/custom.conf` before NoMachine will connect
- **VNC is noticeably slower on WiFi**, use `-depth 16` to cut bandwidth roughly in half; for anything beyond occasional access, NoMachine is worth the extra setup
- **SSH X11 forwarding is not a full remote desktop**, use it for launching single apps like `jtop`, not for a full session
## Which remote desktop option actually works on Jetson?
There are three real options: NoMachine (NX protocol), VNC, and SSH X11 forwarding. Each has a different sweet spot.
| Method | Protocol | Performance | Headless support | Best for |
|--------|----------|-------------|-----------------|----------|
| NoMachine | NX | Excellent | Yes (with dummy display) | Daily dev work |
| TigerVNC | RFB | Moderate | Yes (Xvfb or dummy plug) | Occasional access |
| SSH X11 | X11 over SSH | Poor for GUI-heavy | No | Running single apps |
NoMachine wins for regular development. VNC is fine if you only connect occasionally and have a decent network. SSH X11 forwarding is useful for launching a specific GUI tool, not for a full desktop session.
## How to install NoMachine on Jetson Orin and Nano
NoMachine provides an ARM64 DEB that installs cleanly on all current Jetson modules. Go to [nomachine.com/download](https://www.nomachine.com/download), select Linux, ARM (64-bit), DEB format, and grab the package.
```bash
# Transfer to Jetson (or download directly on the device)
scp nomachine_*.deb user@jetson-ip:/home/user/
# Install
sudo dpkg -i nomachine_*.deb
```
The NX server starts automatically after install. Verify it's running:
```bash
sudo /usr/NX/bin/nxserver --status
```
On your laptop, install the NoMachine client for macOS or Windows from the same download page. Open it, click New, enter your Jetson's IP, and connect with your Linux username and password. The free tier covers everything you need for development.
**JetPack 6 Wayland issue:** JetPack 6 ships with GDM3 running Wayland by default. NoMachine expects an X session. Check what you're running:
```bash
echo $XDG_SESSION_TYPE
```
If it says `wayland`, edit GDM3's config. (If you've run into other JetPack 6 surprises during bring-up, the [JetPack 6 USB enumeration failure post](/blog/jetpack-6-usb-enumeration-failure-fix) covers another common one we see in the field.)
```bash
sudo nano /etc/gdm3/custom.conf
```
Under `[daemon]`, add or uncomment:
```ini
[daemon]
WaylandEnable=false
```
Then restart GDM3:
```bash
sudo systemctl restart gdm3
```
Now `echo $XDG_SESSION_TYPE` should return `x11`. Reconnect with NoMachine and you'll have a full desktop.
## Setting up a Jetson headless without a monitor
This is where most people get stuck. NVIDIA's GPU driver needs a valid display signal to initialize. Without a monitor, X won't start, and NoMachine has nothing to connect to.
**Option 1: HDMI dummy plug (recommended)**
A ~$5 HDMI dummy plug from Amazon tricks the GPU into thinking a monitor is connected. It provides a fake EDID, the driver initializes normally, and X starts without any configuration changes.
Plug it in before booting. That's it. This is what we use on all our development rigs.
**Option 2: Software virtual display**
If you can't use a dummy plug, install the Xorg dummy driver:
```bash
sudo apt install xserver-xorg-video-dummy
```
Create a virtual screen config:
```bash
sudo nano /etc/X11/xorg.conf.d/20-dummy.conf
```
```
Section "Device"
Identifier "Dummy Device"
Driver "dummy"
VideoRam 256000
EndSection
Section "Screen"
Identifier "Dummy Screen"
Device "Dummy Device"
Monitor "Dummy Monitor"
DefaultDepth 24
SubSection "Display"
Depth 24
Modes "1920x1080"
EndSubSection
EndSection
Section "Monitor"
Identifier "Dummy Monitor"
HorizSync 28.0-80.0
VertRefresh 48.0-75.0
Modeline "1920x1080" 148.50 1920 2008 2052 2200 1080 1084 1089 1125 +hsync +vsync
EndSection
```
**JetPack 6 note:** If there's already an `/etc/X11/xorg.conf` at the root level, it conflicts with the `.d/` directory config. Rename it first:
```bash
sudo mv /etc/X11/xorg.conf /etc/X11/xorg.conf.backup
```
Reboot, and the dummy display will come up instead.
## Setting up VNC on Jetson
VNC works, but it's slower than NoMachine because it copies raw framebuffer data over the network. On WiFi, the lag becomes noticeable quickly.
Install TigerVNC:
```bash
sudo apt install tigervnc-standalone-server tigervnc-common
```
Set a VNC password:
```bash
vncpasswd
```
Start the VNC server. The `:1` means display 1 (port 5901):
```bash
vncserver :1 -geometry 1920x1080 -depth 16
```
Using `-depth 16` instead of 24 cuts bandwidth roughly in half, a meaningful difference on slower connections.
To stop the server:
```bash
vncserver -kill :1
```
For persistent VNC across reboots, create a systemd service. Connect from any VNC client (RealVNC Viewer, TigerVNC Viewer) to `jetson-ip:5901`.
**When VNC makes sense:** You have gigabit ethernet and connect rarely. For anything beyond occasional access, the NoMachine setup is worth the extra 10 minutes.
## How to make VNC start automatically on boot
VNC doesn't persist across reboots by default, you have to start it manually each time. The fix is a systemd service.
Create the service file:
```bash
sudo nano /etc/systemd/system/vncserver@.service
```
Paste this, replacing `your-username` with your actual Linux username:
```ini
[Unit]
Description=TigerVNC server
After=syslog.target network.target
[Service]
Type=forking
User=your-username
PAMName=login
PIDFile=/home/your-username/.vnc/%H%i.pid
ExecStartPre=/bin/sh -c '/usr/bin/vncserver -kill :%i > /dev/null 2>&1 || :'
ExecStart=/usr/bin/vncserver :%i -geometry 1920x1080 -depth 16 -localhost no
ExecStop=/usr/bin/vncserver -kill :%i
[Install]
WantedBy=multi-user.target
```
Enable and start it on display `:1` (port 5901):
```bash
sudo systemctl daemon-reload
sudo systemctl enable vncserver@1
sudo systemctl start vncserver@1
```
Check that it's running:
```bash
sudo systemctl status vncserver@1
```
VNC will now start automatically after every reboot. To stop it manually: `sudo systemctl stop vncserver@1`.
## How to set up xrdp on Jetson (Windows Remote Desktop)
xrdp lets you connect to Jetson using the Windows built-in Remote Desktop client, no third-party software needed on your Windows machine. It's the easiest option if your team is mostly on Windows.
Install xrdp:
```bash
sudo apt install xrdp
sudo systemctl enable --now xrdp
```
That's it. On Windows, open Remote Desktop Connection (`Win + R`, type `mstsc`), enter your Jetson's IP address, and click Connect. Log in with your Linux username and password.
**JetPack 6 Wayland note:** xrdp also requires an X session. If you haven't already disabled Wayland for NoMachine, do it now:
```bash
sudo nano /etc/gdm3/custom.conf
# Add under [daemon]:
# WaylandEnable=false
sudo systemctl restart gdm3
```
**Desktop environment note:** On a fresh JetPack install, xrdp sometimes opens to a blank grey screen. If that happens, create a session config:
```bash
echo "startxfce4" > ~/.xsession
chmod +x ~/.xsession
sudo systemctl restart xrdp
```
If you don't have Xfce installed: `sudo apt install xfce4 xfce4-goodies`. Xfce is lightweight and works reliably over xrdp on Jetson.
**Comparison: xrdp vs NoMachine vs VNC**
| | xrdp (RDP) | NoMachine (NX) | VNC |
|--|------------|----------------|-----|
| Windows client | Built-in (mstsc) | Download required | Download required |
| macOS client | Microsoft RD app | NoMachine client | Built-in Screen Sharing |
| Protocol efficiency | Good | Excellent | Poor |
| GPU app support | Limited | Good | Limited |
| Setup time | ~5 min | ~10 min | ~10 min |
xrdp is the fastest to set up for Windows users and good enough for most development tasks. NoMachine is better for anything GPU-accelerated or where you need low latency.
## SSH X11 forwarding
This isn't a full remote desktop. It lets you run individual GUI apps on the Jetson and have their windows appear on your laptop, useful for `jtop` with a GUI, or a quick `gedit` session.
On the Jetson, enable X11 forwarding in SSH:
```bash
sudo nano /etc/ssh/sshd_config
```
Find or add:
```
X11Forwarding yes
X11DisplayOffset 10
X11UseLocalhost yes
```
Restart SSH:
```bash
sudo systemctl restart ssh
```
Connect from your laptop:
```bash
# Linux
ssh -X user@jetson-ip
# macOS, requires XQuartz (xquartz.org) installed
ssh -Y user@jetson-ip # -Y for trusted forwarding, avoids permission errors
```
Then launch any GUI app:
```bash
jtop # or gedit, or anything else
```
The app window opens on your laptop. Performance is slow for anything graphical, stick to lightweight tools.
## Firewall ports for Jetson remote desktop
If you have `ufw` enabled on your Jetson, remote desktop connections will be silently blocked until you open the right ports. Check if ufw is active:
```bash
sudo ufw status
```
Open the ports you need:
```bash
# NoMachine (NX protocol)
sudo ufw allow 4000/tcp
# VNC (display :1 = port 5901, :2 = 5902, etc.)
sudo ufw allow 5901/tcp
# xrdp (RDP)
sudo ufw allow 3389/tcp
# SSH (if not already open)
sudo ufw allow 22/tcp
```
Apply the changes:
```bash
sudo ufw reload
```
Fresh JetPack installs usually have ufw inactive, but if you've hardened the system or are using a custom carrier board image, this is the first thing to check when a connection fails.
## Troubleshooting: can't connect to Jetson remote desktop
**NoMachine says "connection refused" or times out**
- Verify the NX server is running: `sudo /usr/NX/bin/nxserver --status`
- If it's stopped: `sudo /usr/NX/bin/nxserver --startup`
- On JetPack 6, confirm you've disabled Wayland and restarted GDM3
- Check that port 4000 is open if ufw is active
**VNC connects but shows a blank or black screen**
- The X server isn't running. Plug in an HDMI dummy plug or configure the software dummy display (see the headless section above)
- Check if X is running: `ps aux | grep Xorg`
- Try starting VNC on a different display: `vncserver :2`
**xrdp shows a grey screen after login**
- Missing desktop environment in the xrdp session. Create `~/.xsession` with `startxfce4` and restart xrdp
- Confirm Wayland is disabled in `/etc/gdm3/custom.conf`
**"Connection refused" on the right port**
- Confirm the service is running: `sudo systemctl status nomachine` / `vncserver@1` / `xrdp`
- Confirm the Jetson's IP hasn't changed, check with `ip addr show` or `hostname -I`
- Ping the Jetson first (`ping jetson-ip`) to rule out a network issue
**Slow or laggy remote desktop**
- Switch from VNC to NoMachine or xrdp
- On VNC, use `-depth 16` instead of 24
- Connect over ethernet instead of WiFi if possible
- Lower the remote desktop resolution in the client
If you're running a custom carrier board and hitting unexplained connectivity issues at the OS level, it's sometimes a deeper bring-up problem. We've seen cases where network drivers behave differently on custom hardware vs. the devkit. The [NVIDIA Jetson expert support page](/get-expert-nvidia-jetson-support) covers what that kind of engagement looks like.
## JetPack version notes
The setup differs slightly depending on which JetPack you're running. Check yours with:
```bash
cat /etc/nv_tegra_release
```
- **JetPack 5.x (Orin, Xavier):** Xorg by default. NoMachine installs and connects without the Wayland step.
- **JetPack 6.x (Orin):** GDM3 + Wayland by default. Add `WaylandEnable=false` to `/etc/gdm3/custom.conf` before connecting with NoMachine.
- **JetPack 4.x (Nano, Xavier NX):** Xorg. Same as JP5. Check `/etc/gdm3/custom.conf` to confirm Wayland isn't enabled.
NVIDIA's [JetPack SDK documentation](https://developer.nvidia.com/embedded/jetpack) has the full release notes for each version if you need to verify what's included in your specific build. If you're also debugging a carrier board that won't boot, our [Jetson carrier board boot troubleshooting guide](/blog/jetson-carrier-board-not-booting-root-causes) covers the six root causes we see most often.
---
## DWC3 error -71 on Jetson: the JetPack 6 clock reference fix
URL: https://proventusnova.com/blog/dwc3-error-71-jetson-clock-reference-fix/
Published: 2026-03-31
Author: Aaron Angulo
Tags: jetson, usb, dwc3, jetpack 6, bsp, device tree
dwc3 error -71 on Jetson Orin under JetPack 6 means a missing ref clock in the device tree. Here's the exact dmesg pattern, why it regressed in L4T R36.
Error 71 in the DWC3 USB driver on Jetson is one of those failures that looks like a driver bug until you check the hardware. The root cause is almost always a clock reference problem, either the wrong source is selected in the DTS or the reference clock is missing from the carrier board design. Here is how to find which one you are looking at.
## Key Insights
- `dwc3: probe of 3610000.xhci failed with error -71` means the DWC3 USB controller couldn't acquire its `ref` clock during driver probe, USB is completely dead
- L4T R36 (JetPack 6) made the `ref` clock mandatory; L4T R35 (JetPack 5) treated it as optional, so device trees ported from JP5 don't include it
- The fix is a device tree change, add `TEGRA234_CLK_CLK_M` as `ref` to the `xhci@3610000` node; no kernel rebuild required
- Custom carrier board DTS files and vendor BSPs are the most common source of the missing clock entry
- We've applied this fix three times this year across Orin NX, Orin Nano, and a custom board with a six-level-deep vendor DTS
## What DWC3 error -71 actually means on Jetson
When your Jetson shows this in dmesg:
```
[ 4.83] dwc3 3610000.xhci: Failed to get clk ref
[ 4.84] dwc3: probe of 3610000.xhci failed with error -71
```
USB is dead. Not intermittent, not degraded, dead. No enumeration happens because the DWC3 host controller never completed its probe sequence. `lsusb` returns nothing. `/dev/bus/usb/` is empty. Any USB peripheral you plug in does nothing.
Error -71 is Linux `EPROTONOSUPPORT`. In this context it's a driver probe failure: the DWC3 driver tried to get the `ref` clock handle, the clock framework said it doesn't exist in the device tree, and the driver bailed out.
The `3610000` address is the USB3/xHCI controller on Orin NX and Orin Nano. On AGX Orin you'll see a different address but the same error pattern. If you're on Thor (T5000) the clock tree is different enough that the fix path diverges, we'll cover that at the end.
## Why DWC3 error -71 regressed in JetPack 6
JetPack 5 ran on L4T R35.x. JetPack 6 runs on L4T R36.x. NVIDIA made significant changes to the USB subsystem in this transition, and one of them bit a lot of custom carrier board teams.
In L4T R35, the `ref` clock in the DWC3 driver was optional. The driver would attempt to get it, and if it failed, it would log a debug message and keep going. In L4T R36, that changed: the driver now returns `-EPROTONOSUPPORT` and aborts probe if the clock isn't found.
NVIDIA updated their reference DTS files alongside the driver, so teams on standard devkits never saw this. Custom carrier board teams are a different story:
- If you ported your JP5 DTS to JP6 without checking the USB clock entries, you hit this immediately
- If you're on a carrier board vendor BSP that hasn't been updated for JP6, same problem
- Orin NX and Nano teams are disproportionately affected because their reference boards are newer designs and some vendor SDKs still ship older DTS derivations
We saw this on three separate engagements in the past year, each time the team had a working JP5 setup and hit the wall when they tried to move to JP6.
## How to diagnose DWC3 error -71 on Jetson Orin
Run this from the Jetson (or from serial console if USB is completely dead):
```bash
# Confirm the probe failure
sudo dmesg | grep -E "(dwc3|xhci|usb)" | head -40
# Look for the specific error pair
sudo dmesg | grep "Failed to get clk"
sudo dmesg | grep "probe of.*failed with error -71"
```
If you see:
```
[ 4.83] dwc3 3610000.xhci: Failed to get clk ref
[ 4.84] dwc3: probe of 3610000.xhci failed with error -71
```
That's your bug. You don't need to look further.
If USB is working but flaky, or if you see `Set TR Deq Ptr cmd failed` instead, you're on a different failure path, those are xHCI command timeout errors and have a separate diagnosis.
Also confirm you're on L4T R36 and check your active DTS:
```bash
# Confirm JetPack version
cat /etc/nv_tegra_release
# Find your active DTB
cat /proc/device-tree/nvidia,dtsfilename 2>/dev/null || ls /boot/*.dtb | head -5
```
If you're on L4T R36 and the DTS file predates L4T R36, you're almost certainly hitting the missing clock.
## The device tree fix
The fix is in the USB controller's DTS node. You need to add the `ref` clock entry.
Find your device tree source. On Orin NX or Orin Nano with a custom carrier board, you'll have a top-level DTS that includes the SoC dtsi. The USB controller node looks something like this (missing the `ref` clock):
```dts
/* Before, missing ref clock */
xhci@3610000 {
clocks = <&bpmp TEGRA234_CLK_XUSB_CORE_SS_DEV>,
<&bpmp TEGRA234_CLK_XUSB_CORE_DEV>,
<&bpmp TEGRA234_CLK_XUSB_FALCON_DEV>,
<&bpmp TEGRA234_CLK_XUSB_FS_DEV>;
clock-names = "ss_src", "hs_src", "fs_src", "falcon_host";
};
```
Add `CLK_M` (the 38.4 MHz crystal reference clock) as the `ref` entry:
```dts
/* After, with ref clock */
xhci@3610000 {
clocks = <&bpmp TEGRA234_CLK_XUSB_CORE_SS_DEV>,
<&bpmp TEGRA234_CLK_XUSB_CORE_DEV>,
<&bpmp TEGRA234_CLK_XUSB_FALCON_DEV>,
<&bpmp TEGRA234_CLK_XUSB_FS_DEV>,
<&bpmp TEGRA234_CLK_CLK_M>;
clock-names = "ss_src", "hs_src", "fs_src", "falcon_host", "ref";
};
```
After the patch, compile and deploy:
```bash
# In your L4T build tree
make dtbs
# Copy new DTB to target
scp tegra234-p3767-xxxx.dtb user@jetson:/boot/
# Reboot and confirm
sudo reboot
sudo dmesg | grep "Failed to get clk" # Should return nothing
lsusb # Should show your devices
```
If your DTS already has clock entries but you're still getting error -71, the clock name might differ. Check the L4T R36 reference DTS for your SoC under `hardware/nvidia/platform/t23x/` for the exact clock names NVIDIA uses in the updated reference.
## When the DTS patch isn't enough
The two-line fix above handles the straightforward case. It gets more complicated when:
**You're on a carrier board vendor BSP.** The vendor's DTS may override the USB node in ways that conflict with your patch. You'll need to trace the full DTS include chain to find where the clock entries live and which override wins. Depending on how the vendor structured their BSP, this can take a few hours.
**You're using device tree overlays (DTBOs).** Overlays can fail to apply correctly if phandle structures changed between L4T versions. The overlay may look correct but silently not patch the right node.
**USB works after the fix but drops under load.** That's a separate failure mode, typically missing or mismatched firmware (`xusb_sil_rel_fw.bin`), PCIe spread-spectrum clocking conflicts, or VBUS power sequencing on your carrier board. The clock fix just gets probe to succeed; runtime stability is a different problem.
**You're on Jetson Thor (T5000).** Same error code, different clock tree. The fix path exists but it's more involved.
We've resolved this exact error three times in the past year, on Orin NX, Orin Nano, and once on a carrier board with a vendor BSP that had layered DTS overrides six levels deep. If you're past the self-service path, [book a 30-minute scoping call](https://proventusnova.com/get-expert-nvidia-jetson-support) and we'll scope it out.
For related Jetson USB debugging, see our post on [JetPack 6 USB enumeration failure](/blog/jetpack-6-usb-enumeration-failure-fix) which covers the broader class of USB bring-up issues on Orin. For the full JetPack 5 to 6 DTS migration scope, see [what breaks when upgrading from JetPack 5 to 6](/blog/jetpack-5-to-6-upgrade-what-breaks).
The upstream DWC3 driver behavior is documented in the [Linux kernel DWC3 driver source](https://github.com/torvalds/linux/blob/master/drivers/usb/dwc3/dwc3-of-simple.c). NVIDIA's L4T-specific changes are tracked in the [NVIDIA Jetson Linux release notes](https://developer.nvidia.com/embedded/jetson-linux-r3621).
---
---
## Yocto for MediaTek Genio: meta-mediatek-bsp setup guide
URL: https://proventusnova.com/blog/yocto-mediatek-genio-meta-mediatek-bsp/
Published: 2026-03-30
Author: Andres Campos
Tags: mediatek, genio, yocto, meta-mediatek-bsp, bsp, embedded linux
Yocto for MediaTek Genio using meta-mediatek-bsp. Layer setup, machine configs, NDA vs public BSP, RITY OS reference distro, and the multimedia stack.
MediaTek's official Yocto BSP for Genio is `meta-mediatek-bsp`, hosted on GitLab and tracking the `scarthgap` branch. It ships with the RITY reference distribution, 27 machine configurations, and support for both public and NDA-gated camera stacks. Knowing which parts require NDA access and which don't is the first thing to sort out before starting a Genio Yocto project.
## Key Insights
- The BSP layer is at `gitlab.com/mediatek/aiot/bsp/meta-mediatek-bsp.git`, `scarthgap` branch. RITY reference distro is at `gitlab.com/mediatek/aiot/rity/meta-rity.git`.
- Start with `rity-bringup` (minimal, no audio server), move to `rity-demo` for development, use `rity-skeleton` as your production starting point.
- `NDA_BUILD = "1"` unlocks the proprietary camera ISP stack on Genio 510, 700, and 1200 only, Genio 520 and 720 use V4L2 exclusively, no NDA camera path exists for those platforms.
- `MALI_SOC = "mt8189"` for Genio 720, the GPU hardware inside MT8391 is identified as mt8189 internally. Custom GPU recipes must use this name, not mt8391.
- Genio 520 and 720 are the only Genio platforms with ONNX Runtime NPU acceleration (MDLA) on by default. Other platforms require `ENABLE_NEURON_EP = "1"` in `local.conf`.
## Layer setup and dependencies
The meta-mediatek-bsp layer identity:
```bitbake
BBFILE_COLLECTIONS = "mediatek-bsp"
BBFILE_PRIORITY = 7
LAYERVERSION = 1
LAYERSERIES_COMPAT = "scarthgap"
LAYERDEPENDS = "core openembedded-layer meta-python meta-arm"
```
Optional multimedia integration via dynamic layers:
```bitbake
BBFILES_DYNAMIC += "multimedia-layer:${LAYERDIR}/dynamic-layers/multimedia-layer/*/*/*.bbappend"
```
Key URIs:
```bitbake
AIOT_URI = "git://git@gitlab.com/mediatek/aiot"
AIOT_BSP_URI = "${AIOT_URI}/bsp"
AIOT_NDA_URI = "${AIOT_URI}/nda" # NDA access required
NDA_BUILD = "0" # Set to "1" to unlock NDA recipes
```
Setting `NDA_BUILD = "1"` auto-enables the NDA distro feature and unlocks the proprietary camera stack for supported platforms.
## Machine configurations
The BSP ships 27 machine configurations:
```
conf/machine/
├── genio-360-evk.conf (mt8366)
├── genio-510-evk.conf (mt8370)
├── genio-700-evk.conf (mt8390)
├── genio-720-evk.conf (mt8391)
├── genio-1200-evk.conf (mt8395)
├── *-norboot.conf (SPI NOR flash boot variants)
└── include/
├── mediatek-common.inc
├── gpu-provider.inc (Mali vs Panfrost selection)
├── mt8391.inc (Genio 720 SoC include)
├── mt8395.inc (Genio 1200 SoC include)
├── mt7921.inc (WiFi 6 module)
└── mt7925.inc (WiFi 7 module)
```
Each SoC include defines the critical platform variables:
```bitbake
# genio-720-evk (MT8391) example
SOC_FAMILY = "mt8391"
SOC_SRAM_ADDR = "0x2001000"
TFA_PLATFORM = "mt8391"
OPTEE_TARGET = "mediatek-mt8391"
OPTEE_DRAM_SIZE = "0x200000000"
MALI_SOC = "mt8189" # GPU internal name, not mt8391
LK_PROJECT = "genio_720_evk"
```
Note `MALI_SOC = "mt8189"` for Genio 720. The Mali GPU hardware inside MT8391 is identified as mt8189 internally. Custom recipes targeting GPU support must use `mt8189`, not `mt8391`. This is the naming trap explained in the [Genio hardware design gotchas post](/blog/mediatek-genio-hardware-design-gotchas).
## RITY OS, the reference distro
RITY is MediaTek's reference AIoT distribution. Source: `gitlab.com/mediatek/aiot/rity/meta-rity.git`.
| Distro variant | Purpose | Key additions |
|----------------|---------|---------------|
| `rity-bringup` | Minimal dev/debug | `bringup fwupdate` features, no audio |
| `rity-demo` | Full-featured development | PipeWire, Chromium, AI/ML, TSN, Wayland |
| `rity-demo-panfrost` | Open GPU variant | Panfrost Mesa driver, OpenCL via Mesa |
| `rity-skeleton` | Custom derivative template | Minimal, meant to be copied and modified |
Start with `rity-bringup`, fastest path to a bootable console image. Move to `rity-demo` for development. Use `rity-skeleton` as your production starting point.
`rity-demo-panfrost` substitutes the open-source Panfrost driver for the proprietary Mali binary. Performance is lower, but the licensing is clean for products that can't ship the Mali userspace.
## Kernel development workflow
```bash
# Build kernel for a specific board
MACHINE=genio-720-evk bitbake linux-mtk
# Flash kernel partition
genio-flash kernel
# Flash kernel + modules when modimg is enabled
genio-flash kernel modules
```
Kernel config fragments live in `src/meta-mediatek-bsp/recipes-kernel/linux/linux-mtk/`, one per SoC and one per board. To enable a config option:
```
# Enable USB FunctionFS in mt8365.cfg
CONFIG_USB_FUNCTIONFS=m
CONFIG_USB_FUNCTIONFS_GENERIC=y
```
For larger kernel changes, use `devtool modify linux-mtk`, it creates a local checkout linked to the build system.
## Camera: V4L2 vs NDA ImgSensor
| Platform | V4L2 | NDA ImgSensor (`camd.service`) |
|----------|------|--------------------------------|
| Genio 350 | Yes | No |
| Genio 510 / 700 | Yes | Yes (NDA required) |
| Genio 520 / 720 | Yes (only) | No path available |
| Genio 1200 | Yes | Yes (NDA required) |
V4L2 through the SENINF/CAMSV pipeline works on all platforms. The NDA ImgSensor stack gives access to MediaTek's proprietary ISP tuning on G510/G700/G1200, but requires an active NDA with MediaTek.
One important caveat for Genio 520/720 (added to Yocto BSP in v25.1, December 2025): the ISP hardware pipeline is not yet functional. MIPI-CSI transfers sensor data but full ISP processing is pending. Raw V4L2 capture works; ISP-processed frames do not. Check the current BSP release notes before designing a product around ISP on these platforms.
## AI inference on Yocto
| Platform | TFLite CPU/GPU | TFLite Neuron Stable Delegate | ONNX NeuronEP (NPU) |
|----------|---------------|-------------------------------|----------------------|
| Genio 350 | Yes | No | No |
| Genio 510/700 | Yes | Yes | Opt-in |
| Genio 1200 | Yes | Yes | Opt-in |
| Genio 520/720 | Yes | Yes | Yes (default) |
For Genio 510/700/1200, enable NeuronExecutionProvider with `ENABLE_NEURON_EP = "1"` in `local.conf`. For Genio 520/720, it's on by default, they're the only Genio platforms with ONNX Runtime NPU acceleration out of the box.
Generative AI (LLM inference via TFLite/LiteRT) on Yocto: available now on Genio 720, expected Q2 2026 on Genio 520. On Android, it runs on both today.
We handle Genio Yocto BSP bring-up as part of engagements at [ProventusNova](/get-expert-mediatek-genio-support), from initial layer setup through camera drivers and AI inference integration.
## Frequently Asked Questions
### Where can I find the MediaTek Genio Yocto BSP layer?
At `gitlab.com/mediatek/aiot/bsp/meta-mediatek-bsp.git`. Requires `scarthgap`. The RITY reference distro is at `gitlab.com/mediatek/aiot/rity/meta-rity.git`.
### What does NDA_BUILD do in the MediaTek Genio BSP?
Setting `NDA_BUILD = "1"` unlocks proprietary camera ISP and other NDA-only components, only functional on Genio 510, 700, and 1200. Genio 520/720 use V4L2 only.
### Which Yocto image should I start with for MediaTek Genio?
`rity-bringup` for initial bring-up. `rity-demo` for full development. `rity-skeleton` as your production template.
### How do I build and flash just the kernel on MediaTek Genio?
`MACHINE=genio-720-evk bitbake linux-mtk` to build, `genio-flash kernel` to flash. Add `modules` if you have a separate module partition.
### Does the ISP hardware pipeline work on Genio 520 and 720?
Not in the current public BSP (v25.1.x). MIPI-CSI sensor data transfer works; full ISP processing is pending a future release.
---
## JetPack versions and L4T compatibility: complete reference table
URL: https://proventusnova.com/blog/jetpack-versions-l4t-compatibility-table/
Published: 2026-03-27
Author: Aaron Angulo
Tags: jetpack, l4t, jetson, cuda, tensorrt, version compatibility
Complete JetPack version to L4T, CUDA, TensorRT, and supported module reference table. Includes how to check your running version and key differences.
To check which JetPack version is running on your Jetson right now, run `cat /etc/nv_tegra_release` and cross-reference the L4T r-number against the table below. Matching your JetPack version to the right L4T BSP, kernel, and CUDA toolkit is the first thing to get right, and the compatibility matrix is not always obvious from the NVIDIA documentation. A JetPack mismatch or L4T version conflict is a common cause of driver failures and flash issues that look like hardware problems.
## Key Insights
- **To check your JetPack version, run `cat /etc/nv_tegra_release`**, the L4T r-number it prints (e.g., r36.3.x) maps directly to a JetPack version in the table below
- **L4T is the BSP inside JetPack**, the r-number uniquely identifies the BSP version; the JetPack number is the bundled SDK on top
- **Jetson Nano (2019) only goes up to JetPack 4.6.4**, JetPack 5 and 6 don't support it; the newer Orin Nano does support JetPack 6
- **There is no in-place upgrade between major JetPack versions**, going from JP5 to JP6 requires a full reflash via SDK Manager
- **JetPack 6 dropped Xavier support**, if you're on AGX Xavier or Xavier NX, JP5.1.x is your latest option
- **JetPack 6 uses Wayland by default**, which breaks some tools that expect Xorg, the [remote desktop setup guide](/blog/jetson-remote-desktop-nomachine-vnc-headless-setup) covers the fix
## How to check your JetPack and L4T version
The fastest way is to read the L4T release file directly:
```bash
cat /etc/nv_tegra_release
```
Output looks like:
```
# R36 (release), REVISION: 3.0, GCID: 36382493, BOARD: generic, EABI: aarch64,
# DATE: Wed Oct 23 22:17:48 UTC 2024
```
`R36` with revision `3.0` means L4T r36.3.0, which corresponds to JetPack 6.1. Cross-reference with the table below.
To check if the full JetPack SDK was installed:
```bash
dpkg -l | grep nvidia-jetpack
# or
pip3 show jetpack 2>/dev/null | grep Version
```
To get the CUDA version specifically:
```bash
nvcc --version
# or
cat /usr/local/cuda/version.txt
```
## Complete JetPack version reference table
| JetPack | L4T | CUDA | TensorRT | cuDNN | Python | Supported modules |
|---|---|---|---|---|---|---|
| 6.2 | r36.4.x | 12.6 | 10.3 | 9.x | 3.10 | AGX Orin, Orin NX, Orin Nano |
| 6.1 | r36.3.x | 12.4 | 10.3 | 9.x | 3.10 | AGX Orin, Orin NX, Orin Nano |
| 6.0 | r36.2.x | 12.2 | 10.x | 8.9 | 3.10 | AGX Orin, Orin NX, Orin Nano |
| 5.1.4 | r35.6.x | 11.4 | 8.6 | 8.6 | 3.8 | AGX Orin, Orin NX, AGX Xavier, Xavier NX |
| 5.1.3 | r35.5.x | 11.4 | 8.6 | 8.6 | 3.8 | AGX Orin, Orin NX, AGX Xavier, Xavier NX |
| 5.1.2 | r35.4.x | 11.4 | 8.6 | 8.6 | 3.8 | AGX Orin, Orin NX, AGX Xavier, Xavier NX |
| 5.1.1 | r35.3.x | 11.4 | 8.6 | 8.6 | 3.8 | AGX Orin, Orin NX, AGX Xavier, Xavier NX |
| 5.1 | r35.2.x | 11.4 | 8.5 | 8.6 | 3.8 | AGX Orin, AGX Xavier, Xavier NX |
| 5.0.2 | r35.1.x | 11.4 | 8.4 | 8.4 | 3.8 | AGX Orin, AGX Xavier, Xavier NX |
| 4.6.4 | r32.7.4 | 10.2 | 8.x | 8.x | 3.6 | Nano (4GB/2GB), AGX Xavier, Xavier NX, TX2 |
| 4.6.3 | r32.7.3 | 10.2 | 8.x | 8.x | 3.6 | Nano (4GB/2GB), AGX Xavier, Xavier NX, TX2 |
| 4.6.2 | r32.7.2 | 10.2 | 8.x | 8.x | 3.6 | Nano (4GB/2GB), AGX Xavier, Xavier NX, TX2 |
| 4.6.1 | r32.7.1 | 10.2 | 8.x | 8.x | 3.6 | Nano (4GB/2GB), AGX Xavier, Xavier NX, TX2 |
| 4.6 | r32.6.1 | 10.2 | 8.x | 8.x | 3.6 | Nano (4GB/2GB), AGX Xavier, Xavier NX, TX2 |
For exact minor version numbers and the full SDK component list, [NVIDIA's JetPack archive](https://developer.nvidia.com/embedded/jetpack-archive) is the authoritative source.
## What the L4T version number actually means
The format is `Rxx.y.z`:
- `R36` is the major kernel revision
- `3` is the minor release
- `.x` is the patch level
JetPack maps to L4T like this: JetPack 6.1 = L4T r36.3.x, JetPack 5.1.4 = L4T r35.6.x. NVIDIA increments the L4T minor version for each JetPack point release within a major series.
The L4T number is what matters for driver and BSP compatibility. If you're looking for a kernel module, bootloader, or board-level package, you need the L4T r-number, not the JetPack version.
## Key differences across major versions
**JetPack 4.x → 5.x**
- CUDA jumped from 10.2 to 11.4, some older CUDA code needs recompilation
- Python moved from 3.6 to 3.8, pip packages from JP4 venvs may not work
- Dropped support for Jetson Nano and TX1
- Added support for Jetson Orin
**JetPack 5.x → 6.x**
- CUDA jumped from 11.4 to 12.x, check your inference libraries' CUDA requirements
- TensorRT moved from 8.6 to 10.x, the API changed significantly between TRT 8 and 10; model conversion scripts may need updates
- Python moved from 3.8 to 3.10
- Default display server changed from Xorg to Wayland, affects remote desktop and any app that uses `DISPLAY` environment variable
- Dropped support for Xavier series
- L4T security model changed, some bootloader and secure boot workflows are different
**The Nano confusion**
NVIDIA named two very different products "Jetson Nano":
- **Jetson Nano (2019)**, ARM Cortex-A57, Maxwell GPU. Max JetPack: 4.6.4.
- **Jetson Orin Nano (2023)**, ARM Cortex-A78AE, Ampere GPU. Supports JetPack 6.x.
If you're looking at a forum thread about "Jetson Nano" and JetPack 5 or 6, they're talking about the Orin Nano, or the thread is mistaken.
## Flashing a specific JetPack version
Use SDK Manager on a Ubuntu 20.04 or 22.04 host machine. It handles the full flash sequence including bootloader, kernel, and rootfs. For headless systems or CI pipelines, the command-line flash tools under `Linux_for_Tegra/` work without a GUI:
```bash
cd Linux_for_Tegra
sudo ./flash.sh jetson-orin-nano-devkit internal
```
The target board name (`jetson-orin-nano-devkit`) must match your hardware exactly. Wrong board name → wrong devicetree → usually a boot failure. If you're hitting that, our [carrier board not booting guide](/blog/jetson-carrier-board-not-booting-root-causes) covers the devicetree mismatch case.
---
## Upgrading from JetPack 5 to JetPack 6: what breaks and how to fix it
URL: https://proventusnova.com/blog/jetpack-5-to-6-upgrade-what-breaks/
Published: 2026-03-24
Author: Aaron Angulo
Tags: jetpack, jetson, jetpack 6, migration, l4t, bsp
JetPack 5 to 6 is a full platform jump, not a package update. CUDA 11→12, cuDNN 8→9, Ubuntu 20→22, camera drivers, TRT engines, and kernel modules.
The JetPack 5 to JetPack 6 upgrade is a bigger jump than a version number suggests. The kernel moves from 5.10 to 5.15, the container runtime changes, and several BSP APIs that were stable in JetPack 5 are deprecated or removed. What breaks depends on how much custom BSP work your product has accumulated.
## Key Insights
- JetPack 5 to 6 is a full platform jump: Ubuntu 20.04 → 22.04, CUDA 11.4 → 12.6, cuDNN 8 → 9, TensorRT 8 → 10, kernel 5.10 → 5.15
- OTA from JP5 to JP6 is not supported, reflash is required
- Everything compiled against JP5 must be rebuilt: TRT engines, camera drivers, kernel modules, Python environments
- Custom camera drivers need porting, the `tegracam` sensor API changed between L4T R35 and R36
- Xavier-series modules (AGX Xavier, Xavier NX) are not supported in JetPack 6, JP5.1.x is the end of the line for Xavier
## JetPack 5 to 6 is a platform upgrade, not a package update
The version bump from 5 to 6 understates what changed. The full platform delta:
| Component | JetPack 5 (L4T R35) | JetPack 6 (L4T R36) |
|-----------|---------------------|---------------------|
| OS | Ubuntu 20.04 | Ubuntu 22.04 |
| Kernel | Linux 5.10 | Linux 5.15 |
| CUDA | 11.4 | 12.6 |
| cuDNN | 8.x | 9.x |
| TensorRT | 8.x | 10.x |
| Python (default) | 3.8 | 3.10 |
| OpenCV (bundled) | 4.5.4 | 4.8.1 |
| GStreamer | 1.16 | 1.22 |
This means OTA from JP5 to JP6 is not supported. You cannot `apt upgrade` your way there. Reflash is required. Teams that try OTA hit A/B slot errors or partial upgrades that leave the system unbootable.
Also worth knowing: JP6 dropped support for Xavier-series modules (AGX Xavier, Xavier NX). If you're on Xavier, JP5.1.x is your last JetPack.
## What still works on JetPack 6 without changes
Before the break list, here is what typically survives the migration intact. Teams that focus only on what breaks underestimate how much they do NOT need to rebuild.
**Works without changes:**
- Most GStreamer pipelines, GStreamer 1.22 is backwards-compatible with 1.16 for core hardware elements (nvvidconv, nvv4l2decoder, nvv4l2h264enc, nvarguscamerasrc)
- Docker containers that use only userspace libraries, CUDA is mapped in from the host runtime; containers that don't bundle kernel-dependent code work fine
- Application code that doesn't link CUDA directly, pure Python, web servers, business logic, REST APIs, database code
- USB peripherals and Ethernet, no driver changes for standard peripherals
- I2C, SPI, UART on standard carrier board pins, the pinmux and driver stack for standard interfaces is stable
- Most apt-installable packages, Ubuntu 22.04 repos cover the same packages as 20.04 with updated versions
**The break list is real, but it is scoped.** If your JP5 system has no custom camera drivers, no TRT engines, and no code compiled against CUDA 11 directly, the migration is closer to a 1–2 day effort than a 2-week project.
## The complete break list when upgrading JetPack 5 to JetPack 6
Go through this before you start. Every item here has caused a blocked migration in the field.
### 1. CUDA-compiled binaries
Any binary compiled against CUDA 11.4 will not run on CUDA 12.6 without recompilation. This includes your own code and any third-party libraries you built from source. `apt`-installed NVIDIA libraries will update automatically, but binaries in `/opt/`, `/usr/local/`, or your home directory won't.
Audit: `grep -r "libcuda" /opt /usr/local ~/.local 2>/dev/null | grep ".so"`
### 2. cuDNN 8 applications
JetPack 6 ships `libcudnn.so.9`. Any application that dynamically links `libcudnn.so.8` will fail with `error while loading shared libraries: libcudnn.so.8: cannot open shared object file`.
Options: recompile against cuDNN 9, or install cuDNN 8 from the NVIDIA archive alongside 9 (not recommended long-term, but buys time during migration).
### 3. TensorRT engines
TensorRT serialized engines are not portable across TRT versions. Every engine built on JP5 (TRT 8.x) must be regenerated on JP6 (TRT 10.x). This is not optional, attempting to load a TRT 8 engine in TRT 10 will crash at deserialization.
Additionally, TRT 10 removed several deprecated APIs from TRT 8. If your code uses `IPluginV2` directly or the legacy calibrator interfaces, it will fail to compile.
### 4. PyTorch and TorchVision
The JP5-compatible PyTorch wheels (CUDA 11.4 builds) are incompatible with JP6's CUDA 12.6. You need the JP6-specific wheels from NVIDIA's PyPI or the Jetson Containers project. The version numbers don't always match what you'd install from `pip` on a desktop, always use the Jetson-specific builds.
### 5. Custom camera drivers
This is the hardest one. L4T R36 made changes to the V4L2 subdev framework and the `tegracam` sensor driver API. A camera driver that works perfectly on JP5 will often fail to compile on JP6, and even if it compiles, behavior differences in the capture subsystem may cause runtime failures.
Specific things that change:
- Sensor driver registration APIs in `tegracam_core`
- NVCSI configuration interfaces
- The `mclk` clock handling changed in R36
We cover this in more depth in the section below.
### 6. Out-of-tree kernel modules
The kernel version changed from 5.10 to 5.15. Any out-of-tree kernel module (`.ko` file) built for L4T R35 will fail to load on R36 with `ERROR: could not insert module: Invalid module format`. All kernel modules must be rebuilt against the L4T R36 kernel headers.
### 7. Device tree changes on custom carrier boards
L4T R36 updated the reference DTS files significantly. If you have a custom carrier board DTS that was derived from JP5 reference files, it needs an audit before JP6. Known breaking changes:
- DWC3 USB controller: `ref` clock became mandatory (see our [DWC3 error -71 post](/blog/dwc3-error-71-jetson-clock-reference-fix))
- PCIe clock references changed on some Orin variants
- UART/SPI/I2C pinmux configurations may need revalidation
- ODMDATA format changes for some carrier board profiles
### 8. GStreamer plugin compatibility
GStreamer moved from 1.16 to 1.22. Most pipelines work without changes, but some NVIDIA-specific elements (`nvv4l2decoder`, `nvarguscamerasrc`) had interface changes. Pipelines that rely on deprecated property names or pad caps negotiation behavior from 1.16 may need updating.
### 9. Package names and Python environment
The Ubuntu 22.04 jump means some package names changed (`python3-dev` → same, but `libpython3.8-dev` is no longer default, etc.). virtualenvs built against Python 3.8 need to be recreated. Anything using `distutils` directly will break since it was removed in Python 3.12 (not relevant here) but `setuptools` behavior changed in 3.10.
## Camera driver porting from JetPack 5 to JetPack 6
This is the part most teams underestimate. If you have a custom CSI camera driver, plan for 2–5 days of porting work depending on how much the driver deviates from the NVIDIA sensor driver template.
The main changes in L4T R36 that break JP5 camera drivers:
**tegracam API changes.** The `tegracam_device` and `tegracam_ctrl_ops` structures changed. Functions that were called directly in R35 are now wrapped or renamed. Drivers built against the R35 headers will hit compile errors in `tegracam_core.h`.
**MCLK handling.** The sensor `mclk` clock acquisition changed. In R35, many drivers called `clk_get` directly. R36 moved this into the framework. Drivers that manage the mclk themselves need the clock handling rewritten.
**V4L2 subdev pad config API.** The `v4l2_subdev_pad_ops` structure had members renamed in newer kernel versions included in R36. This causes compile errors that look unrelated to camera bring-up but are.
The fastest path: take the NVIDIA reference sensor driver for a similar sensor (the IMX219 or IMX477 reference drivers in the JP6 source tree), diff it against the JP5 version, and apply the same structural changes to your driver. Don't try to patch your JP5 driver forward blindly.
For reference on the full camera bring-up process in JP6, see our [CSI camera driver bring-up post](/blog/csi-camera-driver-jetson-v4l2-argus-imx).
## ML stack and TensorRT migration
Rebuilding the ML stack in sequence matters. Do it in this order to avoid dependency conflicts:
1. Flash JP6 and boot clean
2. Install CUDA 12.6 + cuDNN 9 from the JP6 image (they come pre-installed)
3. Install JP6-specific PyTorch wheels (from NVIDIA's Jetson PyPI or `dusty-nv/jetson-containers`)
4. Install TorchVision matching your PyTorch version (check the Jetson Containers compatibility matrix)
5. Re-export ONNX models from your training framework
6. Rebuild TensorRT engines on the target with `trtexec` or your engine builder
Do not try to install desktop PyTorch wheels. The `pip install torch` from PyPI will attempt to download CUDA 12 wheels but they are x86 builds and will fail or silently install wrong. Use [dusty-nv/jetson-containers](https://github.com/dusty-nv/jetson-containers) for pre-built, verified JP6-compatible PyTorch and TorchVision wheels, it's the most reliable source for the Jetson ML stack.
NVIDIA's official [JetPack 6 release notes](https://developer.nvidia.com/embedded/jetpack-sdk-60) document the full package delta and known issues for each point release.
## Step-by-step migration checklist
Use this sequence to minimize the chance of a blocked migration:
**Pre-migration (on your JP5 system):**
1. `lsmod`, record all loaded kernel modules; every `.ko` will need to be rebuilt
2. List all virtualenvs and their Python package requirements
3. Find all TRT engines: `find / -name "*.engine" 2>/dev/null`
4. Grep for hardcoded CUDA 11 paths: `grep -r "cuda-11\|cuda/11" /opt /usr/local 2>/dev/null`
5. Record your camera driver source location and confirm you have the source, not just the `.ko`
6. If you have a custom DTS, save a copy and note which JP5 reference DTS it was derived from
**Post-flash (on JP6):**
1. Verify CUDA 12.6: `nvcc --version`
2. Verify cuDNN 9: `dpkg -l libcudnn9-dev`
3. Rebuild all out-of-tree kernel modules against L4T R36 headers
4. Port and test camera drivers (biggest time sink, start here)
5. Recreate Python environments with Python 3.10
6. Install Jetson-specific PyTorch and TorchVision
7. Re-export ONNX models and rebuild TRT engines
8. Run your application's full test suite before returning the device to service
## How long does a JetPack 5 to JetPack 6 migration take?
From projects we have scoped and completed, here are realistic timelines:
| System profile | Estimated time |
|---|---|
| No custom drivers, no TRT engines, no CUDA-compiled code | 1–2 days |
| Custom Python/ML stack, needs PyTorch rebuild and TRT engine regen | 2–4 days |
| One custom CSI camera driver needing port to R36 tegracam API | 3–6 days |
| Multiple custom camera drivers + custom carrier board DTS | 5–10 days |
| Custom kernel modules (not camera) needing rebuild for 5.15 | Add 1–2 days |
The tegracam API port for camera drivers is the single most variable item. A driver that closely follows the NVIDIA reference template (IMX219, IMX477 structure) ports in 1–2 days. A driver with non-standard clock handling, custom NVCSI configuration, or heavily patched register sequences can take 4–5 days.
TRT engine regeneration time depends on model complexity and whether your ONNX export pipeline is already scripted. If you have to re-export from a training framework first, add that to your estimate.
## Who offers JetPack 5 to 6 porting support
If you would rather hand the migration off than staff it internally, the vendor landscape splits into three realistic options.
**Freelance marketplaces.** The major marketplaces list embedded Linux engineers at roughly $60–150/hr. The risk is verification: tegracam API porting experience is rare, and a generalist kernel developer will discover the R35-to-R36 breaking changes on your clock, mid-project. If you go this route, ask the candidate to name a specific tegracam change between R35 and R36 before hiring. Anyone who has done the port can answer in one sentence.
**Established embedded consultancies.** Several firms specialize in GStreamer and multimedia work on Jetson. Larger multi-platform firms operate in the same space with broader platform coverage. Most work time-and-materials, so scope discipline is on you.
**ProventusNova (us).** We port JetPack 5 camera drivers and BSPs to JetPack 6 as a fixed-bid engagement: the timeline table above is from our own scoped projects, and a typical single-driver port with carrier board DTS runs 5–10 days. Fixed price is agreed before work starts, you get daily written updates, and every driver, device tree, and build script ships to your repo with full IP transfer. If the milestone slips, the delay is our cost, not yours. Scoping starts with a free [30-minute discovery call](/discovery-call).
Whichever route you pick, three questions filter vendors fast: Have you ported a tegracam driver from R35 to R36 before? What broke last time? Fixed bid or hourly? The first two test experience; the third tests who carries the schedule risk.
## Migrating Docker containers from JetPack 5 to JetPack 6
Containers that use only userspace CUDA libraries (libcuda.so, libcudart.so) work on JetPack 6 without rebuilding, because the NVIDIA container runtime maps the host's libraries into the container at run time.
Containers that will need rebuilding:
- Containers that bundle PyTorch built against CUDA 11.4 (incompatible with CUDA 12.6 host)
- Containers that load kernel modules (.ko files), these always use the host kernel, not a container version
- Containers that hardcode `/usr/local/cuda-11` paths
To test whether a JP5 container works on JP6 before rebuilding:
```bash
# Check what CUDA version the container sees
docker run --runtime=nvidia --rm your-image:tag nvcc --version
# Check library loading
docker run --runtime=nvidia --rm your-image:tag ldconfig -p | grep cuda
```
If `nvcc --version` shows 12.x on a container built for CUDA 11, the runtime injection is working. If your application then throws `CUDA error: forward compatibility was attempted` at runtime, you have a compiled binary that needs a rebuild.
The NVIDIA L4T base images for JetPack 6 are at `nvcr.io/nvidia/l4t-base:r36.x.x`. Use these as your base image for JP6 container builds.
## Xavier on JetPack 6: your options
JetPack 6 does not support Xavier-series modules (AGX Xavier, Xavier NX). JetPack 5.1.x is the last supported release for Xavier hardware.
If you are on Xavier and need to benefit from JP6 improvements, your options:
**Option 1, Stay on JetPack 5.1.x.** NVIDIA has not announced an end-of-security-updates date for JP5. For production systems where hardware swap is not viable, staying on JP5 is a legitimate choice through at least 2026.
**Option 2, Upgrade hardware to Orin.** Orin modules are pin-compatible with Xavier modules for AGX Orin (same 699-pin connector) and for some Xavier NX → Orin NX carrier boards. Software migration is still required (CUDA, TRT, camera drivers), but you avoid a hardware redesign. Verify pin-compatibility with your specific carrier board before ordering.
**Option 3, Parallel deployment.** Keep existing Xavier systems on JP5, migrate new production units to Orin + JP6. Many teams run mixed fleets during transition.
The performance case for moving to Orin is significant, Orin AGX delivers roughly 2.5x the AI TOPS of AGX Xavier (275 vs 32 TOPS sparse INT8), but the migration cost is real and should be scoped before committing.
## What to audit before you start the migration
| Area | What to check | Risk if skipped |
|------|--------------|-----------------|
| Camera drivers | Do you have custom `.c` driver files? | 2–5 days of porting work discovered mid-migration |
| TRT engines | List all `.engine` files in production | Runtime crashes at model load |
| Kernel modules | `lsmod` and `/lib/modules/` on your JP5 system | Modules silently missing on JP6 |
| Python environments | All virtualenvs, conda envs | Import failures in production |
| Hardcoded CUDA paths | Grep for `/usr/local/cuda-11` | Runtime errors in scripts |
| Carrier board DTS | Is your DTS derived from JP5 reference? | Boot failures after flash |
If your JP5 system has custom camera drivers or a complex custom carrier board DTS and you need a scoped porting engagement, the [Jetson BSP and camera bring-up service](/services/gmsl) covers what that typically involves and how we scope the work.
For the complete camera bring-up process on JetPack 6, see [GMSL2 camera bring-up on Jetson Orin](/blog/gmsl2-camera-bringup-jetson-orin-max9295-max9296). For the JetPack version compatibility table with all L4T releases, see [JetPack versions and L4T compatibility](/blog/jetpack-versions-l4t-compatibility-table).
---
## Jailhouse hypervisor on MediaTek Genio: bare-metal isolation on Linux
URL: https://proventusnova.com/blog/jailhouse-hypervisor-mediatek-genio/
Published: 2026-03-23
Author: Andres Campos
Tags: mediatek, genio, jailhouse, hypervisor, zephyr, real-time, embedded linux
Jailhouse hypervisor on MediaTek Genio 720: cell config, GIC addresses, required kernel patches, MTK vendor config, and IVSHMEM communication.
Jailhouse is a partitioning hypervisor that splits a SoC into isolated cells rather than virtualizing hardware. On MediaTek Genio 720, it runs at EL2 and gives dedicated CPU cores, memory, and peripherals exclusively to a Zephyr inmate cell while Linux continues on the remaining cores. Getting it running on Genio requires three kernel patches that aren't in any standard guide, plus MediaTek-specific cell config fields that upstream Jailhouse documentation doesn't cover.
## Key Insights
- Jailhouse runs at EL2; Linux and Zephyr both run at EL1. On Genio 720, the hypervisor sits at `0x44000000` (16MB) with the GIC at `0x0c000000`.
- Three kernel patches are required: disable VHE in `finalise_el2`, export `ioremap_page_range` and `__get_vm_area_caller` from vmalloc.c, and add a 16MB `reserved-memory` DTS node at `0x44000000`.
- Standard ARM Jailhouse peripheral passthrough (MMIO region + disabled DTS node) is not enough on Genio, you also need a `.vendors` array with `JAILHOUSE_VENDOR_MTK_GPIO` and `JAILHOUSE_VENDOR_MTK_EINT` entries.
- The hypervisor memory region must not overlap the Linux kernel image, upgrading from Linux 5.x to 6.6 on Genio 700/720 required shifting the base address by ~48MB as the kernel image grew.
- Status (July 2026): MediaTek now publishes the Jailhouse recipe in its `meta-mediatek-experimental` Yocto layer and maintains a public Zephyr fork with Genio board support, including a full audio driver stack for the Genio 700. Prebuilt cell configs for the Genio 510 and 720 EVKs ship in the image.
## What Jailhouse does and why it matters on Genio
Jailhouse doesn't virtualize hardware. It partitions it. The SoC is divided into cells at startup, and each cell gets exclusive ownership of specific CPU cores, memory regions, and peripherals. There's no scheduling between cells, each runs uninterrupted on its assigned cores.
The typical setup on Genio 720:
- **Root cell (Linux)**: 6 of 8 CPU cores, most RAM, full peripheral access
- **Inmate cell (Zephyr)**: 1-2 dedicated cores, 48MB isolated memory, UART + GPIO + EINT passthrough
- **Jailhouse itself**: runs at EL2, 16MB at `0x44000000`
Linux and Zephyr both run at EL1. Jailhouse at EL2 enforces the partition boundaries. From the inmate's perspective, Linux doesn't exist.
Communication between cells uses IVSHMEM, which appears as a PCI device in both cells. On Genio 720, the IVC communication region is 4KB at physical `0x80000000`.
When we first brought this stack up, every piece below had to be assembled by hand: kernel patches, cell configs, Zephyr port. As of mid-2026 MediaTek ships most of it publicly (see the update section below), which changes the starting point but not the concepts. The config anatomy, the vendor quirks, and the memory sizing rules in this post are exactly what you will be reading and modifying in the released code.
## Three required kernel patches
All three patches are required. Without any one of them, Jailhouse fails to initialize.
**Patch 1, Disable VHE** (`arch/arm64/kernel/hyp-stub.S`):
Add an early return in `finalise_el2` to prevent Linux from taking EL2:
```asm
ENTRY(finalise_el2)
ret /* early return, do not enable VHE */
...
```
Export the EL2 stub vector table:
```c
EXPORT_SYMBOL_GPL(__hyp_stub_vectors)
```
**Patch 2, Export kernel symbols** (`mm/vmalloc.c`):
```c
// Remove pgprot_nx from ioremap
EXPORT_SYMBOL_GPL(ioremap_page_range)
EXPORT_SYMBOL_GPL(__get_vm_area_caller)
```
These are used by `jailhouse.ko` at runtime to set up hypervisor memory space.
**Patch 3, Reserve hypervisor memory in DTS**:
```dts
reserved-memory {
jailhouse@44000000 {
reg = <0x0 0x44000000 0x0 0x01000000>; /* 16 MB */
no-map;
};
};
```
## The Genio 720 cell config, real addresses
The cell config is a C struct compiled into a `.cell` file. Real values from the Genio 720:
```c
.platform_info = {
.gic_version = 3,
.gicd_base = 0x0c000000,
.gicr_base = 0x0c040000, /* 2MB, covers 8 CPU redistributors */
.maintenance_irq = 25,
},
```
Inmate memory region (48MB):
```c
{
.phys_start = 0x45000000,
.virt_start = CONFIG_INMATE_BASE,
.size = 0x03000000, /* 48 MB */
.flags = JAILHOUSE_MEM_READ | JAILHOUSE_MEM_WRITE |
JAILHOUSE_MEM_EXECUTE | JAILHOUSE_MEM_LOADABLE,
},
```
UART1 shared with root cell (inmate console):
```c
{
.phys_start = 0x11002000,
.size = 0x1000,
.flags = JAILHOUSE_MEM_READ | JAILHOUSE_MEM_WRITE |
JAILHOUSE_MEM_IO | JAILHOUSE_MEM_ROOTSHARED | JAILHOUSE_MEM_IO_32,
},
```
IVC communication region:
```c
{
.virt_start = 0x80000000,
.size = 0x00001000,
.flags = JAILHOUSE_MEM_READ | JAILHOUSE_MEM_WRITE | JAILHOUSE_MEM_COMM_REGION,
},
```
Inmate IRQs: SPI 446 (GPIO interrupt), SPI 267 (EINT interrupt).
## The MediaTek vendor config, what makes Genio different
On standard ARM platforms (i.MX, Jetson, QEMU), passing a peripheral to a Jailhouse inmate requires only an MMIO region with `JAILHOUSE_MEM_IO` and disabling the peripheral in the Linux DTS.
On MediaTek Genio, that's not enough. You also need a `.vendors` array to configure GPIO pin mux and EINT interrupt routing. Without it, the inmate can address the peripheral's MMIO but can't use GPIO pins or receive interrupts.
For UART1 passthrough on Genio 720:
```c
.vendors = {
/* GPIO pin mux for UART1 TX/RX (pins 33 & 34) */
{
.type = JAILHOUSE_VENDOR_MTK_GPIO,
.mtk_gpio.address = 0x10005000,
.mtk_gpio.pin_base = 32,
.mtk_gpio.pin_bitmap = {
0x00000006, 0, 0, 0
}
},
/* EINT routing for UART interrupt */
{
.type = JAILHOUSE_VENDOR_MTK_EINT,
.mtk_eint.address = 0x1000b000,
.mtk_eint.pin_base = 32,
.mtk_eint.pin_bitmap = {
0x00000140, 0, 0, 0
}
},
},
```
GPIO base: `0x10005000`. EINT base: `0x1000b000`. Every peripheral that uses GPIO or interrupts needs corresponding entries. This is not in the standard Jailhouse documentation, it's MediaTek-specific.
## The hypervisor memory sizing gotcha
The hypervisor memory region must not overlap with the Linux kernel image. The kernel binary grows with each version, and this causes real problems in practice.
Upgrading from Linux 5.x to 6.6 on Genio 700/720 required shifting the hypervisor base address by approximately 48MB. The kernel image had grown enough to overlap the previously-safe hypervisor region.
To find the actual kernel footprint on a running system:
```bash
cat /proc/iomem | grep Kernel
```
Leave at least 16MB of headroom above the expected kernel load address. The kernel grows faster than expected across major version bumps.
## 2026 update: MediaTek now ships this stack publicly
Everything above used to require assembling patches and configs yourself. In mid-2026 MediaTek published the pieces, which turns a research project into a build step:
- **The Jailhouse recipe is public.** It lives in the [meta-mediatek-experimental layer](https://gitlab.com/mediatek/aiot/rity/meta-mediatek-experimental) (scarthgap branch, matching RITY v25.1 on kernel 6.6.92). Clone it next to your other layers, add it to `bblayers.conf`, and add `IMAGE_INSTALL:append = " jailhouse "` to `local.conf`. The kernel-side changes ride along; in a `devtool` kernel workspace they arrive by merging the `mtk-v6.6` branch.
- **Prebuilt cell configs ship in the image.** The package installs a cell library including `genio-510-evk.cell`, `genio-720-evk.cell`, and matching `-zephyr` inmate cells, plus UART demo and interrupt-latency test cells for the Pumpkin boards. The inmate load address is set by `JH_CONFIG_INMATE_BASE` in the Jailhouse recipe if your memory map needs to differ.
- **The Zephyr side has a maintained public fork.** Initialize with `west init -m https://github.com/ffreimann-mtk/zephyr --mr MTK-Genio_4.3.0` (Zephyr 4.3.0 base) and build for the Genio boards directly. The fork is under active development: in June 2026 it gained a complete audio front end driver stack for the Genio 700, which we break down in [Zephyr audio on MediaTek Genio 700](/blog/mediatek-genio-zephyr-audio).
The lifecycle on the board is unchanged: `modprobe jailhouse`, enable the hypervisor with the root cell config, create the Zephyr cell, load `zephyr.bin` at the inmate base, start the cell. What changed is that the configs you enable and the binary you load now come from vendor-published code, and this post is the map for reading and adapting them.
## When Jailhouse makes sense, and when it doesn't
Jailhouse is the right answer when you need hard real-time behavior on the same SoC as a Linux application, motor control, safety monitoring, deterministic sensor sampling alongside AI inference. The isolation is genuine: the inmate cell's timing is not affected by Linux scheduler behavior or interrupt storms.
It's not the right answer if you just need faster interrupt response from Linux. For that, look at `CONFIG_PREEMPT_RT` or processor affinity.
The Genio 720's 8-core layout (2×A78 + 6×A55) fits this pattern well: run Zephyr on one A55 core with dedicated peripherals, Linux on the remaining 7 cores. The A55 cores have sufficient headroom for real-time tasks while the A78 cores handle AI inference.
For Genio Jailhouse bring-up, kernel patch through IVSHMEM communication, we handle this as part of custom embedded engagements at [ProventusNova](/get-expert-mediatek-genio-support).
## Frequently Asked Questions
### What is Jailhouse and why use it on MediaTek Genio?
Jailhouse partitions the Genio SoC into isolated cells, Linux on most cores, Zephyr on dedicated cores for hard real-time tasks. Each cell has exclusive ownership of its CPU cores, memory, and peripherals.
### What exception level does Jailhouse run at on Genio?
Jailhouse runs at EL2. Linux and Zephyr run at EL1. A required kernel patch prevents Linux from claiming EL2 at startup.
### How do Linux and Zephyr communicate in a Jailhouse setup?
Via IVSHMEM, mapped as a virtual PCI device in both cells. Jailhouse provides an IVC API on top. On Genio 720, the IVC region is 4KB at physical `0x80000000`.
### Why do I need the MTK vendor config for peripheral passthrough?
Standard ARM Jailhouse only needs an MMIO region and disabled DTS node. MediaTek Genio requires a `.vendors` array with `JAILHOUSE_VENDOR_MTK_GPIO` and `JAILHOUSE_VENDOR_MTK_EINT` entries to configure pin mux and interrupt routing.
### What kernel patches are required for Jailhouse on Genio?
Three patches: (1) disable VHE in `finalise_el2` and export `__hyp_stub_vectors`, (2) export `ioremap_page_range` and `__get_vm_area_caller` from vmalloc.c, (3) add a 16MB reserved-memory DTS node at `0x44000000`.
---
## Jetson UEFI shell at boot: assertion errors and how to recover
URL: https://proventusnova.com/blog/jetson-uefi-shell-assertion-boot-recovery/
Published: 2026-03-20
Author: Aaron Angulo
Tags: jetson, uefi, boot, bsp, carrier board, debugging
Dropped into the UEFI shell on Jetson Orin? Here's why it happens, from QSPI bootloader corruption to DTB mismatches, and the exact steps to recover.
A Jetson that drops to the UEFI shell on boot is stuck in a recovery state that most engineers have not seen before. The UEFI assertion failure usually means the bootloader cannot find the EFI system partition or the boot variable is pointing to a non-existent path. This post covers how to recover and what caused it.
## Key Insights
- Jetson Orin (and Thor) uses UEFI, when boot fails for any reason, it drops to an interactive UEFI shell instead of showing a helpful error
- Five failure modes cover nearly all cases: corrupted QSPI bootloader, wrong DTB in `extlinux.conf`, ODMDATA mismatch, failed fuse burn, or corrupted A/B boot partition from a bad OTA
- First diagnostic: does the module appear as "NVIDIA Corp. APX" in `lsusb`? Yes → recoverable via reflash; No → hardware or power issue
- From the UEFI shell, `fs0:` → `ls` tells you immediately if the boot filesystem is visible
- Secure boot fuse burn failures cannot be recovered without NVIDIA involvement, don't experiment with fuse burning on production hardware
## Why Jetson Orin uses UEFI and what the shell means
Jetson Xavier (and earlier) used CBoot, NVIDIA's proprietary bootloader. Starting with Orin-series modules and JetPack 5.0, NVIDIA moved to UEFI. This aligns with industry standards and enables secure boot, A/B partitioning, and standard EFI boot entries, but it also means a new class of boot failures that look nothing like CBoot failures.
When UEFI can't complete its boot sequence, it drops to the interactive UEFI shell, the same shell you'd see on a standard x86 UEFI motherboard. This can happen with or without an assertion error message.
An assertion failure looks like this in the serial console:
```
ASSERT_EFI_ERROR (Status = Not Found)
ASSERT /home/oe-user/oe-workdir/.../TegraBootManager.c(146): !EFI_ERROR (Status)
UEFI Interactive Shell v2.2
UEFI v2.70 (NVIDIA, 0x00010000)
Shell>
```
A quieter drop looks like:
```
BdsDxe: failed to load Boot0001 "UEFI Misc Device" from ...
BdsDxe: failed to load default boot option
Shell>
```
Both land you at the `Shell>` prompt with no kernel booted.
## The five failure modes that cause a UEFI shell drop on Jetson
**1. Corrupted or mismatched QSPI bootloader**
The UEFI firmware itself lives in QSPI flash. If it was partially written during a failed flash, or if the QSPI contains a bootloader from a different JetPack version than your rootfs, boot will fail. This is the most common cause after a flash attempt that was interrupted.
Confirm it: on the host, check if the Jetson appears as "NVIDIA Corp. APX" in `lsusb` when you hold the recovery button. If it does, the module is alive and can be reflashed. If it doesn't appear at all, power sequencing or hardware may be the issue.
**2. DTB not found or wrong DTB**
The UEFI bootloader loads a device tree blob (DTB) before handing off to the kernel. If `extlinux.conf` references a DTB filename that doesn't exist on the boot partition, or if the partition is corrupted, UEFI will fail with `Not Found` and drop to the shell.
Check: from the UEFI shell, navigate to the boot filesystem and inspect the files:
```
Shell> fs0:
fs0:\> ls
fs0:\> cd EFI\BOOT
fs0:\EFI\BOOT\> ls
```
If you can't see `fs0:` at all, the boot partition isn't visible to UEFI, either it's corrupted, or the partition table got mangled.
**3. ODMDATA mismatch**
ODMDATA encodes the module variant and carrier board configuration. If the ODMDATA in QSPI doesn't match the module you're booting (common when reflashing with the wrong board config), the bootloader may assert before even finding the kernel.
This is especially common on custom carrier boards where the ODMDATA was set for one Orin variant and someone reflashed with a BSP for a different one.
**4. Failed fuse burn**
If you enabled secure boot (`fused` mode) and the fuse burn didn't complete correctly, the bootloader will assert at the signature verification step. The forum thread with 5.5k views is largely this case, "Failed Assert during Boot (Post fuse burn)." There's no recovery path without NVIDIA support if PKC fuses were partially burned.
**5. Corrupted boot partition after OTA**
A failed OTA update, especially the JP5 → JP6 migration that OTA doesn't actually support, can leave the A slot boot partition in an inconsistent state. UEFI tries slot A, finds it invalid, tries slot B, finds it equally bad, and drops to the shell.
## How to diagnose which failure mode you have
Work through this in order:
```bash
# On the host: check if module is in recovery mode
lsusb | grep -i nvidia
# "NVIDIA Corp. APX" = recovery mode, can reflash
# Nothing = hardware or power issue
```
If the module is in recovery mode, you can recover. Run the full flash including bootloader:
```bash
# From your L4T package root (adjust for your board and JetPack version)
sudo ./flash.sh jetson-orin-nano-devkit internal
```
If the module boots to the UEFI shell (not recovery mode), try to diagnose from there:
```
Shell> fs0: # Try boot filesystem
Shell> fs1: # If fs0 isn't visible, try fs1
fs0:\> cat extlinux\extlinux.conf # Check what DTB and kernel it references
```
If `extlinux.conf` references a DTB that doesn't exist in the filesystem, that's your problem. Copy the correct DTB from the L4T package.
If `extlinux.conf` looks correct and the files exist, try booting manually:
```
fs0:\> \EFI\BOOT\BOOTAA64.EFI
```
If that fails with an assertion, you're into QSPI corruption or a fuse issue, reflash is required.
## Recovery: the standard path
For most UEFI shell issues on Jetson (excluding secure boot / fuse problems), the recovery procedure is:
1. Hold the Force Recovery button and power cycle the board
2. Confirm `lsusb` shows "NVIDIA Corp. APX" on the host
3. Flash with the complete BSP including bootloader (not just the rootfs)
4. Don't interrupt the flash, QSPI writes are the most corruption-prone step
```bash
# Full flash including bootloader (do not use --no-flash-bootloader)
cd Linux_for_Tegra
sudo ./flash.sh -r internal
```
The `-r` flag reuses your existing rootfs image if you want to preserve data. Remove `-r` to do a full clean flash.
For custom carrier boards, make sure you're using the correct board config for your specific module + carrier combination. Flashing an Orin NX board config onto an Orin Nano module will produce ODMDATA mismatches and put you right back in the UEFI shell.
## When you're in harder territory
The standard recovery path above handles the common cases. It gets more complicated when:
- **Secure boot / fuse errors**: If PKC fuses were partially burned, recovery may require NVIDIA intervention. This is not a DIY fix.
- **Custom carrier board with vendor BSP**: Your flash script and board config may be in the vendor's SDK, not the standard L4T package. Flashing with the wrong config can make things worse.
- **A/B slot corruption in production**: If devices are deployed in the field and the OTA mechanism corrupted both slots, recovery requires physical access and a recovery-mode flash.
- **Thor (T5000)**: The UEFI implementation on Thor differs from Orin. Boot failure modes are similar but the firmware internals are different.
We've recovered from UEFI shell drops on custom carrier boards a number of times, usually from ODMDATA mismatches after board respins or interrupted flashes. If you're stuck and reflash isn't working, [book a scoping call](https://proventusnova.com/get-expert-nvidia-jetson-support) and we'll diagnose from your serial log.
For related boot issues, see [Jetson carrier board not booting: 6 root causes nobody documents](/blog/jetson-carrier-board-not-booting-root-causes) and our [JetPack versions and L4T compatibility table](/blog/jetpack-versions-l4t-compatibility-table) for confirming you're using the right BSP. If you're dealing with A/B slot issues on top of the UEFI problem, see [Jetson A/B OTA updates: what breaks on custom carrier boards](/blog/jetson-ab-ota-custom-carrier-board).
The UEFI Interactive Shell is documented in the [UEFI specification](https://uefi.org/specifications). NVIDIA's Jetson-specific bootloader documentation is in the [Jetson Linux Developer Guide](https://docs.nvidia.com/jetson/archives/r36.4.3/DeveloperGuide/index.html).
---
## Jetson A/B OTA updates: what breaks on custom carrier boards
URL: https://proventusnova.com/blog/jetson-ab-ota-custom-carrier-board/
Published: 2026-03-17
Author: Aaron Angulo
Tags: jetson, ota, a/b slot, bsp, jetpack 6, carrier board
Jetson Orin A/B slot OTA updates fail differently on custom carrier boards than on devkits. Slot switching not persisting, rollback protection blocks, and.
Jetson's A/B OTA update mechanism works reliably on the devkit, but custom carrier boards introduce specific failure modes that the devkit never exercises. EEPROM board ID mismatches, incorrect ODMDATA, and custom partition layouts all cause OTA failures that look like general system instability. This post covers what breaks and how to fix it.
## Key Insights
- Jetson Orin A/B OTA works on devkits but breaks on custom carrier boards in four specific ways
- Slot switching that doesn't persist: usually QSPI write protection or ODMDATA mismatch between slots
- Unexpected slot B switches: the retry counter on slot A incremented too many times, investigate the underlying reboots, not the slot switch itself
- Rollback protection in L4T R36.4+ blocks downgrading, JP5 → JP6 OTA is not possible; reflash only
- Verify slot B is initialized before shipping: `nvbootctrl dump-slots-info` should show both slots bootable after initial flash
## How Jetson Orin A/B slots work
Jetson Orin uses a redundant boot partition scheme inspired by Android A/B updates. Each slot (A and B) contains a complete, independent set of bootloader partitions:
- `kernel_a` / `kernel_b`, Linux kernel images
- `kernel-dtb_a` / `kernel-dtb_b`, Device tree blobs
- `system_a` / `system_b` (if using A/B rootfs)
- Bootloader partitions in QSPI: `mb2`, `xusb-fw`, `bpmp-fw`, etc.
During a normal OTA update:
1. Update engine writes the new firmware to the **inactive** slot
2. Verifies the write
3. Sets the inactive slot as the new active slot
4. Reboots
5. UEFI boots from the new slot and marks it as successful
If the new slot fails to boot (watchdog timeout, kernel panic, boot count exceeded), UEFI reverts to the previous slot automatically. This is the rollback mechanism.
On devkits, this works. On custom carrier boards, multiple things can go wrong.
## Failure mode 1: slot switching doesn't persist across reboot
The most common forum complaint: "OTA appears to complete, reboot happens, but the system comes back on the old slot."
This means the slot switch command was accepted by UEFI but not committed to persistent storage (QSPI) before reboot. Causes:
**QSPI write protection active.** If your carrier board has QSPI write protection enabled (hardware WP signal or software protection), UEFI can read the boot order but can't update it. The switch appears to work in RAM but reverts on power cycle.
Check: during the OTA process, look for UEFI log messages about QSPI write failures. Also check your carrier board's QSPI WP pin, it should be deasserted (write enabled) during normal operation.
**Wrong ODMDATA for the switching slot.** If slot B has different ODMDATA than slot A (because slot B was initialized from a different flash configuration), UEFI may read the ODMDATA and determine the new slot is invalid for this carrier board. It silently reverts to slot A.
Fix: ensure both slots are flashed with the same carrier board configuration. When running the initial flash of a custom carrier board, flash with a full dual-slot write, not just slot A.
```bash
# Verify current slot ODMDATA from running system
cat /proc/device-tree/chosen/nvidia,odmdata | xxd
# Check what's in QSPI for both slots
sudo nvbootctrl dump-slots-info
```
## Failure mode 2: rollback protection blocking updates
L4T R36.4 and R36.5 (JetPack 6.2.x) tightened rollback protection significantly. The firmware now checks a monotonic counter in QSPI that increments with each OTA. Once a firmware version is burned in, older versions are rejected.
Symptoms:
- OTA update is downloaded and verified
- update_engine reports success
- Reboot happens but system stays on old firmware
- `dmesg` shows UEFI rollback rejection
This creates problems when:
- A field device gets an OTA update and you need to roll back due to a bug
- You're testing OTA from a higher version back to a lower version in the lab
- JP5 → JP6 OTA is attempted (not supported at all, the version gap triggers rollback protection)
The rollback protection is intentional and cannot be disabled without disabling secure boot. The practical implication: you can only push OTA updates forward (to higher version numbers), and JP5 → JP6 requires a full reflash, not OTA.
```bash
# Check current slot versions and anti-rollback state
sudo nvbootctrl dump-slots-info
```
If you need to test downgrade in a lab environment, you need to reflash with the full bootchain from recovery mode.
## Failure mode 3: slot B not initialized on custom carrier boards
On devkits, NVIDIA's `flash.sh` script initializes both slots. Some custom carrier board vendors provide modified flash tools or reduced flash scripts that only write slot A. Slot B is left with whatever was in QSPI from the factory, often a previous test firmware or an empty partition.
When OTA writes to slot B and tries to boot from it:
- UEFI reads slot B's ODMDATA, wrong or corrupted
- UEFI marks slot B as unbootable and reverts to slot A
- OTA appears to fail silently
Check if slot B is properly initialized:
```bash
# On a running Jetson
sudo nvbootctrl dump-slots-info
# Output shows something like:
# Current Boot Slot: 0 (a)
# Active Slot: 0 (a)
# Slot 0: Bootable: yes, Priority: 14, Retry Count: 7
# Slot 1: Bootable: no, Priority: 0, Retry Count: 0
```
If slot B shows `Bootable: no` and `Priority: 0` before any OTA has been run, it was never initialized. Initialize it by running a full flash that includes the `--no-external-device` flag and explicitly writes both slots, or by using `nvbootctrl` to initialize the slot metadata and then running OTA.
## Failure mode 4: unexpected slot B switches under load
The forum thread with 89 replies on "Orinnx reboot repeatedly but it switch to B unexpectly" is this failure mode: the system is running normally, something causes a crash or unexpected reboot, and the retry counter on slot A increments. After a configurable number of failed boots (default is typically 7), UEFI marks slot A as unbootable and switches to B.
If slot B has older firmware, the system appears to have "downgraded" spontaneously.
The real question is: what's causing the repeated reboots in the first place? The slot switching is the symptom, not the root cause. Common underlying causes:
- Kernel panic or watchdog timeout (check `/var/log/kern.log` or `journalctl -k`)
- Power rail instability causing unexpected resets (`SYS_RESET*` assertion)
- Thermal throttle leading to CPU stall
Diagnostic steps:
```bash
# Check last reboot reason
sudo cat /proc/last_reset_reason 2>/dev/null
# Check kernel crash dumps if kdump is configured
ls /var/crash/
# Check boot retry counts
sudo nvbootctrl dump-slots-info | grep "Retry Count"
```
Manually reset the retry counter to prevent premature slot switching during debugging:
```bash
# Reset slot A retry count (use with caution)
sudo nvbootctrl set-slot-as-unbootable 1 # Mark B as unbootable temporarily
sudo nvbootctrl set-active-boot-slot 0 # Force back to slot A
sudo nvbootctrl set-slot-as-bootable 1 # Re-enable B when ready
```
## What to do during initial flash for custom carrier boards
Set both slots up correctly from the start. When you run your first flash:
1. Use `flash.sh` with your carrier board config, not a reduced script
2. Verify both slots after flash: `nvbootctrl dump-slots-info` should show both slots bootable
3. Boot from slot A, verify everything works
4. Boot from slot B manually (`nvbootctrl set-active-boot-slot 1 && reboot`) and verify slot B boots correctly
Discovering slot B is broken during an OTA in production is much worse than catching it during bring-up.
For related carrier board bring-up issues, see [Jetson carrier board not booting: 6 root causes](/blog/jetson-carrier-board-not-booting-root-causes) and our [UEFI shell assertion post](/blog/jetson-uefi-shell-assertion-boot-recovery), a corrupted OTA often lands you there. If you're dealing with a JetPack version mismatch between slots, see [upgrading from JetPack 5 to JetPack 6](/blog/jetpack-5-to-6-upgrade-what-breaks) for the full scope of what changed. If you're debugging OTA failures in production hardware, [book a scoping call](https://proventusnova.com/get-expert-nvidia-jetson-support).
NVIDIA's OTA update documentation for Jetson Linux is in the [Over-the-Air Update section of the developer guide](https://docs.nvidia.com/jetson/archives/r36.4.3/DeveloperGuide/SD/SoftwarePackagesAndTheUpdateMechanism.html). The `nvbootctrl` tool reference is in the same guide under [Bootloader Control Block](https://docs.nvidia.com/jetson/archives/r36.4.3/DeveloperGuide/SD/BootAndRootFilesystem.html).
---
## What engineers wish they'd known before their first Jetson carrier board
URL: https://proventusnova.com/blog/jetson-custom-carrier-board-lessons-learned/
Published: 2026-03-13
Author: Aaron Angulo
Tags: jetson, carrier board, board bring-up, lessons learned, bsp, hardware startup
Hard-won lessons from Jetson custom carrier board bring-up: what experienced engineers do differently the second time, covering BSP, hardware design, and.
## Key Insights
- The Jetson Design Guide is not optional reading, engineers who skip it find out the hard way what's in it
- Bring-up on the devkit first, always, it separates hardware problems from software problems
- The devkit DTS is a reference, not a starting point, every GPIO, I2C bus, and regulator needs verification against your schematic
- Plan for bring-up to take twice as long as estimated, and have a scope available from day one
- The second carrier board bring-up takes a fraction of the time the first one takes, the knowledge compounds
## The gap between "board arrived" and "board works"
We have worked with enough hardware startup teams to recognize a pattern. The board arrives from the manufacturer. The team is excited, months of PCB design work are finally in hand. The first boot attempt is usually the beginning of a 6–14 week debugging marathon that nobody budgeted for.
This is not a failure of engineering skill. It is the inevitable result of attempting something for the first time, on a complex platform, with a BSP that assumes you already know what you are doing.
Here is what experienced engineers do differently.
## Read the Design Guide before layout begins
The Jetson Module Design Guide (not the datasheet, the Design Guide) specifies hardware requirements that are not negotiable and not obvious from the module pinout. Power sequencing requirements, signal level compatibility, required pull resistors, and which signals must be actively driven versus which can be left floating, this is all in the Design Guide.
Engineers who skip this document and design from the module pinout alone reliably create the same set of problems: SYS_RESET* pulled up too fast, FORCE_RECOVERY* floating when it should be pulled high, VIN_PWR_BAD_N not handled correctly. These failures produce intermittent behavior that looks like instability rather than a specific hardware error.
Read the Design Guide for your specific module (Orin NX and AGX Orin have different guides). Read it before PCB layout begins. Read the revision specific to the JetPack version you plan to use, the requirements have tightened between module generations.
## Start software development on the devkit
Before your custom board is manufactured, get a Jetson developer kit for your module and start software development on it. Write your application. Validate your camera pipeline. Test your inference workflow. Get everything working on the devkit.
When your custom board arrives, you now have a known-good software baseline. When something fails on the custom board, you know it is a hardware or BSP adaptation problem, not an application bug or a misunderstanding of the software stack.
Teams that skip devkit development and go straight to custom board have two unknowns at once: the hardware and the software. This makes every debugging session twice as long.
## Treat the devkit DTS as a reference, not a starting point
The devkit device tree has hard-coded values that reflect the devkit's specific hardware: GPIO assignments, I2C bus numbers, regulator node names, power domain configurations, PCIe clock source selection.
On a custom board, most of these are different. The camera I2C bus that was bus 3 on the devkit might be bus 1 on your board. The GPIO that controlled the camera power enable on the devkit might be on a different bank on yours. The PCIe reference clock that came from the devkit's on-board oscillator might come from the Jetson SoM on your design.
Build a mapping document before writing any DTS. For every hardware reference in the devkit DTS (GPIO numbers, I2C bus numbers, regulator names), document what your custom board uses instead. Then systematically update the DTS. Changing the obvious things (camera port assignments) and forgetting the non-obvious ones (regulator node names) produces a DTS that is 90% correct and fails in ways that look like hardware problems.
## Put a scope on the bench from day one
The most expensive tool that engineering teams fail to use during bring-up is a scope. When SYS_RESET* timing is wrong, the scope shows it in 30 seconds. When a power rail has a noise problem causing intermittent resets, the scope shows it in one capture. Without a scope, the same problem can consume days of BSP debugging.
Specific things to probe on first power-on:
- VDD_IN rise time and final voltage
- SYS_RESET* deassertion timing relative to VDD_IN stable
- FORCE_RECOVERY* level at power-on
- Any camera power rails if cameras are part of the bring-up
If anything on this list is out of spec, fix the hardware before proceeding to software.
## Budget for bring-up time correctly
First-time custom Jetson carrier board bring-up takes longer than teams plan for, without exception. The common mistake is treating bring-up as a task with a defined end state ("the board boots") rather than as a phase with multiple sub-milestones.
A more realistic model for a moderately complex board (USB 3.x, PCIe, CSI cameras, Ethernet):
| Milestone | Realistic time |
|-----------|----------------|
| First boot to UEFI/serial output | 1–3 days |
| Stable boot to Linux userspace | 3–7 days |
| USB and PCIe functional | 1–2 weeks |
| Camera pipeline working | 2–4 weeks |
| All peripherals validated | 4–8 weeks |
These ranges assume a team with some Jetson experience. First-time teams should budget toward the higher end of each range.
## The second board is always faster
The knowledge gained from the first custom Jetson carrier board bring-up is not wasted, it compounds. Engineers who have been through a Jetson bring-up once know what to verify first, what each error message means, and which failures are hardware versus BSP. Second carrier board bring-up typically takes 30–50% of the time the first one took for similar complexity.
This is also why bringing in experts for the first bring-up has lasting value beyond clearing the immediate blocker, the knowledge transfer to the internal team makes every subsequent bring-up faster.
For specific boot failures and their root causes, see [Jetson carrier board not booting: 6 root causes nobody documents](/blog/jetson-carrier-board-not-booting-root-causes) and [hardware design mistakes that cause Jetson carrier board bring-up failures](/blog/jetson-carrier-board-hardware-design-mistakes). For the A/B OTA path once the board is up, see [Jetson A/B OTA updates: what breaks on custom carrier boards](/blog/jetson-ab-ota-custom-carrier-board).
The Jetson module Design Guides for current modules are available on the [NVIDIA developer download center](https://developer.nvidia.com/embedded/downloads).
---
## Hardware design mistakes that cause Jetson carrier board bring-up failures
URL: https://proventusnova.com/blog/jetson-carrier-board-hardware-design-mistakes/
Published: 2026-03-10
Author: Aaron Angulo
Tags: jetson, carrier board, hardware design, board bring-up, pcb design, bsp
The hardware design mistakes that reliably cause Jetson carrier board bring-up failures: power sequencing, EEPROM errors, ODMDATA mismatches, and PCB.
Most custom Jetson carrier board bring-up failures trace back to hardware design decisions made weeks before the board arrived. Power sequencing violations, EEPROM configuration errors, and PCB routing mistakes all produce software symptoms that make them look like driver problems. This post covers the hardware mistakes we see repeatedly.
## Key Insights
- Most Jetson carrier board bring-up failures we debug trace back to a small set of repeatable hardware design mistakes
- Power sequencing violations (SYS_RESET* timing) are the most common single cause, and the hardest to diagnose without a scope
- ODMDATA mismatches produce silent failures: peripherals that appear missing when they are actually misconfigured
- Inverted MIPI P/N pairs look like driver bugs but are PCB routing errors, fixable in software on Orin without board rework
- EEPROM absence or wrong address causes subtle BSP behavior that doesn't produce obvious error messages
## Why hardware design mistakes look like BSP bugs
When a custom Jetson carrier board fails to bring up correctly, the first instinct is to blame the BSP or the device tree. This is usually wrong. The most common failures we encounter come from the hardware side, and they produce software symptoms that make them look like software problems.
A power rail that rises too quickly makes the module boot inconsistently. An ODMDATA mismatch makes USB disappear. An inverted MIPI lane makes camera bring-up look like a driver failure. None of these show a clear "hardware fault" error message. The engineer chases BSP configuration for days before the scope comes out and the real problem becomes obvious.
Here are the design mistakes we see repeatedly.
## Mistake 1: SYS_RESET* timing violations
The Jetson module requires SYS_RESET* to stay asserted (low) for at least 1 ms after VDD_IN is stable. If SYS_RESET* rises too quickly, because it is pulled up through a low-value resistor or connected to a reset IC with an aggressive timeout, the module enters an undefined state.
The symptom: the board boots sometimes and not others. Or it always boots but hangs at a different point in the boot sequence. Or it boots but peripherals are unreliable.
The check: probe SYS_RESET* and VDD_IN simultaneously on a scope. SYS_RESET* must stay low for at least 1 ms after VDD_IN crosses its nominal voltage. If SYS_RESET* is rising before VDD_IN settles, or within 1 ms of VDD_IN stable, fix the reset circuit timing.
This also applies to modules with VIN_PWR_BAD_N: if this signal asserts during normal operation due to a wrong pull-up value or voltage divider, the module performs a hard reset unexpectedly.
## Mistake 2: ODMDATA not matching carrier board
ODMDATA is a 32-bit value flashed to the module's QSPI that tells the BSP how the carrier board is configured. The wrong ODMDATA means the BSP configures the wrong set of peripherals for the physical hardware.
Common mismatches:
- Boot device bit set to eMMC when the carrier board uses NVMe
- USB mode bits wrong, causing USB3 ports not to enumerate
- Camera configuration bits wrong, causing NVCSI ports to be disabled
The symptom of an ODMDATA mismatch is a peripheral that is completely absent from the OS (`lsusb` shows nothing, `lspci` shows nothing) with no error message. The BSP did not fail to configure it, it never tried, because ODMDATA told it the peripheral was not there.
Fix: use NVIDIA's `odmdata` configuration tool to set the correct value for your carrier board and reflash. Verify the flashed ODMDATA with `cat /proc/device-tree/chosen/nvidia,odmdata | xxd`.
## Mistake 3: carrier board EEPROM absent or wrong address
The Jetson BSP reads the carrier board EEPROM (at I2C address 0x57 by default) to determine which device tree to load. A wrong board ID in the EEPROM loads the wrong DTS, enabling wrong peripherals, disabling correct ones.
An absent EEPROM produces `EEPROM Read Fail` in the early serial output. The module still boots, but the BSP falls back to a default configuration that may not match your carrier board.
An EEPROM populated with all zeros (factory default, never programmed) produces the same effect as an absent EEPROM, the board ID is zero, which typically maps to a devkit configuration.
The fix: program the carrier board EEPROM with the correct board ID, SKU, and FAB revision during board assembly. Verify with `sudo i2cdump -y 0 0x57` after boot.
## Mistake 4: inverted MIPI P/N pairs
MIPI CSI-2 uses differential pairs for data transmission. If a PCB layout swaps the P and N lines on one or more data lanes, an easy mistake in a dense fanout, the NVCSI receives bit-inverted data on that lane.
The symptom: `uncorr_err` from `tegra-camrtc-capture-vi` on every frame. The camera probes successfully, I2C works, the sensor appears to be streaming, but every frame produces NVCSI errors. This looks exactly like a driver configuration problem.
On Jetson Orin, lane polarity inversions can be corrected in the device tree without board rework:
```dts
/* lane_polarity bitmask: bit N inverts lane N */
lane_polarity = "6"; /* Binary 0110: lanes 1 and 2 inverted */
```
If you have access to a logic analyzer capable of MIPI decode, you can identify which lanes are inverted by their bit patterns. If you do not, you can determine the correct bitmask by trial and error, there are only 15 non-zero possibilities for a 4-lane interface.
## Mistake 5: missing or wrong PCIe reference clock
PCIe requires a 100 MHz reference clock. If the carrier board expects this clock from an external oscillator but the DTS is configured to use the Jetson's internal clock source (or vice versa), PCIe enumeration fails. The endpoint device is powered but the link never comes up.
The check: verify whether the PCIe REFCLK on your schematic comes from the Jetson SoM or from an external oscillator on the carrier board. The DTS `nvidia,refclk-select` property must match.
Also check PERST# timing: PERST# must stay asserted until the reference clock is stable and VCC is settled. Asserting PERST# too early or deasserting it before the clock is stable prevents link training.
## Mistake 6: wrong USB pull resistors and ID pin handling
USB3 SuperSpeed lines require proper termination. Missing or incorrect resistors on the TX/RX SuperSpeed pairs prevent USB3 link training. The device enumerates as USB2 (or not at all) with no clear error indicating why.
For USB-C connectors with CC pins: the CC pull resistors (Rd for device, Rp for host) determine the power role and connection orientation. Wrong values produce inconsistent behavior depending on cable orientation.
The ID pin on USB-A connectors must be grounded for host-mode operation. If it is left floating or pulled incorrectly, the USB controller may enter device mode unexpectedly.
For specific boot failure diagnosis, see [Jetson carrier board not booting: 6 root causes nobody documents](/blog/jetson-carrier-board-not-booting-root-causes). And if this list has you weighing an off-the-shelf board instead of a custom design, [Jetson carrier board manufacturers compared](/blog/jetson-carrier-board-manufacturers-compared) covers the third-party options and when each makes sense.
The Jetson Orin module design guide with power sequencing requirements is available on the [NVIDIA developer site](https://developer.nvidia.com/embedded/downloads). The IPC2221A standard for PCB design guidelines covers impedance requirements for differential pairs.
---
## Jetson Carrier Board Not Booting: 6 Root Causes Nobody Documents
URL: https://proventusnova.com/blog/jetson-carrier-board-not-booting-root-causes/
Published: 2026-03-06
Author: Andres Campos
Tags: jetson, carrier board, board bring-up, bsp, debugging
Jetson carrier board not booting? Six root causes -- EEPROM, ODMDATA, power sequencing, boot device, device tree, partial flash -- with how to diagnose each.
A Jetson carrier board that won't boot is one of the most time-consuming problems in embedded development -- not because it's technically complex, but because the root causes are spread across BSP configuration, hardware design, and flash state, and the symptoms often look identical regardless of which one you're dealing with. No serial output. No boot progress. Just silence.
Six root causes account for the majority of Jetson carrier board boot failures. Most of them are BSP configuration mismatches, not hardware defects. The board is usually fine. The software stack isn't matching what the hardware expects.
This is a diagnostic reference for working through them in order.
**Key Insights**
1. **Silence on serial doesn't tell you which layer failed.** No CBoot output means the problem is upstream of the bootloader -- power sequencing or EEPROM. Output that stalls means the problem is downstream -- ODMDATA, device tree, or boot device. The serial console is the first diagnostic tool, but only if you know how to read what it tells you.
2. **Most carrier board boot failures are BSP configuration issues, not hardware defects.** Electrical validation doesn't validate BSP configuration. A board can pass all electrical tests and still fail to boot because the EEPROM is unprogrammed, the ODMDATA doesn't match the hardware, or the device tree is for the wrong JetPack version.
3. **The six root causes are independent but often co-present.** A JetPack 5-to-6 migration on a custom carrier can trigger root causes 3, 5, and sometimes 2 simultaneously. Check all six before concluding you've found the only problem.
4. **Pattern recognition compresses diagnosis from weeks to hours.** Engineers who've debugged these root causes across multiple Jetson carrier boards know which serial output pattern maps to which root cause. Engineers debugging it for the first time are reading documentation that doesn't always point directly to the answer.
5. **For a specific case study of root causes 1, 2, and 3 in production**, the [Farmhand AI carrier board post](/blog/custom-carrier-board-not-booting-jetson-orin) covers how we diagnosed and fixed all three in one working session.
## Root cause 1: Carrier board EEPROM not programmed
**What it looks like:** The board appears dead -- no serial output -- or CBoot outputs an EEPROM read error and stalls on device tree selection.
**Why it happens:** The Jetson module reads the carrier board EEPROM during early boot to identify which board it's connected to. That board ID drives device tree overlay selection. If the EEPROM isn't programmed -- common when the manufacturing BOM doesn't include EEPROM programming as an explicit step -- the BSP defaults to the reference carrier board configuration. If your custom carrier differs from the reference design in power rails, peripherals, or GPIO assignments, that mismatch stalls the boot sequence.
**How to diagnose:** Read the EEPROM over I2C using a USB-I2C adapter before connecting the Jetson module. A blank EEPROM (all 0xFF bytes) or one containing reference board IDs confirms this root cause. You can also check dmesg or CBoot output for EEPROM read failure messages.
**Fix:** Program the EEPROM with the correct board ID for your custom carrier using NVIDIA's Jetson EEPROM tool. The board ID maps to the device tree overlay the BSP will load. For custom carrier boards, this often requires creating a new board ID entry rather than reusing a reference one.
## Root cause 2: ODMDATA mismatch in the BCT
**What it looks like:** CBoot is visible in serial output but stalls during peripheral initialization -- specifically during PCIe, display, or USB initialization.
**Why it happens:** ODMDATA is a configuration field in the Boot Configuration Table (BCT) that controls hardware configuration options: PCIe lane count and assignment, display output configuration, USB mode, and storage device selection. ODMDATA is frequently copied from a reference design without being updated for the custom carrier's actual configuration. If ODMDATA specifies PCIe x4 and your carrier has PCIe x1, CBoot attempts to initialize lanes that don't exist.
**How to diagnose:** Extract the current ODMDATA value from the BCT using `tegraflash` or `jetson-io` tools and compare it against your carrier board's actual peripheral configuration. CBoot serial output will show you which initialization step stalled -- that step usually maps directly to the ODMDATA field that's wrong.
**Fix:** Update ODMDATA to reflect the carrier board's actual hardware -- correct PCIe lane assignment, disable display configuration if no display is connected, correct USB mode. Reflash the BCT. This doesn't require reflashing the full rootfs -- the BCT can be updated independently.
## Root cause 3: Power sequencing out of spec
**What it looks like:** The board boots intermittently, or not at all despite correct EEPROM and ODMDATA. The failure is non-deterministic -- sometimes it boots, sometimes it doesn't.
**Why it happens:** Jetson Orin has strict power-on sequencing requirements documented in the Hardware Design Guide. CARRIER_POWER_ON must assert within a specific window after VDD_IN stabilizes. VDD_IN must rise at a minimum slew rate. If the carrier board's power management IC doesn't meet these timing requirements -- usually because default soft-start settings produce a ramp too slow for the module's expectations -- the module stalls waiting for signals that arrive out of sequence.
**How to diagnose:** Attach a logic analyzer to CARRIER_POWER_ON and VDD_IN and measure the assertion timing against the Jetson Orin Hardware Design Guide specification. Compare the actual CARRIER_POWER_ON assertion window and VDD_IN slew rate against the documented requirements. Non-deterministic boot failure with correct BSP config is almost always a power sequencing timing issue.
**Fix:** Adjust the PMIC soft-start configuration to tighten the VDD_IN ramp rate and bring CARRIER_POWER_ON assertion within spec. The specific register to update depends on the PMIC used on your carrier board, but the target parameters are in the Hardware Design Guide.
## Root cause 4: Boot device not detected
**What it looks like:** CBoot reports no boot device found and falls into recovery mode. The serial output shows it scanning for boot devices and finding none.
**Why it happens:** Two sub-causes. First, wrong boot mode resistors -- the Jetson module checks specific GPIO strapping pins at power-on to determine whether to boot normally or enter forced recovery mode. If the carrier board's boot mode resistors are configured for forced recovery, the module won't attempt to boot from the storage device. Second, the storage device (eMMC, NVMe, or UFS) isn't recognized because the device tree entry doesn't correctly describe the storage interface, or the physical wiring has an issue that prevents enumeration.
**How to diagnose:** First check the boot mode GPIO strapping. The carrier board schematic should show the FORCE_RECOVERY pin. If it's being asserted at power-on, the module enters recovery mode regardless of software state. If boot mode strapping is correct, attach a logic analyzer to the eMMC or NVMe interface lines during boot and verify the storage device is responding.
**Fix:** Correct the boot mode strapping if FORCE_RECOVERY is incorrectly asserted. If the storage device isn't being recognized, verify the device tree storage node against the hardware and re-verify the storage wiring continuity.
## Root cause 5: Device tree mismatch after JetPack version upgrade
**What it looks like:** The board booted correctly on a previous JetPack version. After upgrading, it stalls mid-boot or certain peripherals stop working. USB devices don't enumerate, cameras don't deliver frames, or the board boots but dmesg shows errors during peripheral initialization.
**Why it happens:** JetPack version upgrades can change device tree binding conventions. The most significant recent example is JetPack 5 to JetPack 6 (L4T R35 to R36), which updated the kernel from 5.10 to 5.15 and revised USB PHY node bindings, PINMUX assignments, and host controller conventions. Device trees written for R35 apply correctly to R35 -- but under R36, deprecated properties are silently ignored and the affected peripherals initialize without their correct configuration.
**How to diagnose:** Compare the device tree source files against the BSP documentation for the version you're running. Look for properties marked deprecated in the kernel changelog between your source version and target version. The JetPack 6 USB enumeration failure pattern specifically is covered in the [JetPack 6 USB post](/blog/jetpack-6-usb-enumeration-failure-fix), which includes the four device tree changes that cause most JetPack 5-to-6 USB failures.
**Fix:** Update the device tree to match the BSP version being run. Apply changes as device tree overlays where possible to isolate version-specific changes from the base carrier board DTS -- this makes future BSP migrations easier to manage.
## Root cause 6: Partial JetPack flash
**What it looks like:** The board was working. A flash operation was performed -- an update, a recovery attempt, or a routine reflash. Afterward, the board exhibits unexpected behavior: kernel panics early in boot, CBoot version mismatches in serial output, or intermittent failures that correlate with the flash boundary.
**Why it happens:** A flash process interrupted by power loss, USB disconnect, or timeout writes some components and not others. The most common case: the kernel is updated but the bootloader is not (or vice versa). Bootloader and kernel version mismatches produce subtle failures -- sometimes booting correctly once then failing on reboot, sometimes panicking at a consistent point during kernel initialization.
**How to diagnose:** Check the CBoot version reported in serial output against the expected version for your JetPack release. If they don't match, the flash was incomplete. Compare the kernel version (`uname -r`) against the expected version for the same JetPack release.
**Fix:** Perform a complete flash in a single operation using `flash.sh` with the full component set: bootloader, kernel, and rootfs. A partial re-flash to correct a partial flash usually produces another partial flash. Start clean with a full flash.
## Using this reference
Work through the six root causes in order of how early in the boot sequence they manifest:
1. **No serial output at all** -- check power sequencing (root cause 3) and EEPROM (root cause 1)
2. **CBoot output but stalls at peripheral initialization** -- check ODMDATA (root cause 2)
3. **CBoot reports no boot device** -- check boot mode strapping and storage (root cause 4)
4. **Boots but certain peripherals don't work after JetPack upgrade** -- check device tree (root cause 5)
5. **Intermittent or post-flash failures** -- check for partial flash (root cause 6)
Most carrier board boot failures resolve in one of these six areas. The ones that don't are usually hardware issues -- trace routing, component failures, or impedance mismatches -- that require board-level debugging beyond BSP configuration.
If you've worked through all six and the board still won't boot, the diagnostic path shifts to hardware: checking power rail voltages during the boot sequence, verifying signal integrity on critical interfaces, and isolating whether the Jetson module itself is functional on a known-good carrier.
---
## Custom Carrier Board Not Booting on Jetson Orin: Fixed in One Session
URL: https://proventusnova.com/blog/custom-carrier-board-not-booting-jetson-orin/
Published: 2026-03-03
Author: Aaron Angulo
Tags: jetson, carrier board, board bring-up, bsp, edgeai
Custom carrier board not booting on Jetson Orin? Farmhand AI's board booted in one session. Three BSP parameters cause most Jetson bring-up failures.
Farmhand AI's custom carrier board came back from the board house, passed electrical validation, and then did nothing when connected to a Jetson Orin module. No serial output. No boot progress. The team had been trying to get it booting for two weeks when they called us.
We had it running within one working session.
Not because the problem was simple -- it wasn't. Jetson Orin carrier board bring-up involves a specific sequence of BSP configuration steps that aren't intuitive and aren't documented in one place. The board booted fast because we'd been through enough Jetson Orin bring-up failures to know exactly which parameters to check first.
**Key Insights**
1. **A non-booting carrier board is usually a BSP configuration problem, not a hardware defect.** Electrical validation doesn't validate BSP configuration. A board can pass all electrical tests and still fail to boot because the EEPROM isn't programmed, the ODMDATA is wrong, or the power sequencing doesn't meet Jetson Orin's timing requirements.
2. **Three BSP parameters cause most Jetson Orin carrier board boot failures.** Carrier board EEPROM programming, ODMDATA configuration in the BCT, and power sequencing parameters. Any one of them wrong can produce a board that outputs nothing on serial and appears completely dead.
3. **The serial console tells you where it stalled -- if you can read it.** CBoot outputs diagnostic information during the early boot sequence. Engineers who know what to look for can identify the root cause from that output in minutes. Engineers reading it for the first time spend days searching for what the output means.
4. **Pattern recognition compresses the timeline from weeks to hours.** We'd been through this diagnostic path on prior Jetson Orin custom carrier boards. We knew which parameters to check, in which order, and what each failure mode looks like. Farmhand AI's board was booting the same day.
5. **Full IP transfer included the BSP configuration, device tree, and diagnostic notes.** Everything Farmhand AI needed to reproduce the bring-up on future board revisions was in the handoff documentation. No dependency, no retainer.
## What "not booting" usually means on a Jetson Orin custom carrier board
When a Jetson Orin module is connected to a custom carrier board and produces no output, the instinct is to suspect hardware. A trace is wrong. A power rail is shorted. The module is defective.
Hardware failure does happen -- but it's not the first place to look. The more common cause is BSP configuration that doesn't match the actual hardware. The module has everything it needs electrically, but the software stack is trying to initialize hardware that doesn't exist, looking for a device tree that doesn't describe your board, or waiting for a power signal that's arriving out of sequence.
Three parameters drive the majority of cases:
**Carrier board EEPROM.** The Jetson Orin module reads the carrier board EEPROM during early boot to identify what hardware it's connected to. That ID drives device tree overlay selection -- which peripherals to initialize, which GPIO assignments to apply, which power rails to configure. An unprogrammed EEPROM, or one programmed with the reference board ID rather than your custom board's ID, causes the BSP to load a device tree that doesn't match your hardware. The module may appear to boot partially and then stall, or it may produce no output at all depending on where the mismatch triggers a failure.
**ODMDATA.** ODMDATA is a configuration field in the Boot Configuration Table flashed to the module. It controls hardware configuration options: PCIe lane assignment, display configuration, storage device selection, USB mode. ODMDATA is often copied from a reference design without being updated for the custom carrier's actual configuration. If ODMDATA specifies PCIe x4 and your carrier has PCIe x1, the bootloader initializes the wrong configuration and stalls.
**Power sequencing.** The Jetson Orin Hardware Design Guide specifies strict timing requirements for power rail bring-up. CARRIER_POWER_ON must assert within a specific window after VDD_IN stabilizes. VDD_IN slew rate must meet a minimum. If the carrier board's power management IC doesn't meet these timing requirements, the module stalls waiting for signals that aren't arriving within spec. This produces the same symptom as a non-functional board: no serial output, no boot progress.
All three parameters need to match the actual hardware. Any one of them wrong can produce a board that looks dead.
## How we diagnosed the Farmhand AI carrier board
Farmhand AI's board was producing nothing on serial. That ruled out device tree and software issues -- those produce output before stalling. Silence in CBoot means the problem is earlier in the boot sequence.
**Step 1: Verify the serial console connection.**
Before assuming the board isn't outputting anything, verify the UART connection. The Jetson Orin debug UART runs at 115200 baud, 8N1. Wrong baud rate, wrong wire polarity, wrong port selection -- these produce apparent silence from a board that's actually outputting. We confirmed the console connection first, confirmed real silence.
**Step 2: Check the carrier board EEPROM.**
We read the EEPROM over I2C using a USB-I2C adapter before connecting the Jetson module. The EEPROM hadn't been programmed. The board house manufactured it without the programming step -- a common gap when the manufacturing BOM doesn't explicitly include EEPROM programming as a step. With an unprogrammed EEPROM, the Jetson Orin module would default to the reference carrier board configuration, which doesn't match Farmhand AI's custom hardware.
We programmed the EEPROM with the correct board ID for Farmhand AI's carrier configuration using the Jetson EEPROM tool. Reconnected the module. The board started producing CBoot output.
**Step 3: Audit ODMDATA against the actual carrier hardware.**
CBoot was now visible but stalling during peripheral initialization. The ODMDATA in the BCT had been copied from NVIDIA's reference configuration and not updated for Farmhand AI's custom peripheral set. Their carrier board had a different PCIe configuration than the reference design. CBoot was trying to initialize PCIe lanes that weren't connected.
We updated ODMDATA to match the actual carrier hardware -- reflecting the correct PCIe lane assignment and disabling the display configuration the reference design included. Reflashed the BCT. CBoot cleared peripheral initialization.
**Step 4: Verify power sequencing timing.**
The board was now booting further but occasionally failing at a point that didn't correlate with specific software behavior. Intermittent boot failure after ODMDATA and EEPROM were correct usually means power sequencing. We put a logic analyzer on CARRIER_POWER_ON and VDD_IN and measured the assertion timing against the Jetson Orin Hardware Design Guide spec.
CARRIER_POWER_ON was asserting late -- about 8ms past the specified window. The carrier board's power management IC was using default soft-start settings that produced a VDD_IN ramp too slow for the Jetson module's power-on sequencing expectations. We updated the PMIC configuration registers to tighten the ramp rate. CARRIER_POWER_ON was within spec. Boot became consistent.
Total elapsed time from first call to confirmed stable boot: one working session.
## The fix
Three changes, one session:
**EEPROM programming:** Wrote the correct board ID using the Jetson EEPROM tool. This drives correct device tree overlay selection for Farmhand AI's carrier hardware and eliminates the reference board configuration mismatch.
**ODMDATA update:** Updated the BCT ODMDATA field to reflect Farmhand AI's actual PCIe configuration and removed reference board peripheral configuration that doesn't apply to their hardware. Reflashed the BCT.
**PMIC timing adjustment:** Updated the power management IC soft-start configuration to tighten the VDD_IN ramp rate and bring CARRIER_POWER_ON assertion within the Jetson Orin timing spec.
Board booted cleanly and consistently after all three changes. Everything delivered -- BSP configuration, updated BCT, device tree, PMIC register values, and the diagnostic notes documenting root cause for each issue -- transferred to Farmhand AI with full IP ownership.
## Why this pattern repeats
Hardware teams design carrier boards using Jetson reference schematics and hardware design guides. The electrical design is well-documented. BSP configuration for a custom carrier board is less so. The EEPROM programming step doesn't appear in NVIDIA's carrier board design checklist at the level of specificity that catches it before manufacturing. ODMDATA is documented but the mapping from configuration option to actual carrier hardware isn't always obvious. Power sequencing timing requirements are in the Hardware Design Guide but PMIC configuration is carrier-specific.
The result is that boards come back from the board house electrically correct but BSP-misconfigured. Teams spend two to four weeks debugging something that, with pattern recognition from prior Jetson Orin bring-up work, resolves in hours.
If your custom carrier board isn't booting on Jetson Orin, start with EEPROM, ODMDATA, and power sequencing -- in that order. If you've already been through those and the board still won't boot, the problem is further into the device tree or driver layer, which is a different diagnostic path. For what those failures look like, our [JetPack 6 USB enumeration failure post](/blog/jetpack-6-usb-enumeration-failure-fix) covers a similar category of device tree mismatch on a running board. If repeated bring-up pain has you questioning the custom board itself, [Jetson carrier board manufacturers compared](/blog/jetson-carrier-board-manufacturers-compared) lays out the off-the-shelf alternatives.
---
---
## JetPack 6 USB Enumeration Failure: Root Cause in 4 Hours
URL: https://proventusnova.com/blog/jetpack-6-usb-enumeration-failure-fix/
Published: 2026-02-27
Author: Aaron Angulo
Tags: jetpack, usb enumeration, edgeai, embedded debug, linux kernel
JetPack 6 USB enumeration failure? Root cause found in 4 hours for UncommonLab. Learn the 4 device tree mismatches that break USB on L4T R36.
UncommonLab called on a Thursday. Their team had been debugging a USB enumeration failure for three weeks. Every USB device connected to their custom carrier board came up dead -- no enumeration, no error, nothing in dmesg beyond the host controller initializing. They'd upgraded to JetPack 6 two weeks before a demo deadline. The board had worked on JetPack 5.
We found the root cause in 4 hours. Fixed it in under 20.
**Key Insights**
1. **JetPack 6 is a bigger jump than it looks.** L4T R35 to R36 moves the kernel from 5.10 to 5.15. The USB subsystem changes between those versions are not minor -- PHY node bindings changed, PINMUX assignments changed, and device tree properties that worked in R35 are silently ignored in R36. No warning, no error, just a USB controller that initializes and does nothing.
2. **The failure mode is deceptive.** The host controller comes up. dmesg shows it initializing. But devices never enumerate. There's no obvious error to search. The forums don't have the answer. You're debugging silence, which is harder than debugging a crash.
3. **Four device tree mismatches cause most JetPack 6 USB failures.** PINMUX not updated for R36, VBUS sequencing mismatch, deprecated USB PHY node properties, and host controller binding conventions from JetPack 5. Any one of them can cause the failure. All four need to be checked before you've confirmed root cause.
4. **Pattern recognition is the time multiplier.** We found root cause in 4 hours because we'd been in that exact configuration before -- different carrier board, same JetPack 6 upgrade, same symptom. Without that pattern, it's 2-4 weeks of debugging cycles.
5. **Full IP transfer was a standard term.** The corrected device tree, the PINMUX patch, and the diagnostic notes went to UncommonLab with full IP ownership at handoff. No retainer. No lock-in.
## What JetPack 6 actually changed in USB
When JetPack 5 moved to JetPack 6, the headline changes were performance: Jetson Orin support, updated TensorRT, new DeepStream pipeline. What the release notes don't emphasize is that L4T R36 also updated the Linux kernel from 5.10 to 5.15, and the USB subsystem in 5.15 is not backwards-compatible with device trees written for 5.10.
The specific changes:
- **USB PHY node bindings changed.** Properties valid in the 5.10 USB PHY driver are deprecated in 5.15. They won't throw a hard error on boot -- they'll be silently ignored. The PHY comes up without the configuration you specified.
- **PINMUX assignments shifted.** L4T R36 revised the pin multiplexing configuration for USB-related pins on Orin. A device tree that correctly configured PINMUX for JetPack 5 will not configure the same pins correctly in R36 without explicit updates.
- **VBUS sequencing changed.** The power-enable GPIO timing for the USB VBUS rail changed between BSP versions. If your device tree fires the GPIO at the wrong point in the bring-up sequence, the host controller initializes before the VBUS rail is stable -- and devices never enumerate.
- **Host controller driver binding conventions changed.** The compatible string and register map for the USB host controller node follows JetPack 5 conventions in boards that shipped before JetPack 6. R36 expects different node structure.
None of these produce loud failures. They produce silence. The controller starts. The enumeration never happens.
## How we diagnosed the UncommonLab JetPack 6 USB enumeration failure
When UncommonLab described the symptom -- host controller up, no device enumeration, no error -- the pattern matched immediately. We'd seen the same symptom on two prior JetPack 6 boards. Both times, the root cause was in the same four places.
**Step 1: Check the kernel version and BSP against the device tree origin.**
We confirmed they were running L4T R36 with a device tree written against R35. That's the first thing to verify on any JetPack 6 USB failure. Many custom carrier boards ship with device trees based on NVIDIA's reference BSP for JetPack 5. When the team upgrades JetPack, the device tree doesn't automatically update.
**Step 2: Audit the USB PHY node.**
We pulled the device tree source and compared the PHY node properties against the R36 BSP documentation. Deprecated properties were present. The PHY was initializing without the VBUS current limit and turn-on delay settings the team had specified -- they were being silently dropped by the kernel.
**Step 3: Check the PINMUX configuration.**
NVIDIA's Jetson Pin Mux tool generates a PINMUX configuration for each BSP version. The team had used the R35 tool output. We ran a diff against the R36 reference configuration for the USB pins -- the assignments had changed for several of them.
**Step 4: Trace VBUS sequencing.**
We added boot-time logging to trace when the VBUS power-enable GPIO was firing relative to USB host controller initialization. The GPIO was firing before the controller was ready. VBUS came up too early, the host controller missed it, and devices had no power to enumerate against.
Four issues, all present simultaneously. That's typical for a JetPack 5-to-6 migration on a custom carrier board -- you're not dealing with one wrong thing, you're dealing with four things written against a BSP that no longer matches.
## The fix
We corrected the device tree in three passes.
**PHY node update:** Removed the deprecated properties, added R36-compatible bindings with the correct VBUS current and turn-on delay configuration. Verified the PHY was picking up the new configuration with `usbcore.autosuspend=-1` disabled.
**PINMUX patch:** Generated a fresh PINMUX configuration using the R36 Jetson Pin Mux tool with the correct target hardware. Applied it as a device tree overlay rather than modifying the base board DTS directly -- cleaner for future BSP migrations.
**VBUS sequencing fix:** Added a regulator-fixed node for the VBUS rail with the correct enable timing and GPIO assignment for R36. The host controller now waits for the regulator to come up before attempting enumeration.
Total time from first call to validated fix: under 20 hours. UncommonLab had USB enumeration working across all ports before the end of the next business day.
Everything we built -- the corrected device tree, the overlay structure, the PINMUX patch, the diagnostic notes -- transferred to UncommonLab at handoff. No ongoing dependency.
## Why this keeps appearing on JetPack 6 upgrades
JetPack 6 is not a drop-in upgrade for custom carrier boards. The BSP changes at the kernel level, and device trees written against R35 reference hardware don't automatically become valid R36 device trees.
The upgrade looks clean at first. You flash JetPack 6. The board boots. Most things work. It's only when you connect a USB device -- or a camera over USB -- that the device tree gap becomes visible. The failure shows up weeks after the upgrade, when you're deep into integration and the demo is close.
The other reason this pattern keeps appearing: the documentation gap. NVIDIA publishes the R36 BSP and migration notes, but specific PHY property deprecations aren't flagged with loud kernel warnings. Engineers debugging this for the first time are searching for errors that don't exist. What they need is someone who has already debugged it before.
If you're planning a JetPack 5-to-6 migration on a custom carrier board, audit your device tree against the R36 BSP before you flash. Check the PHY nodes, the PINMUX configuration, and the VBUS sequencing. If you've already hit the wall -- host controller up, no enumeration, no error -- the four areas above are where to start.
For teams weighing whether to debug this in-house or bring in a specialist, the timeline and cost breakdown is in our [post on hiring vs contracting for Jetson work](/blog/hire-embedded-engineer-jetson).
---
## The 30% Tax™ Is Not a Freelancer Problem. It's a Jetson Expertise Problem.
URL: https://proventusnova.com/blog/30-percent-tax-jetson-bsp-ramp-time/
Published: 2026-02-24
Author: Andres Campos
Tags: jetson, bsp, embedded engineer, ramp time, edgeai
20-30% of every engineering hour on Jetson BSP work is platform ramp. It hits internal teams the same as contractors. Here's what it costs and why.
When a hardware startup calls us after two months of stalled board bring-up, there's usually a version of the same conversation. They tried a freelance contractor, or they assigned an internal engineer to the problem, or they're mid-hire on a full-time embedded position. The work isn't moving. The milestone is late. The question is what went wrong.
What went wrong is the 30% Tax™.
Twenty to thirty percent of every engineering hour on Jetson BSP and driver work goes to platform ramp -- not to the deliverable. That's not negligence. It's what any engineer who hasn't debugged that specific JetPack version on that specific carrier board configuration has to do before they can be productive. The form of the engagement changes. The tax doesn't.
**Key Insights**
1. **The 30% Tax™ isn't a freelancer problem -- it's a Jetson expertise problem.** Any engineer who hasn't solved your specific combination before will pay it: freelance contractors, full-time hires in their ramp period, internal team members assigned outside their platform depth. The invoice format is different. The cost is the same.
2. **Internal teams pay the same ramp tax as contractors, but it's invisible.** An hourly contractor makes ramp cost visible as billed hours. An internal engineer spending six weeks learning Jetson BSP shows up as slow velocity and blocked milestones, not a line item. Both are ramp. One is easier to see.
3. **What makes Jetson BSP ramp expensive isn't the volume of knowledge -- it's that the failure modes are version-specific, hardware-specific, and largely undocumented.** A general embedded engineer can learn the basics. Learning that a specific USB PHY property was deprecated in L4T R36, or that CARRIER_POWER_ON timing on a custom carrier needs a PMIC soft-start adjustment, requires having debugged those exact combinations before.
4. **The math on internal ramp is worse than most founders realize.** A senior embedded engineer at $15k-25k per month in loaded cost takes 6-8 weeks to reach productive output on Jetson BSP work specific to a custom carrier board. That's $22k-50k before the first production commit.
5. **The fix isn't to avoid Jetson -- it's to buy back the already-solved foundation once.** A validated BSP foundation with full IP transfer stops the ramp from repeating on every new engineer, every new engagement, every new hire. You pay the ramp once. Every subsequent engineer starts at the validated baseline.
## Why Jetson BSP ramp is different from normal embedded ramp
Engineers ramp on every new codebase. That's expected. What makes Jetson BSP ramp expensive isn't the learning itself -- it's the specific nature of what needs to be learned.
General embedded knowledge transfers. Understanding microcontroller peripherals, communication protocols, real-time scheduling, RTOS patterns -- these apply across platforms. An engineer with deep STM32 experience can apply most of that knowledge to a different microcontroller.
Jetson BSP knowledge doesn't transfer the same way. The failure modes are:
**Version-specific.** A device tree that boots correctly under JetPack 5 (L4T R35) may fail silently under JetPack 6 (L4T R36) because PHY node bindings changed. An engineer who debugged the same symptom on JetPack 5 won't recognize the root cause on JetPack 6. They're starting fresh even if they've been through Jetson bring-up before -- on a different version.
**Hardware-specific.** Two custom carrier boards running the same Jetson module will have different failure modes if they have different power management ICs, different PCIe configurations, different camera interfaces. The ramp isn't to Jetson generally. It's to your specific carrier board and camera combination.
**Largely undocumented.** Stack Overflow doesn't have the answer for production BSP failures. NVIDIA's developer forums have discussions, but most production bring-up issues -- the ones that take weeks -- aren't documented because the teams that solved them don't publish the solution. The knowledge lives in the debugging history of engineers who've been through it.
This is why general intelligence doesn't substitute for pattern recognition. A very smart engineer hitting Jetson Orin carrier board bring-up for the first time will figure it out -- eventually. The ramp is the cost of that figuring-out process happening on your engagement, on your timeline.
## What the ramp actually costs, by engagement format
**Freelance hourly contractor**
An experienced freelance embedded engineer charges $80-150/hour for US-based work. The rate looks accessible. The effective cost isn't.
On Jetson BSP or driver work, expect 20-30% of billed hours to go toward ramp: reading the JetPack documentation specific to your version, familiarizing with your carrier board hardware, setting up the development toolchain, learning the failure modes. On a 200-hour engagement at $100/hour, that's 40-60 hours -- $4,000-$6,000 -- in billed but unproductive ramp time. Add coordination overhead from your side: writing specs, reviewing intermediate output, answering questions. The effective cost of a $20,000 freelance engagement lands at $26,000-$32,000.
**Full-time hire**
A senior embedded engineer with Jetson depth commands $150,000-$220,000 in base salary. Fully loaded with benefits, employer taxes, and equity, that's $15,000-$25,000 per month.
The ramp timeline for a new hire on a custom carrier board and camera configuration is 6-8 weeks before meaningful production output. Not because they're slow -- because the hardware-specific failure modes take time to learn even for someone with prior Jetson experience. At $20,000/month, that's $30,000-$40,000 in ramp cost before the milestone they were hired to deliver has moved.
**Internal engineer reassigned to Jetson work**
The most invisible version of the ramp tax. The engineer is already on payroll. The ramp shows up as velocity loss on their primary deliverables, blocked tickets in the sprint, and a milestone that keeps slipping.
At $15,000-$20,000/month in loaded cost for a senior internal engineer, 6-8 weeks of partial Jetson ramp -- even 50% of their time -- is $11,000-$20,000 in cost before counting the opportunity cost of what they weren't building.
**ProventusNova**
Foundational Layers™ is a pre-validated architecture for Jetson bring-up, built and debugged across enough JetPack versions and carrier board combinations that the starting point is weeks ahead of where any engineer new to the platform would begin. Board bring-up in 7 days. Camera integration in 14-21 days.
Ramp cost doesn't disappear. It's absorbed into our work history rather than billed to the client. On a fixed-bid engagement, any time spent on platform orientation is our cost. The clock you're watching runs on deliverables, not on learning.
## The pattern that keeps the tax in place
Most hardware startups recognize the ramp tax in retrospect, not in advance. The decision to use an hourly contractor or assign an internal engineer sounds reasonable at the time. The hourly rate is visible. The ramp isn't. It only becomes visible weeks later, when the milestone hasn't moved and the burn rate has.
The same pattern applies to hiring. The 4-6 month hiring timeline is accounted for. The 6-8 week ramp after the hire joins often isn't -- it's assumed the new engineer will be productive immediately. The result is a milestone that was supposed to be delivered in month five that's still pending in month eight.
The way to stop paying the tax repeatedly is to buy back the already-solved foundation once. A validated BSP foundation -- EEPROM configuration, ODMDATA, power sequencing, device tree, camera driver -- transferred with full IP and documented at the architecture level is the starting point for every subsequent engineer who touches the platform. The ramp tax isn't eliminated, but it drops from 6-8 weeks of full engineering time to a few days of onboarding against an existing, working baseline.
For the full hiring vs. contracting analysis, see the [hire vs. contractor post](/blog/hire-embedded-engineer-jetson). For a comprehensive cost breakdown of [embedded software development outsourcing versus in-house hire](/blog/outsource-embedded-software-development-vs-hire), including what to look for when evaluating outsourcing firms, see the full comparison.
---
---
## Hire an Embedded Engineer for Jetson or Use a Specialist?
URL: https://proventusnova.com/blog/hire-embedded-engineer-jetson/
Published: 2026-02-17
Author: Aaron Angulo
Tags: jetson, embedded engineer, hiring, edgeai, hardware startup
Hiring a Jetson embedded engineer takes 4 months. ProventusNova delivers board bring-up in 7 days. Compare costs, timelines, and risk before you decide.
At some point in every hardware startup, the embedded software problem gets serious enough that someone says: we need to hire for this.
The instinct is right. The platform -- usually NVIDIA Jetson with a custom carrier board -- has enough complexity that you need someone who knows it well. The question isn't whether to get specialized help. It's whether the right form of that help is a full-time hire or a specialist contractor.
Most founders answer this question based on gut feel or what they did at their last company. The actual data on timing, cost, and risk is rarely laid out in one place. This post does that.
Hiring a senior embedded engineer with real Jetson depth takes four months on average from job posting to accepted offer. That's before onboarding, before ramp on your specific hardware, before the first production commit. During those four months, you're burning $15,000-$25,000 per month in engineering time on the problem the new hire was supposed to solve.
ProventusNova delivers board bring-up in 7 days. Camera integration in 14-21 days. The full stack -- board, camera, inference, handoff -- in 15 weeks. Fixed-bid, with a delivery guarantee.
This isn't an argument against hiring. Sometimes a full-time embedded engineer is exactly the right call. But the decision deserves an honest comparison of what each path actually costs and how long each path actually takes. If you've already decided outsourcing is the model and want to evaluate firms, see [what to look for in an embedded software development outsourcing partner](/blog/outsource-embedded-software-development-vs-hire#what-to-look-for-in-an-embedded-software-outsourcing-partner).
**Key Insights**
1. **Hiring takes 4 months before work starts.** Senior embedded engineers with Jetson-specific depth -- BSP configuration, GMSL2 camera drivers, V4L2 development -- are not common. Job postings sit for weeks. Top candidates have competing offers. Four months from posting to accepted offer is the median, not the outlier.
2. **The fully-loaded cost of a senior embedded hire is $180,000-$280,000 annually.** Base salary runs $150,000-$220,000 for Jetson-depth engineers in the US. Add benefits, equity, and employer taxes. That's $15,000-$25,000 per month before they've shipped a line of production code.
3. **The Silicon Ceiling™ hits before the hire arrives.** The Silicon Ceiling is the failure mode where hardware passes electrical validation but the software stack won't come together. Most startups hit it 2-3 months before they call us -- after internal attempts have stalled and the hire is still 2 months out.
4. **ProventusNova's entry point is the Proof Sprint™ -- 7-14 days, fixed price.** One bounded milestone, delivered before a full-time engineer has cleared their background check. If it doesn't work, keep everything and pay nothing.
5. **The two options aren't mutually exclusive.** Many of our best engagements end with a well-documented, validated codebase that a future internal hire can own. The contractor path and the hiring path can be sequential -- not competing choices.
## What the in-house hiring path actually looks like
Hiring a senior embedded engineer with genuine Jetson depth is a 4-6 month process in practice. Not because startups are slow -- because the candidate pool is small.
NVIDIA Jetson BSP configuration, JetPack kernel patching, GMSL2 camera driver development, V4L2 subsystem work -- these skills don't show up at high density on job boards. The engineers who have them are typically employed, often at companies with strong retention. Posting a job for "embedded software engineer with Jetson experience" will surface candidates with Jetson listed on a resume. Verifying that they've written custom V4L2 drivers under JetPack 6 versus run inference demos on a dev kit is a different screening problem.
The typical hiring timeline breaks down like this:
1. **Job posting goes live.** 2-4 weeks to get meaningful applications.
2. **Phone screens.** 2-3 weeks to screen 20-30 applicants.
3. **Technical interviews.** 3-4 weeks across 3-5 rounds for serious candidates.
4. **Offer, negotiation, background check.** 2-4 weeks.
5. **Notice period at current employer.** 2-4 weeks.
6. **Ramp on your specific hardware.** 4-8 weeks before meaningful output on your carrier board and camera configuration.
Total: 15-28 weeks from posting to first production commit.
During that entire window, your hardware problem isn't getting solved. The carrier board that won't boot sits on a bench. The GMSL2 cameras that won't sync wait. Every week that passes is a week closer to a demo deadline, a field trial window, or an investor meeting -- with nothing to show.
The financial cost compounds. At $20,000/month in fully-loaded engineering cost for the team members already blocked on the problem, a 6-month delay costs $120,000 in wasted burn before counting the new hire's salary. Add the recruiting cost: agency fees typically run 20-25% of first-year salary for specialized technical hires, which is $30,000-$55,000 on a $150,000-$220,000 offer.
And that's the successful outcome. The 4-month hire scenario plays out like this: a founder spends 4 months interviewing, makes an offer to the right candidate, and the candidate takes a competing offer. Four months of burn. Zero product built. Back to square one.
When the hire does come through, they're a full-time employee with all the structure that implies: onboarding, 1:1s, performance reviews, benefits, PTO, and the expectation of long-term career development within the company. That's the right structure for an ongoing embedded roadmap. For a bounded, critical-path milestone, it's significant overhead for a specific deliverable.
## What ProventusNova actually does
ProventusNova is a two-platform specialist -- NVIDIA Jetson and MediaTek Genio. We don't take on other platforms. That narrowness is why the timelines work.
Board bring-up in 7 days. Camera integration in 14-21 days. Full stack -- board, camera, media pipeline, AI inference, handoff documentation -- in 15 weeks. Those aren't aspirational targets. They're delivery records built on Foundational Layers™: five pre-validated layers we bring to every Jetson engagement so we're not starting from scratch.
When Farmhand AI's custom carrier board wouldn't boot, we had it running in a single working session. Not because the problem was trivial -- it wasn't -- but because we'd been through enough carrier board bring-up failures on Jetson Orin to know exactly which BSP configuration parameters to check first. The board was booting within hours because we weren't reading the Jetson hardware design guide for the first time.
When UncommonLab hit a USB enumeration failure on JetPack 6 that their team couldn't diagnose after weeks of debugging, we found the root cause in 4 hours and delivered the full fix in under 20 hours. When CSIR-IGIN needed a USB port fix ported to a new JetPack version, it was done in 10 hours.
These turnarounds come from having debugged the same categories of failures across enough JetPack versions and carrier board configurations that the failure modes are recognizable before you've finished describing the symptom.
The engagement model is fixed-bid for bounded work. One scope, one price, one deadline. The Fixed-Bid Proof Principle™: we only quote fixed-bid on work we've done before, which means the risk of underestimating lands on us, not on the client. If a milestone slips past its deadline, work continues at 50% cost until it's done.
The [Proof Sprint™](/services) is the entry point -- one milestone, 7-14 days, fixed price: board bring-up, camera driver integration, or EdgeAI model deployment. The total cost is typically a fraction of one month of an embedded engineer's fully-loaded salary. If you're not satisfied after two weeks, keep the code, documentation, and IP and pay nothing.
At the end of a ProventusNova engagement, there's full IP transfer: code, device trees, documentation, architecture notes. What you get back isn't a black box -- it's a validated starting point that an internal engineer can own going forward. The contractor path and the hiring path don't have to compete. We build the foundation; your future hire runs on it.
## Hiring vs ProventusNova: direct comparison for Jetson projects
| | **Full-Time Embedded Hire** | **ProventusNova** |
|---|---|---|
| **Time to first output** | 15-28 weeks (hiring + ramp) | 7 days (board bring-up) |
| **Cost to first milestone** | $60,000-$100,000 (hiring period burn) | Fixed-bid Proof Sprint™ |
| **Jetson BSP / GMSL2 / V4L2 depth** | Varies by candidate | Core focus, pre-validated |
| **Delivery guarantee** | None | 50% cost if delayed; zero if unsatisfied |
| **IP ownership** | Employee-created IP (clean) | Full transfer on completion |
| **Ongoing availability** | Full-time, embedded in team | Engagement-scoped |
| **Management overhead** | Benefits, equity, HR, 1:1s | None -- scope and deliver |
| **Right for ongoing roadmap** | ✓ Yes | ⚠ Engagement-by-engagement |
| **Right for bounded critical milestone** | ⚠ Overbuilt for the scope | ✓ Yes |
| **Risk of wrong outcome** | High -- 4+ months lost, recruiting cost | None -- Proof Sprint guarantee |
| **Ramp time cost** | $30,000-$80,000 (2-4 months @ $20k/month) | Absorbed -- Foundational Layers™ |
| **Entry point** | Job posting (4-month process) | Proof Sprint™ (7-14 days) |
## Where hiring a full-time engineer is the right call
**You have an ongoing embedded roadmap spanning 12+ months.** If your product roadmap requires continuous embedded development -- new camera configurations, updated inference models, kernel version upgrades, new carrier board revisions -- a full-time engineer embedded in your team is the right structure. Contractors are good at milestones; full-time engineers are good at ownership.
**The embedded work intersects deeply with product decisions.** A contractor executes defined scope. A full-time engineer participates in architecture decisions, attends sprint planning, and catches embedded implications of product choices early. If your embedded software is tightly coupled to product direction that's still evolving, internal ownership matters.
**You have the runway to absorb the hiring timeline.** If your next critical milestone is 6+ months out and you have sufficient runway, the 4-month hiring timeline is manageable. The risk is bounded and the long-term cost structure makes sense.
**You're past the initial bring-up phase.** Once the board is booting, cameras are streaming, and the inference pipeline is running, the work shifts from specialist bring-up to product iteration. That's a better fit for an embedded engineer who will grow with the product than for a specialist contractor.
## Where ProventusNova has the edge
**The milestone is on the critical path and the clock is running.** A stalled carrier board or non-functional camera pipeline blocking a demo, field trial, or investor meeting can't wait 4 months for a hire. Fixed-bid with a 7-14 day delivery window is a different risk structure.
**You've hit the Silicon Ceiling™.** If your team has been in Driver Hell -- USB enumeration failures on JetPack 6, GMSL2 desync, V4L2 format negotiation errors -- for more than two weeks, that's a specialist problem. A generalist hire learns it on your time.
**You want to understand the problem before committing to a hire.** The Proof Sprint™ gives you a resolved milestone in 7-14 days, with full IP. That's also a way to understand the actual scope before writing a job description. You'll hire better after seeing what the work requires.
**Budget constraints are real.** Not every startup can absorb $180,000-$280,000 in fully-loaded annual compensation for a specialized hire right now. The Proof Sprint™ delivers a resolved milestone at a fraction of that cost, with the option to scope follow-on work as needed.
## The real cost comparison
The comparison isn't rate vs. salary. It's total cost to a resolved milestone.
**Path A -- Full-time hire:**
- Job posting to first production commit: 15-28 weeks
- Recruiting cost: $30,000-$55,000 (agency fees)
- Engineering burn during hiring: $60,000-$100,000 (team blocked on the problem)
- New hire salary for first 6 months before fully productive: $75,000-$110,000
- Total cost to first meaningful output: **$165,000-$265,000**
**Path B -- ProventusNova:**
- Board bring-up: 7 days, fixed price
- Camera integration: 14-21 days, fixed price
- Full 15-week stack under Dead Silicon to Demo™: fixed price, full IP transfer
- Total cost to production-ready demo with documentation: **a fraction of the hire path, delivered on a guaranteed timeline**
A full-time embedded engineer who owns your platform for years is a real asset. The question is whether the hire path is right for the specific problem you have right now, on the timeline you're operating under.
Most founders who call us have already spent $45,000-$150,000 in internal engineering burn on a problem they've been trying to solve for 2-3 months. The Proof Sprint™ resolves that in two weeks, with a full IP handoff. In most cases, that handoff document becomes the foundation for the job description they write next.
## Which path fits your situation
**Choose to hire a full-time embedded engineer if:**
- You have 12+ months of ongoing embedded work ahead with a clear roadmap
- The embedded software decisions are tightly coupled to evolving product direction
- You have sufficient runway to absorb a 4-6 month hiring and ramp timeline
- You're past the initial bring-up phase and into product iteration
**Choose ProventusNova if:**
- A specific milestone is on the critical path and can't wait 4 months
- Your team has been stuck on a BSP, driver, or inference problem for more than 2 weeks
- You want a resolved, documented deliverable before writing a hiring job description
- Budget doesn't support a $180,000+ annual embedded hire right now
- You want to prove the working relationship before a longer-term commitment
## The bottom line
Hiring and contracting aren't competing philosophies. They're tools with different timelines, cost structures, and risk profiles.
A full-time embedded engineer who owns your Jetson platform for years is a real asset -- eventually. The problem is that "eventually" takes 4-6 months to arrive, during which your critical path problem sits unresolved, your demo is delayed, and your engineering burn compounds.
ProventusNova doesn't replace that hire. We solve the milestone blocking you right now, hand off everything with full IP transfer, and leave you with a validated foundation that your future hire can build on. That's not a stopgap -- it's often the fastest path to actually being ready to hire well.
Most of the startups that come to us are stuck because the Silicon Ceiling™ hit before the hiring plan could execute. The Proof Sprint™ is what breaks through it: one milestone, 14 days, fixed price. If it doesn't deliver, keep everything and pay nothing.
*Blocked on a Jetson milestone while your hiring search runs? [Book a scoping call](https://proventusnova.com/contact) -- we'll tell you what it costs and whether it's faster than waiting for a hire.*
---
---